diff --git a/common/constants.py b/common/constants.py
index 417628089e..febfd34071 100644
--- a/common/constants.py
+++ b/common/constants.py
@@ -142,6 +142,7 @@ class FileSource(StrEnum):
LOCAL = ""
KNOWLEDGEBASE = "knowledgebase"
RSS = "rss"
+ SITEMAP = "sitemap"
S3 = "s3"
NOTION = "notion"
REST_API = "rest_api"
diff --git a/common/data_source/__init__.py b/common/data_source/__init__.py
index 909f4c22ae..fdb2871f2b 100644
--- a/common/data_source/__init__.py
+++ b/common/data_source/__init__.py
@@ -63,6 +63,7 @@ from .rss_connector import RSSConnector
from .salesforce_connector import SalesforceConnector
from .seafile_connector import SeaFileConnector
from .sharepoint_connector import SharePointConnector
+from .sitemap_connector import SitemapConnector
from .slack_connector import SlackConnector
from .teams_connector import TeamsConnector
from .webdav_connector import WebDAVConnector
@@ -83,6 +84,7 @@ CONNECTOR_BY_SOURCE: dict[str, type] = {
FileSource.GOOGLE_DRIVE: GoogleDriveConnector,
FileSource.JIRA: JiraConnector,
FileSource.SHAREPOINT: SharePointConnector,
+ FileSource.SITEMAP: SitemapConnector,
FileSource.SLACK: SlackConnector,
FileSource.TEAMS: TeamsConnector,
FileSource.WEBDAV: WebDAVConnector,
@@ -160,6 +162,7 @@ __all__ = [
"SalesforceConnector",
"SeaFileConnector",
"SharePointConnector",
+ "SitemapConnector",
"SlackConnector",
"TeamsConnector",
"TextSection",
diff --git a/common/data_source/config.py b/common/data_source/config.py
index 46089ff62c..da3335760a 100644
--- a/common/data_source/config.py
+++ b/common/data_source/config.py
@@ -44,6 +44,7 @@ class DocumentSource(str, Enum):
"""Document sources"""
RSS = "rss"
+ SITEMAP = "sitemap"
S3 = "s3"
NOTION = "notion"
REST_API = "rest_api"
diff --git a/common/data_source/html_utils.py b/common/data_source/html_utils.py
index 9fd33a7b0e..e64ea1963a 100644
--- a/common/data_source/html_utils.py
+++ b/common/data_source/html_utils.py
@@ -48,8 +48,13 @@ def format_element_text(element_text: str, link_href: str | None) -> str:
return f"[{element_text_no_newlines}]({link_href})"
-def parse_html_with_trafilatura(html_content: str) -> str:
- """Parse HTML content using trafilatura."""
+def parse_html_with_trafilatura(html_content: str, output_format: str = "txt") -> str:
+ """Parse HTML content using trafilatura.
+
+ ``output_format`` is passed through to trafilatura: ``"txt"`` (default) yields the
+ flat text used by the web connectors, ``"markdown"`` keeps headings, lists, links
+ and tables as Markdown (see :func:`web_html_to_markdown`).
+ """
import trafilatura # type: ignore
from trafilatura.settings import use_config # type: ignore
@@ -59,6 +64,24 @@ def parse_html_with_trafilatura(html_content: str) -> str:
config.set("DEFAULT", "include_images", "True")
config.set("DEFAULT", "include_formatting", "True")
+ if output_format == "markdown":
+ # trafilatura reads the include_* switches from keyword arguments, not from the
+ # config object, so they are passed explicitly here: links and tables are kept
+ # as Markdown, images are dropped (noise for retrieval), and favor_recall keeps
+ # short but relevant sections. Markdown is whitespace-sensitive (nested lists,
+ # tables), so only the ends are trimmed.
+ extracted_text = trafilatura.extract(
+ html_content,
+ config=config,
+ output_format="markdown",
+ include_links=True,
+ include_tables=True,
+ include_images=False,
+ include_formatting=True,
+ favor_recall=True,
+ )
+ return extracted_text.strip() if extracted_text else ""
+
extracted_text = trafilatura.extract(html_content, config=config)
return strip_excessive_newlines_and_spaces(extracted_text) if extracted_text else ""
@@ -155,11 +178,20 @@ def parse_html_page_basic(text: str | BytesIO | IO[bytes]) -> str:
return format_document_soup(soup)
-def web_html_cleanup(
+def _clean_web_soup(
page_content: str | bs4.BeautifulSoup,
- mintlify_cleanup_enabled: bool = True,
- additional_element_types_to_discard: list[str] | None = None,
-) -> ParsedHTML:
+ mintlify_cleanup_enabled: bool,
+ additional_element_types_to_discard: list[str] | None,
+ remove_title: bool = True,
+) -> tuple[str | None, bs4.BeautifulSoup]:
+ """Shared pre-processing of web pages: title extraction and removal of boilerplate.
+
+ Boilerplate is dropped by CSS class (``WEB_CONNECTOR_IGNORED_CLASSES``, plus the
+ Mintlify ones when enabled) and by tag (``WEB_CONNECTOR_IGNORED_ELEMENTS`` such as
+ nav/footer/script, plus any caller-provided tags). The ```` text is returned;
+ the tag itself is removed unless ``remove_title`` is False (trafilatura otherwise
+ promotes the first ``<h1>`` to document title and drops it from the body).
+ """
if isinstance(page_content, str):
soup = bs4.BeautifulSoup(page_content, "html.parser")
else:
@@ -169,7 +201,8 @@ def web_html_cleanup(
title = None
if title_tag and title_tag.text:
title = title_tag.text
- title_tag.extract()
+ if remove_title:
+ title_tag.extract()
# Heuristics based cleaning of elements based on css classes
unwanted_classes = copy(WEB_CONNECTOR_IGNORED_CLASSES)
@@ -185,21 +218,51 @@ def web_html_cleanup(
for undesired_tag in additional_element_types_to_discard:
[tag.extract() for tag in soup.find_all(undesired_tag)]
- soup_string = str(soup)
- page_text = ""
+ return title, soup
- if PARSE_WITH_TRAFILATURA:
+
+def _extract_web_text(soup: bs4.BeautifulSoup, output_format: str, use_trafilatura: bool) -> str:
+ """Extract text from a cleaned soup with trafilatura, falling back on the bs4 formatter."""
+ page_text = ""
+ if use_trafilatura:
try:
- page_text = parse_html_with_trafilatura(soup_string)
+ page_text = parse_html_with_trafilatura(str(soup), output_format=output_format)
if not page_text:
raise ValueError("Empty content returned by trafilatura.")
except Exception as e:
logging.info(f"Trafilatura parsing failed: {e}. Falling back on bs4.")
- page_text = format_document_soup(soup)
- else:
+ if not page_text:
+ title_tag = soup.find("title")
+ if title_tag is not None:
+ title_tag.extract()
page_text = format_document_soup(soup)
# 200B is ZeroWidthSpace which we don't care for
- cleaned_text = page_text.replace("\u200b", "")
+ return page_text.replace("\u200b", "")
- return ParsedHTML(title=title, cleaned_text=cleaned_text)
+
+def web_html_cleanup(
+ page_content: str | bs4.BeautifulSoup,
+ mintlify_cleanup_enabled: bool = True,
+ additional_element_types_to_discard: list[str] | None = None,
+) -> ParsedHTML:
+ """Clean a web page and extract its flat text (title + boilerplate-free content)."""
+ title, soup = _clean_web_soup(page_content, mintlify_cleanup_enabled, additional_element_types_to_discard)
+ return ParsedHTML(title=title, cleaned_text=_extract_web_text(soup, "txt", use_trafilatura=PARSE_WITH_TRAFILATURA))
+
+
+def web_html_to_markdown(
+ page_content: str | bs4.BeautifulSoup,
+ mintlify_cleanup_enabled: bool = True,
+ additional_element_types_to_discard: list[str] | None = None,
+) -> ParsedHTML:
+ """Clean a web page like :func:`web_html_cleanup` but keep the structure as Markdown.
+
+ Same boilerplate removal and title extraction; the content is extracted by
+ trafilatura with ``output_format="markdown"`` (headings, lists, links, tables).
+ Markdown output needs trafilatura, so this path does not depend on the
+ ``PARSE_WITH_TRAFILATURA`` switch (which only governs the flat-text connectors);
+ the flat bs4 text is used as a fallback when trafilatura fails or returns nothing.
+ """
+ title, soup = _clean_web_soup(page_content, mintlify_cleanup_enabled, additional_element_types_to_discard, remove_title=False)
+ return ParsedHTML(title=title, cleaned_text=_extract_web_text(soup, "markdown", use_trafilatura=True))
diff --git a/common/data_source/sitemap_connector.py b/common/data_source/sitemap_connector.py
new file mode 100644
index 0000000000..65f45280c2
--- /dev/null
+++ b/common/data_source/sitemap_connector.py
@@ -0,0 +1,615 @@
+import asyncio
+import hashlib
+import logging
+import queue
+import re
+import threading
+from collections.abc import Callable, Iterator
+from datetime import UTC, datetime
+from typing import Any
+from urllib.parse import urljoin, urlparse
+from xml.etree import ElementTree as ET
+
+import regex
+import requests
+
+from common.data_source.config import (
+ INDEX_BATCH_SIZE,
+ REQUEST_TIMEOUT_SECONDS,
+ DocumentSource,
+)
+from common.data_source.html_utils import web_html_to_markdown
+from common.data_source.interfaces import LoadConnector, PollConnector, SlimConnectorWithPermSync
+from common.data_source.models import (
+ Document,
+ GenerateDocumentsOutput,
+ GenerateSlimDocumentOutput,
+ SecondsSinceUnixEpoch,
+ SlimDocument,
+)
+from common.ssrf_guard import assert_url_is_safe
+from common.ssrf_guard import pin_dns as _pin_dns
+
+_SITEMAP_NS = "http://www.sitemaps.org/schemas/sitemap/0.9"
+_MAX_REDIRECTS = 10
+_MAX_SITEMAP_DEPTH = 5
+_MAX_SITEMAP_FETCHES = 1000
+_MAX_RESPONSE_BYTES = 64 * 1024 * 1024
+_READ_CHUNK_BYTES = 64 * 1024
+_MAX_URL_FILTER_LENGTH = 512
+_MAX_MATCHED_URL_LENGTH = 4096
+_URL_FILTER_TIMEOUT_SECONDS = 1.0
+# A quantified group that itself contains a quantifier, e.g. "(a+)+" or "(a*b)*":
+# the classic shape behind catastrophic backtracking in Python's regex engine.
+_NESTED_QUANTIFIER_RE = re.compile(r"\([^()]*[+*}][^()]*\)\s*[+*{?]")
+
+logger = logging.getLogger(__name__)
+
+_QUEUE_END = object()
+_QUEUE_POLL_SECONDS = 0.5
+
+
+class _WorkerThreadIterator:
+ """Iterator over items produced by ``source`` in a daemon worker thread.
+
+ See :func:`iter_in_worker_thread`. ``offload_next`` tells the sync worker that
+ ``next()`` may block and should be awaited through ``asyncio.to_thread``.
+ """
+
+ offload_next = True
+
+ def __init__(self, source: Iterator[Any], maxsize: int, on_close: Callable[[], None] | None):
+ self._source = source
+ self._queue: queue.Queue = queue.Queue(maxsize=maxsize)
+ self._stop = threading.Event()
+ self._closed = False
+ self._on_close = on_close
+ self._worker = threading.Thread(target=self._produce, name="sitemap-batch-producer", daemon=True)
+ self._worker.start()
+
+ def _put(self, item: Any) -> bool:
+ """Enqueue ``item`` unless the consumer went away; never blocks forever."""
+ while not self._stop.is_set():
+ try:
+ self._queue.put(item, timeout=_QUEUE_POLL_SECONDS)
+ return True
+ except queue.Full:
+ continue
+ return False
+
+ def _produce(self) -> None:
+ try:
+ for item in self._source:
+ if not self._put(item):
+ return
+ self._put(_QUEUE_END)
+ except BaseException as exc: # noqa: BLE001 - forwarded to the consumer
+ self._put(exc)
+ finally:
+ close = getattr(self._source, "close", None)
+ if close is not None:
+ try:
+ close()
+ except Exception:
+ logger.debug("worker-thread generator close() failed", exc_info=True)
+
+ def __iter__(self) -> "_WorkerThreadIterator":
+ return self
+
+ def __next__(self) -> Any:
+ while True:
+ if self._closed:
+ raise StopIteration
+ try:
+ item = self._queue.get(timeout=_QUEUE_POLL_SECONDS)
+ except queue.Empty:
+ continue
+ if item is _QUEUE_END:
+ self.close()
+ raise StopIteration
+ if isinstance(item, BaseException):
+ self.close()
+ raise item
+ return item
+
+ def close(self) -> None:
+ """Stop the producer; also invoked when the consumer abandons iteration."""
+ if self._closed:
+ return
+ self._closed = True
+ self._stop.set()
+ if self._on_close is not None:
+ try:
+ self._on_close()
+ except Exception:
+ logger.debug("worker-thread on_close callback failed", exc_info=True)
+
+ def join(self, timeout: float | None = None) -> None:
+ self._worker.join(timeout)
+
+ @property
+ def producer_alive(self) -> bool:
+ return self._worker.is_alive()
+
+
+async def validate_connector_in_thread(connector: "SitemapConnector") -> None:
+ """Run ``validate_connector_settings`` off the event loop and propagate cancellation.
+
+ The sync worker wraps the whole task in ``asyncio.wait_for``. A thread started by
+ ``asyncio.to_thread`` cannot be interrupted, so when the awaiting coroutine is
+ cancelled (task timeout) the connector is told to stop at its next cancellation
+ check instead of finishing its fetches in the background.
+ """
+ try:
+ await asyncio.to_thread(connector.validate_connector_settings)
+ except asyncio.CancelledError:
+ logger.warning("Sitemap validation cancelled (task timeout) for %s; stopping the connector", connector.sitemap_url)
+ connector.cancel()
+ raise
+
+
+def iter_in_worker_thread(source: Iterator[Any], maxsize: int = 2, on_close: Callable[[], None] | None = None) -> _WorkerThreadIterator:
+ """Consume ``source`` in a daemon worker thread and hand its items over through a bounded queue.
+
+ The sync worker iterates connector generators on the asyncio thread. Running the
+ generator (and therefore all its blocking HTTP calls) in a worker thread keeps that
+ blocking off the event-loop thread and lets the next batch be downloaded while the
+ previous one is indexed. Exceptions raised by the source are re-raised in the
+ consumer. Closing the consumer stops the producer: queue writes are abandoned,
+ and ``on_close`` (typically the connector's ``cancel``) is invoked so that an
+ in-progress traversal gives up at its next check instead of finishing its fetches.
+ """
+ return _WorkerThreadIterator(source, maxsize, on_close)
+
+
+class SitemapConnector(LoadConnector, PollConnector, SlimConnectorWithPermSync):
+ """Connector that ingests web pages listed in a sitemap.xml.
+
+ Supports:
+ - Standard urlset sitemaps
+ - Sitemap index files (recursive, up to _MAX_SITEMAP_DEPTH levels)
+ - Incremental polling via <lastmod>
+ """
+
+ def __init__(
+ self,
+ sitemap_url: str,
+ batch_size: int = 10,
+ user_agent: str = "RAGFlow-SitemapConnector/1.0",
+ url_filter: str | None = None,
+ follow_pdf_links: bool = False,
+ restrict_pdf_to_domain: bool = True,
+ ) -> None:
+ self.sitemap_url = sitemap_url.strip()
+ self.batch_size = batch_size
+ self.user_agent = user_agent
+ self._url_filter: regex.Pattern | None = self._compile_url_filter(url_filter) if url_filter else None
+ # Dedicated session: no ambient proxies / .netrc credentials from the worker
+ # environment, so every request goes straight to the DNS-pinned address.
+ self._session = requests.Session()
+ self._session.trust_env = False
+ self._cancel = threading.Event()
+ self.follow_pdf_links = follow_pdf_links
+ self.restrict_pdf_to_domain = restrict_pdf_to_domain
+ self.credentials: dict[str, Any] = {}
+
+ @classmethod
+ def build_connector(cls, config: dict[str, Any]) -> "SitemapConnector":
+ """Build a connector from the connector config stored by the UI/API."""
+ connector = cls(
+ sitemap_url=config["sitemap_url"],
+ batch_size=int(config.get("batch_size") or INDEX_BATCH_SIZE),
+ user_agent=(config.get("user_agent") or "").strip() or "RAGFlow-SitemapConnector/1.0",
+ url_filter=(config.get("url_filter") or "").strip() or None,
+ follow_pdf_links=bool(config.get("follow_pdf_links", False)),
+ restrict_pdf_to_domain=bool(config.get("restrict_pdf_to_domain", True)),
+ )
+ connector.load_credentials(config.get("credentials") or {})
+ return connector
+
+ def load_credentials(self, credentials: dict[str, Any]) -> dict[str, Any] | None:
+ self.credentials = credentials or {}
+ return None
+
+ def cancel(self) -> None:
+ """Ask an in-progress traversal to stop at its next check (next URL or next body chunk)."""
+ self._cancel.set()
+
+ @property
+ def cancelled(self) -> bool:
+ return self._cancel.is_set()
+
+ @staticmethod
+ def _compile_url_filter(pattern: str) -> regex.Pattern:
+ """Compile the user-provided url_filter with bounded evaluation.
+
+ The pattern is matched against sitemap-controlled URLs. It is compiled with the
+ ``regex`` module (already a transitive dependency through tiktoken / nltk) so
+ that every match runs under a timeout, which is the only robust defence against
+ catastrophic backtracking (``(a|aa)+`` and friends cannot be detected syntactically).
+ The obvious nested-quantifier shapes are still refused up front to give users an
+ immediate error, and the pattern length is bounded.
+ """
+ if len(pattern) > _MAX_URL_FILTER_LENGTH:
+ raise ValueError(f"url_filter is too long (max {_MAX_URL_FILTER_LENGTH} characters)")
+ if _NESTED_QUANTIFIER_RE.search(pattern):
+ raise ValueError("url_filter must not contain nested quantifiers such as '(a+)+', which can cause catastrophic backtracking")
+ try:
+ return regex.compile(pattern)
+ except regex.error as exc:
+ raise ValueError(f"url_filter is not a valid regex: {exc}") from exc
+
+ def validate_connector_settings(self) -> None:
+ self._validate_url(self.sitemap_url)
+ if self.batch_size < 1:
+ raise ValueError("batch_size must be greater than 0")
+ if not any(self._url_matches(u[0]) for u in self._iter_sitemap_urls(self.sitemap_url, depth=0)):
+ raise ValueError("Sitemap contains no URLs matching the filter")
+
+ def load_from_state(self) -> GenerateDocumentsOutput:
+ yield from self._load_urls()
+
+ def poll_source(self, start: SecondsSinceUnixEpoch, end: SecondsSinceUnixEpoch) -> GenerateDocumentsOutput:
+ yield from self._load_urls(start=start, end=end)
+
+ def retrieve_all_slim_docs_perm_sync(self, callback: Any = None) -> GenerateSlimDocumentOutput:
+ """Yield the complete set of document IDs the connector currently exposes.
+
+ When ``follow_pdf_links`` is enabled the HTML pages are fetched so that
+ the PDFs discovered in them are part of the retained set; otherwise a
+ prune run would delete them right after they were indexed.
+ """
+ del callback
+ seen: set[str] = set()
+ sitemap_domain = urlparse(self.sitemap_url).netloc
+ batch: list[SlimDocument] = []
+ for url, _lastmod in self._iter_sitemap_urls(self.sitemap_url, depth=0):
+ if url in seen or not self._url_matches(url):
+ continue
+ seen.add(url)
+ batch.append(SlimDocument(id=self._build_document_id(url)))
+ if len(batch) >= self.batch_size:
+ yield batch
+ batch = []
+
+ if not self.follow_pdf_links:
+ continue
+ try:
+ raw, content_type = self._fetch_raw(url)
+ except (requests.RequestException, ValueError, OSError) as exc:
+ logger.warning("Failed to fetch page %s for PDF discovery: %s", url, exc)
+ continue
+ if "application/pdf" in content_type:
+ continue
+ for pdf_url in self._extract_pdf_links(raw, url):
+ if pdf_url in seen:
+ continue
+ if self.restrict_pdf_to_domain and urlparse(pdf_url).netloc != sitemap_domain:
+ continue
+ seen.add(pdf_url)
+ batch.append(SlimDocument(id=self._build_document_id(pdf_url)))
+ if len(batch) >= self.batch_size:
+ yield batch
+ batch = []
+ if batch:
+ yield batch
+
+ # ------------------------------------------------------------------
+ # Internal helpers
+ # ------------------------------------------------------------------
+
+ def _load_urls(
+ self,
+ start: SecondsSinceUnixEpoch | None = None,
+ end: SecondsSinceUnixEpoch | None = None,
+ ) -> GenerateDocumentsOutput:
+ seen: set[str] = set()
+ pending_pdfs: list[tuple[str, str]] = [] # (pdf_url, parent_url)
+ sitemap_domain = urlparse(self.sitemap_url).netloc
+
+ # --- Pass 1: sitemap URLs ---
+ batch: list[Document] = []
+ for url, lastmod in self._iter_sitemap_urls(self.sitemap_url, depth=0):
+ if self._cancel.is_set():
+ logger.info("Sitemap traversal cancelled")
+ return
+ if url in seen or not self._url_matches(url):
+ continue
+ seen.add(url)
+
+ if start is not None or end is not None:
+ if lastmod is None:
+ if start is not None:
+ continue
+ else:
+ ts = lastmod.timestamp()
+ if start is not None and ts <= start:
+ continue
+ if end is not None and ts > end:
+ continue
+
+ doc = self._fetch_and_build_document(url, lastmod, seen, pending_pdfs, sitemap_domain)
+ if doc is None:
+ continue
+
+ batch.append(doc)
+ if len(batch) >= self.batch_size:
+ yield batch
+ batch = []
+
+ if batch:
+ yield batch
+
+ # --- Pass 2: PDF links discovered from HTML pages ---
+ if not self.follow_pdf_links or not pending_pdfs:
+ return
+
+ batch = []
+ for pdf_url, parent_url in pending_pdfs:
+ if self._cancel.is_set():
+ logger.info("Sitemap traversal cancelled during PDF pass")
+ return
+ doc = self._fetch_and_build_document(pdf_url, None, seen, [], sitemap_domain, parent_url)
+ if doc is None:
+ continue
+ batch.append(doc)
+ if len(batch) >= self.batch_size:
+ yield batch
+ batch = []
+
+ if batch:
+ yield batch
+
+ def _iter_sitemap_urls(self, sitemap_url: str, depth: int, _walk: dict[str, Any] | None = None) -> Iterator[tuple[str, datetime | None]]:
+ """Recursively yield (url, lastmod) pairs from a sitemap or sitemap index.
+
+ Each sitemap URL is fetched at most once (an index referencing itself or an
+ ancestor is skipped) and the walk stops after ``_MAX_SITEMAP_FETCHES`` sitemap
+ documents, so one connector cannot trigger unbounded egress.
+ """
+ if _walk is None:
+ _walk = {"visited": set(), "fetched": 0}
+ if depth > _MAX_SITEMAP_DEPTH:
+ logger.warning("Max sitemap depth reached, stopping at %s", sitemap_url)
+ return
+ if sitemap_url in _walk["visited"]:
+ logger.warning("Sitemap %s already visited, skipping", sitemap_url)
+ return
+ _walk["visited"].add(sitemap_url)
+ if _walk["fetched"] >= _MAX_SITEMAP_FETCHES:
+ logger.warning("Maximum number of sitemap fetches (%s) reached, stopping at %s", _MAX_SITEMAP_FETCHES, sitemap_url)
+ return
+ _walk["fetched"] += 1
+ if self._cancel.is_set():
+ return
+
+ try:
+ self._validate_url(sitemap_url)
+ content, _ = self._fetch_raw(sitemap_url)
+ except (requests.RequestException, ValueError, OSError) as exc:
+ logger.warning("Failed to fetch sitemap %s: %s", sitemap_url, exc)
+ return
+
+ try:
+ root = ET.fromstring(content)
+ except ET.ParseError as exc:
+ raise ValueError(f"Failed to parse sitemap XML from {sitemap_url!r}: {exc}") from exc
+
+ tag = root.tag.lower()
+
+ # Sitemap index → recurse into child sitemaps
+ if "sitemapindex" in tag:
+ for sitemap_el in root.iter(f"{{{_SITEMAP_NS}}}sitemap"):
+ loc_el = sitemap_el.find(f"{{{_SITEMAP_NS}}}loc")
+ if loc_el is None or not (loc_el.text or "").strip():
+ continue
+ child_url = loc_el.text.strip()
+ yield from self._iter_sitemap_urls(child_url, depth + 1, _walk)
+ return
+
+ # Standard urlset
+ for url_el in root.iter(f"{{{_SITEMAP_NS}}}url"):
+ loc_el = url_el.find(f"{{{_SITEMAP_NS}}}loc")
+ if loc_el is None or not (loc_el.text or "").strip():
+ continue
+ loc = loc_el.text.strip()
+
+ lastmod: datetime | None = None
+ lastmod_el = url_el.find(f"{{{_SITEMAP_NS}}}lastmod")
+ if lastmod_el is not None and (lastmod_el.text or "").strip():
+ lastmod = self._parse_lastmod(lastmod_el.text.strip())
+
+ yield loc, lastmod
+
+ def _fetch_and_build_document(
+ self,
+ url: str,
+ lastmod: datetime | None,
+ seen: set[str] | None = None,
+ pending_pdfs: list[tuple[str, str]] | None = None,
+ sitemap_domain: str | None = None,
+ parent_url: str | None = None,
+ ) -> Document | None:
+ try:
+ self._validate_url(url)
+ raw, content_type = self._fetch_raw(url)
+ except (requests.RequestException, ValueError, OSError) as exc:
+ logger.warning("Failed to fetch page %s: %s", url, exc)
+ return None
+
+ updated_at = lastmod or datetime.now(UTC)
+
+ if "application/pdf" in content_type:
+ if not raw:
+ logger.debug("Empty PDF for %s, skipping", url)
+ return None
+ blob = raw
+ extension = ".pdf"
+ else:
+ if self.follow_pdf_links and seen is not None and pending_pdfs is not None:
+ for pdf_url in self._extract_pdf_links(raw, url):
+ if pdf_url in seen:
+ continue
+ if not self.restrict_pdf_to_domain or urlparse(pdf_url).netloc == sitemap_domain:
+ pending_pdfs.append((pdf_url, url))
+ seen.add(pdf_url)
+
+ try:
+ text = web_html_to_markdown(raw.decode("utf-8", errors="replace")).cleaned_text
+ except Exception as exc: # noqa: BLE001 - third-party extractor, any failure just skips the page
+ logger.warning("Failed to parse page %s: %s", url, exc)
+ return None
+
+ if not text or not text.strip():
+ logger.debug("Empty content for %s, skipping", url)
+ return None
+
+ blob = text.encode("utf-8")
+ extension = ".md"
+
+ return Document(
+ id=self._build_document_id(url),
+ source=DocumentSource.SITEMAP,
+ semantic_identifier=self._url_to_identifier(url),
+ extension=extension,
+ blob=blob,
+ doc_updated_at=updated_at,
+ size_bytes=len(blob),
+ metadata={
+ "sitemap_url": self.sitemap_url,
+ "url": url,
+ **({"parent_url": parent_url} if parent_url else {}),
+ },
+ )
+
+ @staticmethod
+ def _extract_pdf_links(html_bytes: bytes, base_url: str) -> list[str]:
+ """Extract absolute PDF href links from an HTML page."""
+ from html.parser import HTMLParser
+
+ class _Extractor(HTMLParser):
+ def __init__(self):
+ super().__init__()
+ self.links: list[str] = []
+
+ def handle_starttag(self, tag, attrs):
+ if tag == "a":
+ href = (dict(attrs).get("href", "") or "").strip()
+ if href:
+ self.links.append(href)
+
+ ex = _Extractor()
+ ex.feed(html_bytes.decode("utf-8", errors="replace"))
+ pdf_links: list[str] = []
+ for href in ex.links:
+ absolute = urljoin(base_url, href)
+ # Match on the path only, so "/manual.pdf?download=1#page=2" counts.
+ if urlparse(absolute).path.lower().endswith(".pdf"):
+ pdf_links.append(absolute)
+ return pdf_links
+
+ def _fetch_raw(self, url: str) -> tuple[bytes, str]:
+ """Fetch a URL with redirect following, SSRF protection and a response size cap.
+
+ Every hop is validated by ``assert_url_is_safe`` and the resolved address is
+ pinned for the duration of the request (DNS rebinding protection). The body
+ is streamed and rejected once it exceeds ``_MAX_RESPONSE_BYTES``.
+
+ Returns (content, content_type).
+ """
+ current_url = url
+ current_hostname, current_ip = assert_url_is_safe(current_url)
+
+ response: requests.Response | None = None
+ for _ in range(_MAX_REDIRECTS + 1):
+ with _pin_dns(current_hostname, current_ip):
+ response = self._session.get(
+ current_url,
+ timeout=REQUEST_TIMEOUT_SECONDS,
+ allow_redirects=False,
+ stream=True,
+ headers={"User-Agent": self.user_agent},
+ )
+ if response.status_code not in (301, 302, 303, 307, 308):
+ response.raise_for_status()
+ content_type = response.headers.get("Content-Type", "").lower()
+ return self._read_capped(response, current_url), content_type
+ response.close()
+ location = response.headers.get("Location")
+ if not location:
+ response.raise_for_status()
+ raise ValueError(f"Redirect without Location header fetching {url!r}")
+ redirect_url = urljoin(current_url, location)
+ current_hostname, current_ip = assert_url_is_safe(redirect_url)
+ current_url = redirect_url
+ raise ValueError(f"Exceeded {_MAX_REDIRECTS} redirects fetching {url!r}")
+
+ def _read_capped(self, response: requests.Response, url: str) -> bytes:
+ """Read a streamed response body, refusing anything larger than _MAX_RESPONSE_BYTES.
+
+ Stops early (raising ``ValueError``) when :meth:`cancel` was called.
+ """
+ declared = response.headers.get("Content-Length")
+ if declared and declared.isdigit() and int(declared) > _MAX_RESPONSE_BYTES:
+ response.close()
+ raise ValueError(f"Response for {url!r} exceeds the maximum allowed size of {_MAX_RESPONSE_BYTES} bytes")
+ chunks: list[bytes] = []
+ total = 0
+ try:
+ for chunk in response.iter_content(chunk_size=_READ_CHUNK_BYTES):
+ if self._cancel.is_set():
+ raise ValueError(f"Fetch of {url!r} cancelled")
+ if not chunk:
+ continue
+ total += len(chunk)
+ if total > _MAX_RESPONSE_BYTES:
+ raise ValueError(f"Response for {url!r} exceeds the maximum allowed size of {_MAX_RESPONSE_BYTES} bytes")
+ chunks.append(chunk)
+ finally:
+ response.close()
+ return b"".join(chunks)
+
+ @staticmethod
+ def _validate_url(url: str) -> tuple[str, str]:
+ if not url:
+ raise ValueError("URL is required")
+ parsed = urlparse(url)
+ if parsed.scheme not in {"http", "https"} or not parsed.netloc:
+ raise ValueError(f"URL must be a valid http or https URL: {url!r}")
+ return assert_url_is_safe(url)
+
+ def _url_matches(self, url: str) -> bool:
+ if self._url_filter is None:
+ return True
+ try:
+ return bool(self._url_filter.search(url[:_MAX_MATCHED_URL_LENGTH], timeout=_URL_FILTER_TIMEOUT_SECONDS))
+ except TimeoutError:
+ logger.warning("url_filter evaluation timed out after %ss on %s; URL skipped", _URL_FILTER_TIMEOUT_SECONDS, url[:200])
+ return False
+
+ @staticmethod
+ def _url_to_identifier(url: str) -> str:
+ parsed = urlparse(url)
+ identifier = f"{parsed.netloc}{parsed.path}"
+ if parsed.query:
+ identifier += f"?{parsed.query}"
+ if parsed.fragment:
+ identifier += f"#{parsed.fragment}"
+ return identifier.strip("/") or url
+
+ @staticmethod
+ def _build_document_id(url: str) -> str:
+ return f"sitemap:{hashlib.md5(url.encode('utf-8')).hexdigest()}"
+
+ @staticmethod
+ def _parse_lastmod(value: str) -> datetime | None:
+ for fmt in ("%Y-%m-%dT%H:%M:%S.%f%z", "%Y-%m-%dT%H:%M:%S.%fZ", "%Y-%m-%dT%H:%M:%S%z", "%Y-%m-%dT%H:%M:%SZ", "%Y-%m-%d"):
+ try:
+ dt = datetime.strptime(value, fmt) # noqa: DTZ007 - tz set explicitly below
+ if dt.tzinfo is None:
+ dt = dt.replace(tzinfo=UTC)
+ return dt.astimezone(UTC)
+ except ValueError:
+ continue
+ logger.debug("Unrecognised lastmod format: %r", value)
+ return None
diff --git a/docs/guides/data_source/data_source_categories_and_selection.md b/docs/guides/data_source/data_source_categories_and_selection.md
index d5db580887..8949f8d8b9 100644
--- a/docs/guides/data_source/data_source_categories_and_selection.md
+++ b/docs/guides/data_source/data_source_categories_and_selection.md
@@ -24,6 +24,6 @@ RAGFlow supports many data sources. It is recommended to first select a major ca
**Business systems and tables**: Used to synchronize CRM, tickets, online tables, courses, or operation records. This category is suitable for building business ledgers and service knowledge bases. It includes Salesforce, Airtable, Dingtalk AI Table, Zendesk, and Moodle.
-**General APIs and subscriptions**: Used to connect custom APIs, X search results, or public subscription feeds. This category is suitable for business systems without standard connectors and for collecting public content. It includes REST API, Xquik, and RSS.
+**General APIs and subscriptions**: Used to connect custom APIs, X search results, or public subscription feeds. This category is suitable for business systems without standard connectors and for collecting public content. It includes REST API, Xquik, RSS, and Sitemap.
Account version note: In this manual, **Personal Edition** and **Enterprise Edition** refer to the external system account or service version, not the RAGFlow license. Whether synchronization is available ultimately depends on whether the external system allows the current account to access the target content and API.
diff --git a/docs/guides/data_source/data_source_configuration.md b/docs/guides/data_source/data_source_configuration.md
index f7f762fea8..5751793678 100644
--- a/docs/guides/data_source/data_source_configuration.md
+++ b/docs/guides/data_source/data_source_configuration.md
@@ -699,3 +699,26 @@ The RSS data source is used to subscribe public websites, blogs, announcements,
- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.
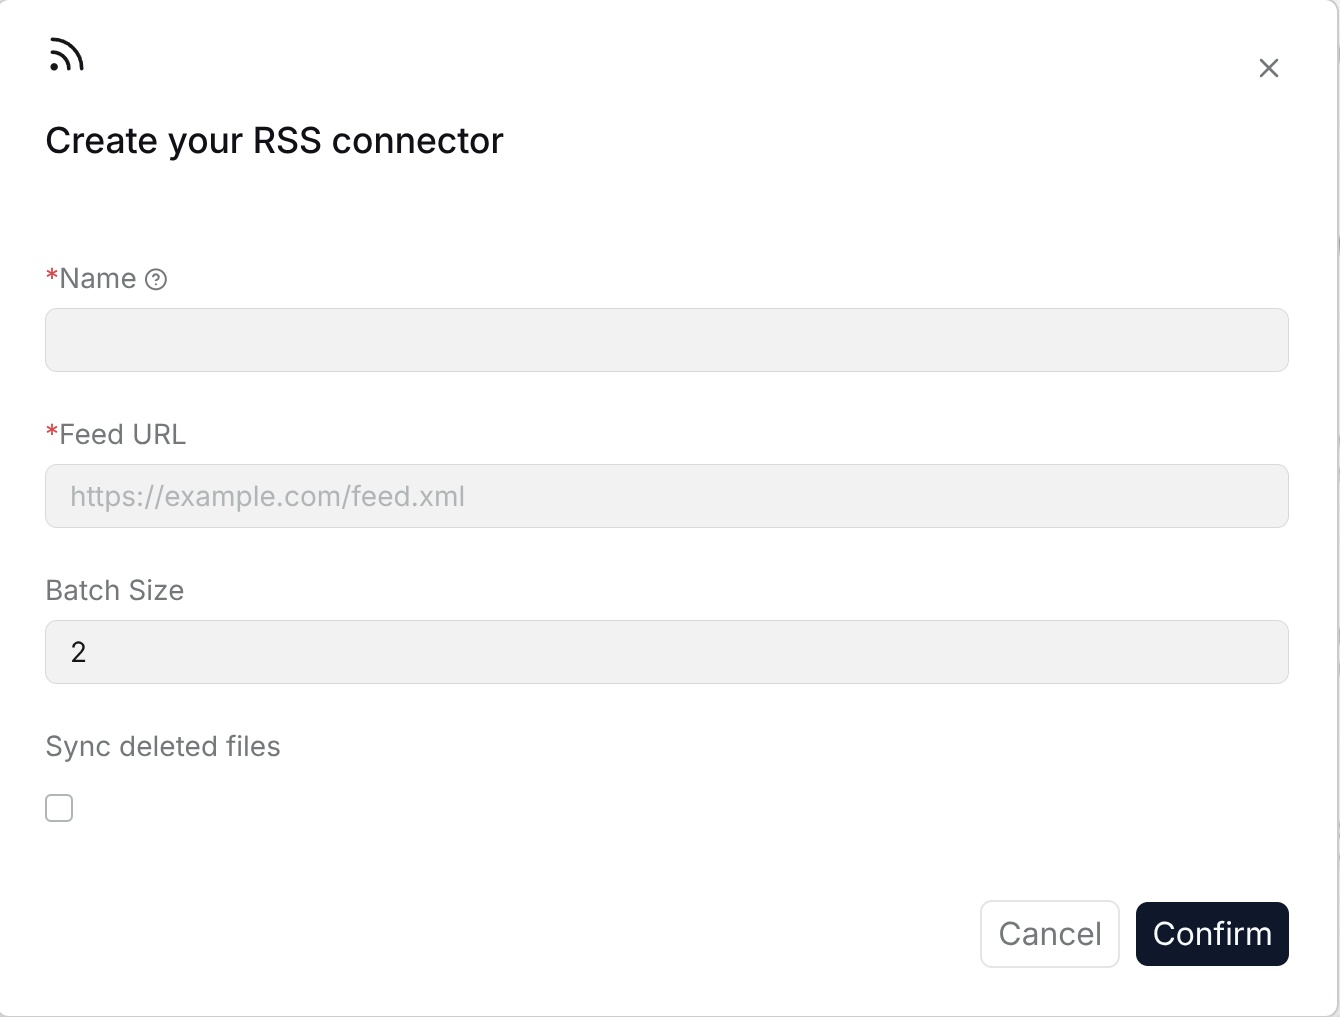
+
+## Sitemap
+
+The Sitemap data source is used to synchronize the web pages listed in a public `sitemap.xml` to a RAGFlow knowledge base. It is the simplest way to index a documentation site, a corporate website, or a blog without writing a crawler: the site itself declares which pages exist and when they were last modified.
+
+**Permission requirements**: The sitemap and the pages it lists must be reachable over HTTP or HTTPS from the RAGFlow server. No credentials are used. Every request is checked by the SSRF guard, so private or loopback addresses are rejected.
+
+**Account version requirements**: None. Sitemaps are a public XML standard ([sitemaps.org](https://www.sitemaps.org/protocol.html)); both plain `urlset` files and `sitemapindex` files (followed recursively, up to 5 levels) are supported.
+
+**Configuration parameters**:
+
+- **Name**: Customize the name in RAGFlow to identify this Sitemap connection.
+- **Sitemap URL**: The URL of the `sitemap.xml` or sitemap index to crawl, for example `https://example.com/sitemap.xml`.
+- **URL filter (regex)**: Optional regular expression. Only URLs matching it are indexed, for example `^https://example\.com/docs/` to restrict the sync to one section of the site. The connection test fails when no URL matches. The pattern is limited to 512 characters, nested quantifiers such as `(a+)+` are refused, and it is evaluated with a 1-second timeout against the first 4,096 characters of each URL.
+- **Follow PDF links**: When enabled, PDF files linked from the crawled HTML pages are indexed as well. Each PDF is indexed once even when several pages link to it.
+- **Restrict PDFs to sitemap domain**: When enabled (default), only PDF links hosted on the same domain as the sitemap are followed.
+- **User-Agent**: The `User-Agent` header sent with every request. Leave empty to use `RAGFlow-SitemapConnector/1.0`. Set it when the target site filters unknown crawlers.
+- **Batch size**: The number of pages fetched and sent to RAGFlow per batch.
+- **Sync deleted files**: After this is enabled, pages removed from the sitemap are removed from the knowledge base index.
+
+Every request goes through the SSRF guard with the resolved address pinned for the duration of the request, response bodies are capped at 64 MB, and at most 1000 sitemap documents are fetched per sync (each sitemap URL once). HTML pages are converted to Markdown with the same boilerplate removal as the other web connectors (`WEB_CONNECTOR_IGNORED_ELEMENTS`: navigation, footer, aside, scripts and styles by default) and stored as `.md` documents. URLs served with `Content-Type: application/pdf` are stored as `.pdf` documents and processed by the regular PDF pipeline. Each document keeps the page URL, the sitemap URL, and, for discovered PDFs, the parent page URL in its metadata.
+
+Incremental syncs rely on the `<lastmod>` element: only pages whose `lastmod` falls inside the sync window are fetched again, and pages without `lastmod` are only fetched by a full sync. Every document also carries a content fingerprint, so a page that is fetched again but has not changed is skipped instead of being re-indexed.
diff --git a/internal/syncer/connector/builtin.go b/internal/syncer/connector/builtin.go
index 2f68bf45c4..68144a4beb 100644
--- a/internal/syncer/connector/builtin.go
+++ b/internal/syncer/connector/builtin.go
@@ -28,6 +28,7 @@ import (
func RegisterBuiltIns(registry *Registry) {
registerBuiltIn(registry, "confluence", NewConfluenceConnector)
registerBuiltIn(registry, "rss", NewRSSConnector)
+ registerBuiltIn(registry, "sitemap", NewSitemapConnector)
registerBuiltIn(registry, "salesforce", NewSalesforceConnector)
registerBuiltIn(registry, "bitbucket", NewBitbucketConnector)
registerBuiltIn(registry, "azure_devops", NewAzureDevOpsConnector)
diff --git a/internal/syncer/connector/sitemap.go b/internal/syncer/connector/sitemap.go
new file mode 100644
index 0000000000..3109eec854
--- /dev/null
+++ b/internal/syncer/connector/sitemap.go
@@ -0,0 +1,765 @@
+//
+// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+//
+
+package connector
+
+import (
+ "bytes"
+ "context"
+ "crypto/md5"
+ "encoding/hex"
+ "encoding/xml"
+ "fmt"
+ "io"
+ "log/slog"
+ "net/http"
+ "net/url"
+ "regexp"
+ "strings"
+ "time"
+
+ "ragflow/internal/utility"
+
+ md "github.com/JohannesKaufmann/html-to-markdown"
+ "golang.org/x/net/html"
+)
+
+const (
+ defaultSitemapBatchSize = 10
+ defaultSitemapUserAgent = "RAGFlow-SitemapConnector/1.0"
+ maxSitemapDepth = 5
+ maxSitemapFetches = 1000
+ maxSitemapRedirects = 10
+ maxSitemapFileSize = 64 * 1024 * 1024
+ sitemapFetchTimeout = 60 * time.Second
+)
+
+// sitemapFetchFunc downloads one URL and returns its body and Content-Type.
+type sitemapFetchFunc func(ctx context.Context, rawURL string) ([]byte, string, error)
+
+// sitemapAssertURLSafe is the SSRF guard, indirected so tests can stub DNS resolution.
+var sitemapAssertURLSafe = utility.AssertURLSafe
+
+// SitemapConnector ingests the web pages listed in a sitemap.xml.
+//
+// It supports plain urlset sitemaps and sitemapindex files (recursively, up to
+// maxSitemapDepth levels), incremental polling via <lastmod>, HTML to Markdown
+// extraction, PDF documents served directly, and optional discovery of PDF
+// links inside HTML pages. Sitemaps are a public XML standard (sitemaps.org),
+// so there is no vendor SDK: every request is a plain HTTP GET guarded by the
+// shared SSRF checks.
+type SitemapConnector struct {
+ sitemapURL string
+ batchSize int
+ userAgent string
+ urlFilter *regexp.Regexp
+ followPDFLinks bool
+ restrictPDFToDomain bool
+
+ fetch sitemapFetchFunc
+}
+
+// NewSitemapConnector creates a sitemap connector from Python-compatible config.
+func NewSitemapConnector(config map[string]any) (*SitemapConnector, error) {
+ sitemapURL := strings.TrimSpace(stringConfig(config["sitemap_url"]))
+ userAgent := strings.TrimSpace(stringConfig(config["user_agent"]))
+ if userAgent == "" {
+ userAgent = defaultSitemapUserAgent
+ }
+
+ var urlFilter *regexp.Regexp
+ if pattern := strings.TrimSpace(stringConfig(config["url_filter"])); pattern != "" {
+ compiled, err := regexp.Compile(pattern)
+ if err != nil {
+ return nil, fmt.Errorf("url_filter is not a valid regex: %w", err)
+ }
+ urlFilter = compiled
+ }
+
+ connector := &SitemapConnector{
+ sitemapURL: sitemapURL,
+ batchSize: configInt(config["batch_size"], defaultSitemapBatchSize),
+ userAgent: userAgent,
+ urlFilter: urlFilter,
+ followPDFLinks: configBoolDefault(config["follow_pdf_links"], false),
+ restrictPDFToDomain: configBoolDefault(config["restrict_pdf_to_domain"], true),
+ }
+ connector.fetch = connector.fetchRemote
+ return connector, nil
+}
+
+// Validate validates sitemap settings and checks that the sitemap lists at
+// least one URL accepted by the filter.
+func (c *SitemapConnector) Validate(ctx context.Context) error {
+ if c == nil {
+ return fmt.Errorf("sitemap connector is nil")
+ }
+ if c.sitemapURL == "" {
+ return fmt.Errorf("sitemap URL is required")
+ }
+ if err := validateSitemapURL(c.sitemapURL); err != nil {
+ return err
+ }
+ if c.batchSize <= 0 {
+ return fmt.Errorf("batch_size must be a positive integer")
+ }
+
+ entries, err := c.listEntries(ctx)
+ if err != nil {
+ return err
+ }
+ for _, entry := range entries {
+ if c.urlMatches(entry.loc) {
+ return nil
+ }
+ }
+ return fmt.Errorf("sitemap contains no URLs matching the filter")
+}
+
+// ValidateConnectorSetting validates sitemap settings from an unsaved config.
+func (c *SitemapConnector) ValidateConnectorSetting(ctx context.Context, request map[string]any) error {
+ ctx, cancel := context.WithTimeout(ctx, connectorSettingValidationTimeout)
+ defer cancel()
+ return c.Validate(ctx)
+}
+
+// OpenSync opens one sitemap sync session.
+//
+// Page bodies are fetched lazily, batch by batch, inside NextBatch so that a
+// large sitemap never has to be materialized in memory. Documents carry a
+// content fingerprint, so unchanged pages are skipped by the runner before
+// being re-indexed even when the sitemap exposes no usable <lastmod>.
+func (c *SitemapConnector) OpenSync(ctx context.Context, request SyncRequest) (SyncSession, error) {
+ entries, err := c.listEntries(ctx)
+ if err != nil {
+ return nil, err
+ }
+
+ incremental := !request.FromBeginning && request.WindowStart != nil
+ pending := make([]sitemapEntry, 0, len(entries))
+ for _, entry := range entries {
+ if incremental {
+ // Pages without <lastmod> cannot be attributed to a window; they are
+ // only picked up by a full sync, exactly like the Python connector.
+ if entry.lastmod.IsZero() {
+ continue
+ }
+ if beforeOrAtWindowStart(entry.lastmod, request.WindowStart) || afterWindowEnd(entry.lastmod, request.WindowEnd) {
+ continue
+ }
+ }
+ pending = append(pending, entry)
+ }
+
+ session := &sitemapSyncSession{
+ connector: c,
+ pending: pending,
+ seen: make(map[string]struct{}, len(entries)),
+ }
+ for _, entry := range entries {
+ session.seen[entry.loc] = struct{}{}
+ }
+ if err := session.applyResume(request.Resume); err != nil {
+ return nil, err
+ }
+ return session, nil
+}
+
+// OpenPrune opens one complete sitemap prune snapshot session.
+//
+// When PDF link discovery is enabled the HTML pages are fetched so that the
+// discovered PDFs are part of the retained set; otherwise they would be pruned
+// as stale right after being indexed.
+func (c *SitemapConnector) OpenPrune(ctx context.Context, request PruneRequest) (PruneSession, error) {
+ entries, err := c.listEntries(ctx)
+ if err != nil {
+ return nil, err
+ }
+
+ documents := make([]SlimDocument, 0, len(entries))
+ seen := make(map[string]struct{}, len(entries))
+ for _, entry := range entries {
+ seen[entry.loc] = struct{}{}
+ if !c.urlMatches(entry.loc) {
+ continue
+ }
+ documents = append(documents, SlimDocument{SourceID: sitemapSourceID(entry.loc)})
+ }
+
+ if c.followPDFLinks {
+ for _, entry := range entries {
+ if !c.urlMatches(entry.loc) {
+ continue
+ }
+ body, contentType, err := c.fetch(ctx, entry.loc)
+ if err != nil {
+ slog.Warn("sitemap prune: failed to fetch page for PDF discovery", "url", entry.loc, "error", err)
+ continue
+ }
+ if isPDFResponse(contentType, body) {
+ continue
+ }
+ for _, pdfURL := range c.discoverPDFLinks(body, entry.loc) {
+ if _, exists := seen[pdfURL]; exists {
+ continue
+ }
+ seen[pdfURL] = struct{}{}
+ documents = append(documents, SlimDocument{SourceID: sitemapSourceID(pdfURL)})
+ }
+ }
+ }
+
+ return &sitemapPruneSession{documents: documents, batchSize: c.batchSize}, nil
+}
+
+// listEntries walks the sitemap (and nested sitemap indexes) and returns the
+// deduplicated entries in document order. url_filter is applied by callers.
+//
+// Every sitemap URL is fetched at most once (a sitemapindex that references
+// itself or an ancestor is skipped) and the walk stops after maxSitemapFetches
+// sitemap documents, so one connector configuration cannot trigger unbounded
+// egress.
+func (c *SitemapConnector) listEntries(ctx context.Context) ([]sitemapEntry, error) {
+ var (
+ entries []sitemapEntry
+ seen = make(map[string]struct{})
+ visited = make(map[string]struct{})
+ fetched int
+ )
+ var walk func(sitemapURL string, depth int) error
+ walk = func(sitemapURL string, depth int) error {
+ if depth > maxSitemapDepth {
+ slog.Warn("sitemap: max depth reached, stopping", "url", sitemapURL)
+ return nil
+ }
+ if _, done := visited[sitemapURL]; done {
+ slog.Warn("sitemap: nested sitemap already visited, skipping", "url", sitemapURL)
+ return nil
+ }
+ visited[sitemapURL] = struct{}{}
+ if fetched >= maxSitemapFetches {
+ slog.Warn("sitemap: maximum number of sitemap fetches reached, stopping", "url", sitemapURL, "max", maxSitemapFetches)
+ return nil
+ }
+ if err := validateSitemapURL(sitemapURL); err != nil {
+ if depth == 0 {
+ return err
+ }
+ slog.Warn("sitemap: skipping invalid nested sitemap URL", "url", sitemapURL, "error", err)
+ return nil
+ }
+ body, _, err := c.fetch(ctx, sitemapURL)
+ if err != nil {
+ if depth == 0 {
+ return fmt.Errorf("failed to fetch sitemap %s: %w", sitemapURL, err)
+ }
+ slog.Warn("sitemap: failed to fetch nested sitemap", "url", sitemapURL, "error", err)
+ return nil
+ }
+ fetched++
+
+ document, err := parseSitemapXML(body)
+ if err != nil {
+ return fmt.Errorf("failed to parse sitemap XML from %s: %w", sitemapURL, err)
+ }
+ if document.isIndex {
+ for _, child := range document.sitemaps {
+ if err := walk(child, depth+1); err != nil {
+ return err
+ }
+ }
+ return nil
+ }
+ for _, entry := range document.entries {
+ if _, exists := seen[entry.loc]; exists {
+ continue
+ }
+ seen[entry.loc] = struct{}{}
+ entries = append(entries, entry)
+ }
+ return nil
+ }
+ if err := walk(c.sitemapURL, 0); err != nil {
+ return nil, err
+ }
+ if fetched == 0 {
+ return nil, fmt.Errorf("failed to fetch sitemap %s", c.sitemapURL)
+ }
+ return entries, nil
+}
+
+// urlMatches reports whether a URL passes the optional url_filter regex.
+func (c *SitemapConnector) urlMatches(rawURL string) bool {
+ return c.urlFilter == nil || c.urlFilter.MatchString(rawURL)
+}
+
+// buildDocument downloads one URL and converts it into a source document.
+// It returns nil when the page must be skipped (fetch error or empty content).
+func (c *SitemapConnector) buildDocument(ctx context.Context, rawURL string, lastmod time.Time, parentURL string) (*SourceDocument, []string) {
+ if err := validateSitemapURL(rawURL); err != nil {
+ slog.Warn("sitemap: skipping invalid page URL", "url", rawURL, "error", err)
+ return nil, nil
+ }
+ body, contentType, err := c.fetch(ctx, rawURL)
+ if err != nil {
+ slog.Warn("sitemap: failed to fetch page", "url", rawURL, "error", err)
+ return nil, nil
+ }
+
+ updatedAt := lastmod
+ if updatedAt.IsZero() {
+ updatedAt = time.Now().UTC()
+ }
+
+ var (
+ blob []byte
+ extension string
+ pdfLinks []string
+ )
+ if isPDFResponse(contentType, body) {
+ if len(body) == 0 {
+ slog.Debug("sitemap: empty PDF, skipping", "url", rawURL)
+ return nil, nil
+ }
+ blob = body
+ extension = ".pdf"
+ } else {
+ if c.followPDFLinks {
+ pdfLinks = c.discoverPDFLinks(body, rawURL)
+ }
+ text, err := sitemapHTMLToMarkdown(body)
+ if err != nil {
+ slog.Warn("sitemap: failed to parse page", "url", rawURL, "error", err)
+ return nil, pdfLinks
+ }
+ if strings.TrimSpace(text) == "" {
+ slog.Debug("sitemap: empty content, skipping", "url", rawURL)
+ return nil, pdfLinks
+ }
+ blob = []byte(text)
+ extension = ".md"
+ }
+
+ metadata := map[string]any{
+ "sitemap_url": c.sitemapURL,
+ "url": rawURL,
+ }
+ if parentURL != "" {
+ metadata["parent_url"] = parentURL
+ }
+ return &SourceDocument{
+ SourceID: sitemapSourceID(rawURL),
+ SemanticIdentifier: sitemapSemanticIdentifier(rawURL),
+ Extension: extension,
+ Blob: blob,
+ UpdatedAt: updatedAt,
+ SizeBytes: int64(len(blob)),
+ Metadata: metadata,
+ Fingerprint: contentFingerprint(blob),
+ }, pdfLinks
+}
+
+// discoverPDFLinks returns the absolute PDF links found in an HTML page that
+// pass the optional same-domain restriction.
+func (c *SitemapConnector) discoverPDFLinks(body []byte, pageURL string) []string {
+ links := extractPDFLinks(body, pageURL)
+ if !c.restrictPDFToDomain {
+ return links
+ }
+ sitemapHost := hostOf(c.sitemapURL)
+ filtered := links[:0]
+ for _, link := range links {
+ if hostOf(link) == sitemapHost {
+ filtered = append(filtered, link)
+ }
+ }
+ return filtered
+}
+
+// fetchRemote downloads rawURL with SSRF protection, manual redirect handling
+// that re-validates every hop, the configured User-Agent, and a hard size cap.
+func (c *SitemapConnector) fetchRemote(ctx context.Context, rawURL string) ([]byte, string, error) {
+ currentURL := rawURL
+ for redirects := 0; redirects <= maxSitemapRedirects; redirects++ {
+ hostname, resolvedIP, err := sitemapAssertURLSafe(currentURL)
+ if err != nil {
+ return nil, "", err
+ }
+ client := utility.PinnedHTTPClient(hostname, resolvedIP, sitemapFetchTimeout)
+ client.CheckRedirect = func(req *http.Request, via []*http.Request) error {
+ return http.ErrUseLastResponse
+ }
+
+ req, err := http.NewRequestWithContext(ctx, http.MethodGet, currentURL, nil)
+ if err != nil {
+ return nil, "", fmt.Errorf("failed to create request: %w", err)
+ }
+ req.Header.Set("User-Agent", c.userAgent)
+ resp, err := client.Do(req) // `#nosec` G107
+ if err != nil {
+ return nil, "", fmt.Errorf("failed to fetch URL: %w", err)
+ }
+
+ switch resp.StatusCode {
+ case http.StatusMovedPermanently, http.StatusFound, http.StatusSeeOther, http.StatusTemporaryRedirect, http.StatusPermanentRedirect:
+ location := resp.Header.Get("Location")
+ resp.Body.Close()
+ if location == "" {
+ return nil, "", fmt.Errorf("redirect response missing Location header")
+ }
+ base, parseErr := url.Parse(currentURL)
+ if parseErr != nil {
+ return nil, "", parseErr
+ }
+ next, resolveErr := base.Parse(location)
+ if resolveErr != nil {
+ return nil, "", resolveErr
+ }
+ currentURL = next.String()
+ continue
+ }
+
+ if resp.StatusCode >= 400 {
+ resp.Body.Close()
+ return nil, "", fmt.Errorf("remote URL returned HTTP %d", resp.StatusCode)
+ }
+ data, readErr := io.ReadAll(io.LimitReader(resp.Body, maxSitemapFileSize+1))
+ contentType := strings.ToLower(resp.Header.Get("Content-Type"))
+ resp.Body.Close()
+ if readErr != nil {
+ return nil, "", fmt.Errorf("failed to read remote content: %w", readErr)
+ }
+ if int64(len(data)) > maxSitemapFileSize {
+ return nil, "", fmt.Errorf("remote file exceeds the maximum allowed size of %d bytes", maxSitemapFileSize)
+ }
+ return data, contentType, nil
+ }
+ return nil, "", fmt.Errorf("exceeded %d redirects fetching %s", maxSitemapRedirects, rawURL)
+}
+
+// sitemapSyncSession streams sitemap pages and then the PDFs discovered in them.
+type sitemapSyncSession struct {
+ connector *SitemapConnector
+
+ pending []sitemapEntry // sitemap URLs still to fetch
+ index int
+
+ seen map[string]struct{}
+ pendingPDFs []sitemapPDFLink // discovered PDFs, emitted after the sitemap pass
+ pdfIndex int
+}
+
+// sitemapPDFLink is a PDF discovered inside an HTML page.
+type sitemapPDFLink struct {
+ url string
+ parentURL string
+}
+
+// NextBatch fetches and returns the next batch of documents.
+func (s *sitemapSyncSession) NextBatch(ctx context.Context) (SyncBatch, error) {
+ batchSize := s.connector.batchSize
+ documents := make([]SourceDocument, 0, batchSize)
+
+ for s.index < len(s.pending) && len(documents) < batchSize {
+ if err := ctx.Err(); err != nil {
+ return SyncBatch{}, err
+ }
+ entry := s.pending[s.index]
+ s.index++
+ if !s.connector.urlMatches(entry.loc) {
+ continue
+ }
+ doc, pdfLinks := s.connector.buildDocument(ctx, entry.loc, entry.lastmod, "")
+ for _, pdfURL := range pdfLinks {
+ if _, exists := s.seen[pdfURL]; exists {
+ continue
+ }
+ s.seen[pdfURL] = struct{}{}
+ s.pendingPDFs = append(s.pendingPDFs, sitemapPDFLink{url: pdfURL, parentURL: entry.loc})
+ }
+ if doc != nil {
+ documents = append(documents, *doc)
+ }
+ }
+
+ if len(documents) == 0 {
+ for s.pdfIndex < len(s.pendingPDFs) && len(documents) < batchSize {
+ if err := ctx.Err(); err != nil {
+ return SyncBatch{}, err
+ }
+ link := s.pendingPDFs[s.pdfIndex]
+ s.pdfIndex++
+ doc, _ := s.connector.buildDocument(ctx, link.url, time.Time{}, link.parentURL)
+ if doc != nil {
+ documents = append(documents, *doc)
+ }
+ }
+ }
+
+ if len(documents) == 0 {
+ return SyncBatch{}, io.EOF
+ }
+ return SyncBatch{Documents: documents, Checkpoint: sitemapSyncCheckpoint(documents[len(documents)-1])}, nil
+}
+
+// Close closes the sitemap sync session.
+func (s *sitemapSyncSession) Close() error {
+ return nil
+}
+
+// applyResume advances past the last committed sitemap page when retrying a task.
+//
+// Only sitemap-listed URLs can anchor a resume: PDFs discovered inside pages are
+// not known before those pages are fetched, so a checkpoint taken during the
+// PDF pass anchors on the last sitemap page instead and the PDF pass replays.
+func (s *sitemapSyncSession) applyResume(checkpoint *SyncCheckpoint) error {
+ if checkpoint == nil {
+ return nil
+ }
+ sourceID := firstNonEmpty(checkpoint.SourceID, checkpoint.Cursor)
+ if sourceID == "" {
+ return fmt.Errorf("sitemap sync checkpoint has no source anchor: %w", ErrSyncResumeInvalid)
+ }
+ for index, entry := range s.pending {
+ if sitemapSourceID(entry.loc) == sourceID {
+ s.index = index + 1
+ return nil
+ }
+ }
+ return fmt.Errorf("sitemap resume anchor %q was not found in the current sitemap: %w", sourceID, ErrSyncResumeInvalid)
+}
+
+// sitemapSyncCheckpoint returns a resume point after a committed document.
+func sitemapSyncCheckpoint(doc SourceDocument) *SyncCheckpoint {
+ // Discovered PDFs carry parent_url; anchor on the parent page so the
+ // checkpoint always points at a sitemap-listed URL.
+ anchor := doc.SourceID
+ if parent, ok := doc.Metadata["parent_url"].(string); ok && parent != "" {
+ anchor = sitemapSourceID(parent)
+ }
+ updatedAt := doc.UpdatedAt
+ return &SyncCheckpoint{
+ Cursor: anchor,
+ SourceID: anchor,
+ UpdatedAt: &updatedAt,
+ }
+}
+
+type sitemapPruneSession struct {
+ documents []SlimDocument
+ batchSize int
+ index int
+}
+
+// NextBatch returns the next sitemap prune snapshot batch.
+func (s *sitemapPruneSession) NextBatch(ctx context.Context) (PruneBatch, error) {
+ if s.index >= len(s.documents) {
+ return PruneBatch{}, io.EOF
+ }
+ end := s.index + s.batchSize
+ if end > len(s.documents) {
+ end = len(s.documents)
+ }
+ batch := PruneBatch{Documents: s.documents[s.index:end]}
+ s.index = end
+ return batch, nil
+}
+
+// Close closes the sitemap prune session.
+func (s *sitemapPruneSession) Close() error {
+ return nil
+}
+
+// sitemapEntry is one <url> element of a urlset.
+type sitemapEntry struct {
+ loc string
+ lastmod time.Time
+}
+
+// sitemapDocument is a parsed sitemap or sitemap index.
+type sitemapDocument struct {
+ isIndex bool
+ sitemaps []string
+ entries []sitemapEntry
+}
+
+type sitemapXMLRoot struct {
+ XMLName xml.Name
+ Sitemaps []sitemapXMLLoc `xml:"sitemap"`
+ URLs []sitemapXMLURL `xml:"url"`
+}
+
+type sitemapXMLLoc struct {
+ Loc string `xml:"loc"`
+}
+
+type sitemapXMLURL struct {
+ Loc string `xml:"loc"`
+ Lastmod string `xml:"lastmod"`
+}
+
+// parseSitemapXML parses a urlset or sitemapindex payload.
+func parseSitemapXML(data []byte) (*sitemapDocument, error) {
+ var root sitemapXMLRoot
+ decoder := xml.NewDecoder(bytes.NewReader(data))
+ decoder.Strict = false
+ if err := decoder.Decode(&root); err != nil {
+ return nil, err
+ }
+ document := &sitemapDocument{}
+ switch strings.ToLower(root.XMLName.Local) {
+ case "sitemapindex":
+ document.isIndex = true
+ for _, item := range root.Sitemaps {
+ if loc := strings.TrimSpace(item.Loc); loc != "" {
+ document.sitemaps = append(document.sitemaps, loc)
+ }
+ }
+ case "urlset":
+ for _, item := range root.URLs {
+ loc := strings.TrimSpace(item.Loc)
+ if loc == "" {
+ continue
+ }
+ document.entries = append(document.entries, sitemapEntry{loc: loc, lastmod: parseSitemapLastmod(item.Lastmod)})
+ }
+ default:
+ return nil, fmt.Errorf("unexpected root element <%s>", root.XMLName.Local)
+ }
+ return document, nil
+}
+
+// parseSitemapLastmod parses W3C Datetime values used by <lastmod>.
+func parseSitemapLastmod(value string) time.Time {
+ value = strings.TrimSpace(value)
+ if value == "" {
+ return time.Time{}
+ }
+ layouts := []string{
+ time.RFC3339Nano,
+ time.RFC3339,
+ "2006-01-02T15:04:05.999999999",
+ "2006-01-02T15:04:05",
+ "2006-01-02T15:04Z07:00",
+ "2006-01-02T15:04",
+ "2006-01-02",
+ }
+ for _, layout := range layouts {
+ if parsed, err := time.Parse(layout, value); err == nil {
+ return parsed.UTC()
+ }
+ }
+ slog.Debug("sitemap: unrecognised lastmod format", "value", value)
+ return time.Time{}
+}
+
+// validateSitemapURL checks scheme/host shape and the SSRF guard.
+func validateSitemapURL(rawURL string) error {
+ if rawURL == "" {
+ return fmt.Errorf("URL is required")
+ }
+ parsed, err := url.Parse(rawURL)
+ if err != nil || parsed.Host == "" || (parsed.Scheme != "http" && parsed.Scheme != "https") {
+ return fmt.Errorf("URL must be a valid http or https URL: %q", rawURL)
+ }
+ if _, _, err := sitemapAssertURLSafe(rawURL); err != nil {
+ return err
+ }
+ return nil
+}
+
+// isPDFResponse reports whether a response is a PDF by Content-Type or magic bytes.
+func isPDFResponse(contentType string, body []byte) bool {
+ return strings.Contains(strings.ToLower(contentType), "application/pdf") || utility.BytesLooksLikePDF(body)
+}
+
+// sitemapSourceID returns the Python-compatible sitemap document ID.
+func sitemapSourceID(rawURL string) string {
+ sum := md5.Sum([]byte(rawURL))
+ return "sitemap:" + hex.EncodeToString(sum[:])
+}
+
+// sitemapSemanticIdentifier strips the scheme so the name is a valid storage key.
+func sitemapSemanticIdentifier(rawURL string) string {
+ parsed, err := url.Parse(rawURL)
+ if err != nil {
+ return rawURL
+ }
+ identifier := parsed.Host + parsed.Path
+ if parsed.RawQuery != "" {
+ identifier += "?" + parsed.RawQuery
+ }
+ if parsed.Fragment != "" {
+ identifier += "#" + parsed.Fragment
+ }
+ identifier = strings.Trim(identifier, "/")
+ if identifier == "" {
+ return rawURL
+ }
+ return identifier
+}
+
+// hostOf returns the lower-cased host of a URL, or "" when unparsable.
+func hostOf(rawURL string) string {
+ parsed, err := url.Parse(rawURL)
+ if err != nil {
+ return ""
+ }
+ return strings.ToLower(parsed.Host)
+}
+
+// sitemapHTMLToMarkdown converts a page to Markdown, dropping navigation chrome.
+func sitemapHTMLToMarkdown(body []byte) (string, error) {
+ converter := md.NewConverter("", true, &md.Options{EmDelimiter: "*"})
+ converter.Remove("script", "style", "noscript", "nav", "header", "footer", "aside", "form", "iframe", "svg")
+ out, err := converter.ConvertString(string(body))
+ if err != nil {
+ return "", err
+ }
+ return strings.TrimSpace(out), nil
+}
+
+// extractPDFLinks returns absolute <a href> links whose path ends in .pdf
+// (query strings and fragments are ignored, so "/manual.pdf?download=1" counts).
+func extractPDFLinks(body []byte, pageURL string) []string {
+ base, err := url.Parse(pageURL)
+ if err != nil {
+ return nil
+ }
+ var links []string
+ tokenizer := html.NewTokenizer(bytes.NewReader(body))
+ for {
+ switch tokenizer.Next() {
+ case html.ErrorToken:
+ return links
+ case html.StartTagToken, html.SelfClosingTagToken:
+ token := tokenizer.Token()
+ if token.Data != "a" {
+ continue
+ }
+ for _, attr := range token.Attr {
+ if attr.Key != "href" {
+ continue
+ }
+ resolved, err := base.Parse(strings.TrimSpace(attr.Val))
+ if err != nil || !strings.HasSuffix(strings.ToLower(resolved.Path), ".pdf") {
+ continue
+ }
+ links = append(links, resolved.String())
+ }
+ }
+ }
+}
diff --git a/internal/syncer/connector/sitemap_test.go b/internal/syncer/connector/sitemap_test.go
new file mode 100644
index 0000000000..fb9522a570
--- /dev/null
+++ b/internal/syncer/connector/sitemap_test.go
@@ -0,0 +1,454 @@
+//
+// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+//
+
+package connector
+
+import (
+ "context"
+ "crypto/md5"
+ "encoding/hex"
+ "errors"
+ "fmt"
+ "io"
+ "strings"
+ "testing"
+)
+
+// sitemapFixture is an in-memory site: URL -> (Content-Type, body).
+type sitemapFixture map[string][2]string
+
+func (f sitemapFixture) fetch(ctx context.Context, rawURL string) ([]byte, string, error) {
+ entry, ok := f[rawURL]
+ if !ok {
+ return nil, "", fmt.Errorf("not found: %s", rawURL)
+ }
+ return []byte(entry[1]), entry[0], nil
+}
+
+const sitemapTestIndex = `<?xml version="1.0" encoding="UTF-8"?>
+<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
+ <sitemap><loc>https://example.com/sitemap-pages.xml</loc></sitemap>
+ <sitemap><loc>https://example.com/sitemap-missing.xml</loc></sitemap>
+ <sitemap><loc>https://example.com/sitemap.xml</loc></sitemap>
+ <sitemap><loc>https://example.com/sitemap-pages.xml</loc></sitemap>
+</sitemapindex>`
+
+const sitemapTestURLSet = `<?xml version="1.0" encoding="UTF-8"?>
+<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
+ <url><loc>https://example.com/old</loc><lastmod>2026-01-01</lastmod></url>
+ <url><loc>https://example.com/new</loc><lastmod>2026-01-03T10:00:00.123Z</lastmod></url>
+ <url><loc>https://example.com/future</loc><lastmod>2026-01-06T00:00:00+00:00</lastmod></url>
+ <url><loc>https://example.com/undated</loc></url>
+ <url><loc>https://example.com/brochure.pdf</loc><lastmod>2026-01-02</lastmod></url>
+ <url><loc>https://example.com/new</loc></url>
+</urlset>`
+
+func newSitemapTestConnector(t *testing.T, config map[string]any, fixture sitemapFixture) *SitemapConnector {
+ t.Helper()
+ restore := sitemapAssertURLSafe
+ sitemapAssertURLSafe = func(rawURL string) (string, string, error) { return "example.com", "203.0.113.10", nil }
+ t.Cleanup(func() { sitemapAssertURLSafe = restore })
+
+ if _, ok := config["sitemap_url"]; !ok {
+ config["sitemap_url"] = "https://example.com/sitemap.xml"
+ }
+ connector, err := NewSitemapConnector(config)
+ if err != nil {
+ t.Fatalf("NewSitemapConnector failed: %v", err)
+ }
+ connector.fetch = fixture.fetch
+ return connector
+}
+
+func defaultSitemapFixture() sitemapFixture {
+ return sitemapFixture{
+ "https://example.com/sitemap.xml": {"application/xml", sitemapTestIndex},
+ "https://example.com/sitemap-pages.xml": {"application/xml", sitemapTestURLSet},
+ "https://example.com/old": {"text/html; charset=utf-8", `<html><head><title>OldOld page
Old body