mirror of
https://github.com/infiniflow/ragflow.git
synced 2026-11-12 06:10:52 +08:00
feat(chunker): support media context in title and manual pipelines (#21111)
This commit is contained in:
 Xinliang Zheng authored and
 GitHub committed
1 parent
6aeb92deff
commit
45b08b9cdf
19 files changed
+998
-21
No files matched your search
@@ -50,3 +50,51 @@ Use Title Chunker for documents with clear headings, such as manuals and papers.
|
||||
|
||||
|
||||
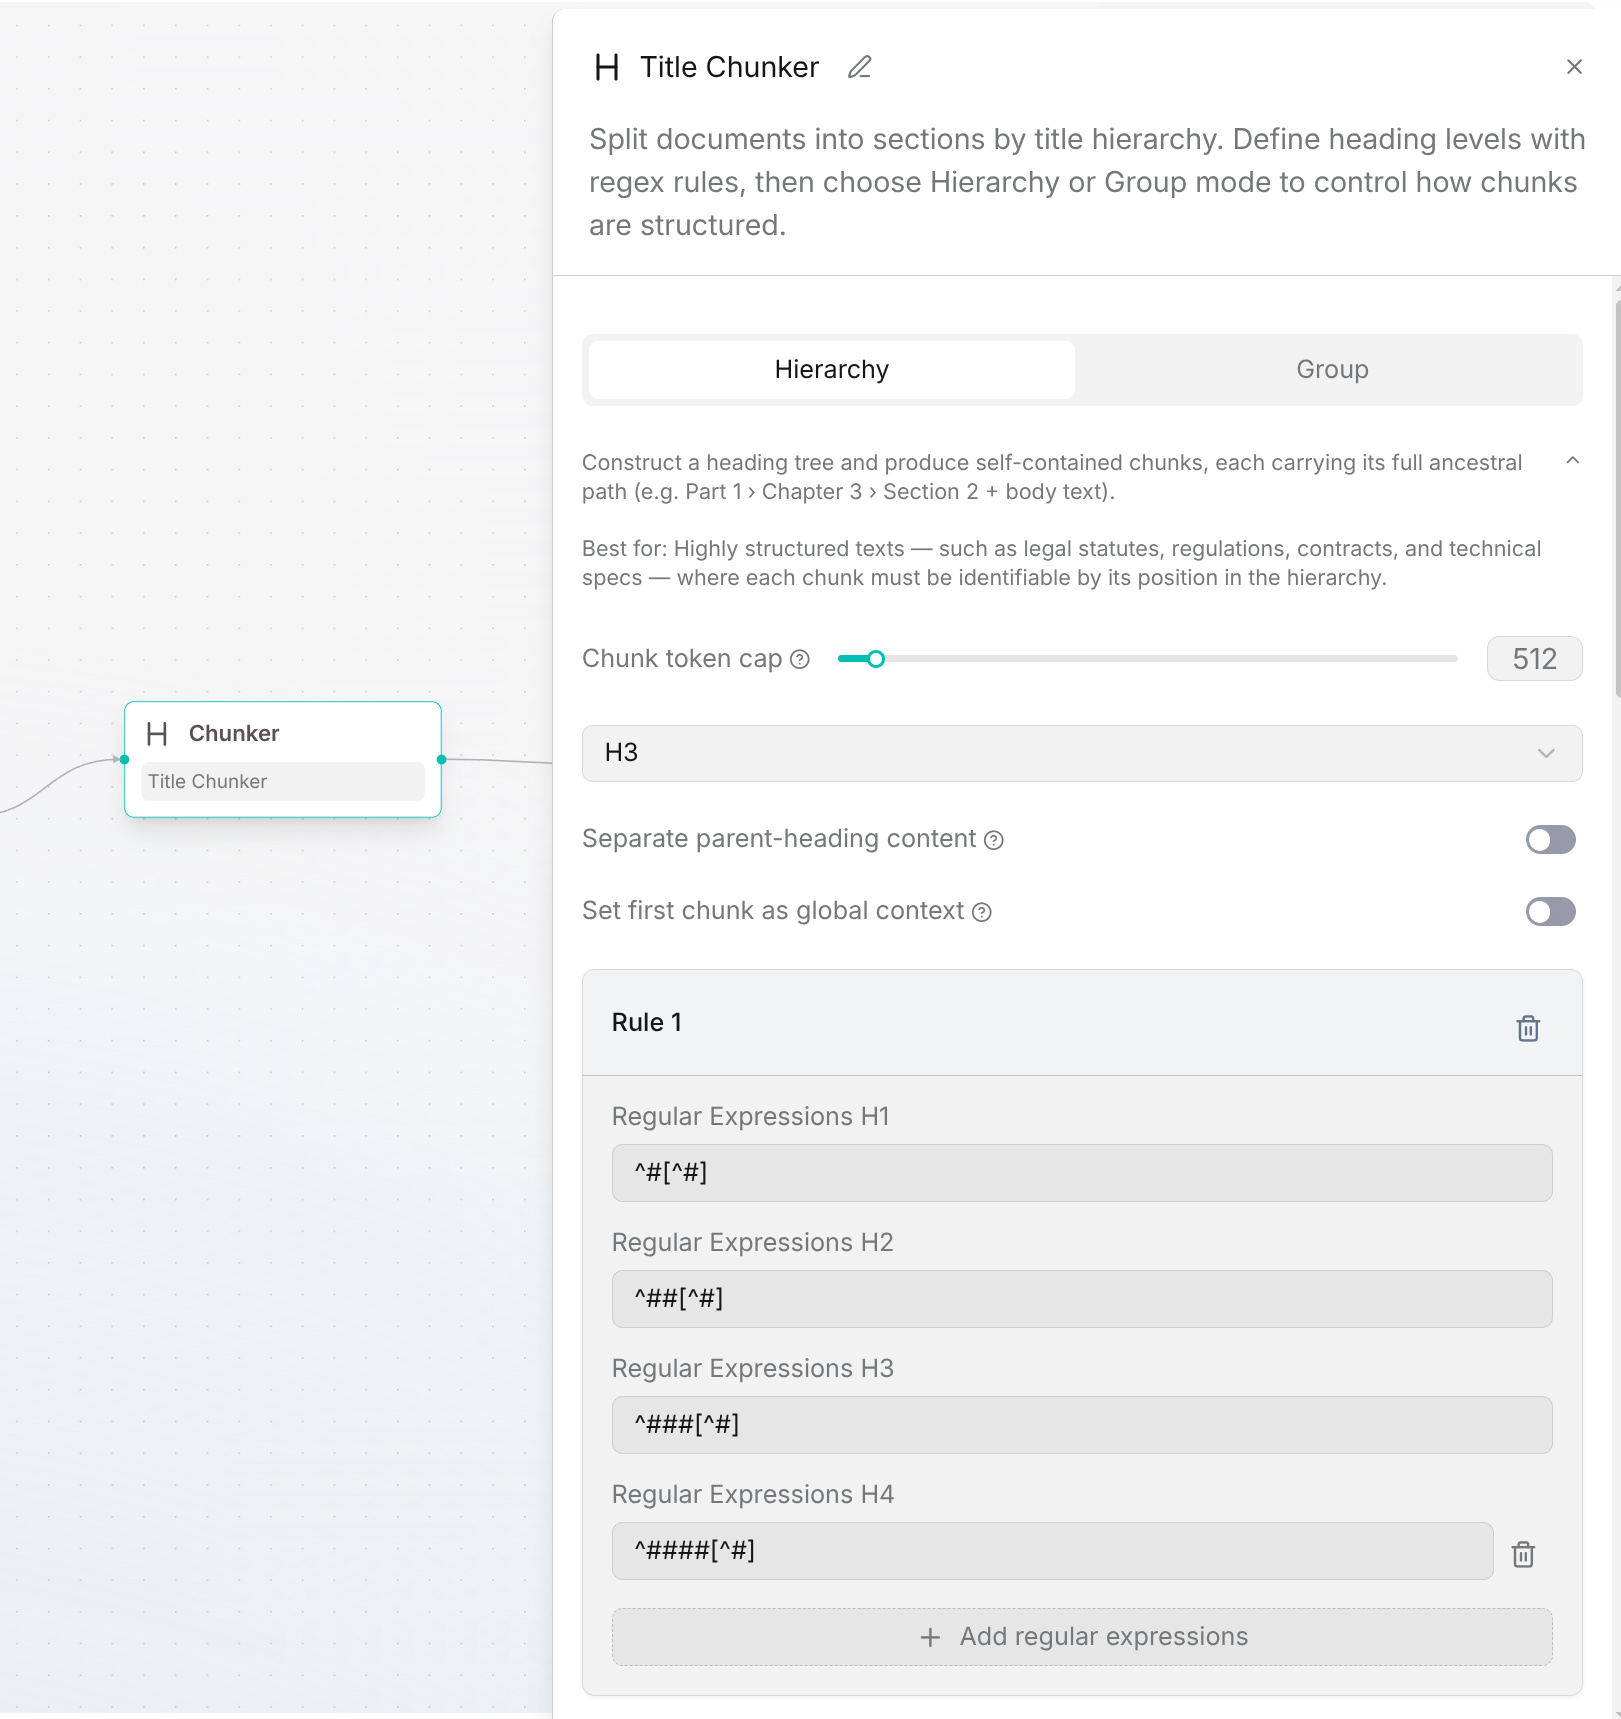
For Markdown headings, add `^# ` for level 1 and `^## ` for level 2, then select level 2. In Hierarchy mode, check that each subsection retains its parent heading. Use the output `chunks` in downstream components.
|
||||
|
||||
## Table and image context for books, papers and manuals
|
||||
|
||||
Title Chunker (both Hierarchy and Group) and Manual Chunker accept independent
|
||||
**Table context window** (`table_context_size`) and **Image context window**
|
||||
(`image_context_size`) settings. Both default to `0` (disabled); leaving them
|
||||
unset or explicitly zero preserves the existing output.
|
||||
Budgets must be non-negative integers; invalid API values fail component
|
||||
construction instead of being silently rounded or ignored.
|
||||
|
||||
A positive value is a token budget **for each side** of the corresponding media
|
||||
chunk. Text is collected from neighboring source records in document order,
|
||||
skipping other tables and images. Manual Chunker preserves parser-supplied reading
|
||||
order when marked; other records are sorted by page, top and left. Collection uses the same whole-sentence
|
||||
rules as General Chunker: `。!??;!`, newline and period followed by a space.
|
||||
The last selected sentence is kept whole even if it exceeds the remaining
|
||||
budget; a paragraph without a sentence boundary may therefore exceed it too.
|
||||
|
||||
Windows can cross headings and pages within the source document, but not
|
||||
spreadsheet sheet boundaries. Each invocation processes a single source file,
|
||||
with no context retained between documents. Context is collected before
|
||||
heading grouping and token-cap splitting, so generated heading copies are not
|
||||
used as neighbors. Text chunks keep their existing token-cap behavior; a media
|
||||
chunk remains atomic and its context is not trimmed by `chunk_token_cap`.
|
||||
|
||||
Selected text is separated from the table/image body with newlines and becomes
|
||||
part of that chunk's final text, token count and identifier before image
|
||||
cropping/upload. Original media payloads, references, positions and chunk order
|
||||
are preserved. Context text remains in its original text chunk as well.
|
||||
For a captionless image whose body consists only of context, the identifier also
|
||||
includes its original image payload/reference identity, so distinct images with
|
||||
the same neighbors cannot overwrite each other.
|
||||
|
||||
For example, component-scoped configuration for a book pipeline can enable
|
||||
table context while leaving image context off:
|
||||
|
||||
```json
|
||||
{
|
||||
"TitleChunker:GrumpyGarlicsBake": {
|
||||
"table_context_size": 64,
|
||||
"image_context_size": 0
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Use the actual component ID from the selected pipeline. The same parameters
|
||||
are accepted on the built-in book, paper and manual chunkers; no flat
|
||||
`parser_config` migration is required.
|
||||
@@ -356,21 +356,16 @@ func canonicalChunkText(ck schema.ChunkDoc) string {
|
||||
// keeps the source from colliding with ordinary chunk text.
|
||||
const mediaChunkIDPrefix = "\x00media:"
|
||||
|
||||
// canonicalChunkID returns the deterministic chunk id: the single identity
|
||||
// used both as the MinIO object key and as ck["id"]. The id formula (ChunkID
|
||||
// over chunkIDSource) is centralized here, so the identity that feeds the
|
||||
// hash lives in exactly one place. The decorator in register.go re-derives
|
||||
// ck["id"] from the same already-finalized text as a fallback for chunks that
|
||||
// bypassed the streamed crop-upload path; the two routes cannot disagree
|
||||
// because a chunk is either stamped by crop-upload (and the decorator reuses
|
||||
// that id) or computed by the decorator fallback — never both. Position-only
|
||||
// title media instead reuses the coordinate-and-text id finalized after headings
|
||||
// are applied.
|
||||
// canonicalChunkID derives the crop/upload key from the canonical chunk source.
|
||||
// The decorator in register.go reuses stamped IDs or derives the same identity
|
||||
// from finalized text, media payloads and crop regions for chunks without a stamp.
|
||||
// Title-family media IDs also retain source identity when context or headings
|
||||
// give distinct captionless media the same text.
|
||||
func canonicalChunkID(docID string, ck schema.ChunkDoc) string {
|
||||
// Title-family position-only media is stamped with both coordinates and
|
||||
// finalized heading text. Keep that identity through crop uploads,
|
||||
// including failed-upload retries.
|
||||
if isMediaChunk(ck) && ck.ID != "" {
|
||||
// A title-family captionless image can already carry a source/payload/body
|
||||
// identity. Only the title crop bridge marks these finalized IDs; other
|
||||
// chunkers may carry upstream IDs whose text they have since rewritten.
|
||||
if ck.ID != "" && string(ck.Extra[titleMediaContextIDKey]) == "true" {
|
||||
return ck.ID
|
||||
}
|
||||
return common.ChunkID(docID, chunkIDSource(ck))
|
||||
|
||||
@@ -24,6 +24,7 @@ import (
|
||||
"ragflow/internal/agent/runtime"
|
||||
"ragflow/internal/common"
|
||||
"ragflow/internal/ingestion/component"
|
||||
"ragflow/internal/ingestion/component/schema"
|
||||
"ragflow/internal/tokenizer"
|
||||
)
|
||||
|
||||
@@ -281,3 +282,37 @@ func TestCropTitleChunks_NilEnginePassthrough(t *testing.T) {
|
||||
t.Fatalf("nil engine should pass through unchanged: %v", got)
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextCropIDProvenance exercises the real crop/upload bridge:
|
||||
// only Title's finalized media IDs survive; unrelated upstream IDs are rebuilt.
|
||||
func TestTitleMediaContextCropIDProvenance(t *testing.T) {
|
||||
ctx := withIngestionGlobals(t, "kb1", "doc1")
|
||||
rec := &recordingUploader{}
|
||||
orig := ChunkImageUploader
|
||||
ChunkImageUploader = rec.upload
|
||||
t.Cleanup(func() { ChunkImageUploader = orig })
|
||||
pos := jsonPositions(t, []float64{1, 10, 100, 10, 100})
|
||||
titleID := "source-scoped-media-id"
|
||||
title := cropTitleChunks(ctx, mockCropEngine{}, []map[string]any{
|
||||
{"text": "Context-only body.", "doc_type_kwd": "image", "id": titleID, "positions": pos},
|
||||
})
|
||||
if len(title) != 1 || title[0]["id"] != titleID || title[0]["img_id"] != "kb1-"+titleID {
|
||||
t.Fatalf("title crop lost its finalized identity: %#v", title)
|
||||
}
|
||||
if _, leaked := title[0]["_title_media_context_id"]; leaked {
|
||||
t.Fatal("internal crop provenance leaked into the output")
|
||||
}
|
||||
|
||||
upstream := schema.ChunkDoc{
|
||||
ID: "stale-upstream-id", DocType: "image", Text: "Caption.@@1\t2##",
|
||||
ContextAbove: "Source explanation.\n", PDFPositions: pos,
|
||||
}
|
||||
want := common.ChunkID("doc1", chunkIDSource(upstream))
|
||||
other := cropImageChunks(ctx, mockCropEngine{}, []schema.ChunkDoc{upstream})
|
||||
if len(other) != 1 || other[0].ID != want || other[0].ImgID != "kb1-"+want {
|
||||
t.Fatalf("non-title crop reused upstream identity: %#v", other)
|
||||
}
|
||||
if len(rec.calls) != 2 || rec.calls[0].chunkID != titleID || rec.calls[1].chunkID != want {
|
||||
t.Fatalf("crop upload keys differ from output IDs: %#v", rec.calls)
|
||||
}
|
||||
}
|
||||
@@ -141,6 +141,7 @@ func invokeGroup(parentCtx context.Context, db *gorm.DB, inputs map[string]any,
|
||||
// p.ChunkTokenCap. The cap is applied right after build_chunks and BEFORE the
|
||||
// on-demand crop, mirroring Python's invoke() order (build -> cap -> set_chunks).
|
||||
func chunkFromRecords(parentCtx context.Context, db *gorm.DB, upstream schema.ChunkerFromUpstream, p *titleChunkerParam, records []lineRecord, tokenCap int) (map[string]any, error) {
|
||||
attachTitleMediaContext(records, p.TableContextSize, p.ImageContextSize)
|
||||
ctx := newLevelContext(records, outlineFromUpstream(upstream), p)
|
||||
levels := ctx.Levels()
|
||||
// Count heading level distribution for debugging.
|
||||
@@ -305,8 +306,13 @@ func isPlainTextFormat(upstream schema.ChunkerFromUpstream) bool {
|
||||
// stay aligned with the returned chunks after empty groups are dropped and
|
||||
// root_chunk_as_heading is applied, so the token-cap pass can re-prepend a
|
||||
// chunk's chain to every piece it splits off.
|
||||
// docID scopes contextual captionless media identities to their source document.
|
||||
func buildChunksFromRecordGroups(groups [][]lineRecord, prefixes []string, p *titleChunkerParam, plain bool, docID string) ([]map[string]any, []string) {
|
||||
chunks := make([]map[string]any, 0, len(groups))
|
||||
var mediaIdentities []string
|
||||
if p.TableContextSize > 0 || p.ImageContextSize > 0 {
|
||||
mediaIdentities = make([]string, 0, len(groups))
|
||||
}
|
||||
var outPrefixes []string
|
||||
if prefixes != nil {
|
||||
outPrefixes = make([]string, 0, len(groups))
|
||||
@@ -326,6 +332,21 @@ func buildChunksFromRecordGroups(groups [][]lineRecord, prefixes []string, p *ti
|
||||
chunkText = removeTag(g[0].text)
|
||||
}
|
||||
chunk := map[string]any{"text": chunkText}
|
||||
mediaIdentity := ""
|
||||
if !g[0].isText() && (g[0].contextAbove != "" || g[0].contextBelow != "") {
|
||||
media := materializeMediaContext(schema.ChunkDoc{
|
||||
Text: chunkText, ContextAbove: g[0].contextAbove, ContextBelow: g[0].contextBelow,
|
||||
})
|
||||
chunk["text"] = media.Text
|
||||
chunk["tk_nums"] = intValue(media.TKNums)
|
||||
if chunkText == "" {
|
||||
imgID := ""
|
||||
if g[0].imgID != nil {
|
||||
imgID = *g[0].imgID
|
||||
}
|
||||
mediaIdentity = mediaTextIdentity(mediaChunkIdentity(g[0].image, imgID, g[0].mediaRef), true, mergePositionMatrix(g[0].pdfPositions, g[0].positions))
|
||||
}
|
||||
}
|
||||
if g[0].preserveOrder {
|
||||
chunk["_preserve_order"] = true
|
||||
}
|
||||
@@ -383,6 +404,9 @@ func buildChunksFromRecordGroups(groups [][]lineRecord, prefixes []string, p *ti
|
||||
}
|
||||
}
|
||||
chunks = append(chunks, chunk)
|
||||
if mediaIdentities != nil {
|
||||
mediaIdentities = append(mediaIdentities, mediaIdentity)
|
||||
}
|
||||
if prefixes != nil {
|
||||
outPrefixes = append(outPrefixes, prefixes[i])
|
||||
}
|
||||
@@ -391,6 +415,9 @@ func buildChunksFromRecordGroups(groups [][]lineRecord, prefixes []string, p *ti
|
||||
rootText := toString(chunks[0]["text"])
|
||||
for i := 1; i < len(chunks); i++ {
|
||||
chunks[i]["text"] = rootText + "\n" + toString(chunks[i]["text"])
|
||||
if _, contextual := chunks[i]["tk_nums"]; contextual {
|
||||
chunks[i]["tk_nums"] = tokenizeStr(toString(chunks[i]["text"]))
|
||||
}
|
||||
if id := toString(chunks[i]["id"]); id != "" {
|
||||
// Extractor caches key on id, so it must also identify the final text.
|
||||
chunks[i]["id"] = common.ChunkID(docID, mediaChunkIDPrefix+id+":"+toString(chunks[i]["text"]))
|
||||
@@ -400,10 +427,21 @@ func buildChunksFromRecordGroups(groups [][]lineRecord, prefixes []string, p *ti
|
||||
}
|
||||
}
|
||||
chunks = chunks[1:]
|
||||
if mediaIdentities != nil {
|
||||
mediaIdentities = mediaIdentities[1:]
|
||||
}
|
||||
if prefixes != nil {
|
||||
outPrefixes = outPrefixes[1:]
|
||||
}
|
||||
}
|
||||
for i, identity := range mediaIdentities {
|
||||
if identity != "" {
|
||||
// Context can give two distinct captionless images identical
|
||||
// bodies. Keep their payload identity as well as the final body
|
||||
// in the key, before either crop or decorator upload can run.
|
||||
chunks[i]["id"] = common.ChunkID(docID, identity+"\x00"+toString(chunks[i]["text"]))
|
||||
}
|
||||
}
|
||||
return chunks, outPrefixes
|
||||
}
|
||||
|
||||
@@ -722,7 +760,9 @@ func NewGroupTitleChunker(params map[string]any) (runtime.Component, error) {
|
||||
conf[k] = v
|
||||
}
|
||||
p := defaultsTitle()
|
||||
p.Update(conf)
|
||||
if err := p.Update(conf); err != nil {
|
||||
return nil, fmt.Errorf("GroupTitleChunker: %w", err)
|
||||
}
|
||||
if err := p.TitleChunkerParam.Validate(); err != nil {
|
||||
return nil, fmt.Errorf("GroupTitleChunker: %w", err)
|
||||
}
|
||||
|
||||
@@ -154,6 +154,7 @@ func invokeHierarchy(parentCtx context.Context, db *gorm.DB, inputs map[string]a
|
||||
if len(records) == 0 {
|
||||
return emptyOutputs(), nil
|
||||
}
|
||||
attachTitleMediaContext(records, p.TableContextSize, p.ImageContextSize)
|
||||
ctx := newLevelContext(records, outlineFromUpstream(upstream), p)
|
||||
levels := ctx.Levels()
|
||||
// Count heading level distribution for debugging.
|
||||
@@ -322,7 +323,9 @@ func NewHierarchyTitleChunker(params map[string]any) (runtime.Component, error)
|
||||
conf[k] = v
|
||||
}
|
||||
p := defaultsTitle()
|
||||
p.Update(conf)
|
||||
if err := p.Update(conf); err != nil {
|
||||
return nil, fmt.Errorf("HierarchyTitleChunker: %w", err)
|
||||
}
|
||||
if err := p.TitleChunkerParam.Validate(); err != nil {
|
||||
return nil, fmt.Errorf("HierarchyTitleChunker: %w", err)
|
||||
}
|
||||
|
||||
@@ -71,7 +71,9 @@ func NewManualChunker(params map[string]any) (runtime.Component, error) {
|
||||
zap.Strings("dropped", dropped))
|
||||
}
|
||||
p := defaultsTitle()
|
||||
p.Update(conf)
|
||||
if err := p.Update(conf); err != nil {
|
||||
return nil, fmt.Errorf("ManualChunker: %w", err)
|
||||
}
|
||||
if err := p.TitleChunkerParam.Validate(); err != nil {
|
||||
return nil, fmt.Errorf("ManualChunker: %w", err)
|
||||
}
|
||||
|
||||
@@ -69,6 +69,7 @@ import (
|
||||
"context"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"math"
|
||||
"regexp"
|
||||
"strings"
|
||||
"unicode/utf8"
|
||||
@@ -87,9 +88,10 @@ type titleChunkerParam struct {
|
||||
schema.TitleChunkerParam
|
||||
}
|
||||
|
||||
func (p *titleChunkerParam) Update(conf map[string]any) {
|
||||
// Update applies title/manual heading settings and independent media windows.
|
||||
func (p *titleChunkerParam) Update(conf map[string]any) error {
|
||||
if conf == nil {
|
||||
return
|
||||
return nil
|
||||
}
|
||||
if v, ok := conf["method"].(string); ok {
|
||||
p.TitleChunkerParam.Method = v
|
||||
@@ -112,6 +114,25 @@ func (p *titleChunkerParam) Update(conf map[string]any) {
|
||||
if v, ok := schema.NumericFromAny(conf["chunk_token_cap"]); ok {
|
||||
p.TitleChunkerParam.ChunkTokenCap = int(v)
|
||||
}
|
||||
for _, field := range []struct {
|
||||
name string
|
||||
target *int
|
||||
}{
|
||||
{"table_context_size", &p.TableContextSize},
|
||||
{"image_context_size", &p.ImageContextSize},
|
||||
} {
|
||||
raw, exists := conf[field.name]
|
||||
if !exists {
|
||||
continue
|
||||
}
|
||||
value, ok := schema.NumericFromAny(raw)
|
||||
if !ok || math.IsNaN(value) || math.IsInf(value, 0) || value < 0 ||
|
||||
math.Trunc(value) != value || value >= float64(^uint(0)>>1) {
|
||||
return fmt.Errorf("%s must be a non-negative integer", field.name)
|
||||
}
|
||||
*field.target = int(value)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// parseLevels accepts a [[string]] representation — the natural
|
||||
@@ -694,6 +715,8 @@ type lineRecord struct {
|
||||
sheet string
|
||||
sheetIndex *int
|
||||
parentMeta map[string]any
|
||||
contextAbove string
|
||||
contextBelow string
|
||||
}
|
||||
|
||||
func (r lineRecord) textOrEmpty() string { return r.text }
|
||||
@@ -798,7 +821,9 @@ type TitleChunkerComponent struct {
|
||||
func NewTitleChunker(params map[string]any) (runtime.Component, error) {
|
||||
p := defaultsTitle()
|
||||
p.Method = "group" // default to group
|
||||
p.Update(params)
|
||||
if err := p.Update(params); err != nil {
|
||||
return nil, fmt.Errorf("TitleChunker: %w", err)
|
||||
}
|
||||
if err := p.TitleChunkerParam.Validate(); err != nil {
|
||||
return nil, fmt.Errorf("TitleChunker: %w", err)
|
||||
}
|
||||
|
||||
@@ -0,0 +1,75 @@
|
||||
// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package chunker
|
||||
|
||||
import (
|
||||
"go.uber.org/zap"
|
||||
|
||||
"ragflow/internal/common"
|
||||
"ragflow/internal/ingestion/component/schema"
|
||||
)
|
||||
|
||||
// titleMediaContextIDKey is transient provenance added by the title crop bridge
|
||||
// and removed before returning chunks. It never enters saved pipeline output.
|
||||
const titleMediaContextIDKey = "_title_media_context_id"
|
||||
|
||||
// attachTitleMediaContext adapts this invocation's source records to the shared
|
||||
// General collector. Call after Manual's physical sort and before heading
|
||||
// grouping: context must not include duplicated ancestor/root headings or
|
||||
// cap-split copies. The collector skips other media, respects sheet boundaries
|
||||
// and selects complete sentences independently on either side of each media.
|
||||
func attachTitleMediaContext(records []lineRecord, tableTokens, imageTokens int) {
|
||||
attached, withoutContext := 0, 0
|
||||
defer func() {
|
||||
common.Debug("chunker stage",
|
||||
zap.String("variant", "title-media-context"),
|
||||
zap.Int("records", len(records)),
|
||||
zap.Int("table_context_size", tableTokens),
|
||||
zap.Int("image_context_size", imageTokens),
|
||||
zap.Int("media_with_context", attached),
|
||||
zap.Int("enabled_media_without_context", withoutContext),
|
||||
)
|
||||
}()
|
||||
if tableTokens <= 0 && imageTokens <= 0 {
|
||||
return
|
||||
}
|
||||
units := make([]schema.ChunkDoc, len(records))
|
||||
for i, rec := range records {
|
||||
units[i] = schema.ChunkDoc{
|
||||
Text: removeTag(rec.text), DocType: rec.docType,
|
||||
Sheet: rec.sheet, SheetIndex: rec.sheetIndex,
|
||||
}
|
||||
}
|
||||
attachGeneralMediaContext(units, tableTokens, imageTokens, nil)
|
||||
for i, unit := range units {
|
||||
if (unit.DocType == "table" && tableTokens > 0) || (unit.DocType == "image" && imageTokens > 0) {
|
||||
if unit.ContextAbove != "" || unit.ContextBelow != "" {
|
||||
attached++
|
||||
} else {
|
||||
// The shared collector found no eligible neighboring text
|
||||
// within this media record's sheet boundary.
|
||||
withoutContext++
|
||||
}
|
||||
}
|
||||
// Keep an explicit boundary between prose and the atomic media body,
|
||||
// including captionless images; do not glue words or HTML to prose.
|
||||
if unit.ContextAbove != "" {
|
||||
records[i].contextAbove = unit.ContextAbove + "\n"
|
||||
}
|
||||
if unit.ContextBelow != "" {
|
||||
records[i].contextBelow = "\n" + unit.ContextBelow
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,414 @@
|
||||
// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package chunker
|
||||
|
||||
import (
|
||||
"context"
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"math"
|
||||
"reflect"
|
||||
"strings"
|
||||
"testing"
|
||||
|
||||
"ragflow/internal/agent/runtime"
|
||||
"ragflow/internal/common"
|
||||
"ragflow/internal/entity"
|
||||
"ragflow/internal/ingestion/component/schema"
|
||||
)
|
||||
|
||||
// mediaContextComponents exercises both Title dispatch modes and standalone variants.
|
||||
func mediaContextComponents(t *testing.T, windows map[string]any) []titleFamilyCase {
|
||||
t.Helper()
|
||||
var cases []titleFamilyCase
|
||||
for _, tc := range []struct {
|
||||
name string
|
||||
method string
|
||||
factory func(map[string]any) (runtime.Component, error)
|
||||
}{
|
||||
{"title-group", "group", NewTitleChunker},
|
||||
{"title-hierarchy", "hierarchy", NewTitleChunker},
|
||||
{"group", "group", NewGroupTitleChunker},
|
||||
{"hierarchy", "hierarchy", NewHierarchyTitleChunker},
|
||||
{"manual", "group", NewManualChunker},
|
||||
} {
|
||||
conf := map[string]any{"method": tc.method, "hierarchy": 1, "levels": [][]string{{`^# `}}}
|
||||
for k, v := range windows {
|
||||
conf[k] = v
|
||||
}
|
||||
comp, err := tc.factory(conf)
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
cases = append(cases, titleFamilyCase{tc.name, comp})
|
||||
}
|
||||
return cases
|
||||
}
|
||||
|
||||
// titleContextFixture contains source text, an atomic table and a captionless image.
|
||||
func titleContextFixture(t *testing.T) []map[string]any {
|
||||
t.Helper()
|
||||
return []map[string]any{
|
||||
{"text": "Alpha explains the table.", "doc_type_kwd": "text"},
|
||||
tableItem(t, titleTestTableHTML, map[string]any{"img_id": "table-preview", "_pdf_positions": [][]float64{{1, 10, 100, 20, 30}}}),
|
||||
{"text": "Beta explains both media.", "doc_type_kwd": "text"},
|
||||
{"text": "", "doc_type_kwd": "image", "image": "data:image/png;base64," + pngBase64, "_pdf_positions": [][]float64{{1, 10, 100, 50, 60}}},
|
||||
{"text": "Gamma follows the image.", "doc_type_kwd": "text"},
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContext attaches independent windows without changing payloads or ordering.
|
||||
func TestTitleMediaContext(t *testing.T) {
|
||||
for _, windows := range []map[string]any{
|
||||
{"table_context_size": 1, "image_context_size": 1},
|
||||
{"table_context_size": 1, "image_context_size": 0},
|
||||
{"table_context_size": 0, "image_context_size": 1},
|
||||
} {
|
||||
for _, tc := range mediaContextComponents(t, windows) {
|
||||
t.Run(fmt.Sprintf("%s/table=%v/image=%v", tc.name, windows["table_context_size"], windows["image_context_size"]), func(t *testing.T) {
|
||||
fixture := titleContextFixture(t)
|
||||
before, _ := json.Marshal(fixture)
|
||||
chunks := titleFamilyChunks(t, tc.comp, fixture)
|
||||
if len(chunks) != 5 {
|
||||
t.Fatalf("chunks=%d: %#v", len(chunks), chunks)
|
||||
}
|
||||
tableText := renderedChunkText(t, fixture[1])
|
||||
if windows["table_context_size"] == 1 {
|
||||
tableText = "Alpha explains the table.\n" + tableText + "\nBeta explains both media."
|
||||
}
|
||||
imageText := ""
|
||||
if windows["image_context_size"] == 1 {
|
||||
imageText = "Beta explains both media.\n\nGamma follows the image."
|
||||
}
|
||||
for index, want := range map[int]string{1: tableText, 3: imageText} {
|
||||
if got := chunks[index]["text"]; got != want {
|
||||
t.Errorf("chunk %d text=%q, want %q", index, got, want)
|
||||
}
|
||||
for _, key := range []string{"_pdf_positions", "img_id", "image"} {
|
||||
if want, exists := fixture[index][key]; exists {
|
||||
gotJSON, _ := json.Marshal(chunks[index][key])
|
||||
wantJSON, _ := json.Marshal(want)
|
||||
if string(gotJSON) != string(wantJSON) {
|
||||
t.Errorf("chunk %d lost %s: %v", index, key, chunks[index][key])
|
||||
}
|
||||
}
|
||||
}
|
||||
if _, ok := chunks[index]["context_above"]; ok {
|
||||
t.Fatal("context was not materialized")
|
||||
}
|
||||
if count, ok := chunks[index]["tk_nums"]; ok && count != tokenizeStr(toString(chunks[index]["text"])) {
|
||||
t.Errorf("chunk %d has a stale token count: %v", index, count)
|
||||
}
|
||||
}
|
||||
if chunks[0]["text"] != "Alpha explains the table.\n" || chunks[2]["text"] != "Beta explains both media.\n" || chunks[4]["text"] != "Gamma follows the image.\n" {
|
||||
t.Fatalf("neighbor text changed: %#v", chunks)
|
||||
}
|
||||
after, _ := json.Marshal(fixture)
|
||||
if string(before) != string(after) {
|
||||
t.Fatal("input payload was mutated")
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextSheetBoundary stops before a different spreadsheet source.
|
||||
func TestTitleMediaContextSheetBoundary(t *testing.T) {
|
||||
for _, tc := range mediaContextComponents(t, map[string]any{"image_context_size": 128}) {
|
||||
t.Run(tc.name, func(t *testing.T) {
|
||||
chunks := titleFamilyChunks(t, tc.comp, []map[string]any{
|
||||
{"text": "Sheet one.", "doc_type_kwd": "text", "sheet": "One", "sheet_index": 0},
|
||||
{"text": "", "doc_type_kwd": "image", "img_id": "one", "sheet": "One", "sheet_index": 0},
|
||||
{"text": "Sheet two.", "doc_type_kwd": "text", "sheet": "Two", "sheet_index": 1},
|
||||
{"text": "", "doc_type_kwd": "image", "img_id": "two", "sheet": "Two", "sheet_index": 1},
|
||||
{"text": "Sheet two ending.", "doc_type_kwd": "text", "sheet": "Two", "sheet_index": 1},
|
||||
})
|
||||
if chunks[1]["text"] != "Sheet one.\n" || chunks[3]["text"] != "Sheet two.\n\nSheet two ending." {
|
||||
t.Fatalf("context crossed sheet boundary: %#v", chunks)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextInvalidParameters rejects invalid API input at construction.
|
||||
func TestTitleMediaContextInvalidParameters(t *testing.T) {
|
||||
for _, factory := range []func(map[string]any) (runtime.Component, error){
|
||||
NewTitleChunker, NewGroupTitleChunker, NewHierarchyTitleChunker, NewManualChunker,
|
||||
} {
|
||||
for _, key := range []string{"table_context_size", "image_context_size"} {
|
||||
for _, invalid := range []any{-1, -0.5, 0.5, true, nil, "invalid", math.Inf(1), math.NaN(), 1e30} {
|
||||
_, err := factory(map[string]any{
|
||||
"method": "group", "levels": [][]string{{`^# `}}, "hierarchy": 1, key: invalid,
|
||||
})
|
||||
if err == nil || !strings.Contains(err.Error(), key) {
|
||||
t.Errorf("%s=%v (%T) not rejected: %v", key, invalid, invalid, err)
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextRootAndCap keeps media atomic and counts the final prefixed body.
|
||||
func TestTitleMediaContextRootAndCap(t *testing.T) {
|
||||
for _, tc := range mediaContextComponents(t, map[string]any{
|
||||
"image_context_size": 1, "chunk_token_cap": 128, "root_chunk_as_heading": true,
|
||||
}) {
|
||||
t.Run(tc.name, func(t *testing.T) {
|
||||
sentence := strings.Repeat("neighbor ", 160) + "ends."
|
||||
chunks := titleFamilyChunks(t, tc.comp, []map[string]any{
|
||||
{"text": "Root.", "doc_type_kwd": "text"},
|
||||
{"text": "Caption.", "doc_type_kwd": "image", "img_id": "figure"},
|
||||
{"text": sentence, "doc_type_kwd": "text"},
|
||||
})
|
||||
var images []map[string]any
|
||||
for _, chunk := range chunks {
|
||||
if chunk["doc_type_kwd"] == "image" {
|
||||
images = append(images, chunk)
|
||||
}
|
||||
}
|
||||
if len(images) != 1 || !strings.Contains(toString(images[0]["text"]), sentence) {
|
||||
t.Fatalf("media body was split or lost context: %#v", chunks)
|
||||
}
|
||||
if images[0]["tk_nums"] != tokenizeStr(toString(images[0]["text"])) {
|
||||
t.Fatalf("stale prefixed token count: %#v", images[0])
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextZero preserves byte-for-byte output when windows are disabled.
|
||||
func TestTitleMediaContextZero(t *testing.T) {
|
||||
omitted := mediaContextComponents(t, nil)
|
||||
explicit := mediaContextComponents(t, map[string]any{"table_context_size": 0, "image_context_size": 0})
|
||||
for i, tc := range omitted {
|
||||
t.Run(tc.name, func(t *testing.T) {
|
||||
first := titleFamilyChunks(t, tc.comp, titleContextFixture(t))
|
||||
second := titleFamilyChunks(t, explicit[i].comp, titleContextFixture(t))
|
||||
if !reflect.DeepEqual(first, second) {
|
||||
t.Fatalf("zero windows changed output: %#v / %#v", first, second)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextInvocationBoundary proves a reused component keeps no source state.
|
||||
func TestTitleMediaContextInvocationBoundary(t *testing.T) {
|
||||
for _, tc := range mediaContextComponents(t, map[string]any{"image_context_size": 128}) {
|
||||
t.Run(tc.name, func(t *testing.T) {
|
||||
titleFamilyChunks(t, tc.comp, []map[string]any{{"text": "PRIVATE FIRST DOCUMENT.", "doc_type_kwd": "text"}})
|
||||
chunks := titleFamilyChunks(t, tc.comp, []map[string]any{
|
||||
{"text": "", "doc_type_kwd": "image", "img_id": "second-document"},
|
||||
{"text": "Only second document.", "doc_type_kwd": "text"},
|
||||
})
|
||||
if len(chunks) != 2 || chunks[0]["text"] != "\nOnly second document." {
|
||||
t.Fatalf("wrong source context: %#v", chunks)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextManualOrder selects neighbors after the physical-position sort.
|
||||
func TestTitleMediaContextManualOrder(t *testing.T) {
|
||||
comp, err := NewManualChunker(map[string]any{"levels": [][]string{{`^# `}}, "image_context_size": 1})
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
chunks := titleFamilyChunks(t, comp, []map[string]any{
|
||||
{"text": "Below.", "doc_type_kwd": "text", "_pdf_positions": [][]float64{{1, 10, 100, 30, 40}}},
|
||||
{"text": "", "doc_type_kwd": "image", "img_id": "figure", "_pdf_positions": [][]float64{{1, 10, 100, 20, 25}}},
|
||||
{"text": "Above.", "doc_type_kwd": "text", "_pdf_positions": [][]float64{{1, 10, 100, 10, 15}}},
|
||||
})
|
||||
if len(chunks) != 3 || chunks[1]["text"] != "Above.\n\nBelow." {
|
||||
t.Fatalf("context did not follow physical order: %#v", chunks)
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextPreservesReadingOrder keeps PaddleOCR's source sequence
|
||||
// when its positions disagree with the physical sort used for other inputs.
|
||||
func TestTitleMediaContextPreservesReadingOrder(t *testing.T) {
|
||||
for _, budget := range []int{0, 1} {
|
||||
for _, tc := range mediaContextComponents(t, map[string]any{"image_context_size": budget}) {
|
||||
t.Run(fmt.Sprintf("%s/budget=%d", tc.name, budget), func(t *testing.T) {
|
||||
chunks := titleFamilyChunks(t, tc.comp, []map[string]any{
|
||||
{"text": "Source before.", "doc_type_kwd": "text", "_preserve_order": true, "_pdf_positions": [][]float64{{1, 10, 100, 30, 40}}},
|
||||
{"text": "", "doc_type_kwd": "image", "img_id": "figure", "_preserve_order": true, "_pdf_positions": [][]float64{{1, 10, 100, 20, 25}}},
|
||||
{"text": "Source after.", "doc_type_kwd": "text", "_preserve_order": true, "_pdf_positions": [][]float64{{1, 10, 100, 10, 15}}},
|
||||
})
|
||||
want := ""
|
||||
if budget > 0 {
|
||||
want = "Source before.\n\nSource after."
|
||||
}
|
||||
if len(chunks) != 3 || chunks[1]["text"] != want || chunks[0]["text"] != "Source before.\n" || chunks[2]["text"] != "Source after.\n" {
|
||||
t.Fatalf("source reading order or context lost: %#v", chunks)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextDeferredAndPositionOnlyIdentity preserves upstream media
|
||||
// identities when equal neighboring text gives captionless media equal bodies.
|
||||
func TestTitleMediaContextDeferredAndPositionOnlyIdentity(t *testing.T) {
|
||||
for _, kind := range []string{"reference", "position"} {
|
||||
t.Run(kind, func(t *testing.T) {
|
||||
groups := make([][]lineRecord, 2)
|
||||
for i := range groups {
|
||||
rec := lineRecord{docType: "image", contextAbove: "Same context.\n"}
|
||||
if kind == "reference" {
|
||||
rec.mediaRef = &entity.MediaRef{Format: "html", Kind: entity.MediaKindKV, SHA256: strings.Repeat(fmt.Sprint(i+1), 64)}
|
||||
} else {
|
||||
rec.positions = json.RawMessage(fmt.Sprintf("[[1,10,100,%d,%d]]", i*30+10, i*30+20))
|
||||
}
|
||||
groups[i] = []lineRecord{rec}
|
||||
}
|
||||
p := defaultsTitle()
|
||||
p.ImageContextSize = 1
|
||||
chunks, _ := buildChunksFromRecordGroups(groups, nil, &p, false, "source")
|
||||
if len(chunks) != 2 || chunks[0]["text"] != chunks[1]["text"] || chunks[0]["id"] == chunks[1]["id"] {
|
||||
t.Fatalf("distinct %s media collided: %#v", kind, chunks)
|
||||
}
|
||||
groups[0][0].contextAbove = "Changed context.\n"
|
||||
changed, _ := buildChunksFromRecordGroups(groups[:1], nil, &p, false, "source")
|
||||
if changed[0]["id"] == chunks[0]["id"] {
|
||||
t.Fatalf("%s media identity ignored changed context", kind)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextSentences uses whole adjacent sentences even over a one-token budget.
|
||||
func TestTitleMediaContextSentences(t *testing.T) {
|
||||
for _, tc := range mediaContextComponents(t, map[string]any{"image_context_size": 1}) {
|
||||
t.Run(tc.name, func(t *testing.T) {
|
||||
chunks := titleFamilyChunks(t, tc.comp, []map[string]any{
|
||||
{"text": "Distant above. Nearest complete sentence.", "doc_type_kwd": "text"},
|
||||
{"text": "Caption.", "doc_type_kwd": "image", "img_id": "figure"},
|
||||
{"text": "Closest below. Distant below.", "doc_type_kwd": "text"},
|
||||
})
|
||||
if got, want := chunks[1]["text"], "Nearest complete sentence.\nCaption.\nClosest below. "; got != want {
|
||||
t.Fatalf("text=%q, want whole boundary sentences %q", got, want)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextDecoratorID hashes the final context-bearing body used by upload.
|
||||
func TestTitleMediaContextDecoratorID(t *testing.T) {
|
||||
prev := ChunkImageUploader
|
||||
var uploaded string
|
||||
ChunkImageUploader = func(_ context.Context, kbID, chunkID string, _ []byte) (string, error) {
|
||||
uploaded = chunkID
|
||||
return kbID + "-" + chunkID, nil
|
||||
}
|
||||
t.Cleanup(func() { ChunkImageUploader = prev })
|
||||
comp := mediaContextComponents(t, map[string]any{"image_context_size": 1})[0].comp
|
||||
decorated := &imageUploadDecorator{inner: comp}
|
||||
out, err := decorated.Invoke(t.Context(), nil, map[string]any{
|
||||
"name": "book.docx", "kb_id": testKBID, "output_format": "json",
|
||||
"json": []map[string]any{
|
||||
{"text": "Source explanation.", "doc_type_kwd": "text"},
|
||||
{"text": "Caption.", "doc_type_kwd": "image", "image": "data:image/png;base64," + pngBase64},
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
chunks := out["chunks"].([]map[string]any)
|
||||
wantText := "Source explanation.\nCaption."
|
||||
wantID := common.ChunkID("", wantText)
|
||||
if chunks[1]["text"] != wantText || chunks[1]["id"] != wantID || uploaded != wantID || chunks[1]["img_id"] != testKBID+"-"+wantID {
|
||||
t.Fatalf("context/id/upload mismatch: %#v, uploaded=%s", chunks[1], uploaded)
|
||||
}
|
||||
if strings.Contains(toString(chunks[1]["text"]), "@@") {
|
||||
t.Fatal("position tags leaked into indexed text")
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextCaptionlessIDs prevents different images with identical
|
||||
// surrounding text from overwriting each other's storage and index entries.
|
||||
func TestTitleMediaContextCaptionlessIDs(t *testing.T) {
|
||||
prev := ChunkImageUploader
|
||||
t.Cleanup(func() { ChunkImageUploader = prev })
|
||||
for _, tc := range mediaContextComponents(t, map[string]any{"image_context_size": 1}) {
|
||||
t.Run(tc.name, func(t *testing.T) {
|
||||
uploaded := map[string]int{}
|
||||
ChunkImageUploader = func(_ context.Context, kbID, chunkID string, _ []byte) (string, error) {
|
||||
uploaded[chunkID]++
|
||||
return kbID + "-" + chunkID, nil
|
||||
}
|
||||
ctx := runtime.WithState(t.Context(), &runtime.CanvasState{Globals: map[string]any{"doc_id": "source-doc"}})
|
||||
out, err := (&imageUploadDecorator{inner: tc.comp}).Invoke(ctx, nil, map[string]any{
|
||||
"name": "book.docx", "kb_id": testKBID, "output_format": "json",
|
||||
"json": []map[string]any{
|
||||
{"text": "Same before.", "doc_type_kwd": "text"},
|
||||
{"text": "", "doc_type_kwd": "image", "image": "data:image/png;base64," + pngBase64},
|
||||
{"text": "", "doc_type_kwd": "image", "image": "data:image/png;base64," + pngBase64Red},
|
||||
{"text": "Same after.", "doc_type_kwd": "text"},
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
chunks := out["chunks"].([]map[string]any)
|
||||
if len(chunks) != 4 || chunks[1]["text"] != chunks[2]["text"] {
|
||||
t.Fatalf("fixture must produce identical contextual bodies: %#v", chunks)
|
||||
}
|
||||
if chunks[1]["id"] == chunks[2]["id"] || len(uploaded) != 2 {
|
||||
t.Fatalf("distinct images collided: %#v; uploads=%v", chunks, uploaded)
|
||||
}
|
||||
for i, payload := range []string{pngBase64, pngBase64Red} {
|
||||
text := toString(chunks[i+1]["text"])
|
||||
source := mediaChunkIdentity("data:image/png;base64,"+payload, "", nil) + "\x00" + text
|
||||
if want := common.ChunkID("source-doc", source); chunks[i+1]["id"] != want || uploaded[want] != 1 {
|
||||
t.Fatalf("context/media/document identity lost: %#v", chunks[i+1])
|
||||
}
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextStampedCropID keeps the crop/upload identity already
|
||||
// derived from a contextual captionless image, matching decorator behavior.
|
||||
func TestTitleMediaContextStampedCropID(t *testing.T) {
|
||||
ck := schema.ChunkDoc{
|
||||
ID: "source-scoped-media-id", Text: "Context-only body.", DocType: "image",
|
||||
Extra: map[string]json.RawMessage{titleMediaContextIDKey: json.RawMessage("true")},
|
||||
}
|
||||
if got := canonicalChunkID("doc", ck); got != ck.ID {
|
||||
t.Fatalf("crop replaced stamped identity: %s", got)
|
||||
}
|
||||
}
|
||||
|
||||
// TestTitleMediaContextCropIDRejectsUpstreamID keeps unrelated upstream IDs
|
||||
// from surviving normalization of the text used by the shared crop helper.
|
||||
func TestTitleMediaContextCropIDRejectsUpstreamID(t *testing.T) {
|
||||
for _, kind := range []string{"image", "table", "text"} {
|
||||
for _, marker := range []string{"", "false", "null", "1", `"true"`} {
|
||||
t.Run(kind+"/"+marker, func(t *testing.T) {
|
||||
ck := schema.ChunkDoc{
|
||||
ID: "stale-upstream-id", Text: "Caption.@@1\t2##", DocType: kind,
|
||||
ContextAbove: "Source explanation.\n",
|
||||
}
|
||||
if marker != "" {
|
||||
ck.Extra = map[string]json.RawMessage{titleMediaContextIDKey: json.RawMessage(marker)}
|
||||
}
|
||||
want := common.ChunkID("doc", chunkIDSource(ck))
|
||||
if got := canonicalChunkID("doc", ck); got != want {
|
||||
t.Fatalf("crop retained upstream ID: got %s, want %s", got, want)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -324,9 +324,21 @@ func cropTitleChunks(ctx context.Context, engine deepdoctype.PDFEngine, chunks [
|
||||
normalizeTitleChunkMaps(chunks)
|
||||
return chunks
|
||||
}
|
||||
for i := range docs {
|
||||
// Only this bridge receives IDs finalized by the title-family
|
||||
// builder. Mark them for the shared crop helper without extending
|
||||
// ID trust to General/Token chunks decoded from upstream input.
|
||||
if docs[i].ID != "" {
|
||||
if docs[i].Extra == nil {
|
||||
docs[i].Extra = make(map[string]json.RawMessage)
|
||||
}
|
||||
docs[i].Extra[titleMediaContextIDKey] = json.RawMessage("true")
|
||||
}
|
||||
}
|
||||
cropped := cropImageChunks(ctx, engine, docs)
|
||||
for i := range cropped {
|
||||
clearStructuralLayout(&cropped[i])
|
||||
delete(cropped[i].Extra, titleMediaContextIDKey)
|
||||
}
|
||||
return schema.ChunkDocsToMaps(cropped)
|
||||
}
|
||||
|
||||
@@ -390,6 +390,11 @@ type TitleChunkerParam struct {
|
||||
// boundaries into <= cap sub-chunks. 0 disables the ceiling. The Python
|
||||
// default is 512; valid range when non-zero is 128..8000.
|
||||
ChunkTokenCap int `json:"chunk_token_cap"`
|
||||
|
||||
// TableContextSize and ImageContextSize are per-side media context budgets.
|
||||
// Zero disables context; whole sentences may exceed a positive budget.
|
||||
TableContextSize int `json:"table_context_size"`
|
||||
ImageContextSize int `json:"image_context_size"`
|
||||
}
|
||||
|
||||
// Defaults returns the Python default TitleChunkerParam. `Method` is
|
||||
@@ -410,6 +415,12 @@ func (TitleChunkerParam) Defaults() TitleChunkerParam {
|
||||
// expressible in pure-data terms: when Method == "hierarchy" the
|
||||
// hierarchy depth and level config must be present.
|
||||
func (p *TitleChunkerParam) Validate() error {
|
||||
if p.TableContextSize < 0 {
|
||||
return errInvalidValue{Field: "table_context_size", Value: fmt.Sprintf("%d", p.TableContextSize)}
|
||||
}
|
||||
if p.ImageContextSize < 0 {
|
||||
return errInvalidValue{Field: "image_context_size", Value: fmt.Sprintf("%d", p.ImageContextSize)}
|
||||
}
|
||||
// chunk_token_cap: 0 disables the ceiling; when set it must be a positive
|
||||
// integer in [128, 8000] (mirrors Python title_chunker #18455). Checked
|
||||
// BEFORE the method switch so an unset method cannot bypass the range.
|
||||
|
||||
@@ -0,0 +1,61 @@
|
||||
// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package schema
|
||||
|
||||
import (
|
||||
"encoding/json"
|
||||
"strings"
|
||||
"testing"
|
||||
)
|
||||
|
||||
// TestTitleContextParameters checks zero defaults, serialization and validation.
|
||||
func TestTitleContextParameters(t *testing.T) {
|
||||
defaults := TitleChunkerParam{}.Defaults()
|
||||
if defaults.TableContextSize != 0 || defaults.ImageContextSize != 0 {
|
||||
t.Fatal("media context must default to disabled")
|
||||
}
|
||||
for _, raw := range []string{
|
||||
`{}`, `{"table_context_size":0,"image_context_size":0}`,
|
||||
`{"table_context_size":32,"image_context_size":64}`,
|
||||
} {
|
||||
var params TitleChunkerParam
|
||||
if err := json.Unmarshal([]byte(raw), ¶ms); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
if err := params.Validate(); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
encoded, err := json.Marshal(params)
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
var reloaded TitleChunkerParam
|
||||
if err := json.Unmarshal(encoded, &reloaded); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
if reloaded.TableContextSize != params.TableContextSize || reloaded.ImageContextSize != params.ImageContextSize {
|
||||
t.Fatal("context windows did not survive serialization")
|
||||
}
|
||||
}
|
||||
for _, field := range []string{"table_context_size", "image_context_size"} {
|
||||
var params TitleChunkerParam
|
||||
if err := json.Unmarshal([]byte(`{"`+field+`":-1}`), ¶ms); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
if err := params.Validate(); err == nil || !strings.Contains(err.Error(), field) {
|
||||
t.Fatalf("%s was not rejected before method dispatch: %v", field, err)
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -1048,7 +1048,7 @@ func TestBuildParserConfig_TitleFamilyParamsSurviveBuiltinTemplates(t *testing.T
|
||||
var operatorFormParamKeys = map[string][]string{
|
||||
"TitleChunker": {
|
||||
"method", "levels", "hierarchy", "include_heading_content",
|
||||
"root_chunk_as_heading", "chunk_token_cap",
|
||||
"root_chunk_as_heading", "chunk_token_cap", "table_context_size", "image_context_size",
|
||||
// Per-method persistence keys: each method's rules, hierarchy value
|
||||
// and token cap are stored under their own key so the dataset config
|
||||
// keeps them independent of the active method (the runtime reads only
|
||||
@@ -1058,6 +1058,7 @@ var operatorFormParamKeys = map[string][]string{
|
||||
},
|
||||
"ManualChunker": {
|
||||
"method", "levels", "hierarchy", "root_chunk_as_heading",
|
||||
"table_context_size", "image_context_size",
|
||||
"hierarchyRules", "groupRules", "hierarchyHierarchy", "hierarchyGroup",
|
||||
},
|
||||
"TokenChunker": {
|
||||
|
||||
@@ -0,0 +1,139 @@
|
||||
// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
|
||||
package pipeline
|
||||
|
||||
import (
|
||||
"encoding/json"
|
||||
"fmt"
|
||||
"reflect"
|
||||
"testing"
|
||||
|
||||
"ragflow/internal/agent/runtime"
|
||||
"ragflow/internal/ingestion/component/chunker"
|
||||
"ragflow/internal/parser/tableutil"
|
||||
)
|
||||
|
||||
// TestBuiltinTitleMediaContext verifies saved configuration and mixed-media output
|
||||
// using the actual book/paper/manual templates, without external parser services.
|
||||
func TestBuiltinTitleMediaContext(t *testing.T) {
|
||||
registry, err := DefaultRegistry()
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
table, err := tableutil.ParseTableHTML("<table><tr><td>Value</td></tr></table>")
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
tableHTML := tableutil.RenderTableHTML(table)
|
||||
for _, ref := range []string{"book", "paper", "manual"} {
|
||||
tpl, ok := registry.Get(ref)
|
||||
if !ok {
|
||||
t.Fatalf("missing builtin %s", ref)
|
||||
}
|
||||
dsl, err := json.Marshal(tpl.DSL)
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
components, err := ExtractAllComponentParams(dsl)
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
tested := false
|
||||
for _, spec := range components {
|
||||
if spec.ComponentName != "TitleChunker" && spec.ComponentName != "ManualChunker" {
|
||||
continue
|
||||
}
|
||||
tested = true
|
||||
for _, pair := range [][2]int{{0, 0}, {1, 0}, {0, 1}, {1, 1}, {64, 32}} {
|
||||
t.Run(fmt.Sprintf("%s/table=%d/image=%d", ref, pair[0], pair[1]), func(t *testing.T) {
|
||||
config, err := BuildParserConfig(dsl, map[string]any{spec.CpnID: map[string]any{
|
||||
"table_context_size": pair[0], "image_context_size": pair[1],
|
||||
}})
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
raw, err := json.Marshal(config)
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
var saved map[string]map[string]any
|
||||
if err := json.Unmarshal(raw, &saved); err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
params := saved[spec.CpnID]
|
||||
for key, want := range map[string]int{"table_context_size": pair[0], "image_context_size": pair[1]} {
|
||||
if got := params[key]; got != float64(want) {
|
||||
t.Fatalf("%s lost %s=%d: %#v", ref, key, want, params)
|
||||
}
|
||||
}
|
||||
var comp runtime.Component
|
||||
if spec.ComponentName == "ManualChunker" {
|
||||
comp, err = chunker.NewManualChunker(params)
|
||||
} else {
|
||||
comp, err = chunker.NewTitleChunker(params)
|
||||
}
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
out, err := comp.Invoke(t.Context(), nil, map[string]any{
|
||||
"name": ref + ".docx", "output_format": "json",
|
||||
"json": []map[string]any{
|
||||
{"text": "Alpha.", "doc_type_kwd": "text"},
|
||||
{"table": table, "doc_type_kwd": "table", "img_id": "table-preview"},
|
||||
{"text": "Beta.", "doc_type_kwd": "text"},
|
||||
{"text": "Caption.", "doc_type_kwd": "image", "img_id": "figure"},
|
||||
{"text": "Gamma.", "doc_type_kwd": "text"},
|
||||
},
|
||||
})
|
||||
if err != nil {
|
||||
t.Fatal(err)
|
||||
}
|
||||
if problem := out["_ERROR"]; problem != nil {
|
||||
t.Fatal(problem)
|
||||
}
|
||||
chunks, ok := out["chunks"].([]map[string]any)
|
||||
if !ok || len(chunks) != 5 {
|
||||
t.Fatalf("unexpected chunks: %#v", out)
|
||||
}
|
||||
wantTable, wantImage := tableHTML, "Caption."
|
||||
if pair[0] > 0 {
|
||||
wantTable = "Alpha.\n" + tableHTML + "\nBeta."
|
||||
if pair[0] > 1 {
|
||||
wantTable += "\nGamma."
|
||||
}
|
||||
}
|
||||
if pair[1] > 0 {
|
||||
wantImage = "Beta.\nCaption.\nGamma."
|
||||
if pair[1] > 1 {
|
||||
wantImage = "Alpha.\n" + wantImage
|
||||
}
|
||||
}
|
||||
if chunks[1]["text"] != wantTable || chunks[3]["text"] != wantImage {
|
||||
t.Fatalf("wrong media context: table=%q image=%q", chunks[1]["text"], chunks[3]["text"])
|
||||
}
|
||||
if chunks[1]["img_id"] != "table-preview" || chunks[3]["img_id"] != "figure" {
|
||||
t.Fatalf("media reference changed: %#v", chunks)
|
||||
}
|
||||
if !reflect.DeepEqual([]any{chunks[0]["text"], chunks[2]["text"], chunks[4]["text"]}, []any{"Alpha.\n", "Beta.\n", "Gamma.\n"}) {
|
||||
t.Fatalf("text order changed: %#v", chunks)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
if !tested {
|
||||
t.Fatalf("%s has no title/manual component", ref)
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -287,6 +287,8 @@ export const initialTitleChunkerValues = {
|
||||
hierarchyGroup: '0',
|
||||
include_heading_content: false,
|
||||
root_chunk_as_heading: false,
|
||||
table_context_size: 0,
|
||||
image_context_size: 0,
|
||||
hierarchyChunkTokenCap: 512,
|
||||
groupChunkTokenCap: 512,
|
||||
hierarchyRules: cloneDeep(originalRules),
|
||||
|
||||
@@ -63,6 +63,7 @@ function parseChunkTokenCap(value: unknown): number {
|
||||
return Number.isFinite(cap) ? cap : 512;
|
||||
}
|
||||
|
||||
// Restore title/manual configuration without losing independently saved media windows.
|
||||
function transformApiResponseToForm(
|
||||
apiData: Record<string, any>,
|
||||
): TitleChunkerFormSchemaType {
|
||||
@@ -149,6 +150,8 @@ function transformApiResponseToForm(
|
||||
hierarchyGroup,
|
||||
include_heading_content: Boolean(apiData.include_heading_content),
|
||||
root_chunk_as_heading: Boolean(apiData.root_chunk_as_heading),
|
||||
table_context_size: Number(apiData.table_context_size ?? 0),
|
||||
image_context_size: Number(apiData.image_context_size ?? 0),
|
||||
hierarchyChunkTokenCap,
|
||||
groupChunkTokenCap,
|
||||
hierarchyRules,
|
||||
|
||||
@@ -68,6 +68,8 @@ export const FormSchema = z.object({
|
||||
groupRules: rulesSchema,
|
||||
hierarchyChunkTokenCap: z.coerce.number().int().min(128).max(8000).optional(),
|
||||
groupChunkTokenCap: z.coerce.number().int().min(128).max(8000).optional(),
|
||||
table_context_size: z.number().int().nonnegative().optional(),
|
||||
image_context_size: z.number().int().nonnegative().optional(),
|
||||
});
|
||||
|
||||
export enum TitleChunkerRulesField {
|
||||
@@ -254,6 +256,7 @@ function RootChunkAsHeadingItem() {
|
||||
);
|
||||
}
|
||||
|
||||
// TitleChunkerForm also configures Manual's pinned-group variant.
|
||||
const TitleChunkerForm = ({
|
||||
node,
|
||||
onValuesChange,
|
||||
@@ -375,6 +378,22 @@ const TitleChunkerForm = ({
|
||||
)}
|
||||
/>
|
||||
)}
|
||||
<SliderInputFormField
|
||||
name="table_context_size"
|
||||
max={256}
|
||||
min={0}
|
||||
integer
|
||||
label={t('knowledgeConfiguration.tableContextWindow')}
|
||||
tooltip={t('knowledgeConfiguration.tableContextWindowTip')}
|
||||
/>
|
||||
<SliderInputFormField
|
||||
name="image_context_size"
|
||||
max={256}
|
||||
min={0}
|
||||
integer
|
||||
label={t('knowledgeConfiguration.imageContextWindow')}
|
||||
tooltip={t('knowledgeConfiguration.imageContextWindowTip')}
|
||||
/>
|
||||
<RAGFlowFormItem
|
||||
name={'hierarchyHierarchy'}
|
||||
label={''}
|
||||
|
||||
@@ -0,0 +1,89 @@
|
||||
import { TitleChunkerMethod } from '../../constant/pipeline';
|
||||
import { transformTitleChunkerParams } from '../../utils';
|
||||
import { FormSchema } from './index';
|
||||
import { transformApiResponseToForm } from './hook';
|
||||
import {
|
||||
transformApiConfigToForm,
|
||||
transformFormConfigToApi,
|
||||
} from '@/utils/pipeline-operator';
|
||||
|
||||
describe('title/manual media context configuration', () => {
|
||||
it.each([TitleChunkerMethod.Group, TitleChunkerMethod.Hierarchy])(
|
||||
'defaults omitted windows to zero for %s',
|
||||
(method) => {
|
||||
const values = transformApiResponseToForm({ method });
|
||||
const saved = transformTitleChunkerParams(FormSchema.parse(values));
|
||||
expect(saved.table_context_size).toBe(0);
|
||||
expect(saved.image_context_size).toBe(0);
|
||||
},
|
||||
);
|
||||
|
||||
it.each([
|
||||
[0, 0],
|
||||
[32, 0],
|
||||
[0, 64],
|
||||
[32, 64],
|
||||
[256, 256],
|
||||
])(
|
||||
'round trips table=%i and image=%i across method changes',
|
||||
(table, image) => {
|
||||
const original = {
|
||||
method: TitleChunkerMethod.Hierarchy,
|
||||
table_context_size: table,
|
||||
image_context_size: image,
|
||||
};
|
||||
const values = FormSchema.parse(transformApiResponseToForm(original));
|
||||
const saved = transformTitleChunkerParams(values);
|
||||
const reloaded = transformApiResponseToForm(
|
||||
JSON.parse(JSON.stringify(saved)),
|
||||
);
|
||||
expect(reloaded.table_context_size).toBe(table);
|
||||
expect(reloaded.image_context_size).toBe(image);
|
||||
const group = transformTitleChunkerParams(
|
||||
FormSchema.parse({ ...reloaded, method: TitleChunkerMethod.Group }),
|
||||
);
|
||||
expect(group.table_context_size).toBe(table);
|
||||
expect(group.image_context_size).toBe(image);
|
||||
},
|
||||
);
|
||||
|
||||
it.each(['table_context_size', 'image_context_size'])(
|
||||
'rejects negative, fractional and nonnumeric %s values',
|
||||
(field) => {
|
||||
for (const value of [-1, 0.5, NaN, Infinity, '32', false, null]) {
|
||||
const values = transformApiResponseToForm({
|
||||
method: TitleChunkerMethod.Group,
|
||||
});
|
||||
expect(
|
||||
FormSchema.safeParse({ ...values, [field]: value }).success,
|
||||
).toBe(false);
|
||||
}
|
||||
},
|
||||
);
|
||||
|
||||
it.each(['TitleChunker', 'ManualChunker'])(
|
||||
'preserves both windows through the actual %s operator bridge',
|
||||
(operator) => {
|
||||
const loaded = transformApiConfigToForm(operator, {
|
||||
method: 'group',
|
||||
hierarchy: 0,
|
||||
levels: [['^# ']],
|
||||
table_context_size: 32,
|
||||
image_context_size: 64,
|
||||
});
|
||||
const parsed = FormSchema.parse(transformApiResponseToForm(loaded));
|
||||
const saved = transformFormConfigToApi(operator, parsed);
|
||||
const reloaded = transformApiConfigToForm(
|
||||
operator,
|
||||
JSON.parse(JSON.stringify(saved)),
|
||||
);
|
||||
expect(reloaded.table_context_size).toBe(32);
|
||||
expect(reloaded.image_context_size).toBe(64);
|
||||
if (operator === 'ManualChunker') {
|
||||
expect(saved).not.toHaveProperty('chunk_token_cap');
|
||||
// The existing bridge writes false; Manual ignores this setting.
|
||||
expect(saved.include_heading_content).toBe(false);
|
||||
}
|
||||
},
|
||||
);
|
||||
});
|
||||
@@ -444,6 +444,7 @@ export function transformGeneralChunkerParams(
|
||||
return result;
|
||||
}
|
||||
|
||||
// Resolve active heading settings and preserve independent media-context budgets.
|
||||
export function transformTitleChunkerParams(
|
||||
params: TitleChunkerFormSchemaType,
|
||||
) {
|
||||
@@ -488,6 +489,8 @@ export function transformTitleChunkerParams(
|
||||
hierarchy: Number(hierarchyValue || 0),
|
||||
include_heading_content: Boolean(params.include_heading_content),
|
||||
root_chunk_as_heading: Boolean(params.root_chunk_as_heading),
|
||||
table_context_size: Number(params.table_context_size ?? 0),
|
||||
image_context_size: Number(params.image_context_size ?? 0),
|
||||
...(chunkTokenCap === undefined || chunkTokenCap === null
|
||||
? {}
|
||||
: { chunk_token_cap: Number(chunkTokenCap) }),
|
||||
|
||||
Reference in new issue
Block a user