mirror of
https://github.com/infiniflow/ragflow.git
synced 2026-11-11 05:40:52 +08:00
docs: update images locations and links (#21787)
update images locations and links
This commit is contained in:
 YanZhang authored and
 GitHub committed
1 parent
88aba86d21
commit
c5604bd4ce
15 files changed
+37
-23
No files matched your search
@@ -10,12 +10,6 @@ title: Manage User Accounts
|
||||
|
||||
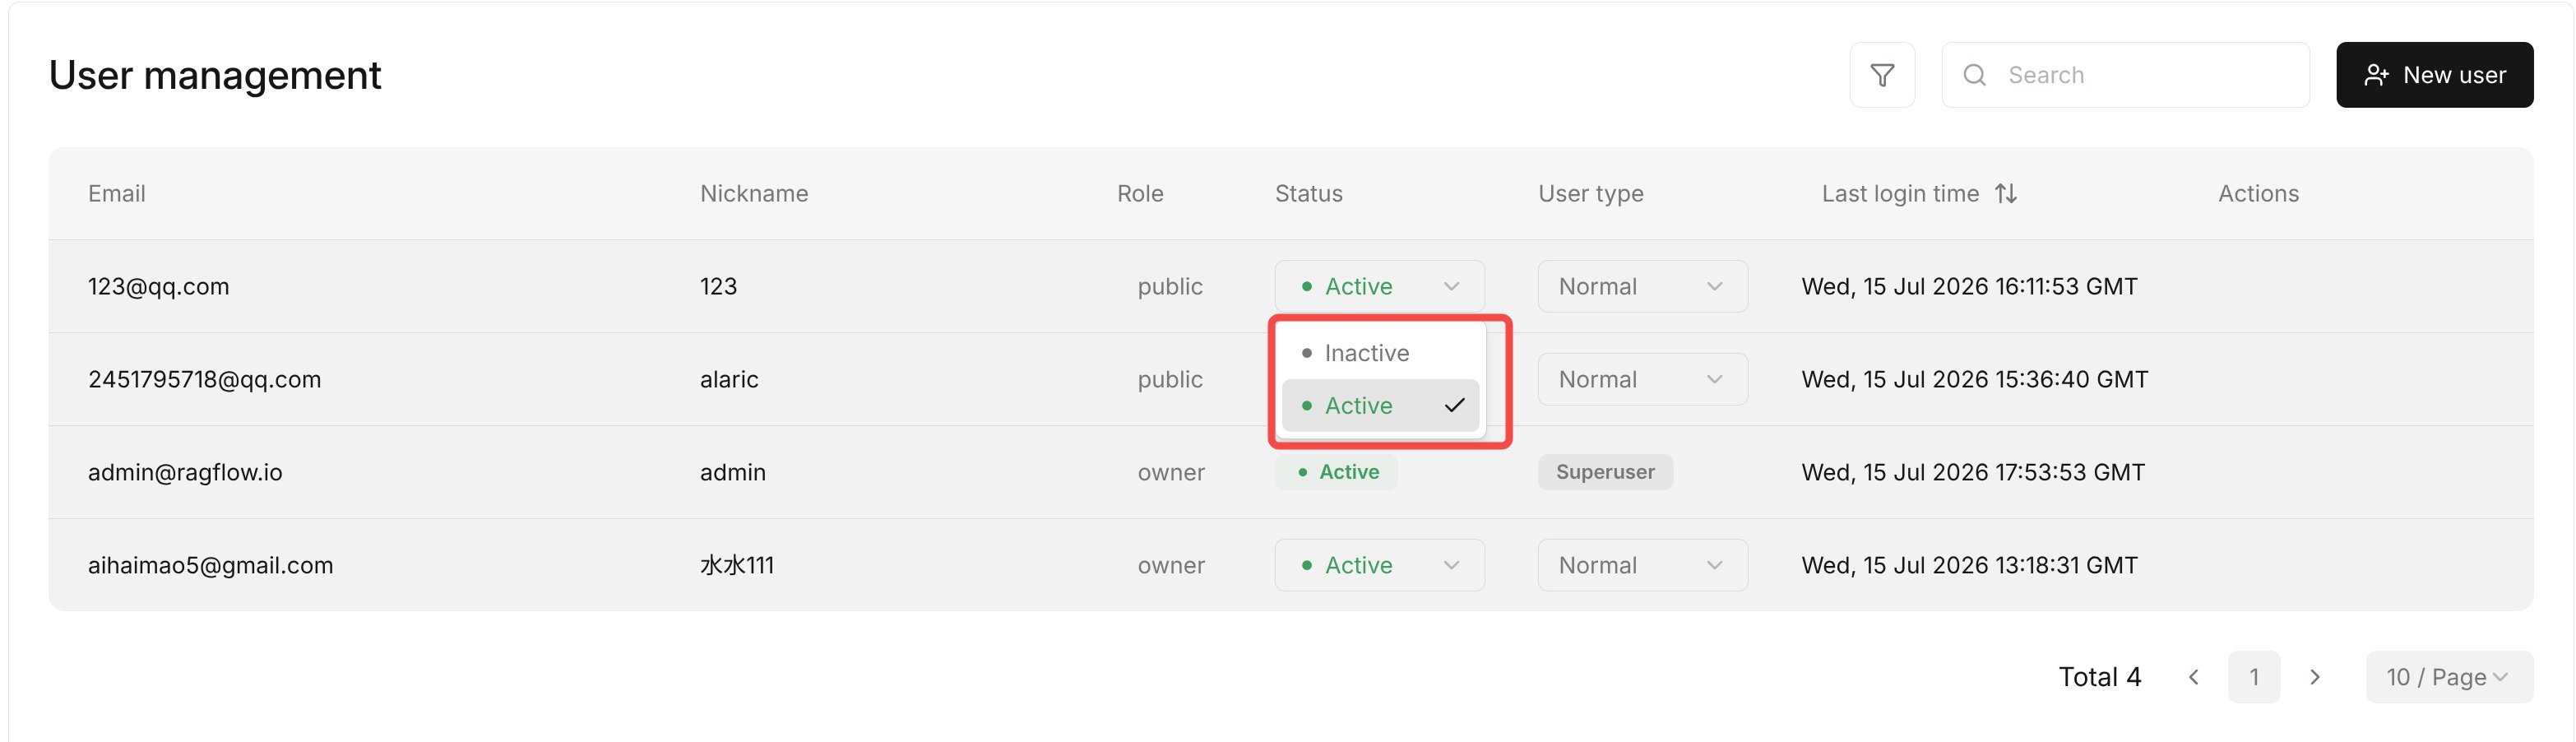
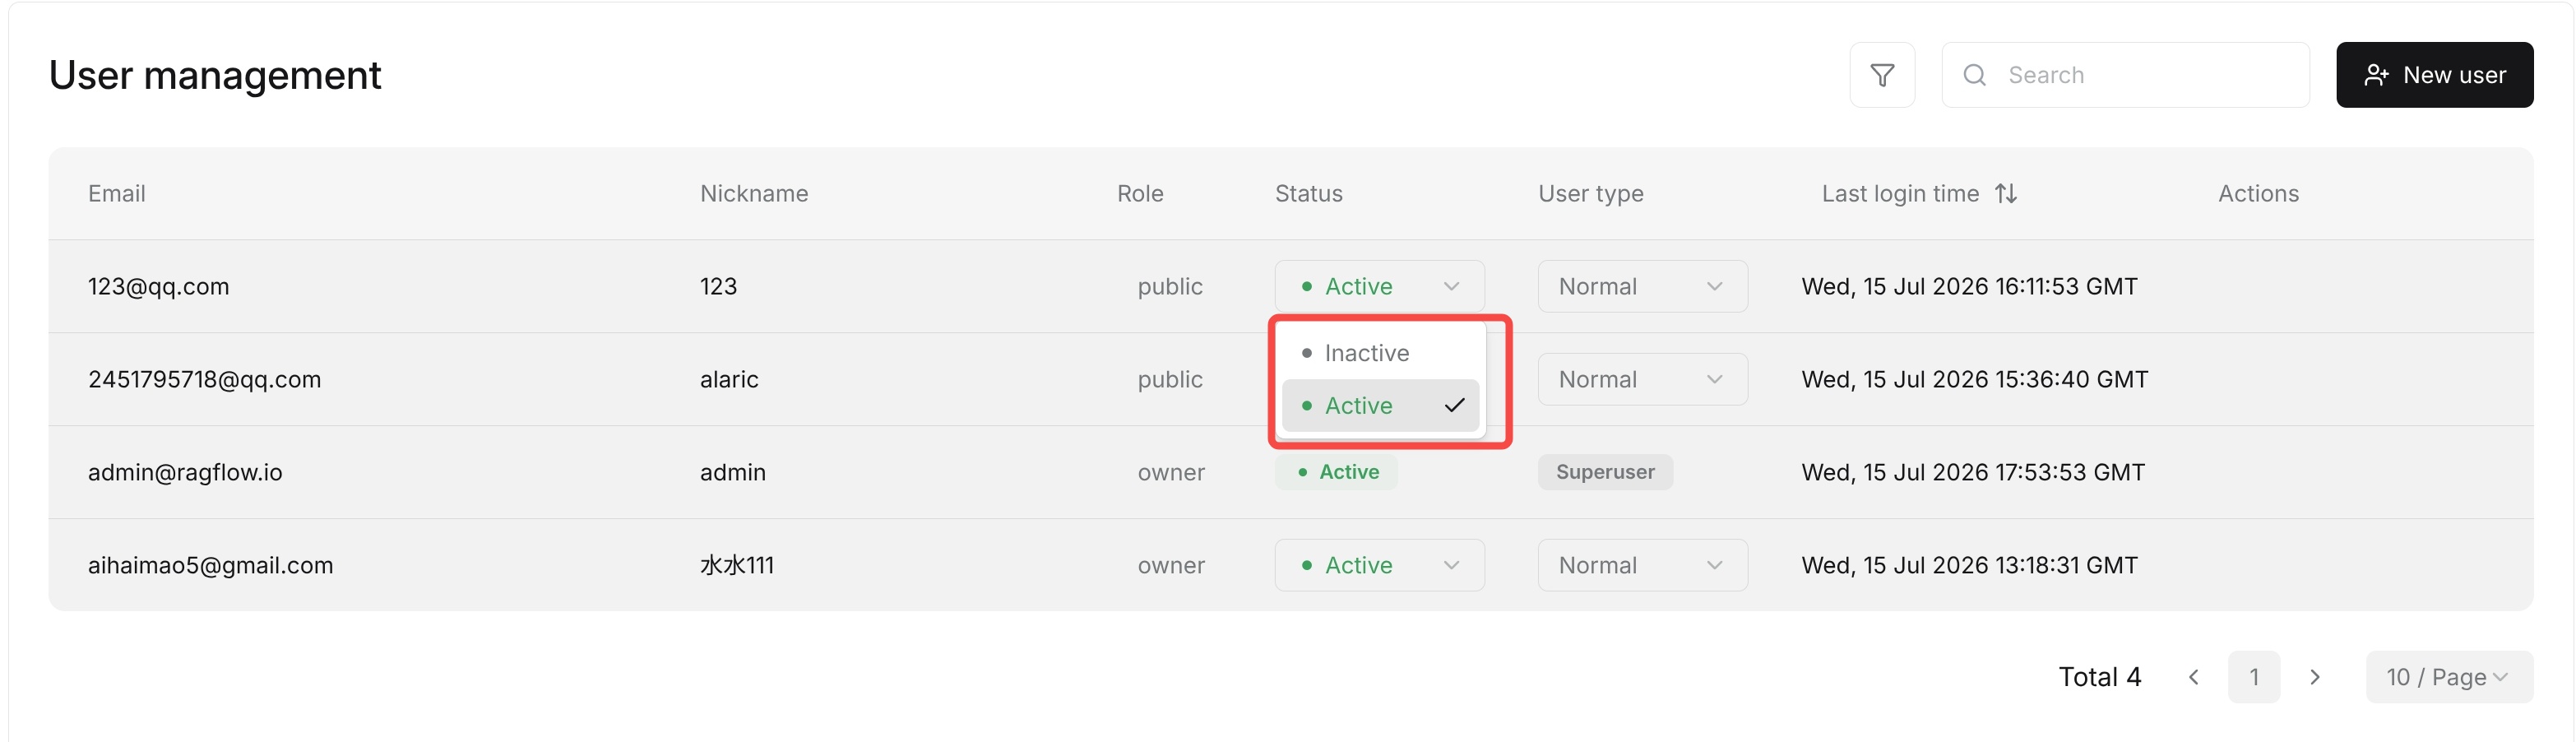
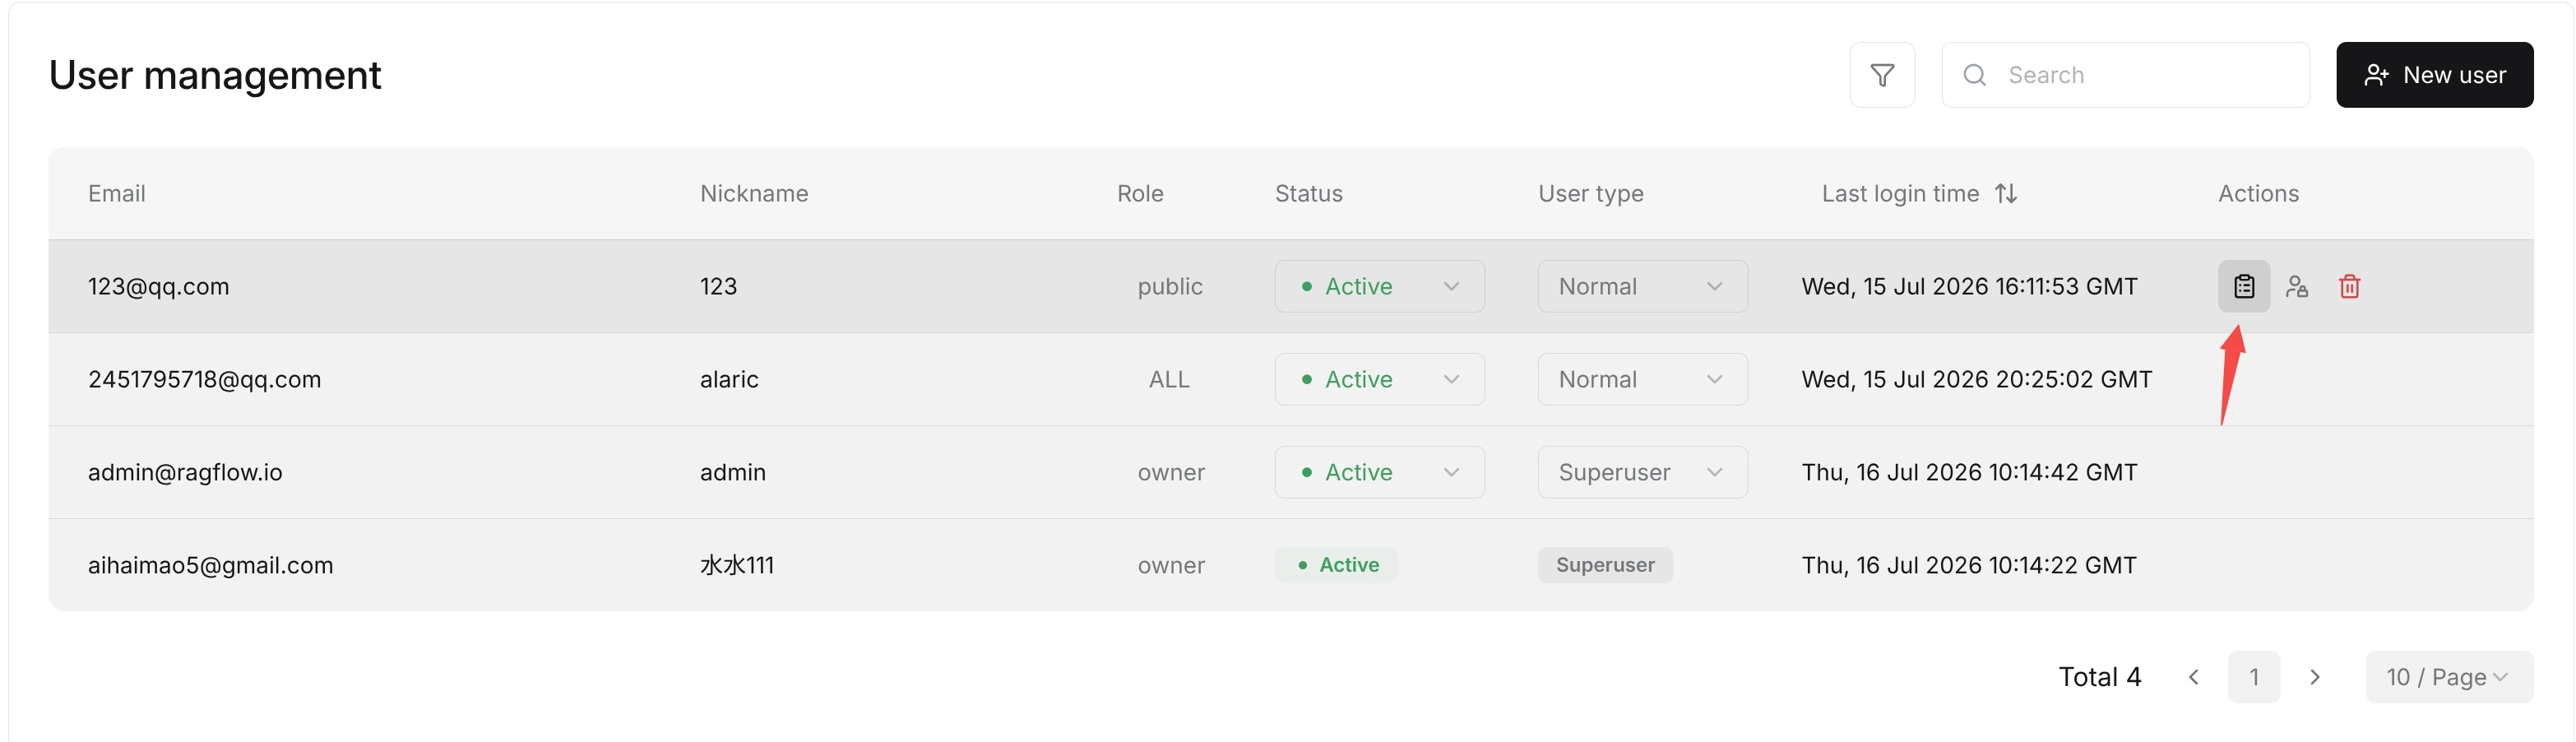
User accounts are managed on the **Users** page. Administrators can view the user list, including `Email`, `Nickname`, `Status`, and `User type`.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
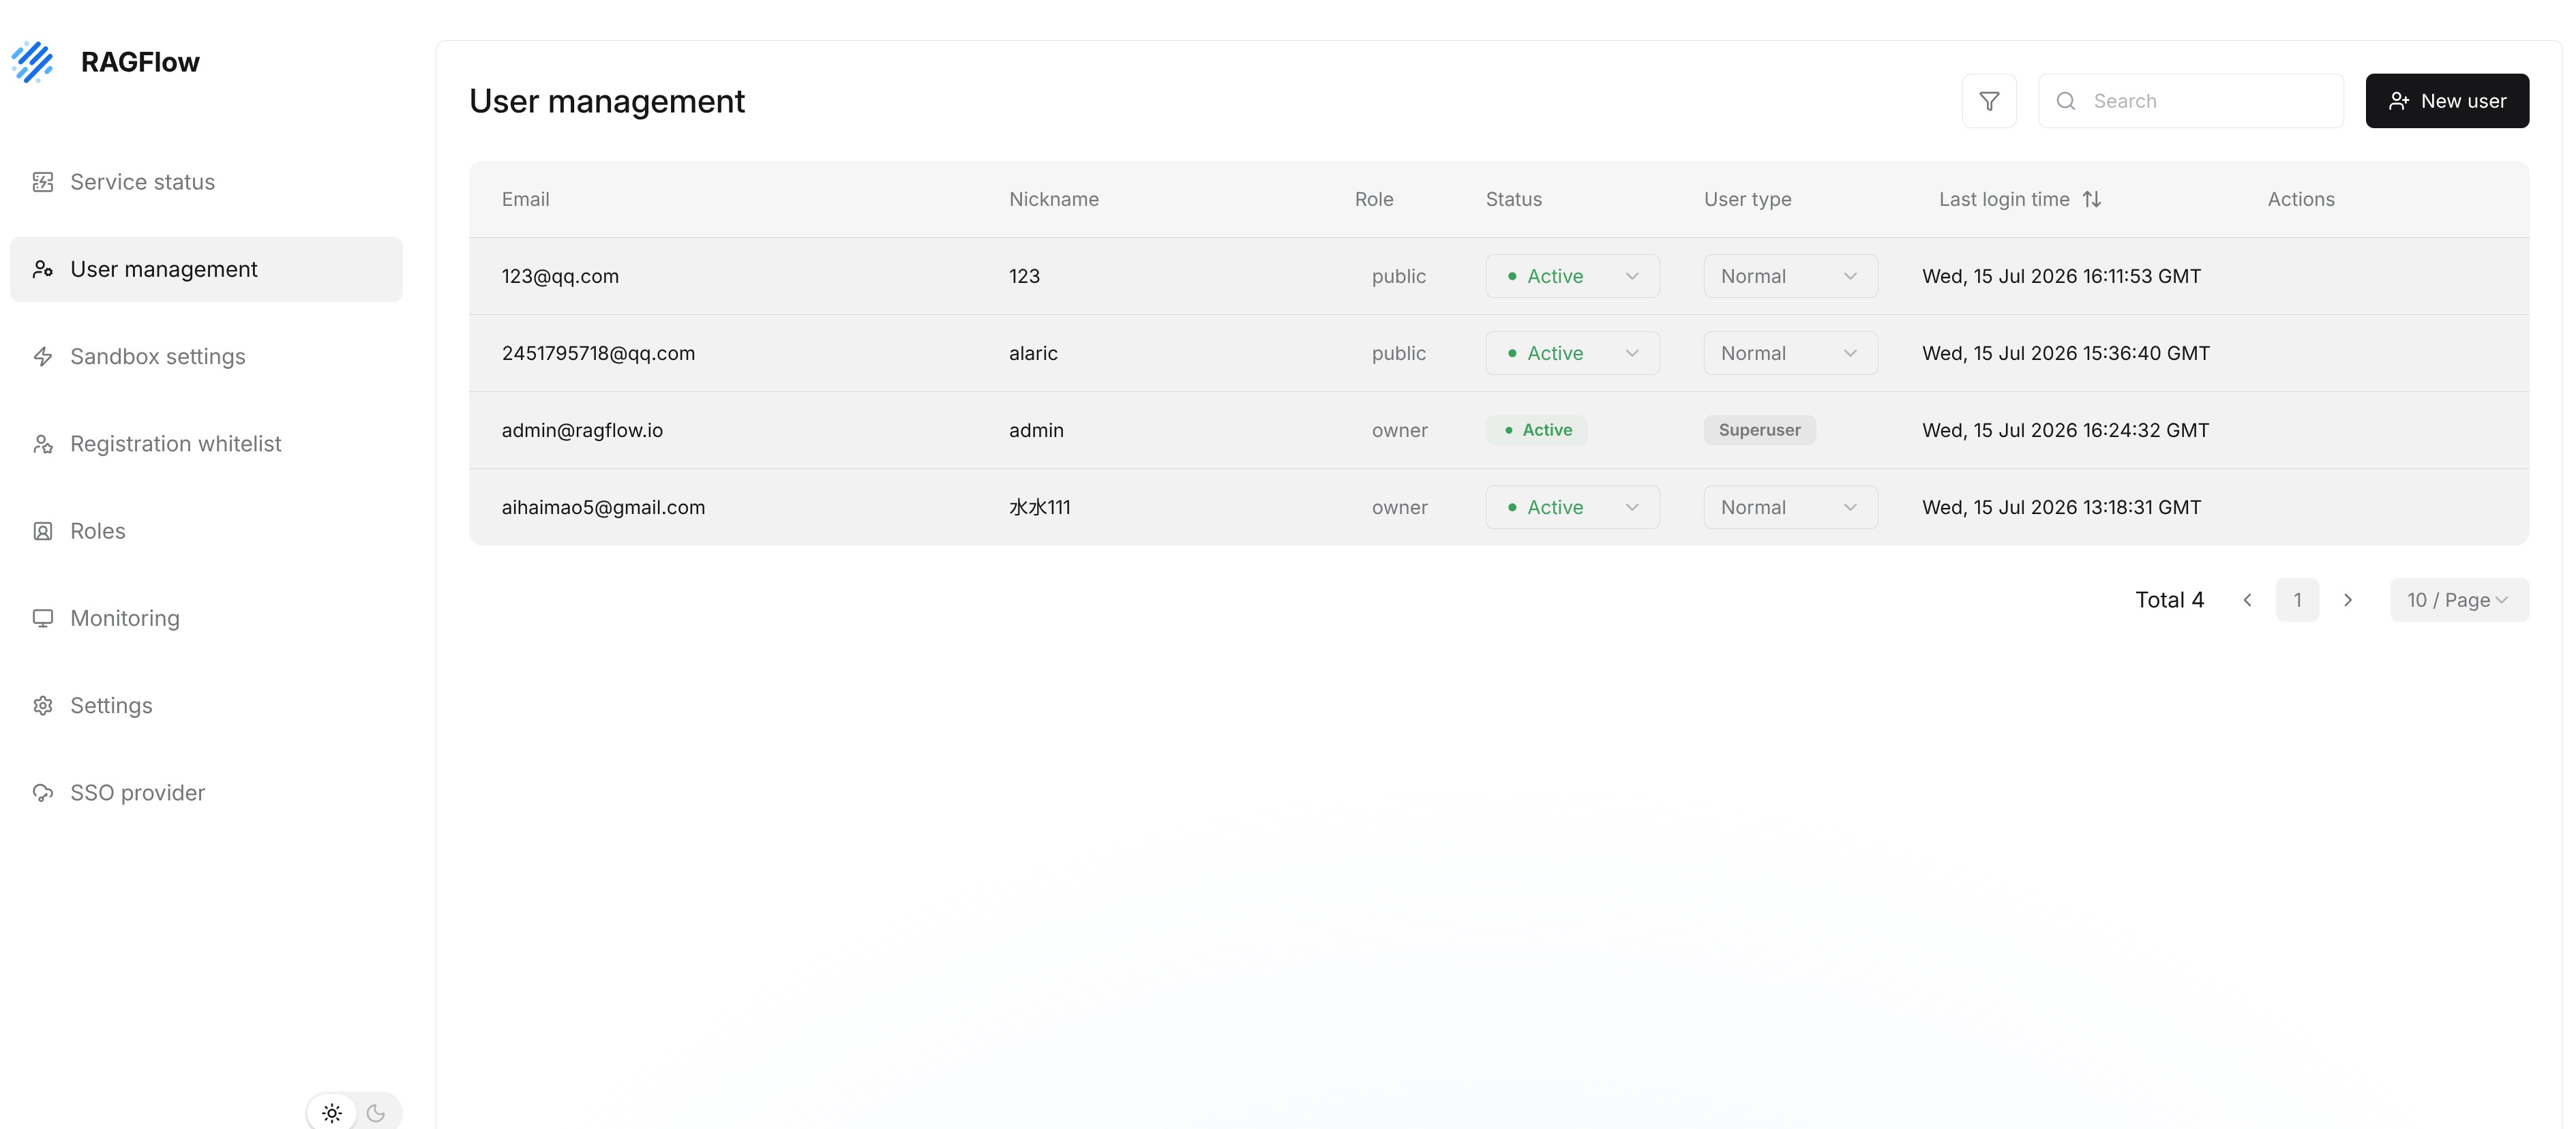
Use the search box in the upper-right corner to search users by `Email` or `Nickname`. You can also filter `Active` or `Inactive` users by `Status`.
|
||||
|
||||
|
||||
|
||||
@@ -27,6 +27,8 @@ Use token-based chunking for text without reliable section structure. Click the
|
||||
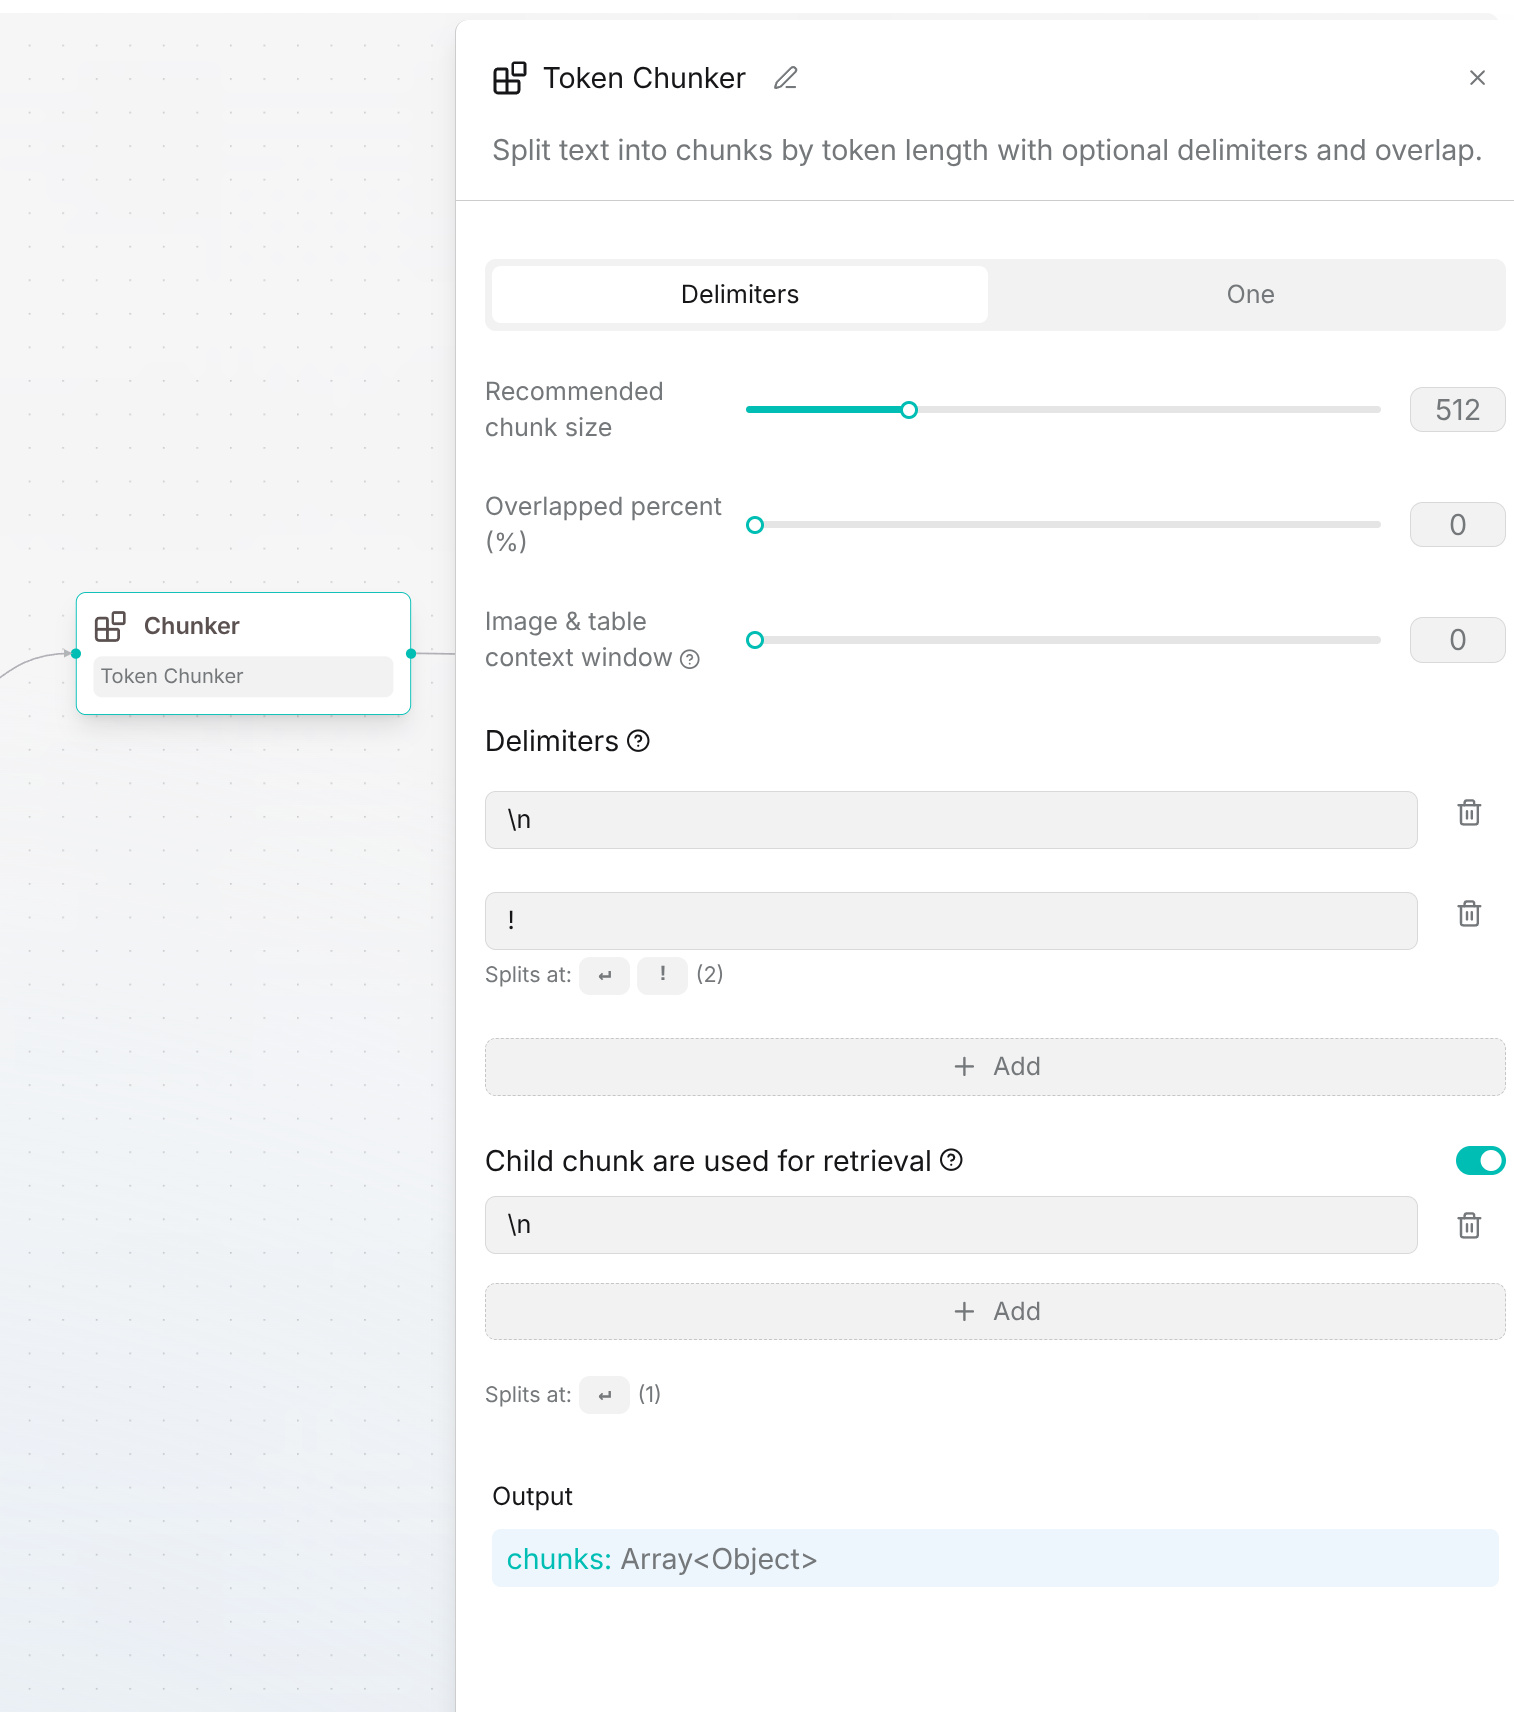
| Delimiters | Defaults to `\n`, `!`, `?`, `;`, `。`, `;`, `!`, and `?`. Each entry is a separate delimiter. Edit or remove entries, or click **Add** for another delimiter; check the **Splits at** preview. |
|
||||
| Child chunk are used for retrieval | Splits parent chunks into smaller retrieval chunks using **Child delimiters**, which appear after enabling the switch. Disabled by default. For line-based child chunks, enable it and add `\n`. |
|
||||
|
||||
|
||||
|
||||
The output is `chunks`, an array of objects that downstream components can process.
|
||||
|
||||
Click **Save draft** after configuring the node. [Publish and validate](./test_run.md) on a sample to check chunk boundaries, overlap, and child chunks.
|
||||
@@ -45,4 +47,6 @@ Use Title Chunker for documents with clear headings, such as manuals and papers.
|
||||
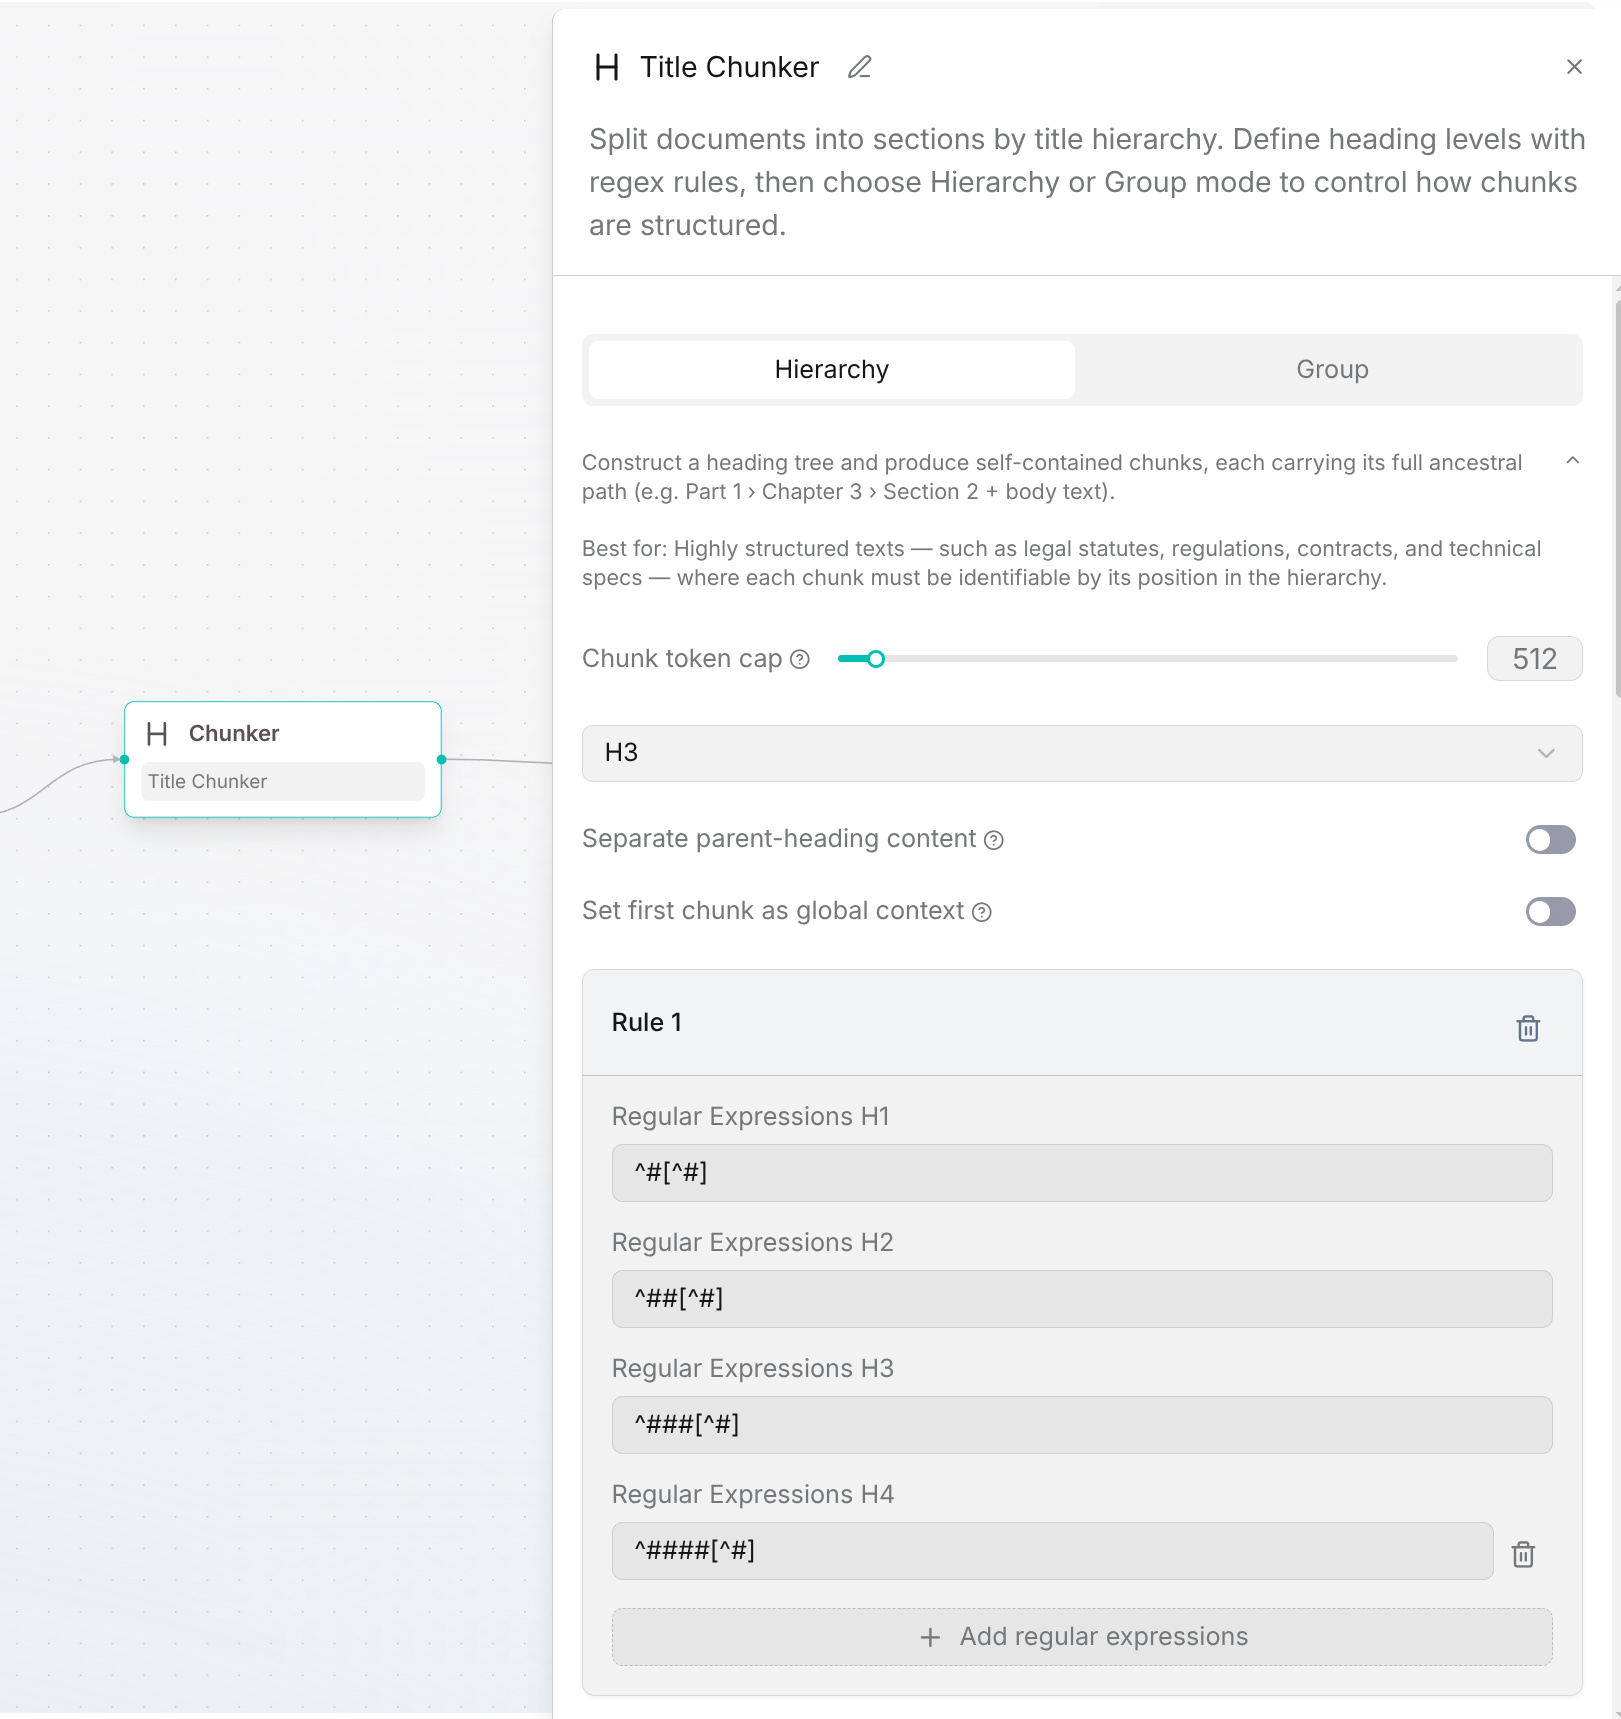
| Separate parent-heading content | Keeps content directly below a parent heading in a separate chunk. Disabled by default. |
|
||||
| Set first chunk as global context | Uses the first section as shared context across the heading hierarchy. Disabled by default. |
|
||||
|
||||
|
||||
|
||||
For Markdown headings, add `^# ` for level 1 and `^## ` for level 2, then select level 2. In Hierarchy mode, check that each subsection retains its parent heading. Use the output `chunks` in downstream components.
|
||||
@@ -37,6 +37,8 @@ Select the content to embed:
|
||||
|
||||
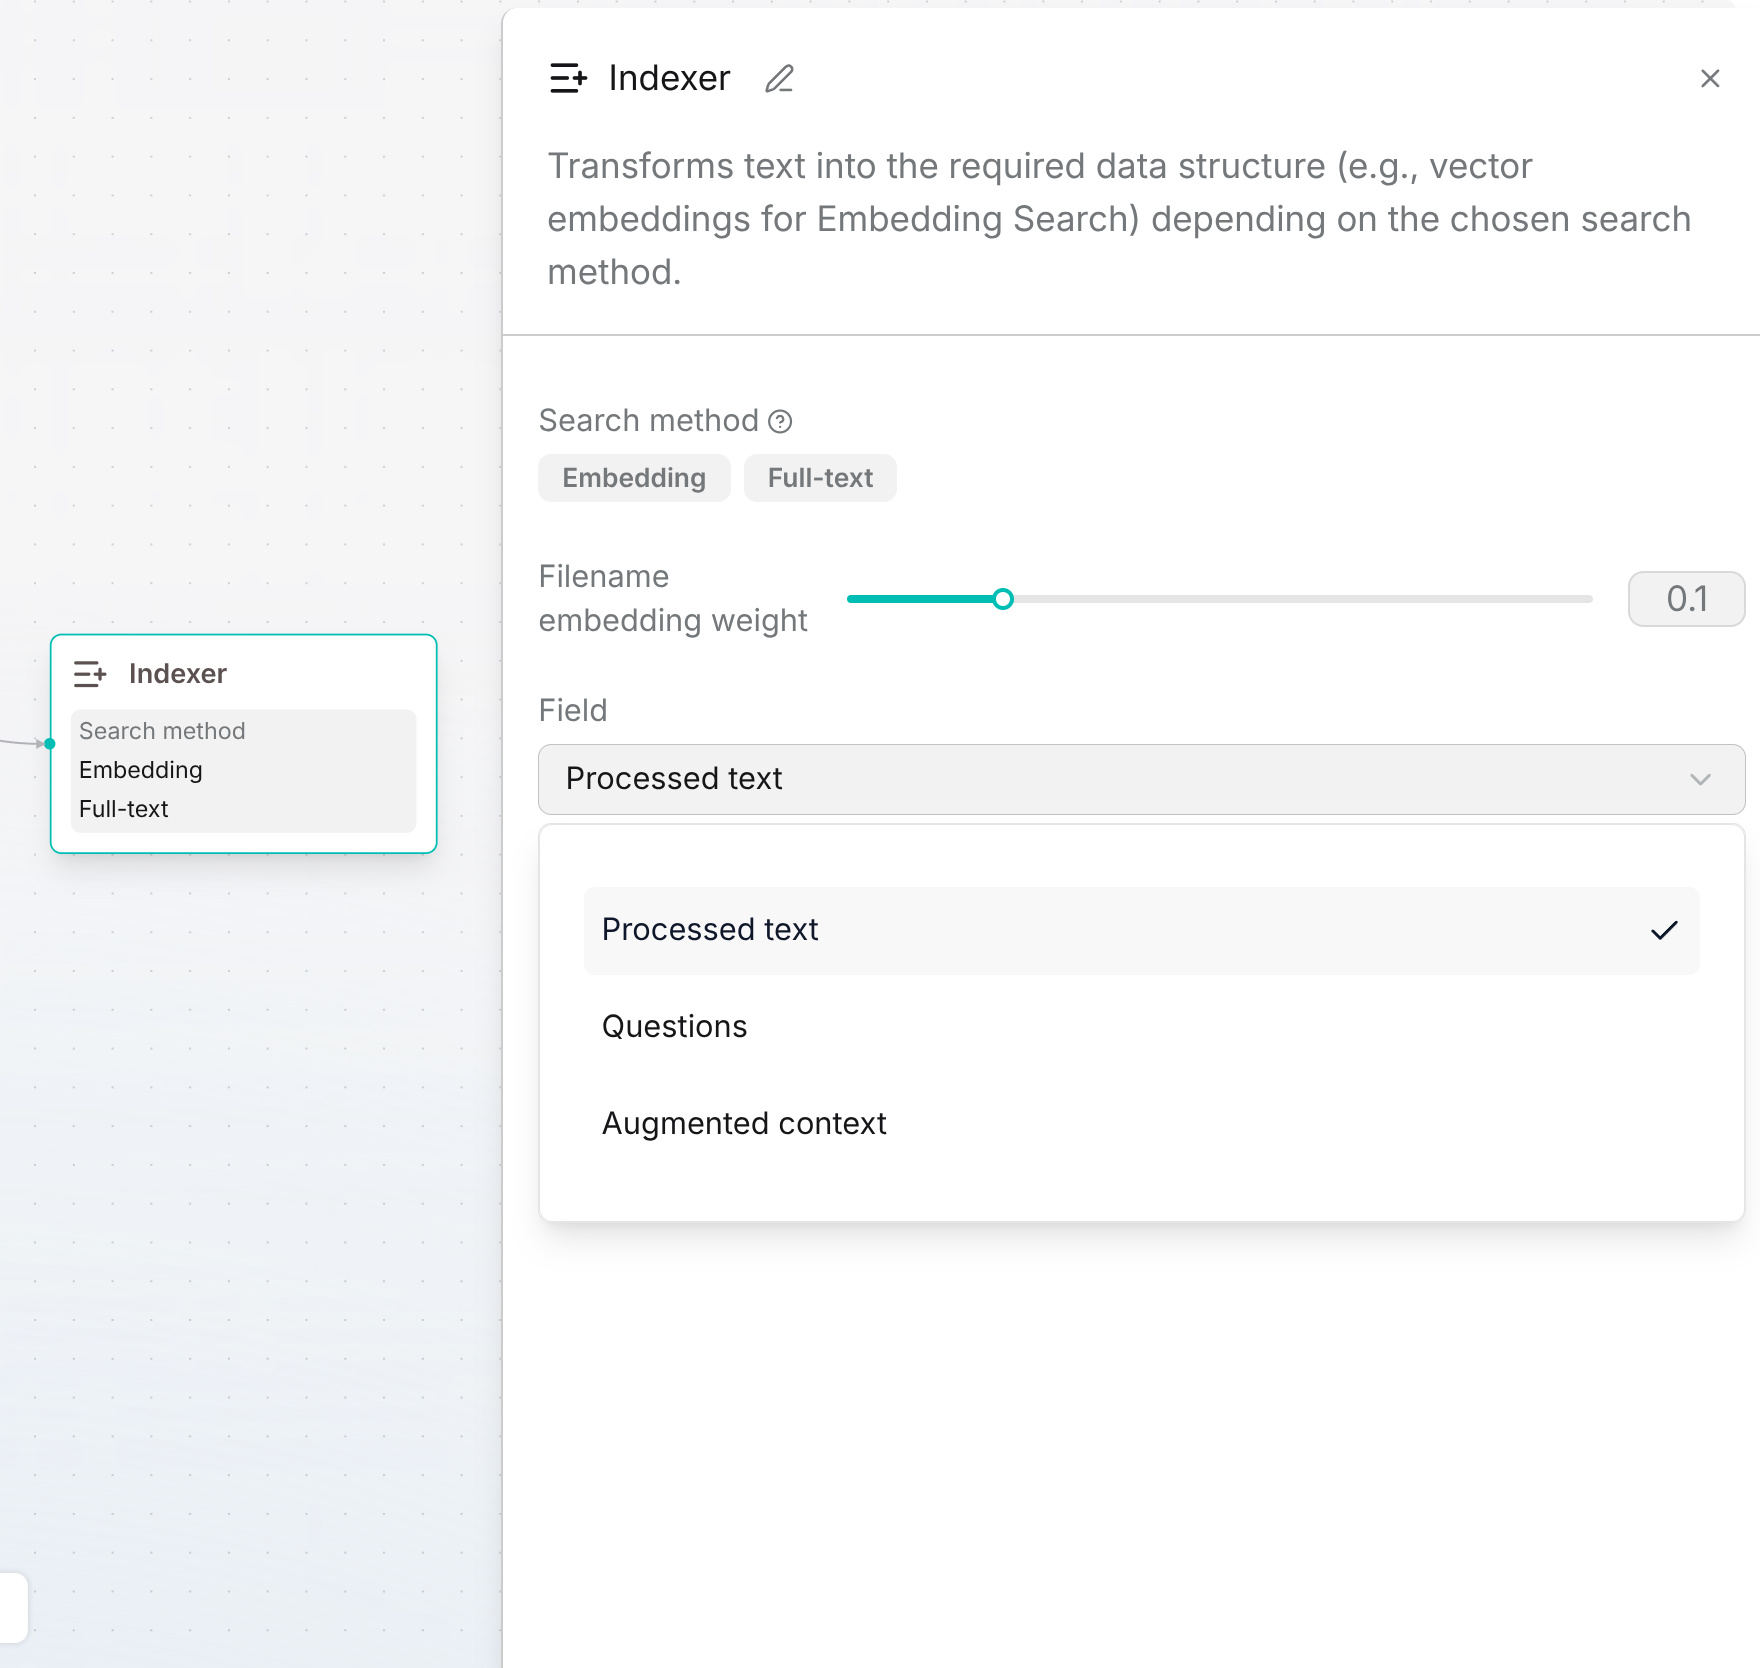
For Questions or Augmented context, first enable the corresponding function in Transformer. This setting selects embedding content; it does not replace the configured search methods.
|
||||
|
||||
|
||||
|
||||
## Embedding model
|
||||
|
||||
The model comes from the connected knowledge base, rather than an independent model selector in this panel. Knowledge bases searched together must use the same embedding model.
|
||||
|
||||
@@ -52,6 +52,8 @@ Configured OCR and vision models depend on the pipeline owner's available provid
|
||||
|
||||
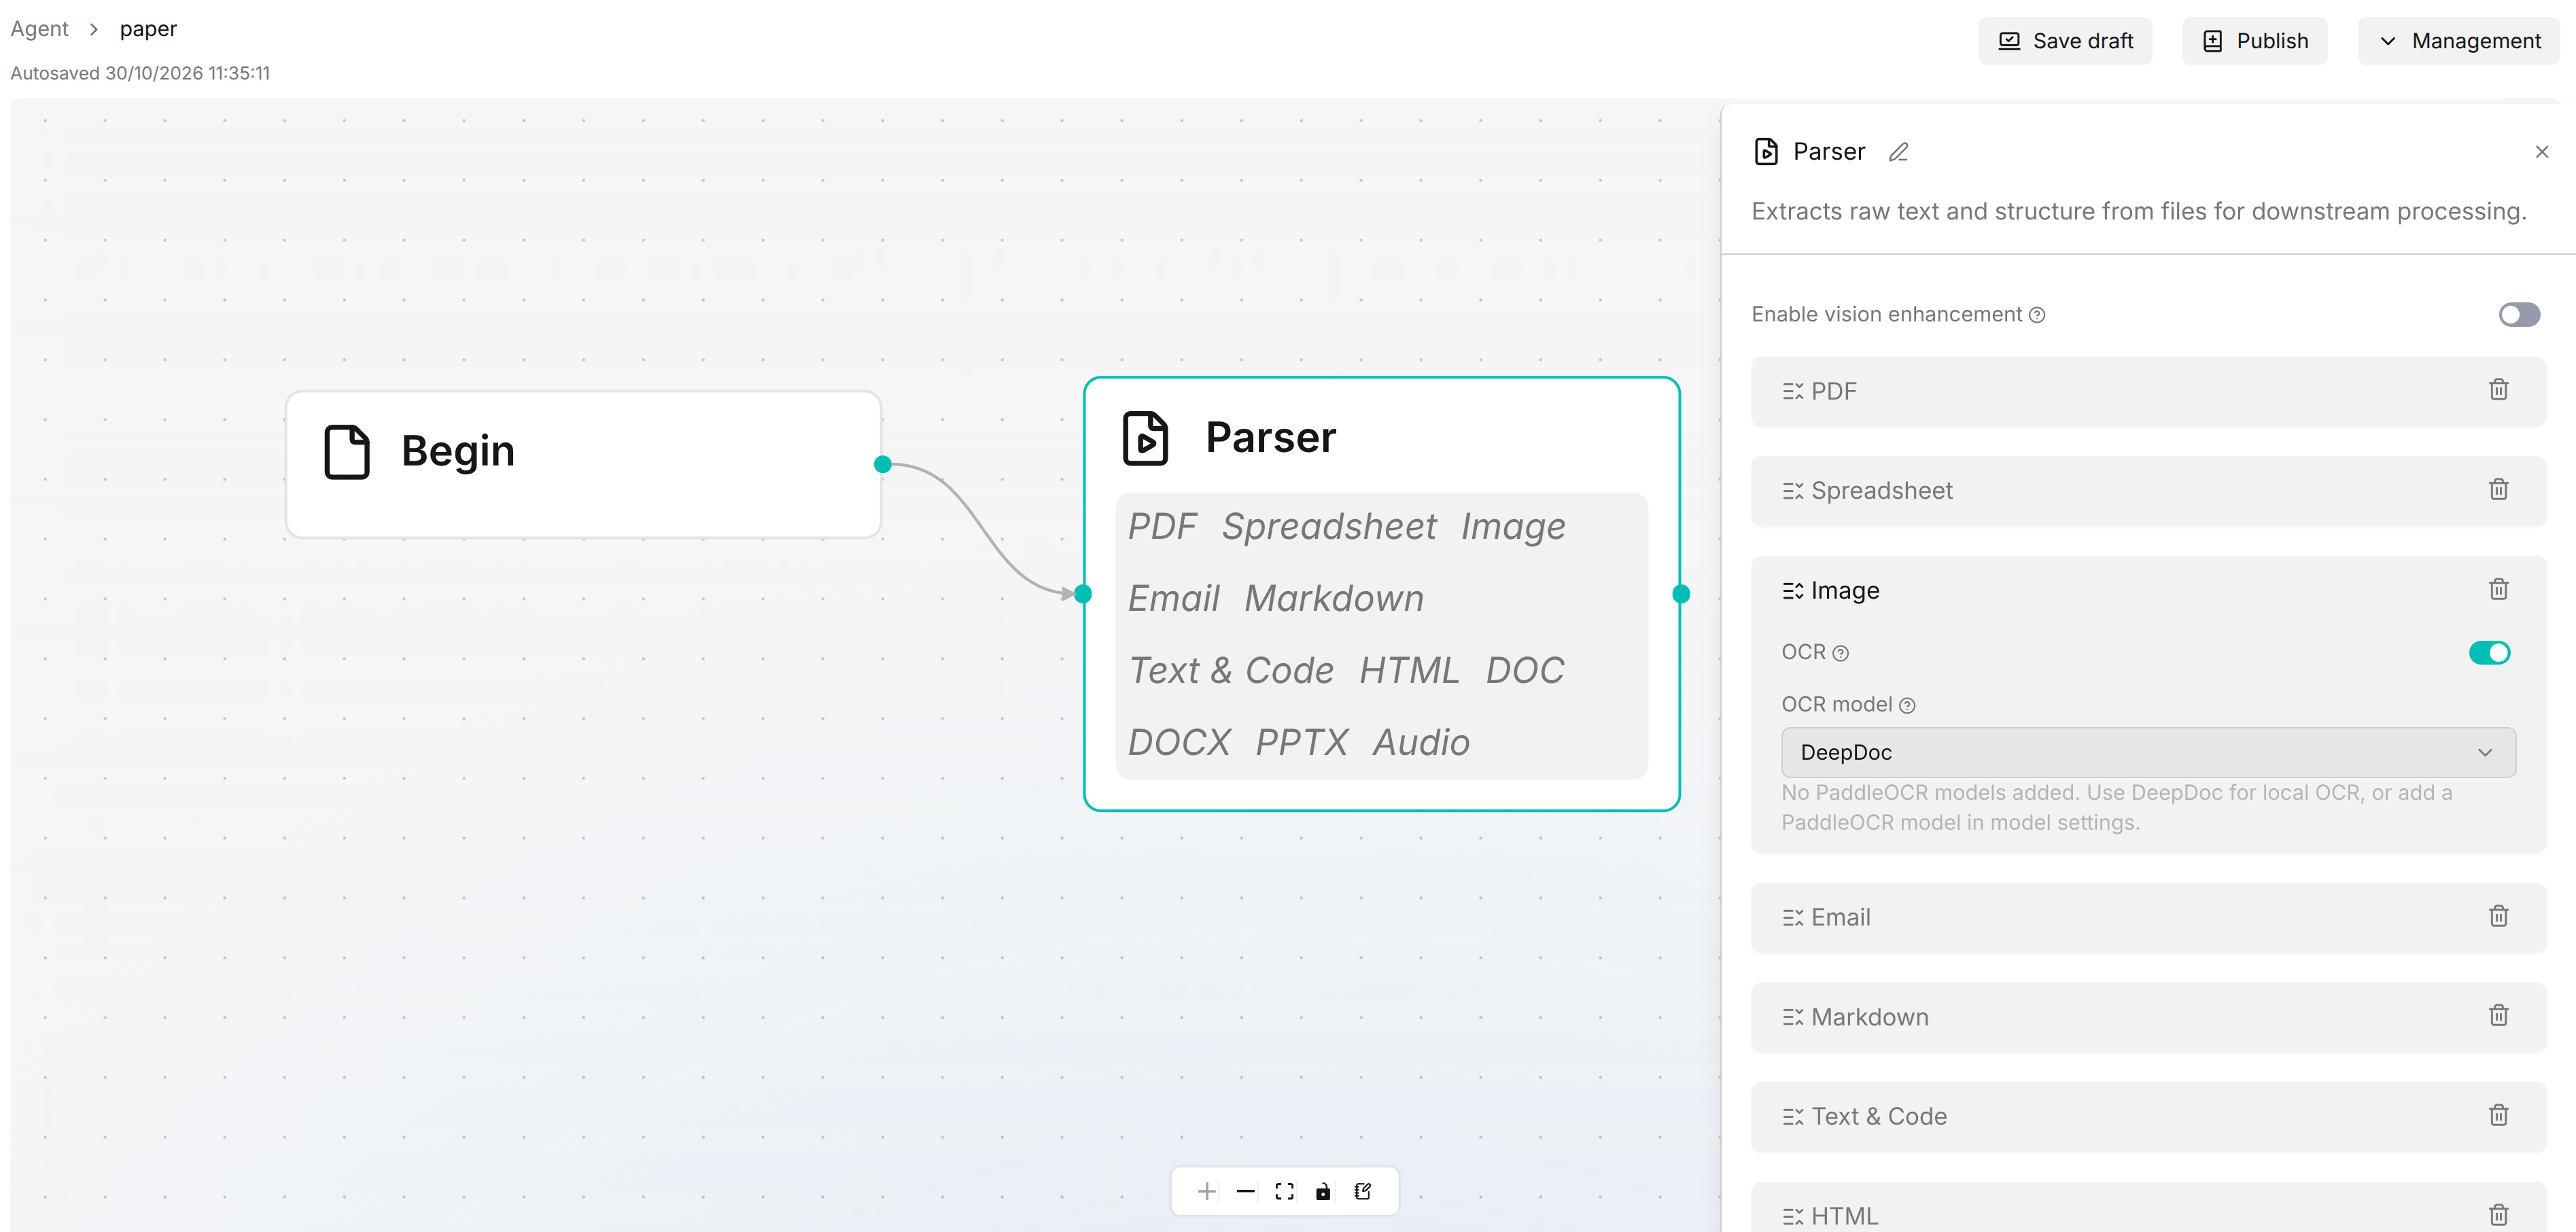
To turn OCR off, enable vision enhancement first. The panel rejects a configuration with both disabled.
|
||||
|
||||
|
||||
|
||||
## Other File Categories
|
||||
|
||||
| Category | Configuration |
|
||||
|
||||
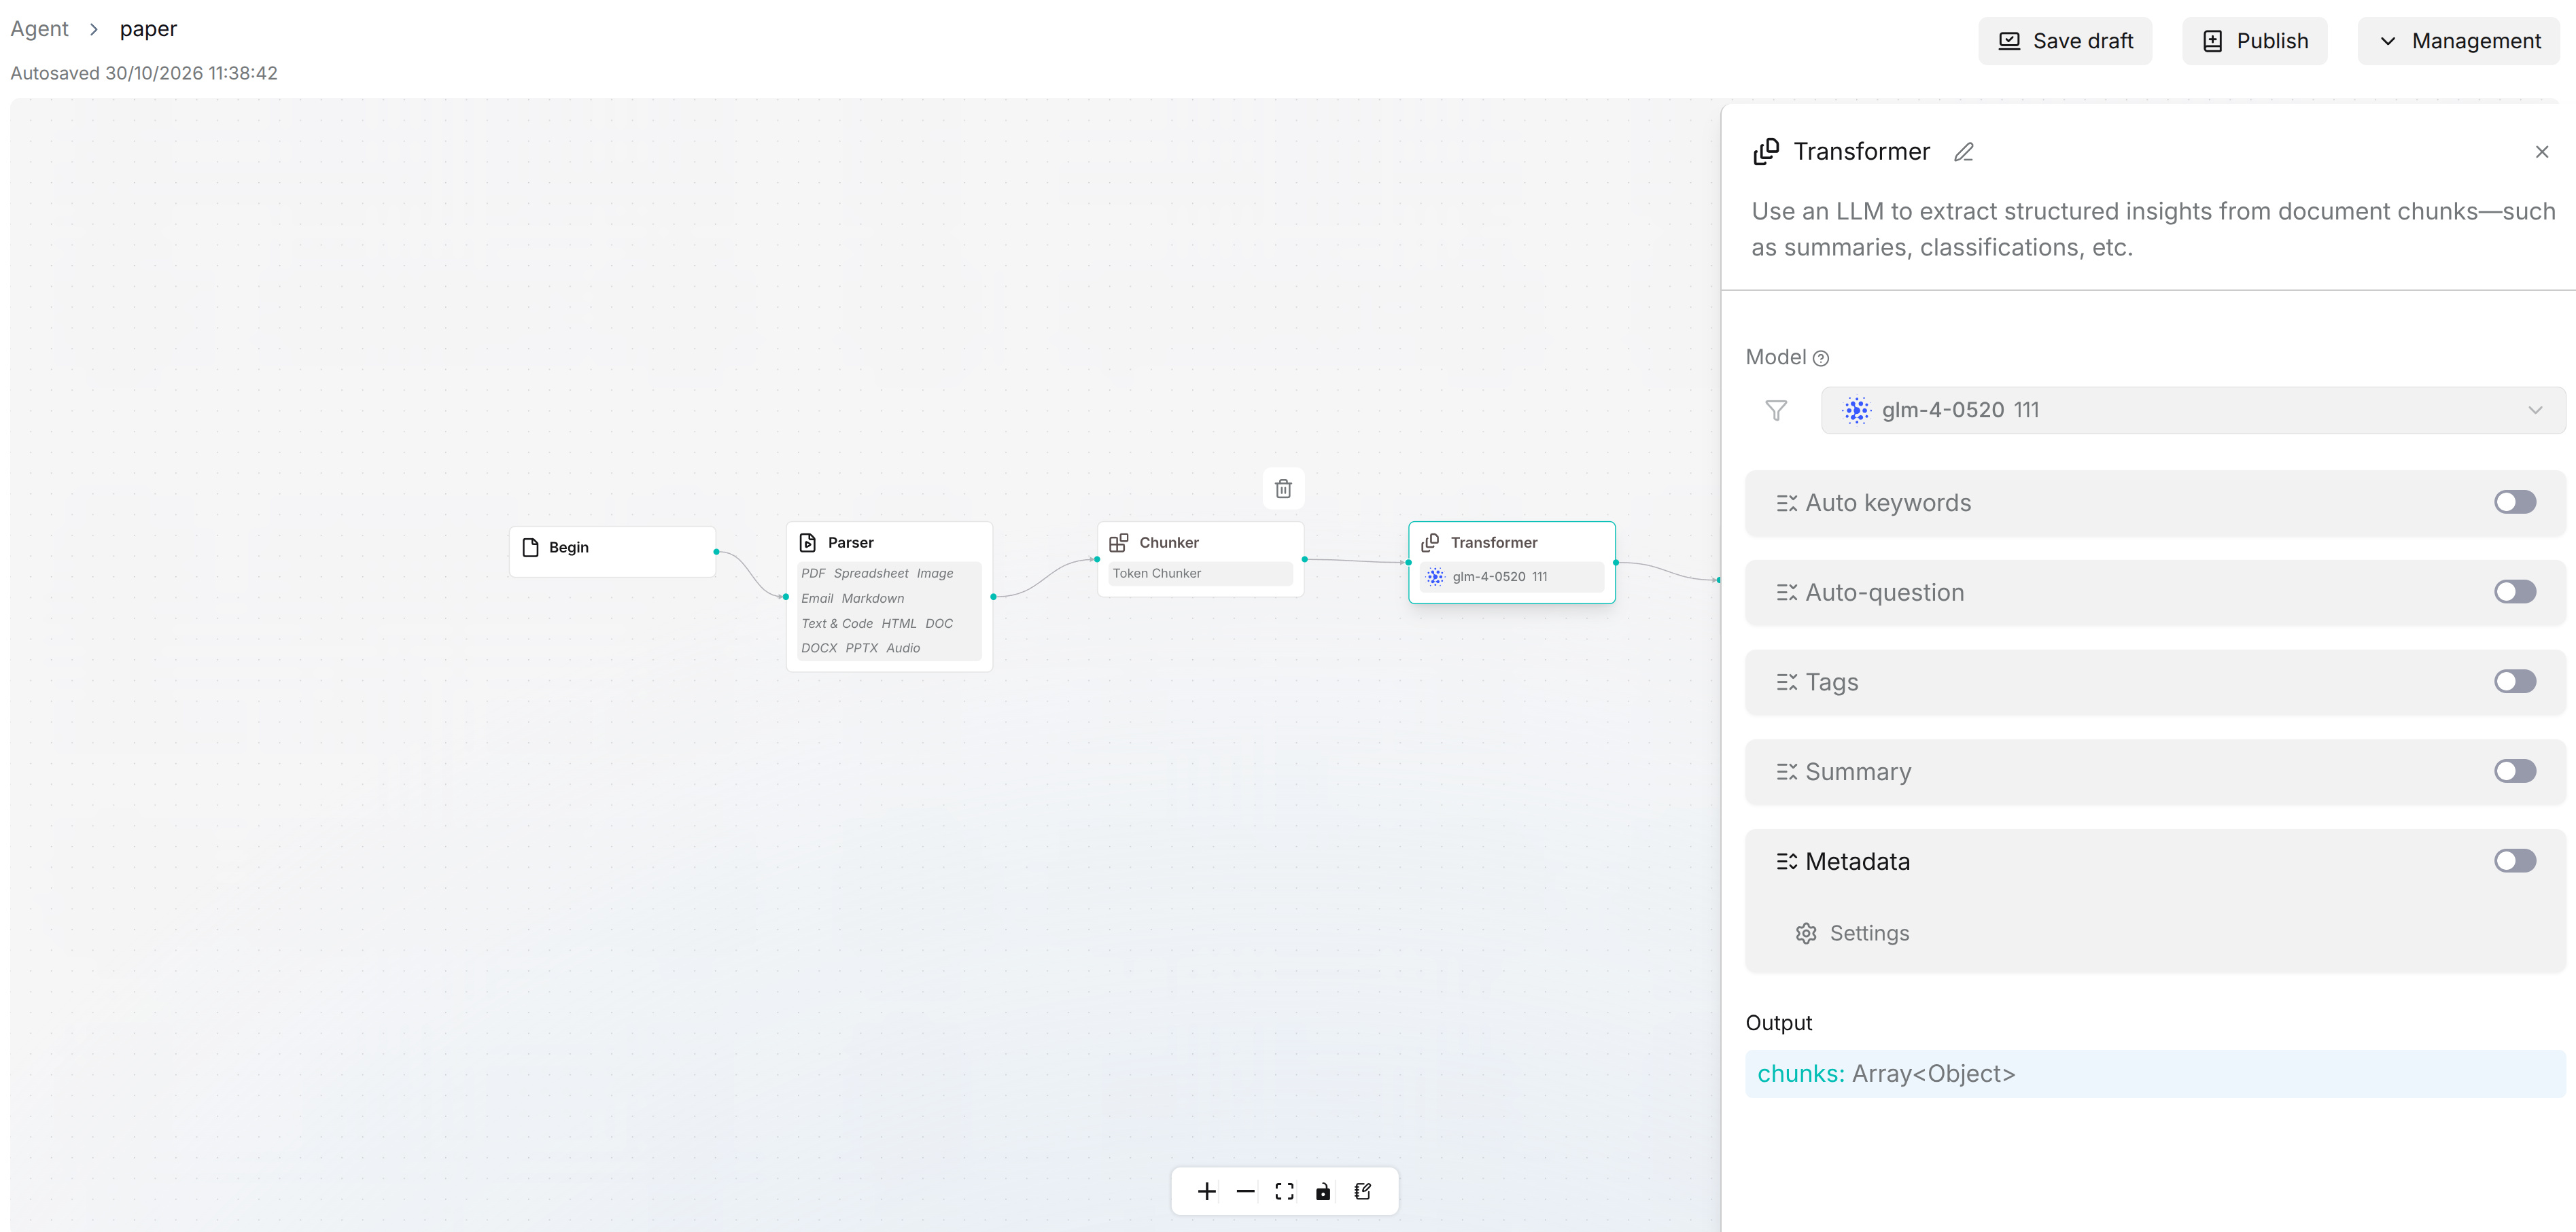
@@ -33,6 +33,8 @@ The panel lists **Auto keywords**, **Auto-question**, **Tags**, **Summary**, and
|
||||
|
||||
Enable only the functions you need. Review the prompts for your document language, required output, and business scope before processing a large collection of files.
|
||||
|
||||
|
||||
|
||||
## Configure Metadata
|
||||
|
||||
1. Expand **Metadata**, turn on its switch, and click **Settings**.
|
||||
|
||||
@@ -16,7 +16,7 @@ Publish a pipeline version before applying a custom pipeline to a Dataset. Savin
|
||||
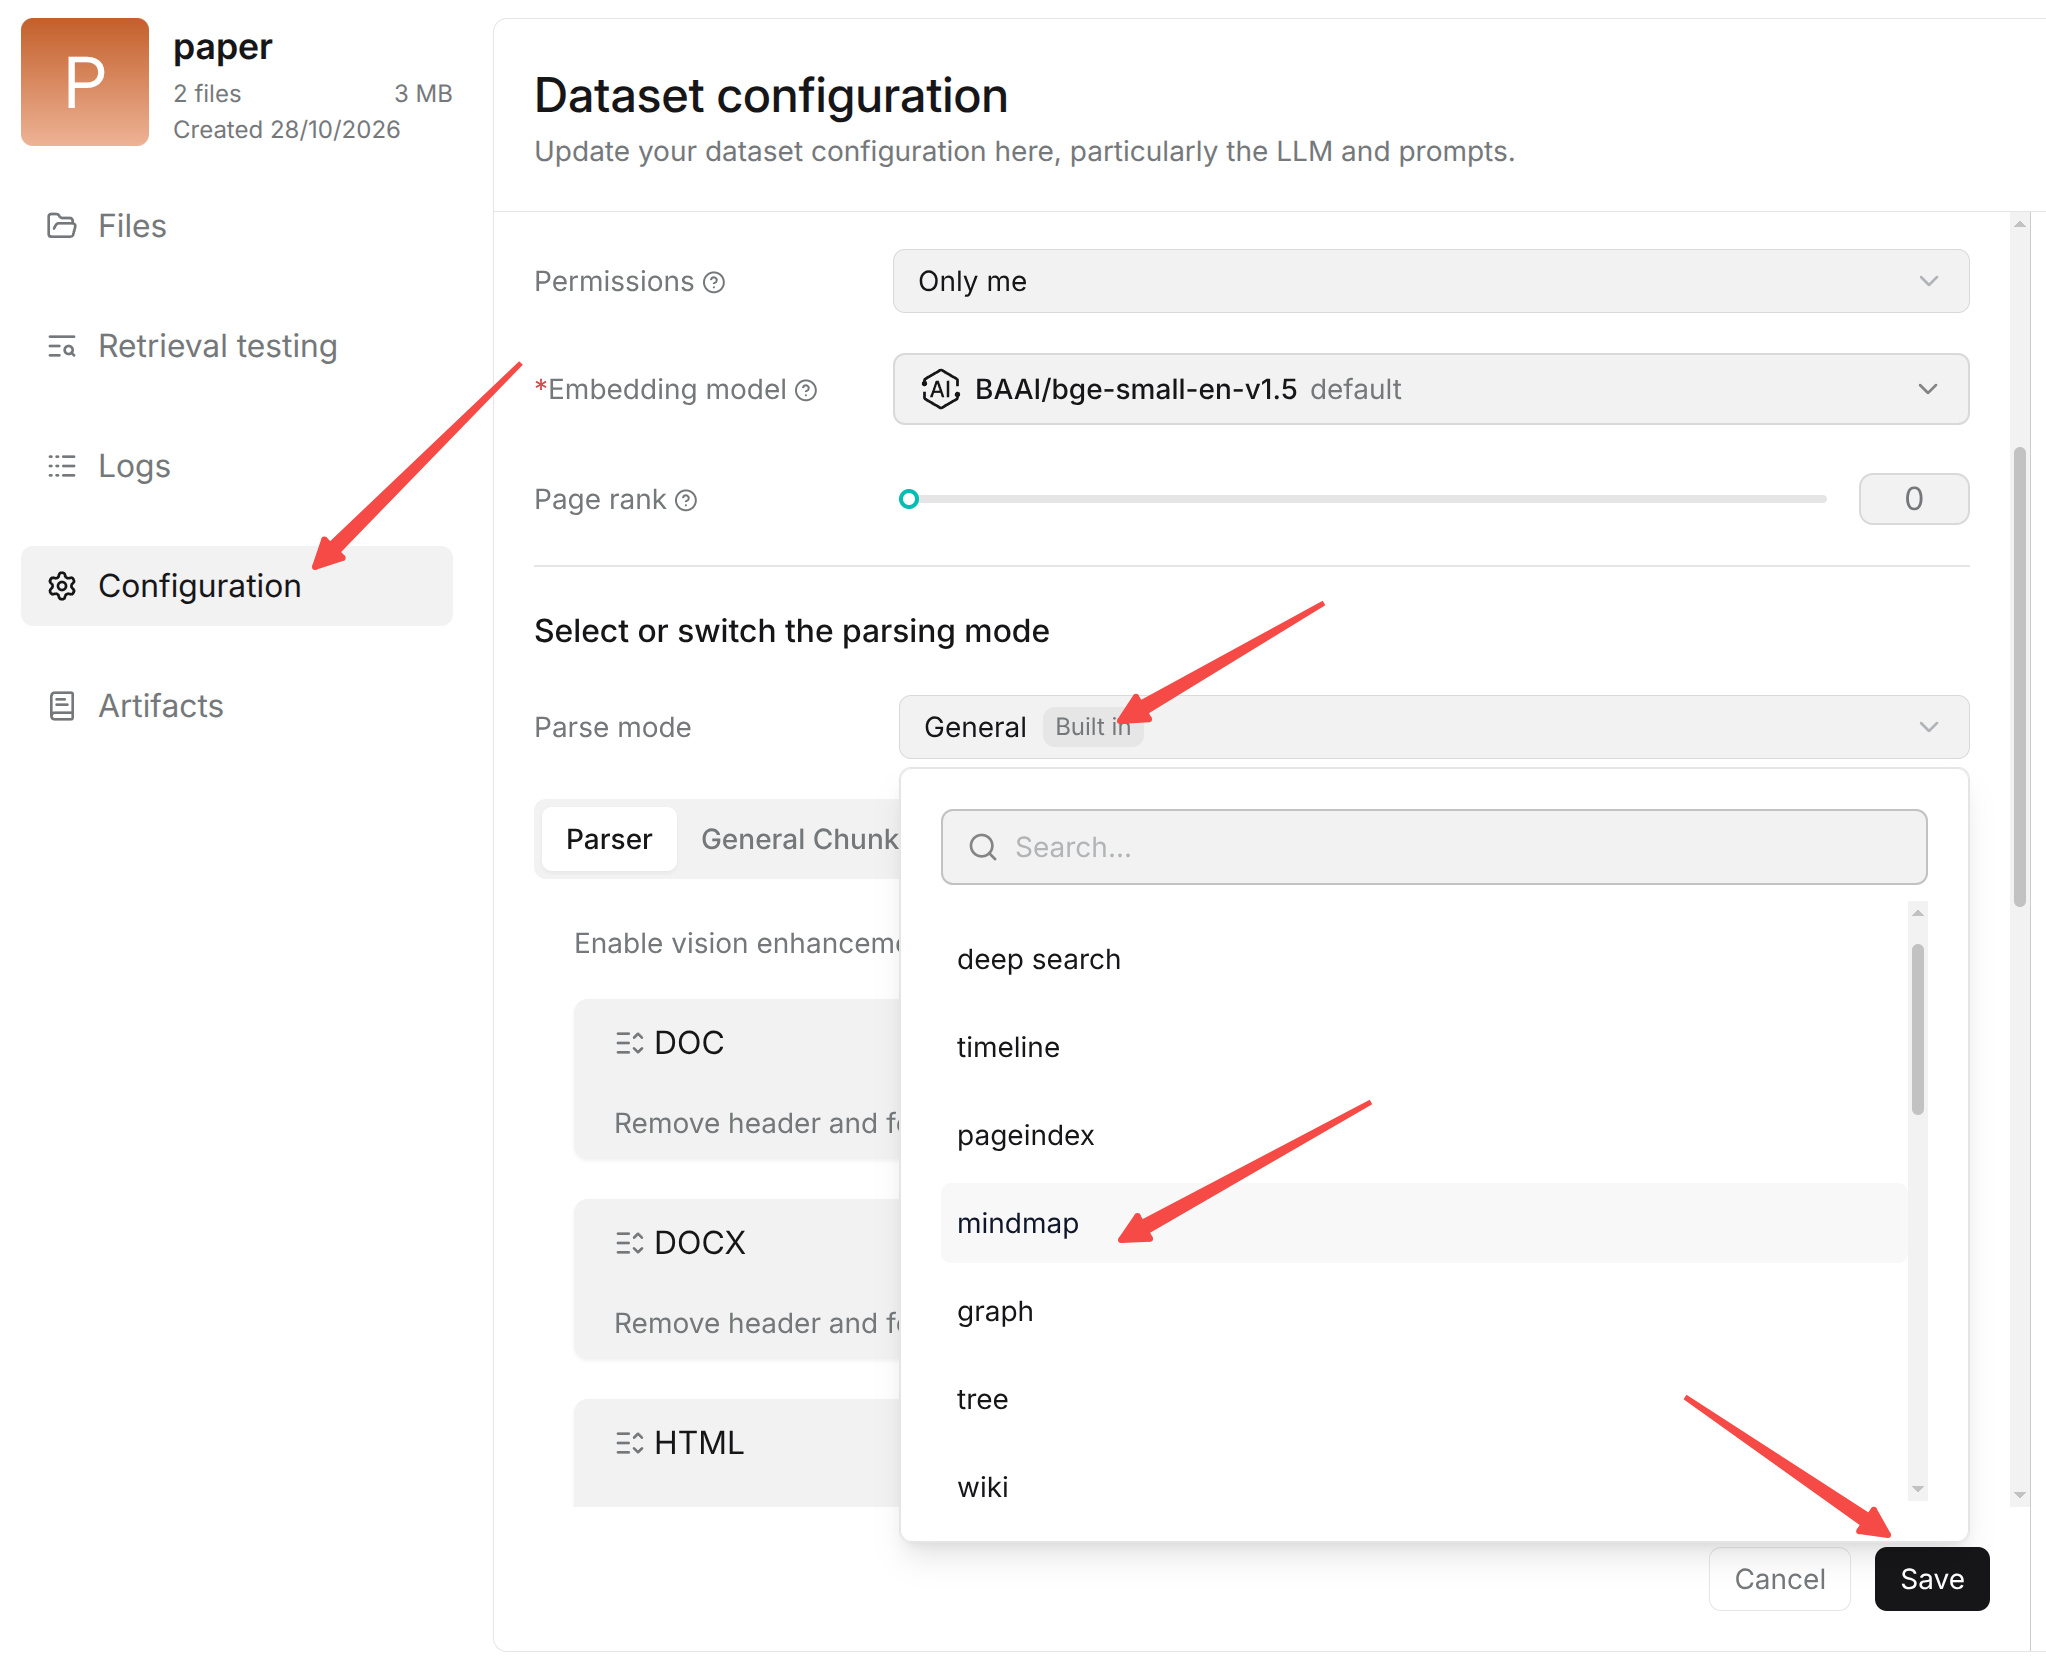
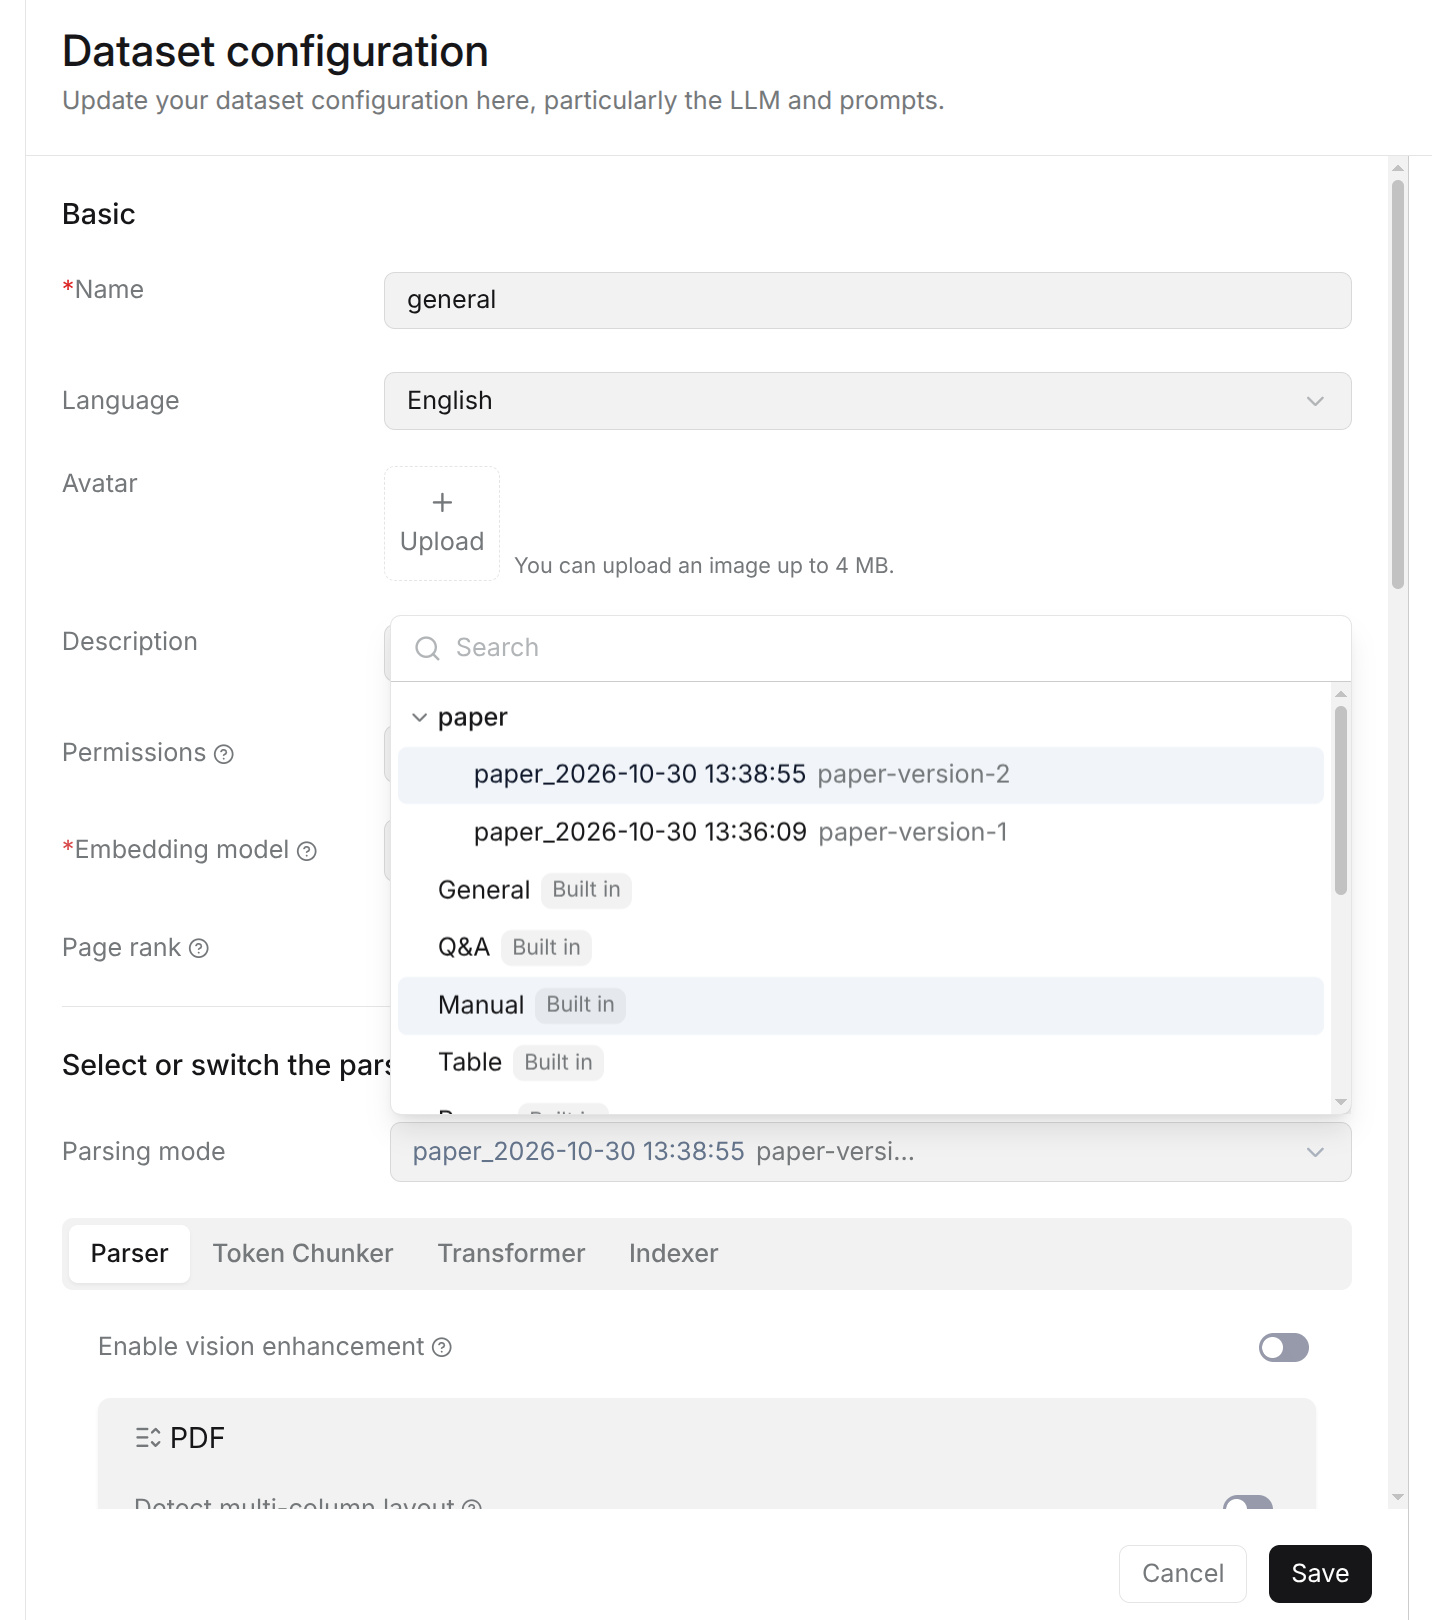
2. Find **Parsing mode** and open its dropdown. Search for the pipeline name if needed.
|
||||
3. Expand the custom pipeline to view its published versions, then select the required version within the same dropdown. Use the version title and alias, when provided, to identify the intended configuration. The pipeline name itself is a group, not a selectable draft.
|
||||
|
||||
|
||||
|
||||
|
||||
4. Click **Save** to apply the selection to the Dataset.
|
||||
5. [Parse a sample document and inspect the results](./test_run.md) before processing more files.
|
||||
|
||||
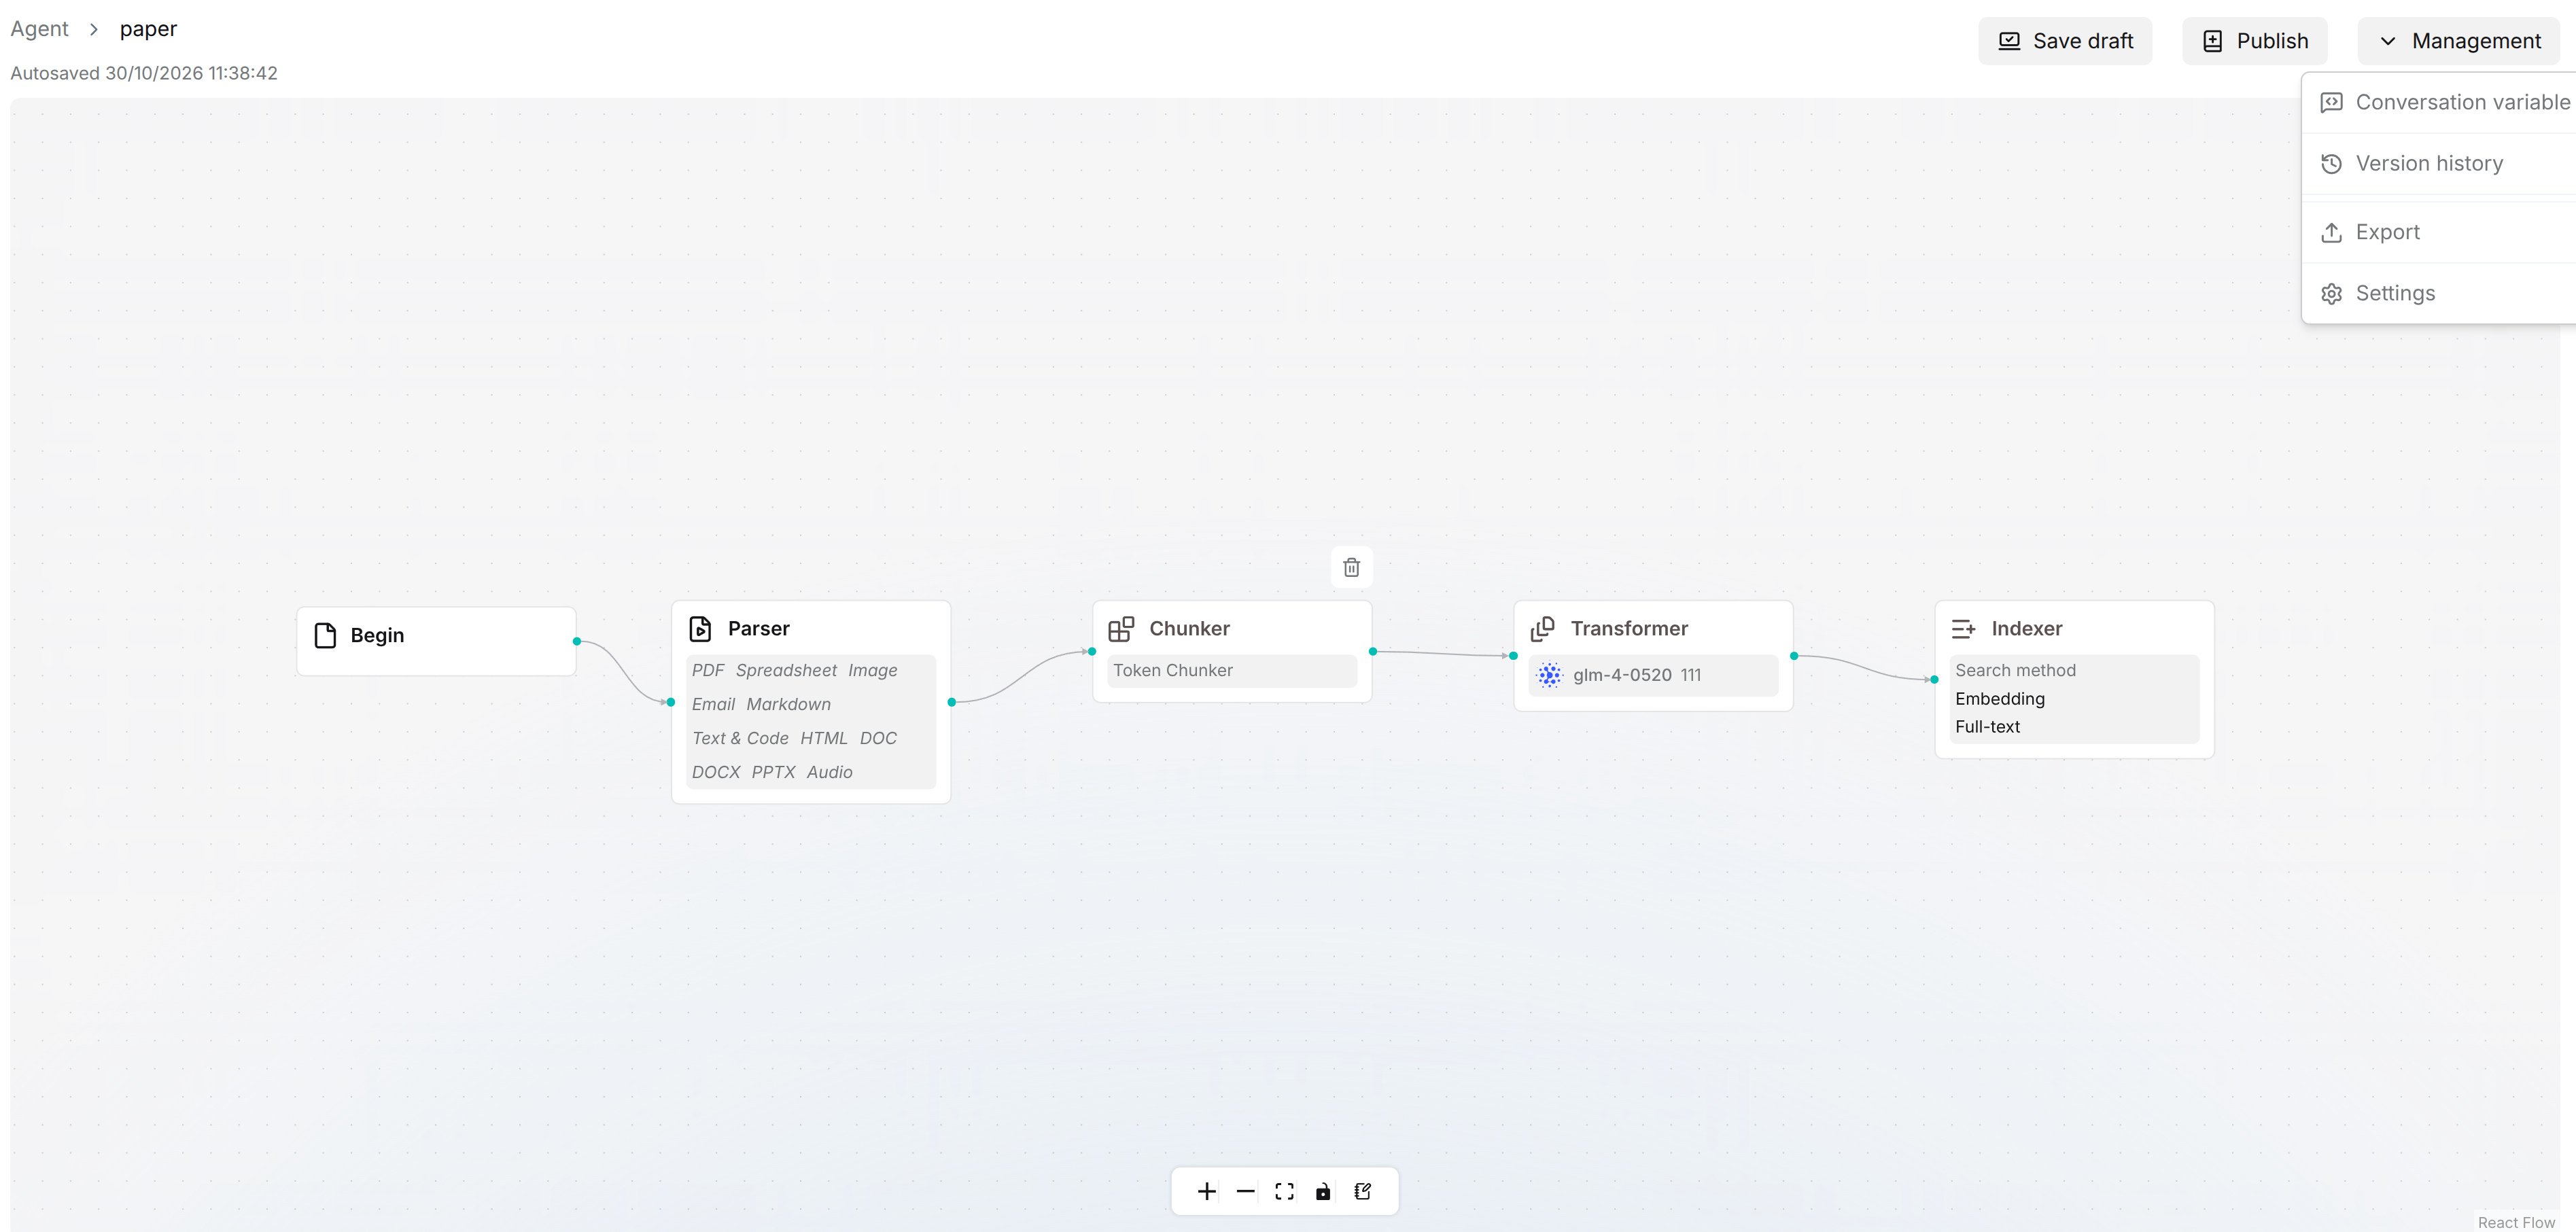
@@ -44,6 +44,8 @@ An editable pipeline has **Save draft**, **Publish**, and **Management** in the
|
||||
| Checklist | Appears when configuration issues are detected. Open it and click an issue to locate the affected component. Correct the configuration; the button disappears when no issues are detected. |
|
||||
| Management | Open the pipeline's variables, version history, JSON export, or settings. |
|
||||
|
||||
|
||||
|
||||
### Management Menu
|
||||
|
||||
| Entry | What you can do |
|
||||
|
||||
@@ -37,4 +37,6 @@ The connection menu depends on the selected node and the components already on t
|
||||
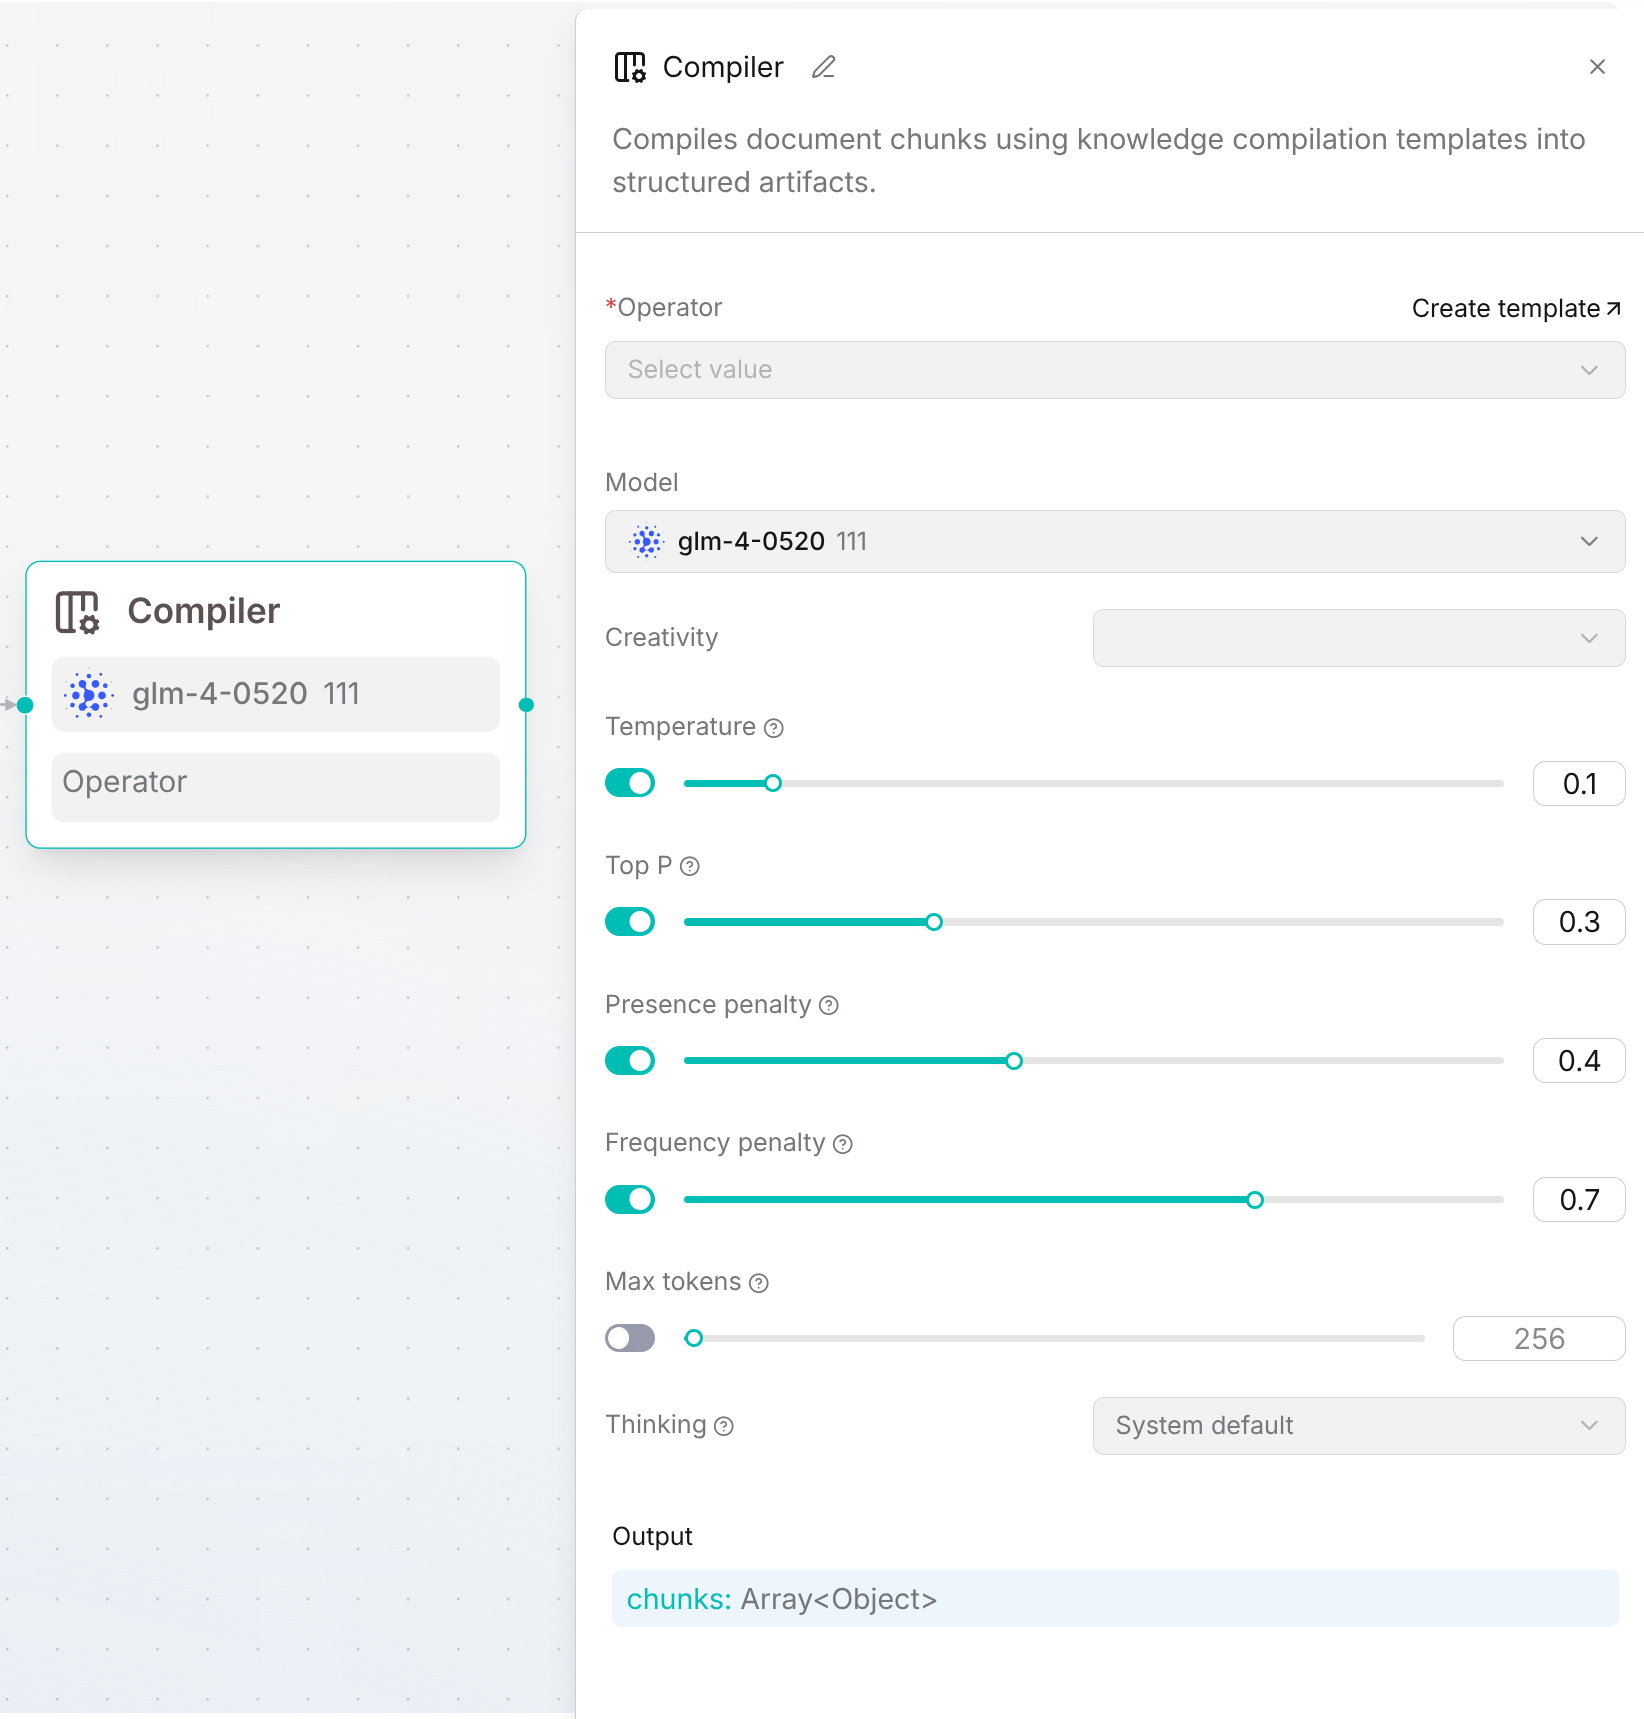
2. In the Compiler panel, select a template group under **Operator**. To create a group from this panel, click **Create template** beside the field and complete the dialog. You can also manage groups on the **Compilation operator** tab. Select the execution model under **Model** and review its model settings. The selected group determines the compilation tasks, such as a knowledge tree or wiki.
|
||||
3. Connect **Compiler → Indexer** to index the original and generated chunks. Click **Save draft**, publish a version, and [validate the pipeline](./test_run.md) with a sample document.
|
||||
|
||||
|
||||
|
||||
Example: **Begin → Parser → Token Chunker → Compiler → Indexer**. After parsing, check the generated content and retrieval results. If the template group or model is unavailable after import, select an accessible one.
|
||||
@@ -14,18 +14,20 @@ sidebar_custom_props:
|
||||
Multi-model comparison tests several models simultaneously with the same Chat configuration and the same question, then displays the answer generated by each model.
|
||||
|
||||
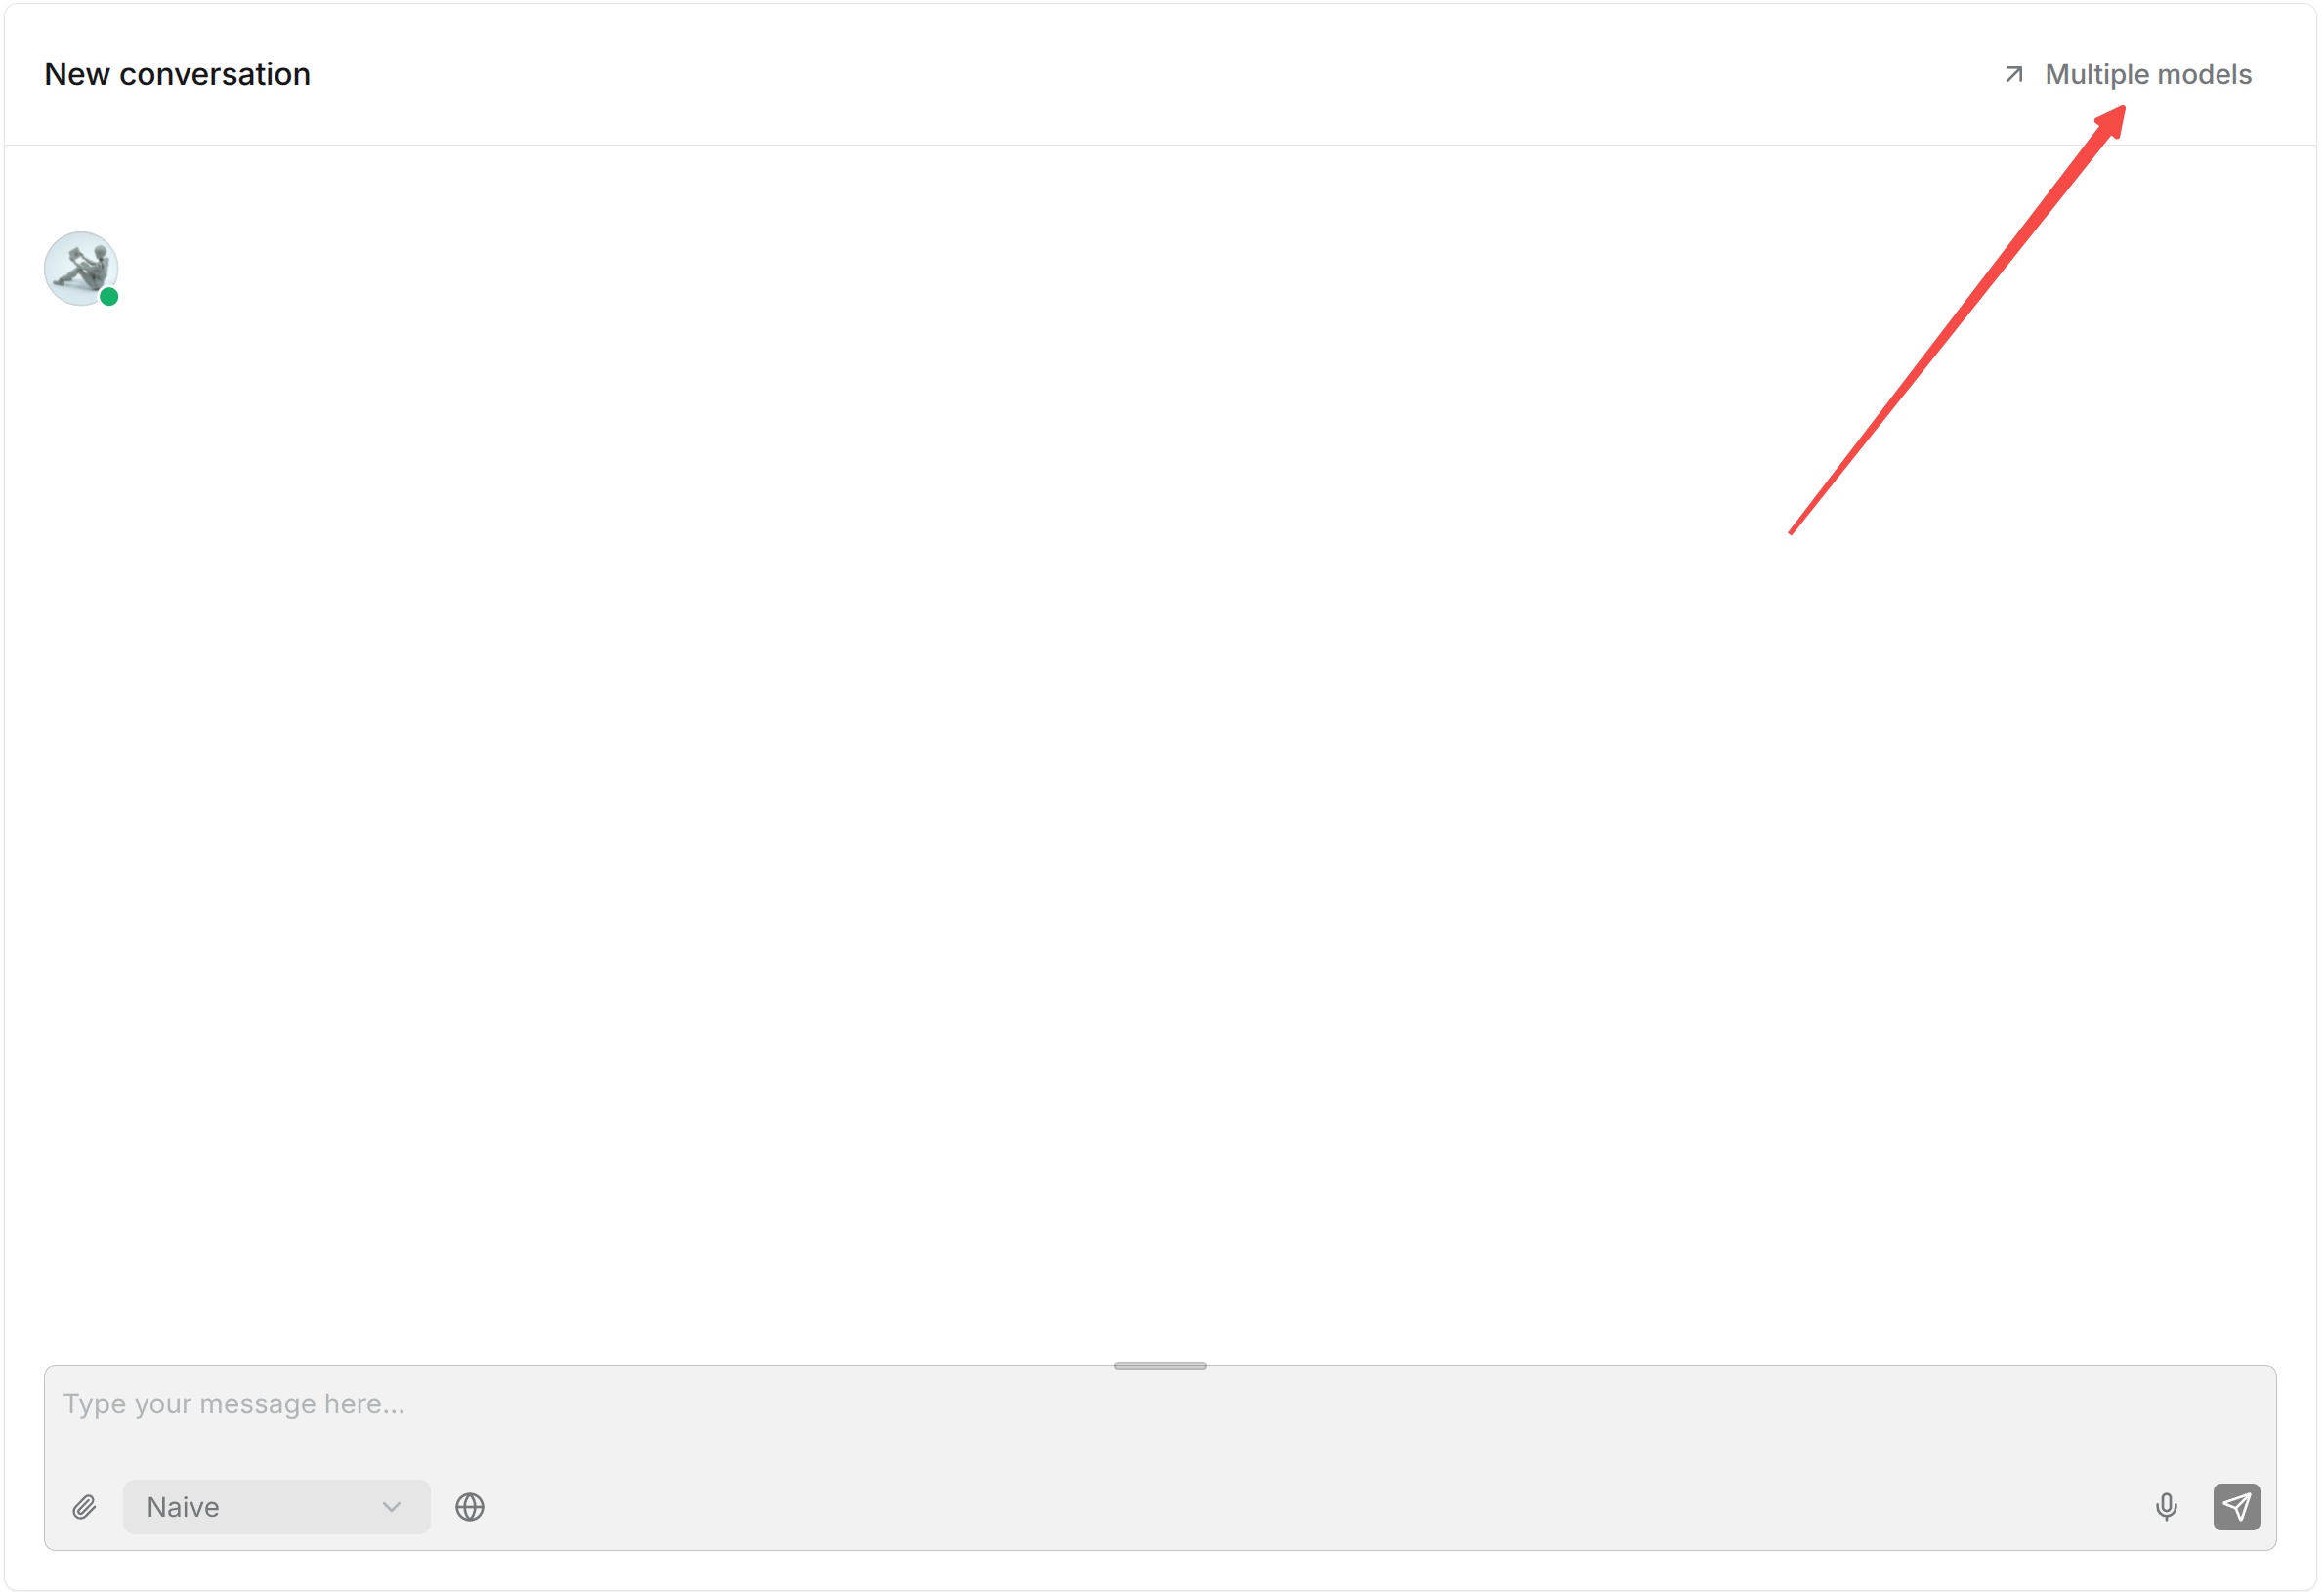
1. Open the Chat you want to test and click **Multiple models** above the conversation area.
|
||||
|
||||
|
||||
|
||||
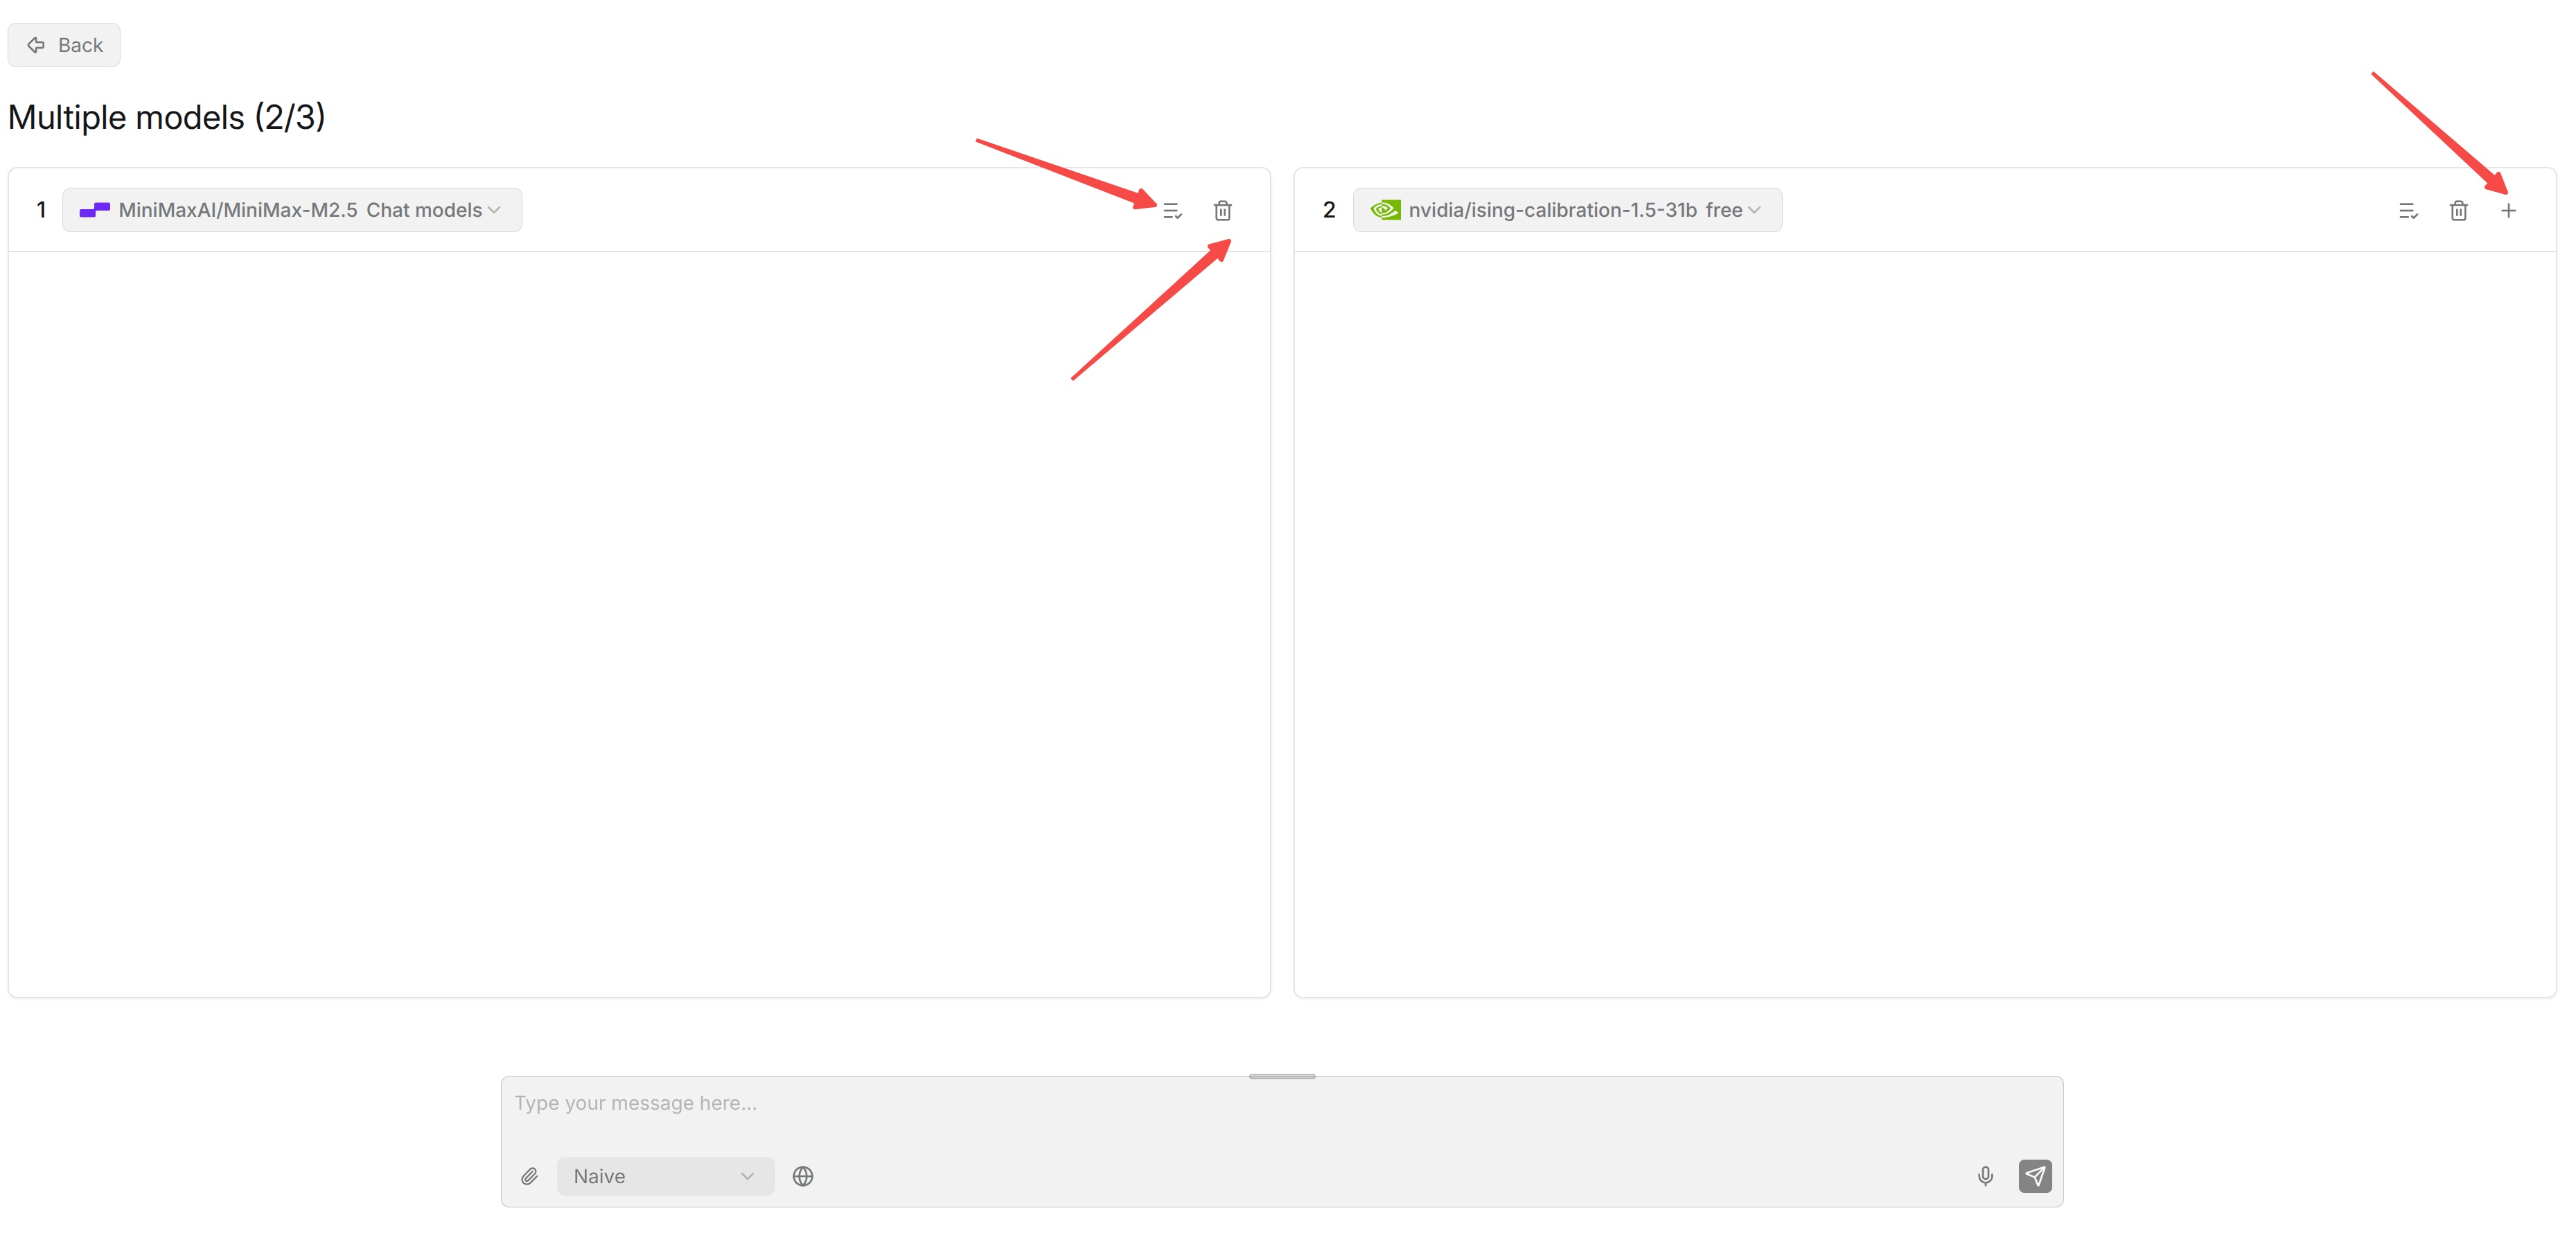
2. The comparison page initially displays one model panel. Click **+** in the last panel to add another. The counter beside **Multiple models** shows the number of panels; the current UI supports up to **3**.
|
||||
3. Use the model dropdown at the top of each panel to select the model for that panel. Configure the required model providers first if a model is not available.
|
||||
|
||||
|
||||
|
||||
4. Enter one test question in the shared message box at the bottom, select **Naive** or **Agentic** as needed, and click **Send message**. The selected models receive the same question for comparison.
|
||||
5. Compare the answers side by side. Check accuracy, use of dataset evidence, completeness, and differences in the responses.
|
||||
6. To remove a panel, click its trash icon. This action is available when more than one panel is present. Click **Back** to return to the normal Chat view.
|
||||
|
||||
To use a panel's model configuration for the Chat, click its **Apply model configs** icon. This updates the Chat's saved model configuration; simply selecting a model for comparison does not apply it to the Chat.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
Use representative questions from actual business scenarios instead of selecting a model based on a single question. Multi-model comparison is primarily intended for model selection and debugging. For example, after changing a model provider or model version, use the same questions to quickly compare the practical performance of the old and new models.
|
||||
|
||||
# FAQ
|
||||
|
||||
@@ -33,6 +33,8 @@ Expand **Advanced settings** below **Datasets**. It contains shared options foll
|
||||
|
||||
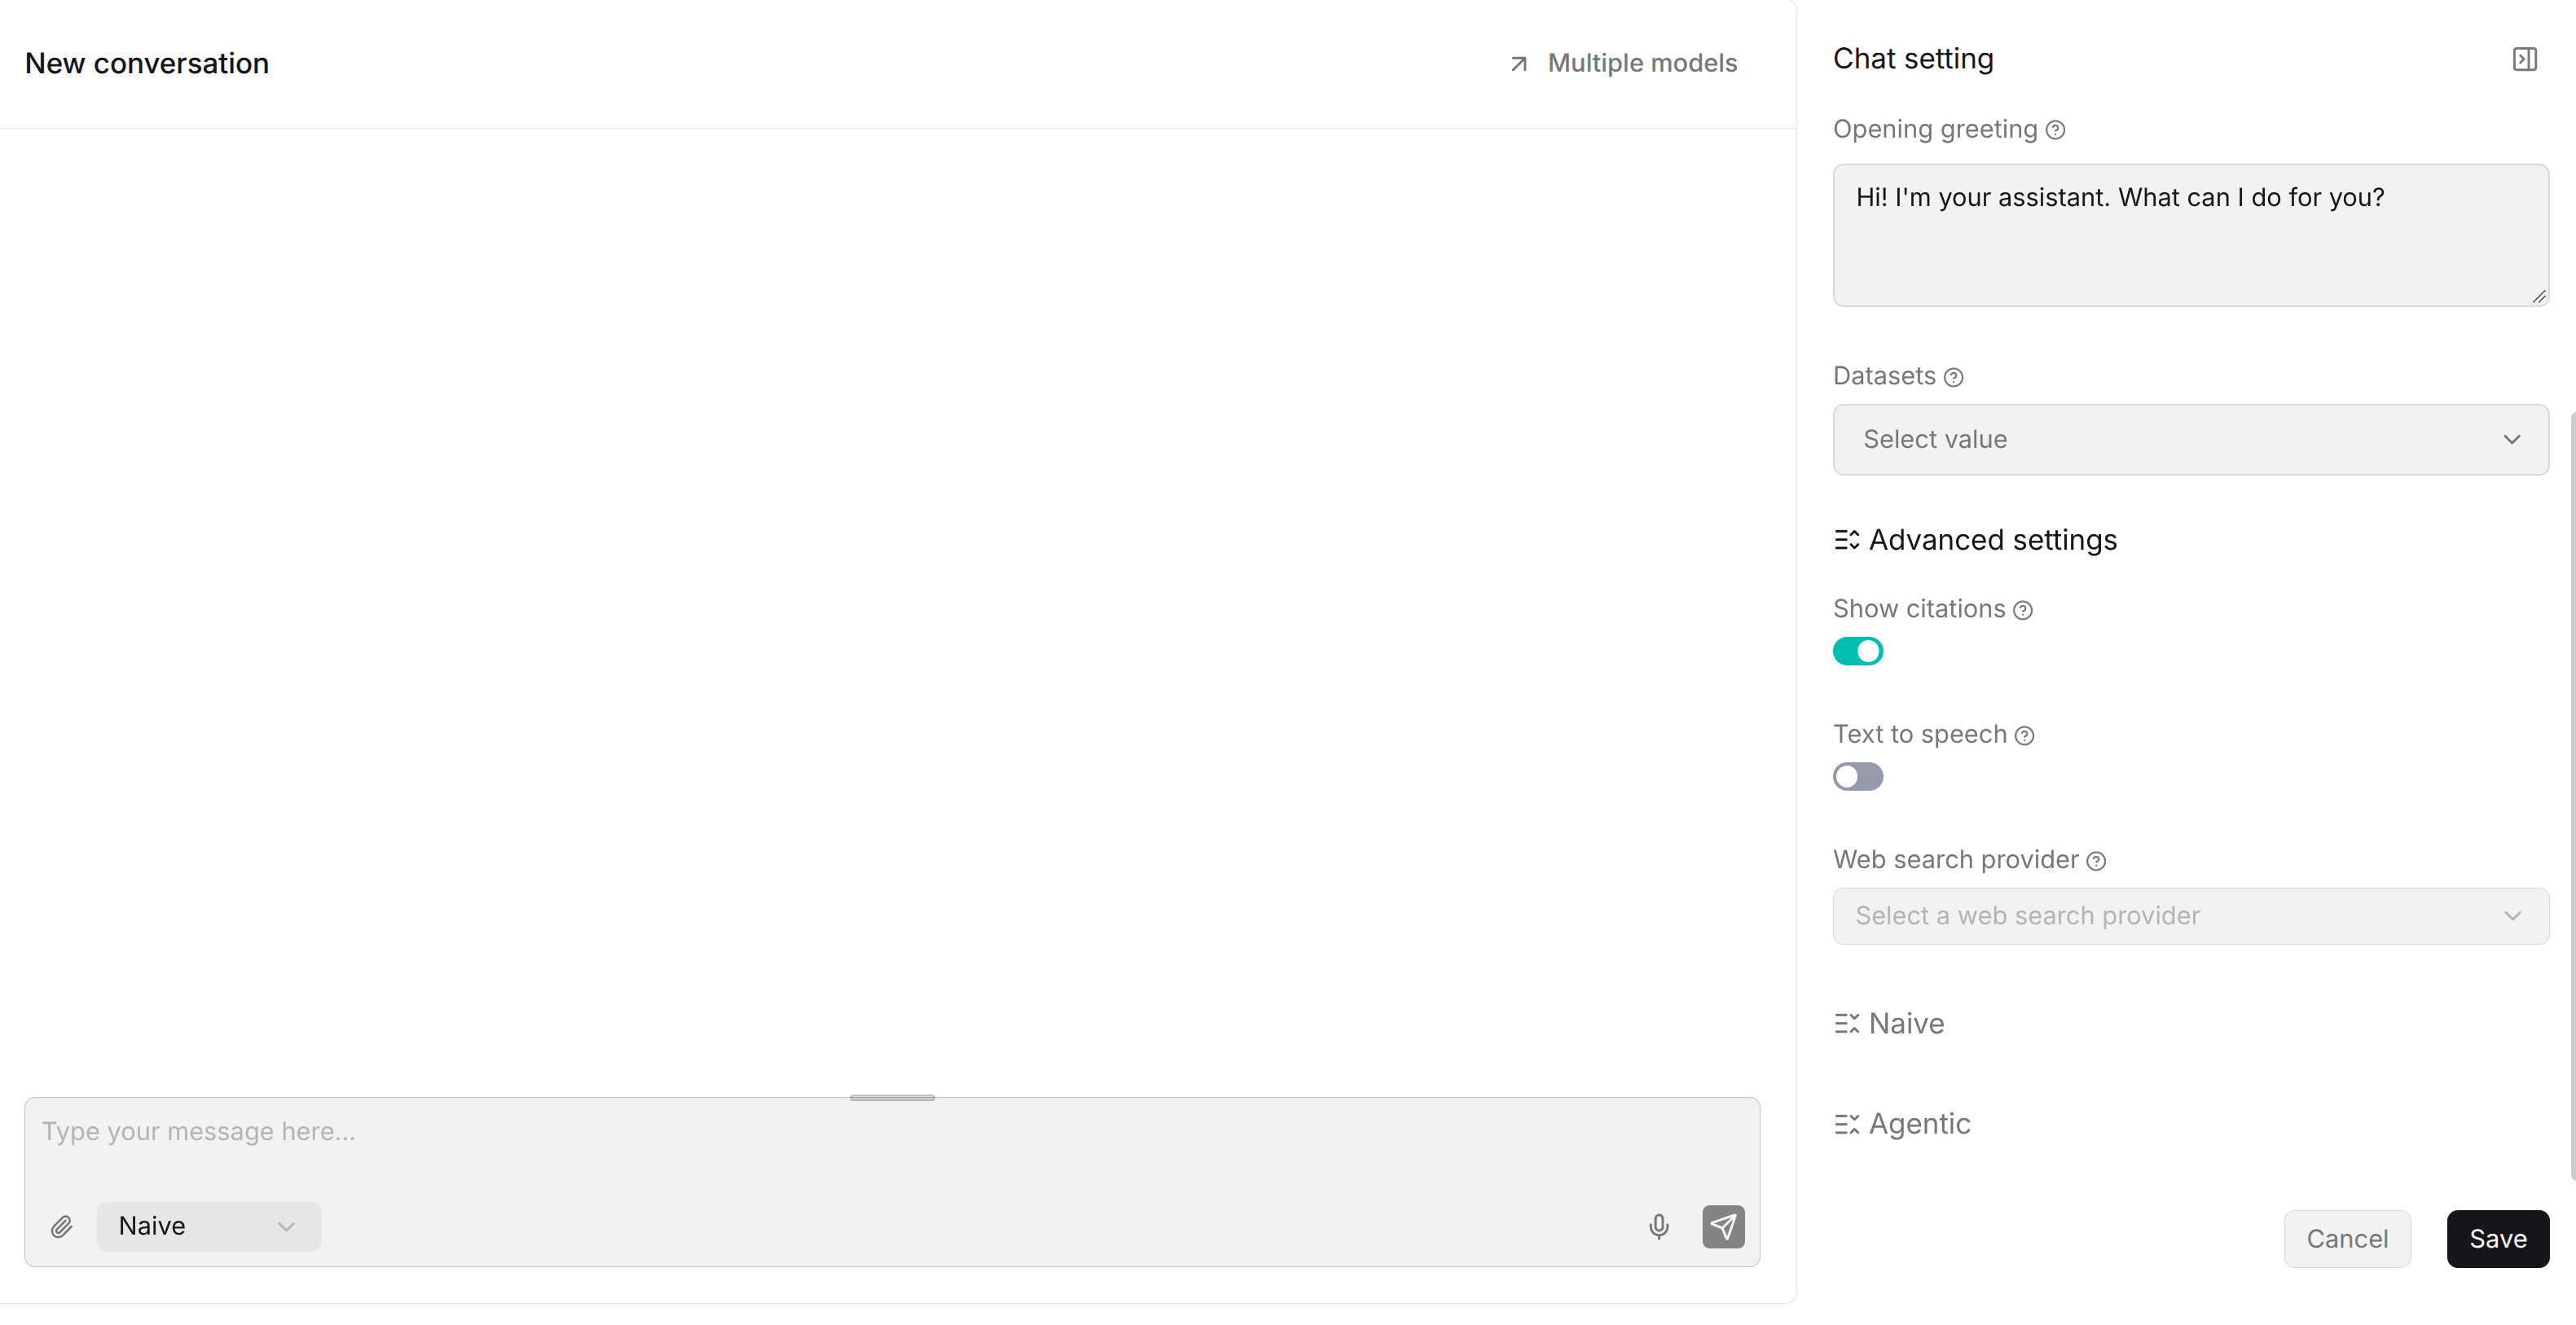
The groups configure how each mode works. To choose the mode for a question, use the selector beside the message box; expanding a group in the settings panel does not switch the conversation's mode.
|
||||
|
||||
|
||||
|
||||
### Shared Options
|
||||
|
||||
| Setting | Purpose and operation |
|
||||
|
||||
@@ -47,7 +47,11 @@ Area description: the connected data source area is used to manage the connectio
|
||||
|
||||
### Set a Connected Data Source
|
||||
|
||||
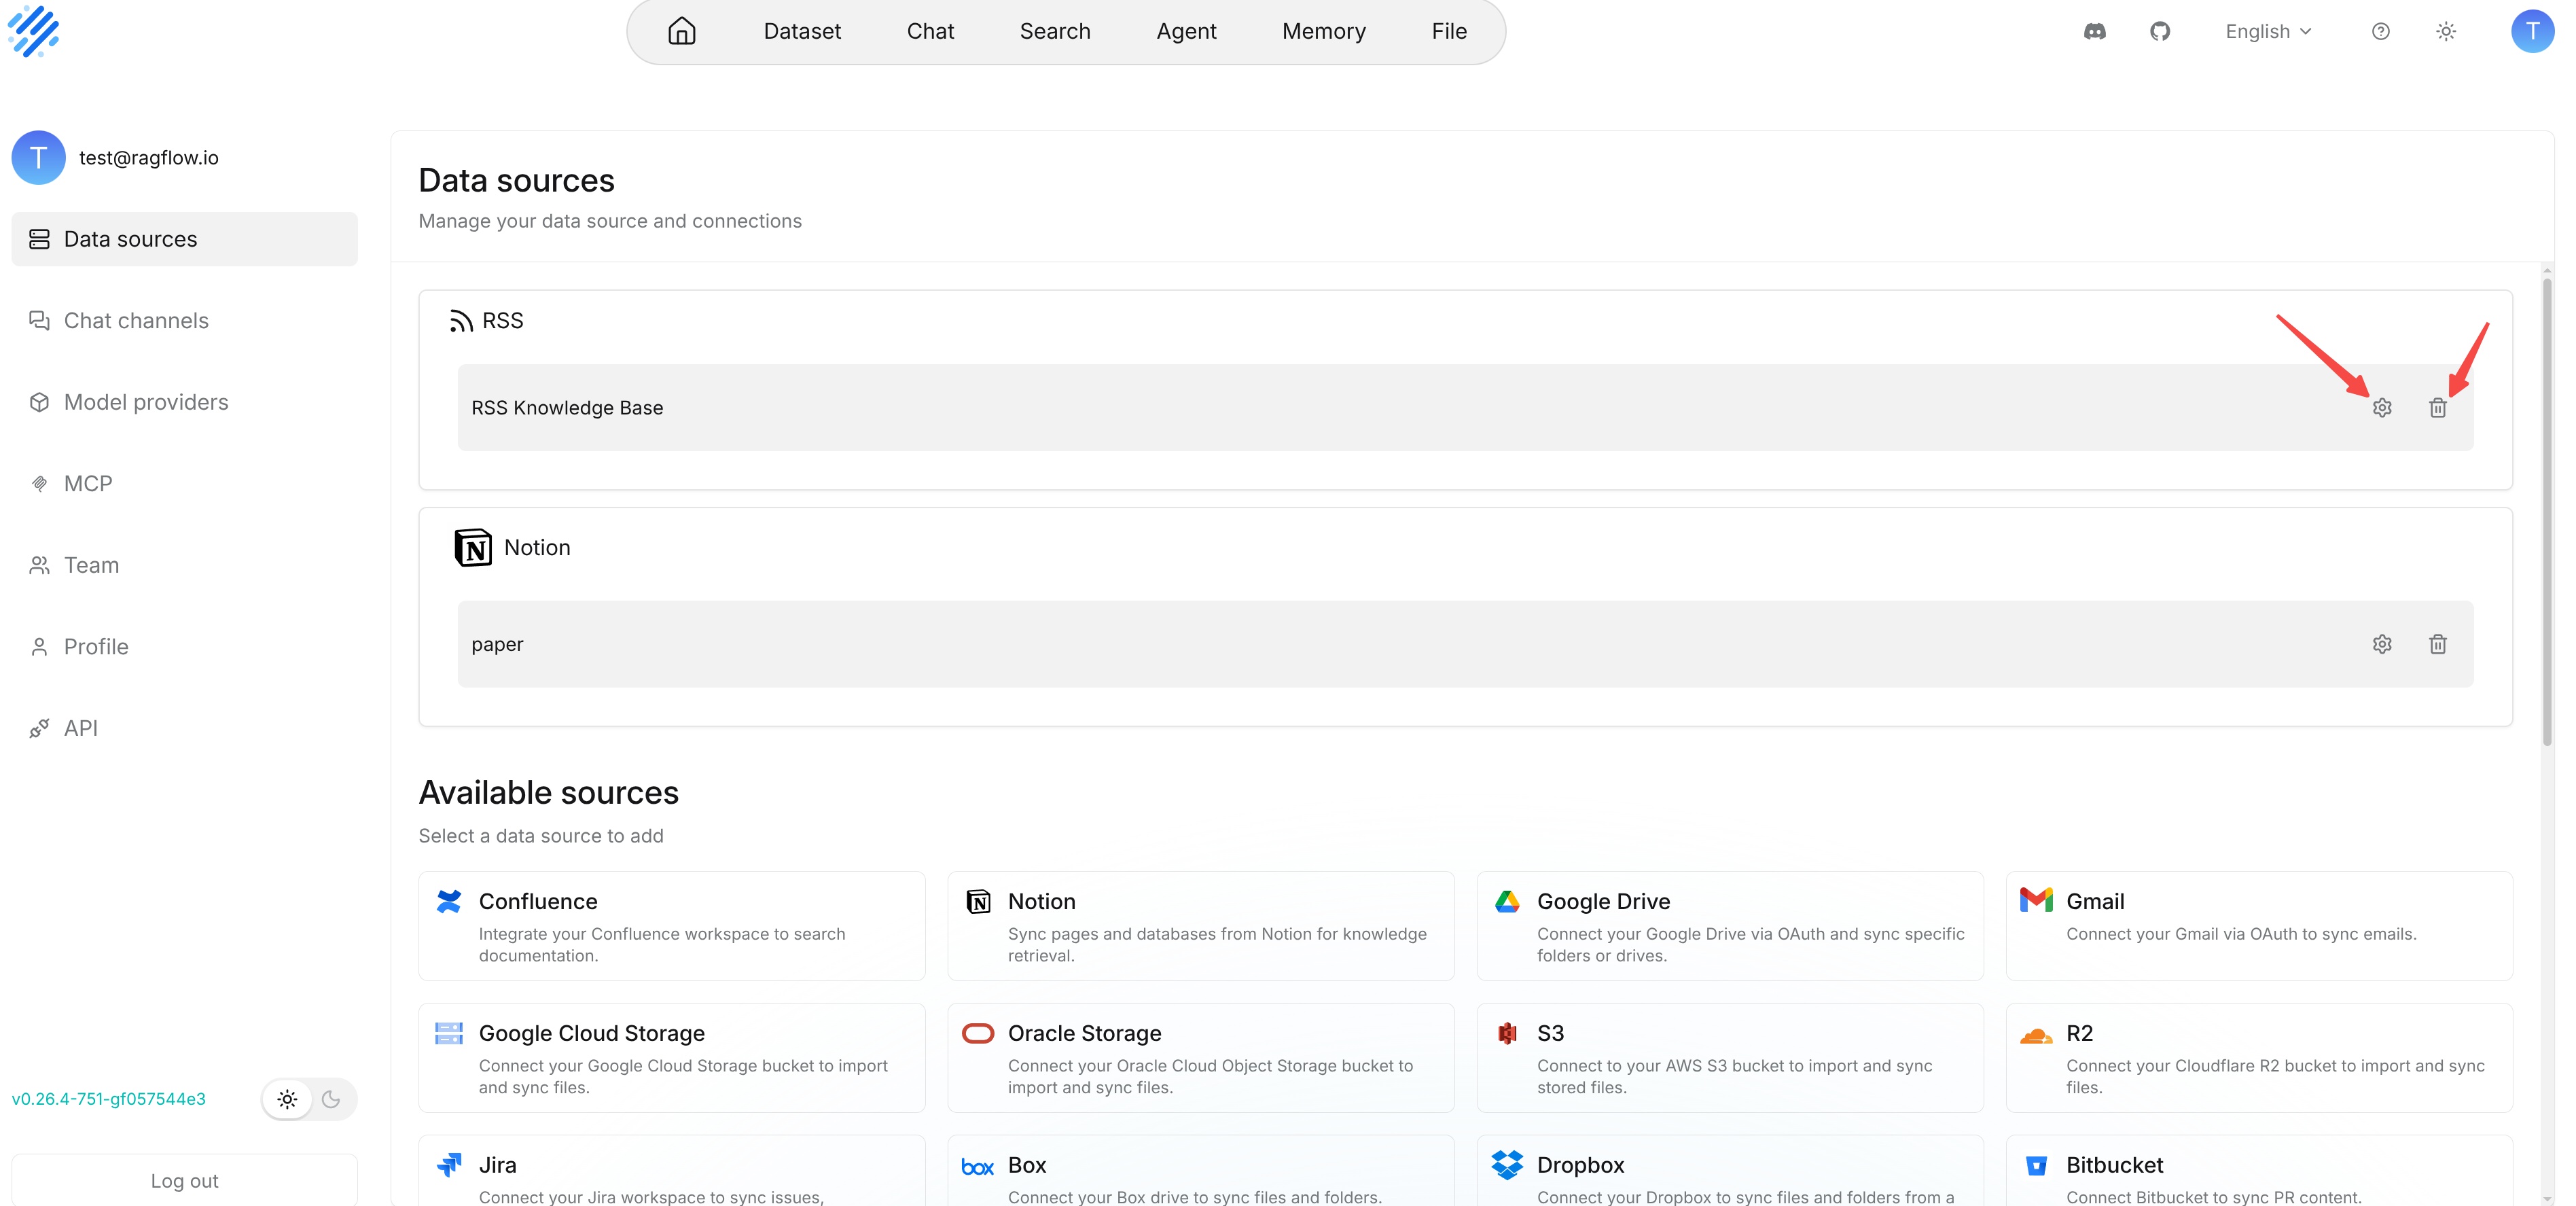
Click the settings button on the right side of a connected data source to enter the settings page of that connection. The settings page is used to view and maintain the configuration of the current connection. It is suitable for use when a token expires, the synchronization scope changes, the refresh frequency needs to be adjusted, or the synchronization result is abnormal.
|
||||
Click the settings button on the right side of a connected data source to enter the settings page of that connection.
|
||||
|
||||
|
||||
|
||||
The settings page is used to view and maintain the configuration of the current connection. It is suitable for use when a token expires, the synchronization scope changes, the refresh frequency needs to be adjusted, or the synchronization result is abnormal.
|
||||
|
||||
Common fields on the settings page include:
|
||||
|
||||
@@ -62,8 +66,6 @@ Common fields on the settings page include:
|
||||
|
||||
After changing settings, click **Test connection**, then **Save**. With no unsaved changes, the primary button may show **Stop** or **Resume**, depending on the connection status. Updated settings apply to subsequent synchronization tasks.
|
||||
|
||||

|
||||
|
||||
### View Connected Data Source Logs
|
||||
|
||||
A log area is provided at the bottom of the data source settings page to view synchronization task records related to the connection. Logs can help determine whether synchronization has been executed, whether it failed, and the reason for failure.
|
||||
|
||||
@@ -31,7 +31,7 @@ RAGFlow file management lets you build your own file system through nested folde
|
||||
|
||||
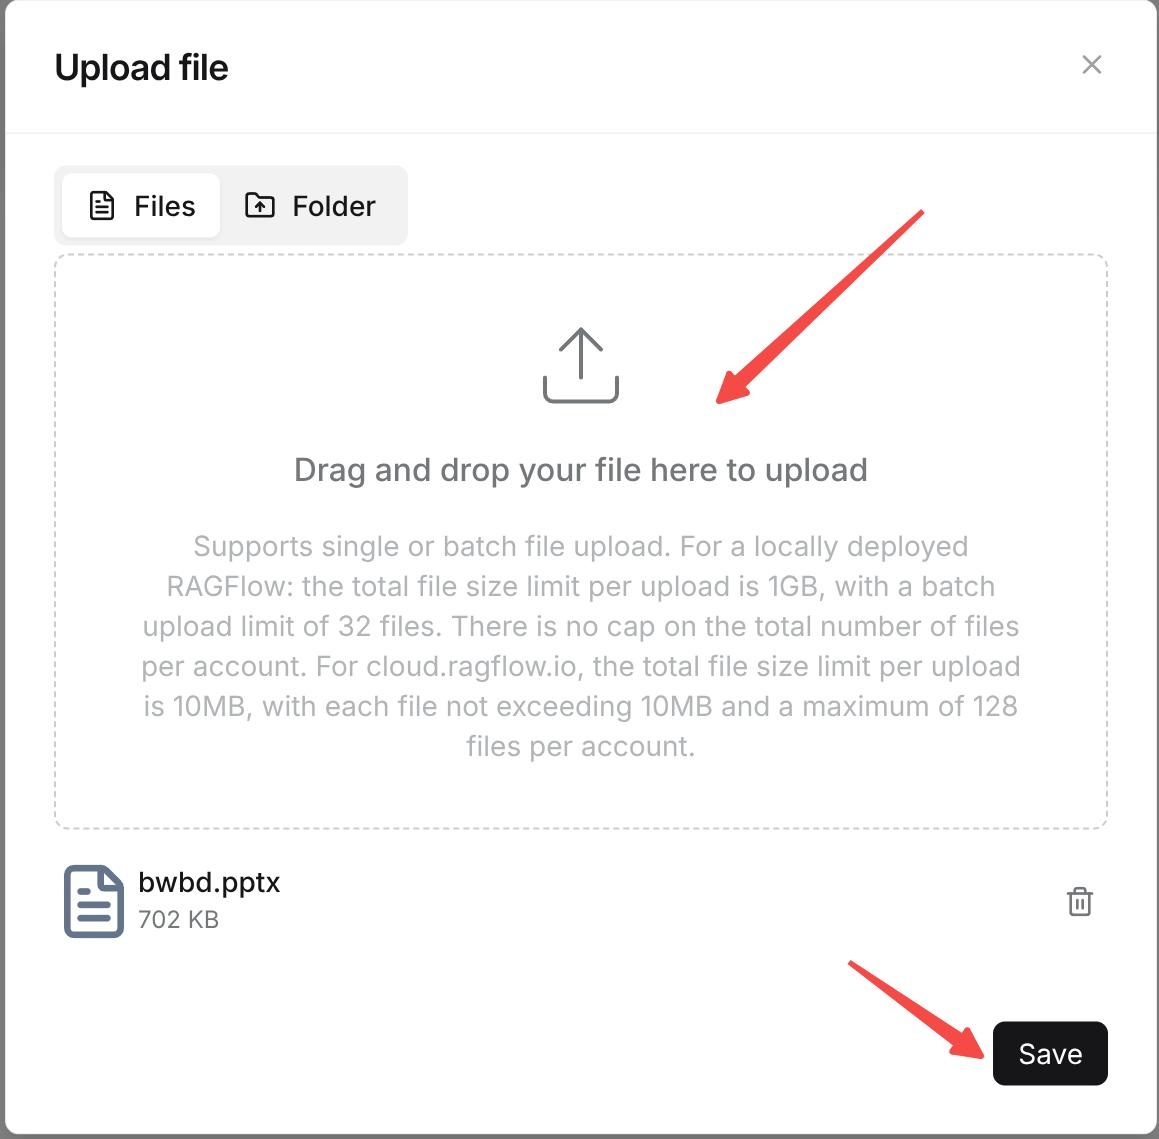
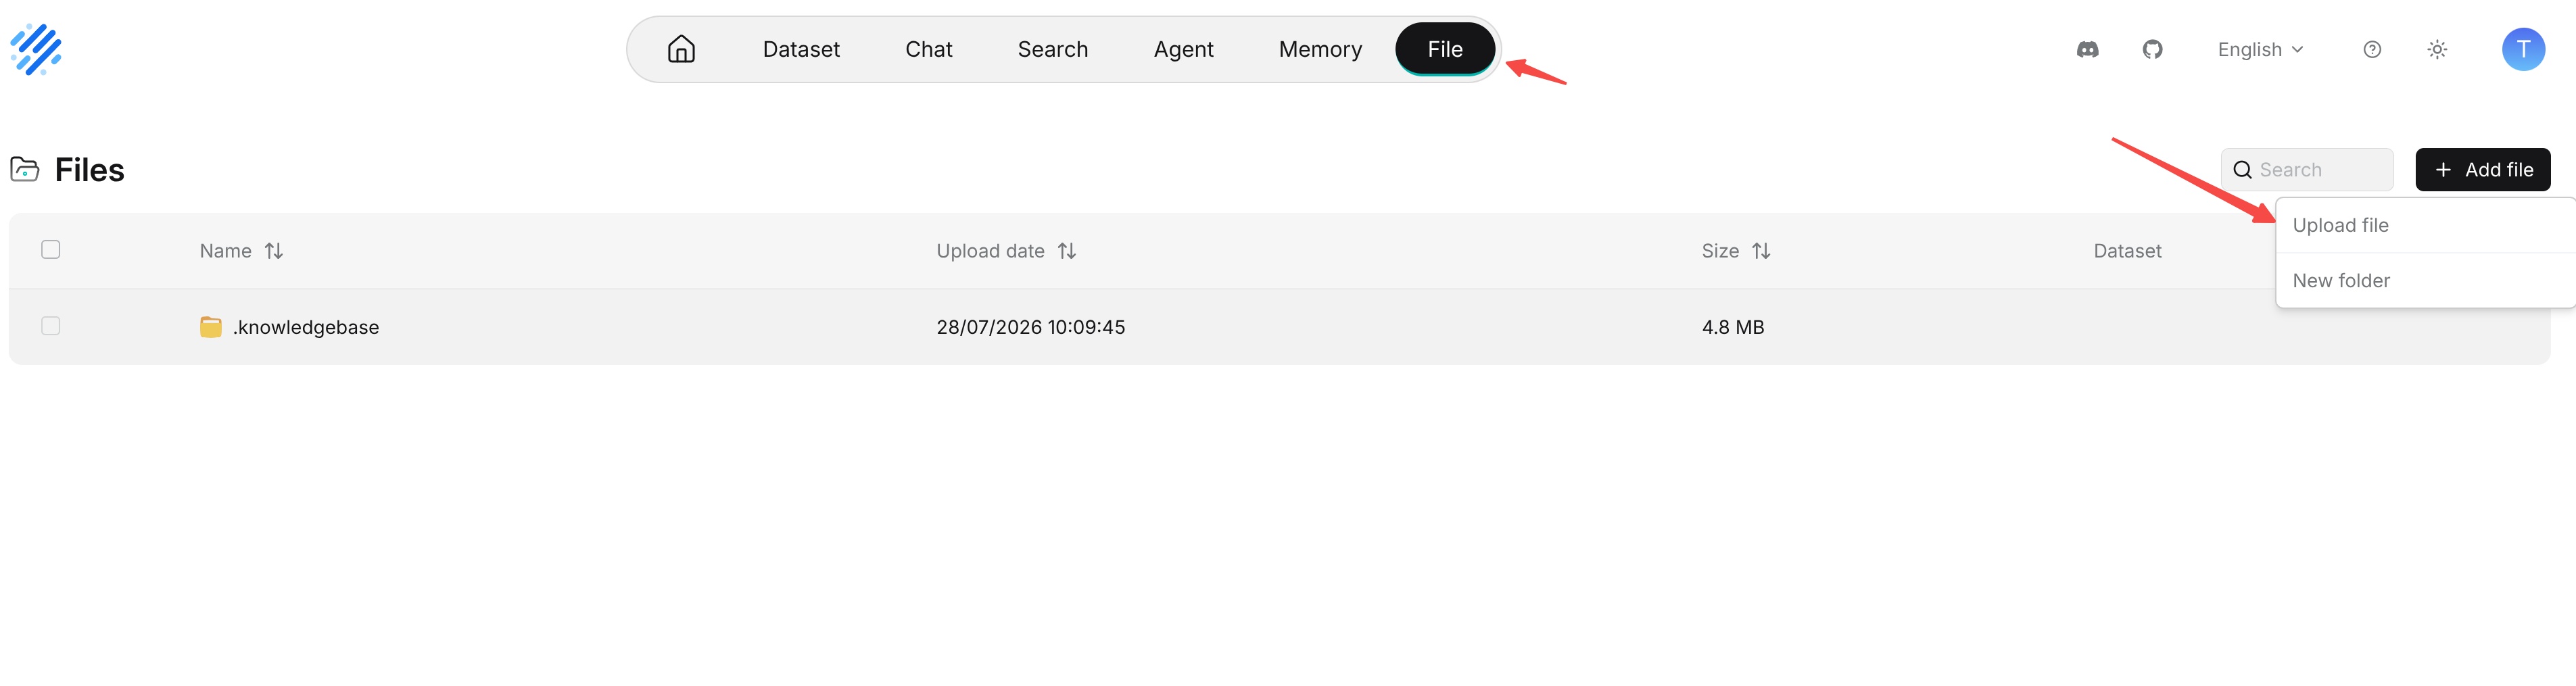
After clicking **Add File** in the upper-right corner of the page, select **Upload File** to open the upload window. The upload control contains two tabs: **File** and **Folder**. You can select one or more files, or upload an entire folder.
|
||||
|
||||
|
||||
|
||||
|
||||
### Upload File
|
||||
|
||||
@@ -41,7 +41,7 @@ After clicking **Add File** in the upper-right corner of the page, select **Uplo
|
||||
4. Confirm the list of files to be uploaded. If you selected a file by mistake, click the delete button on the right side of the file row to remove it.
|
||||
5. Click **Confirm** or **Save**, then wait for the upload progress to complete.
|
||||
|
||||

|
||||

|
||||
|
||||
### Upload Folder
|
||||
|
||||
|
||||
@@ -21,7 +21,7 @@ Configuration steps:
|
||||
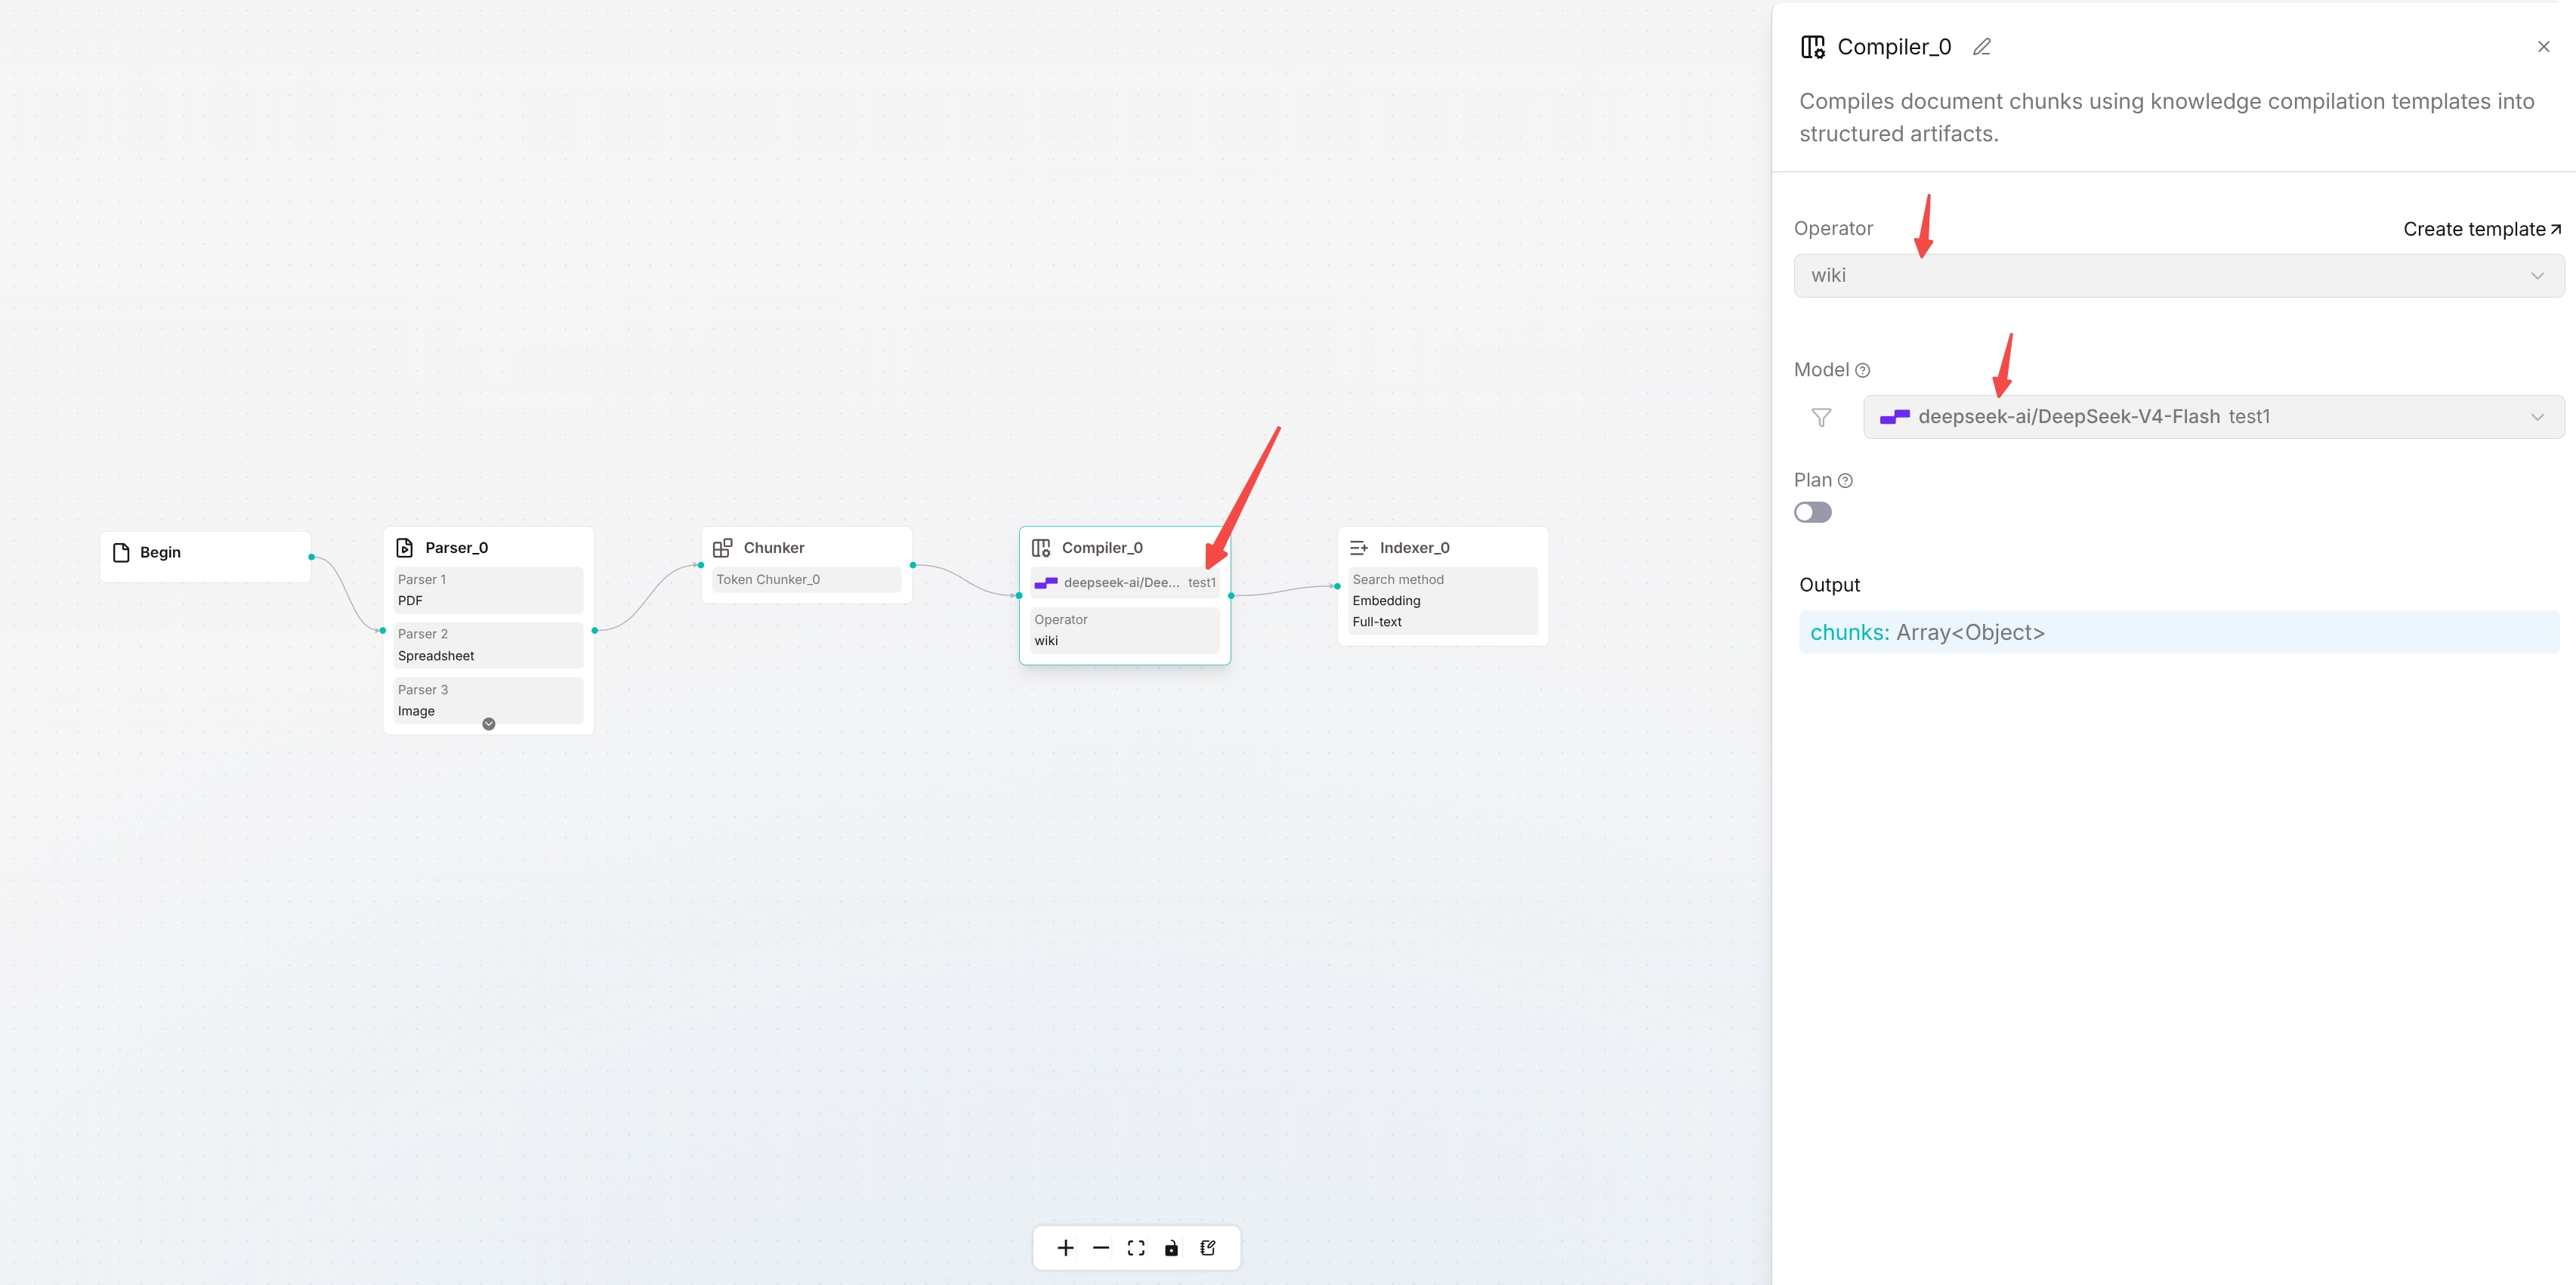
3. Open **Compiler**, select the target template group under **Operator**, and choose an available compilation model.
|
||||
4. Check node connections and required parameters, click **Save draft**, then **Publish** and confirm to create a pipeline version.
|
||||
|
||||
|
||||

|
||||
|
||||
Note: CompilationTemplate only defines "how to compile". A KnowledgeArtifact is generated only after the template is referenced in CompilerOperator and the document actually executes this Pipeline.
|
||||
|
||||
@@ -33,7 +33,7 @@ Note: CompilationTemplate only defines "how to compile". A KnowledgeArtifact is
|
||||
4. Open **Parsing mode**, expand the ingestion pipeline that contains **Compiler**, select its published version within that dropdown, and click **Save**. If it shows **No published versions**, publish the pipeline first.
|
||||
5. Start parsing and check in the task logs whether Parser, Chunker, Compiler, and Indexer complete in sequence.
|
||||
|
||||

|
||||

|
||||
|
||||
If CompilationTemplate is modified, completed documents are not automatically recompiled. You need to reparse or rerun the Pipeline according to the operations currently provided by the product before the new configuration can be applied.
|
||||
|
||||
|
||||
@@ -33,4 +33,4 @@ A memory must be connected to an Agent before historical messages can be written
|
||||
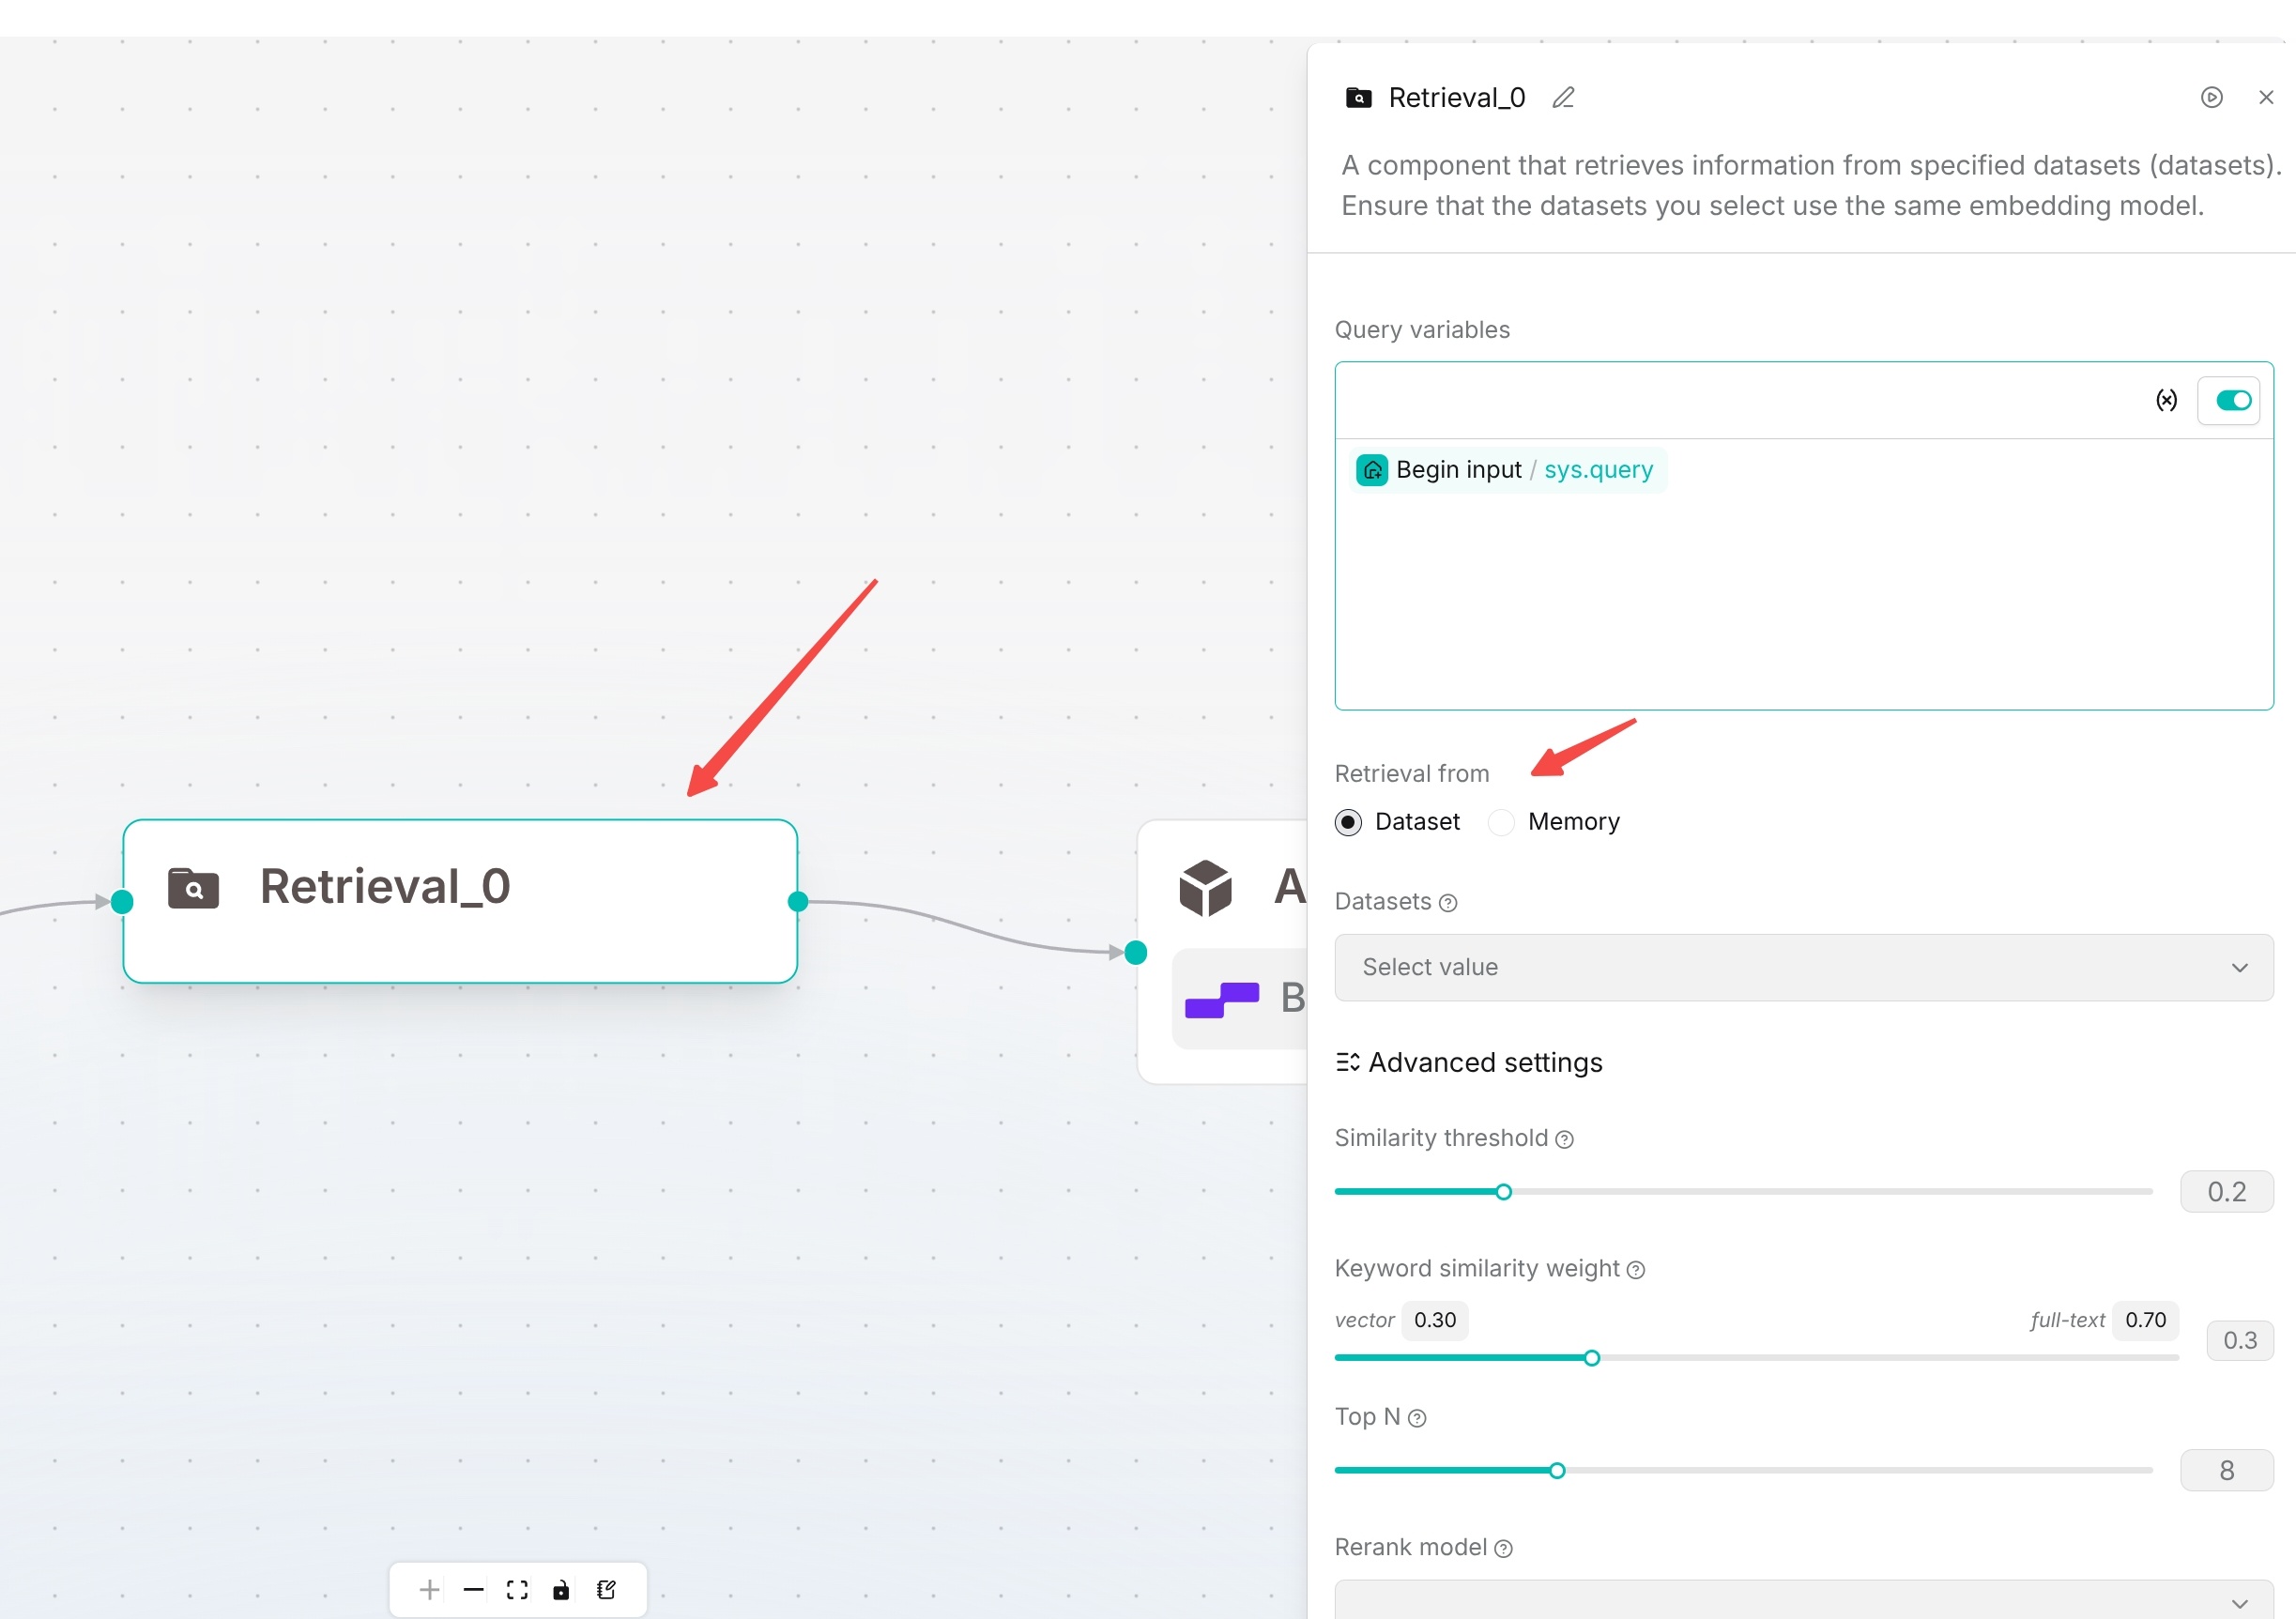
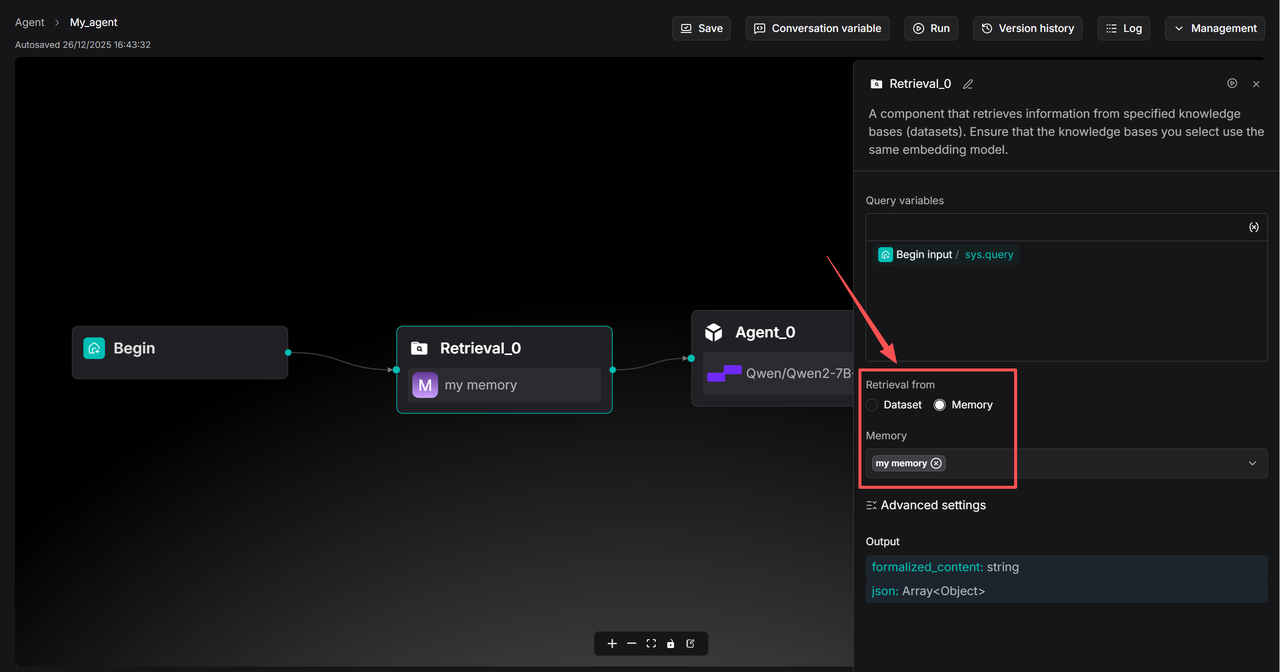
6. Save and run a test, and check whether the answer correctly references historical memories.
|
||||
|
||||
|
||||
|
||||
|
||||
@@ -44,7 +44,7 @@ To configure a model provider:
|
||||
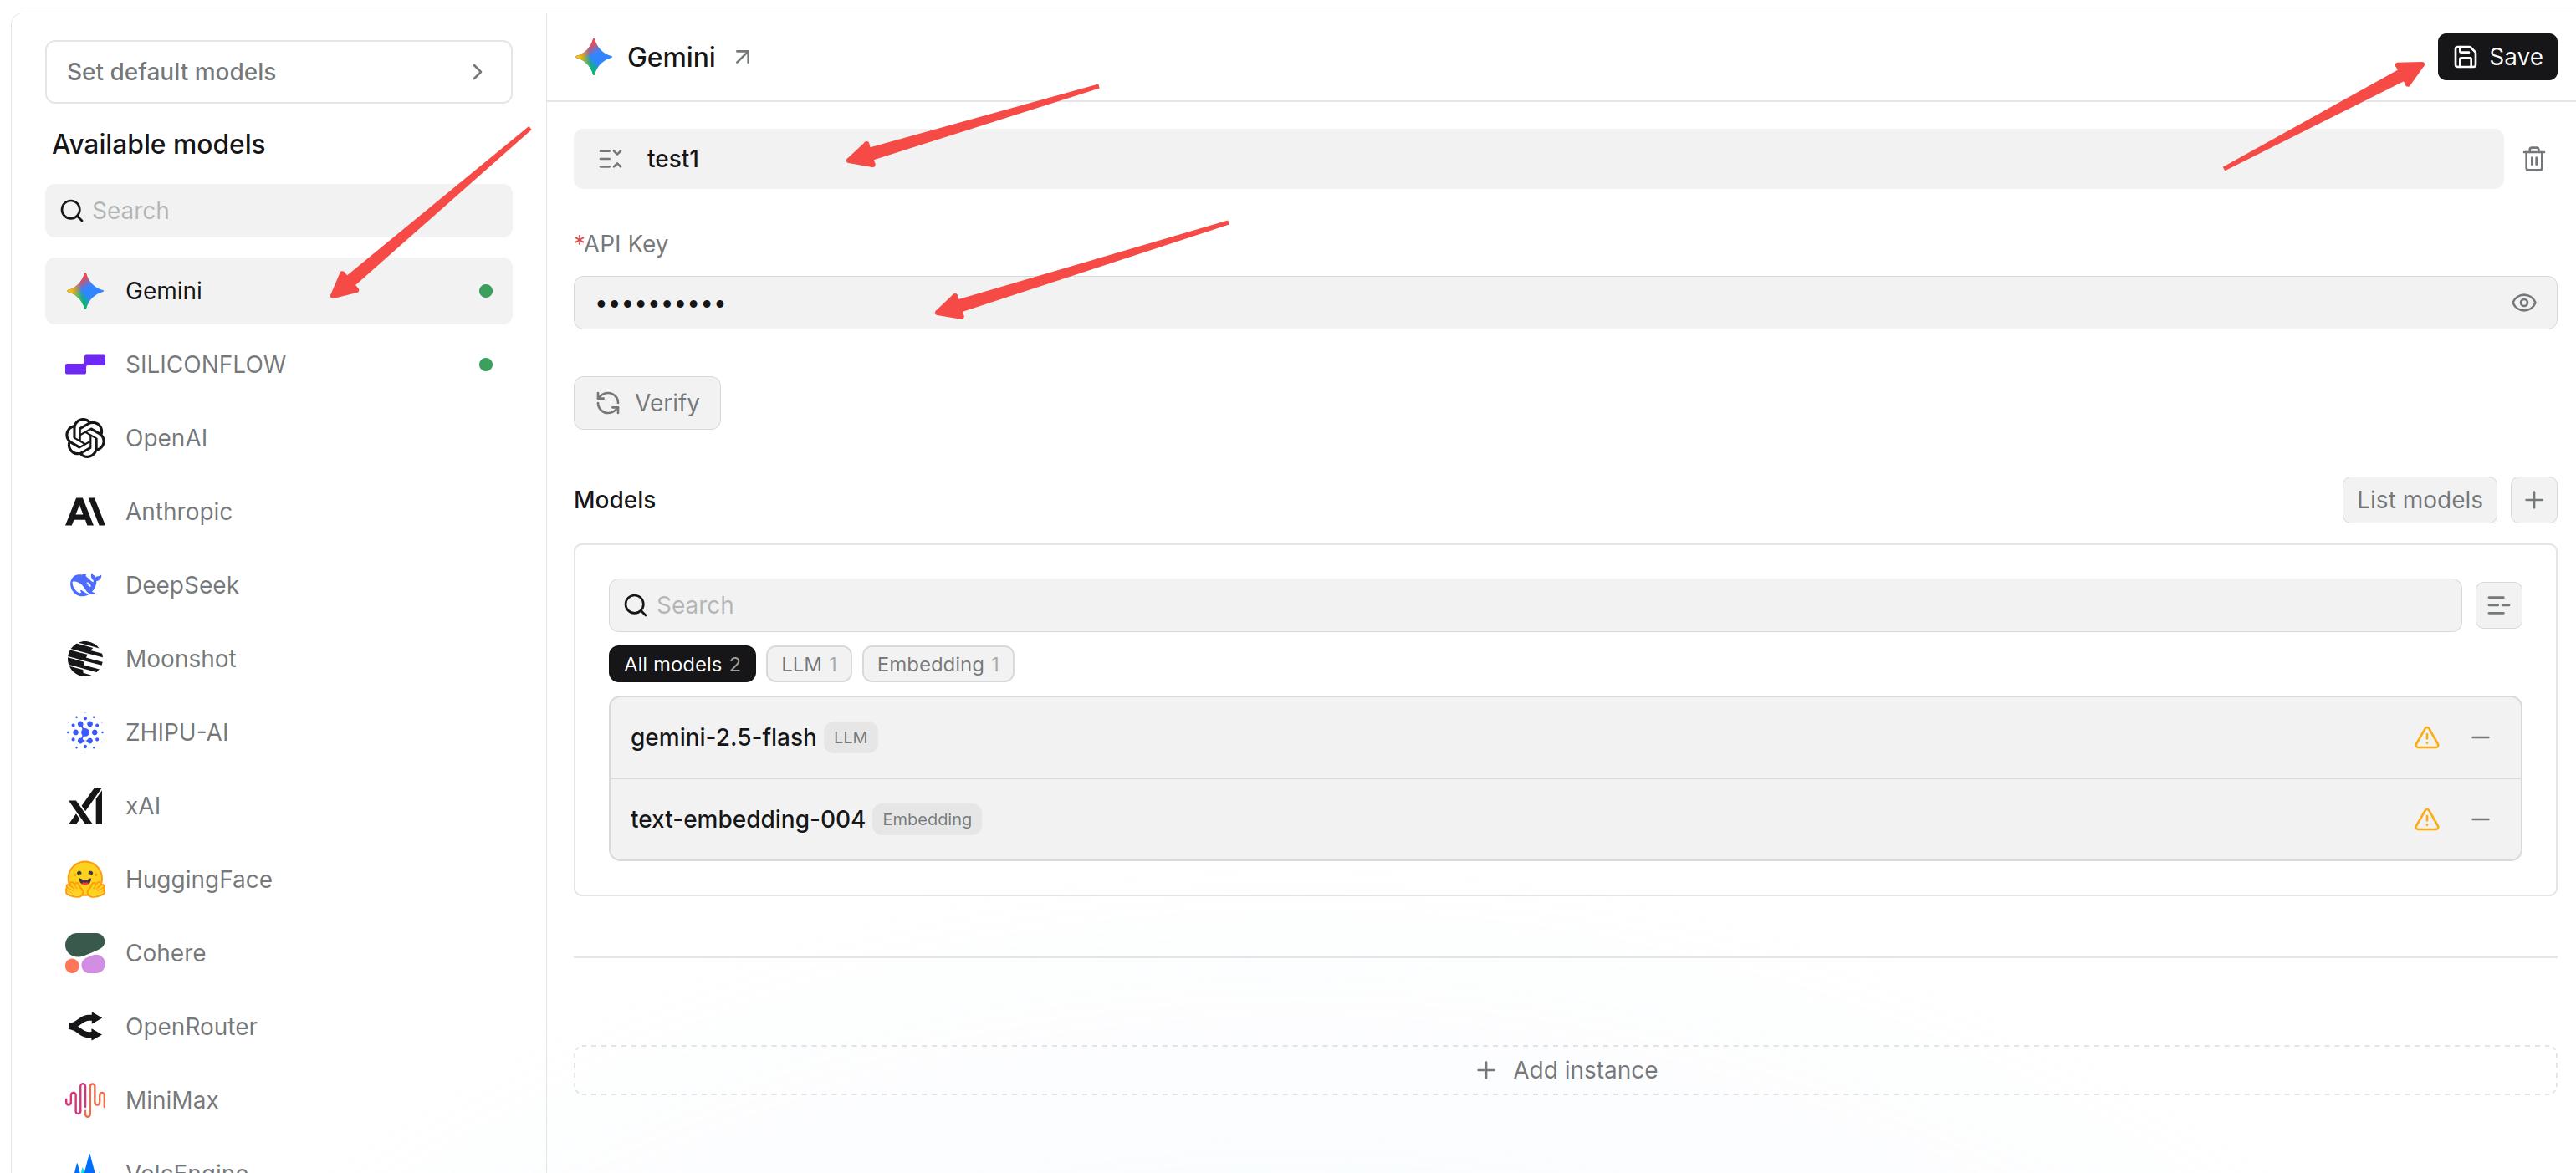
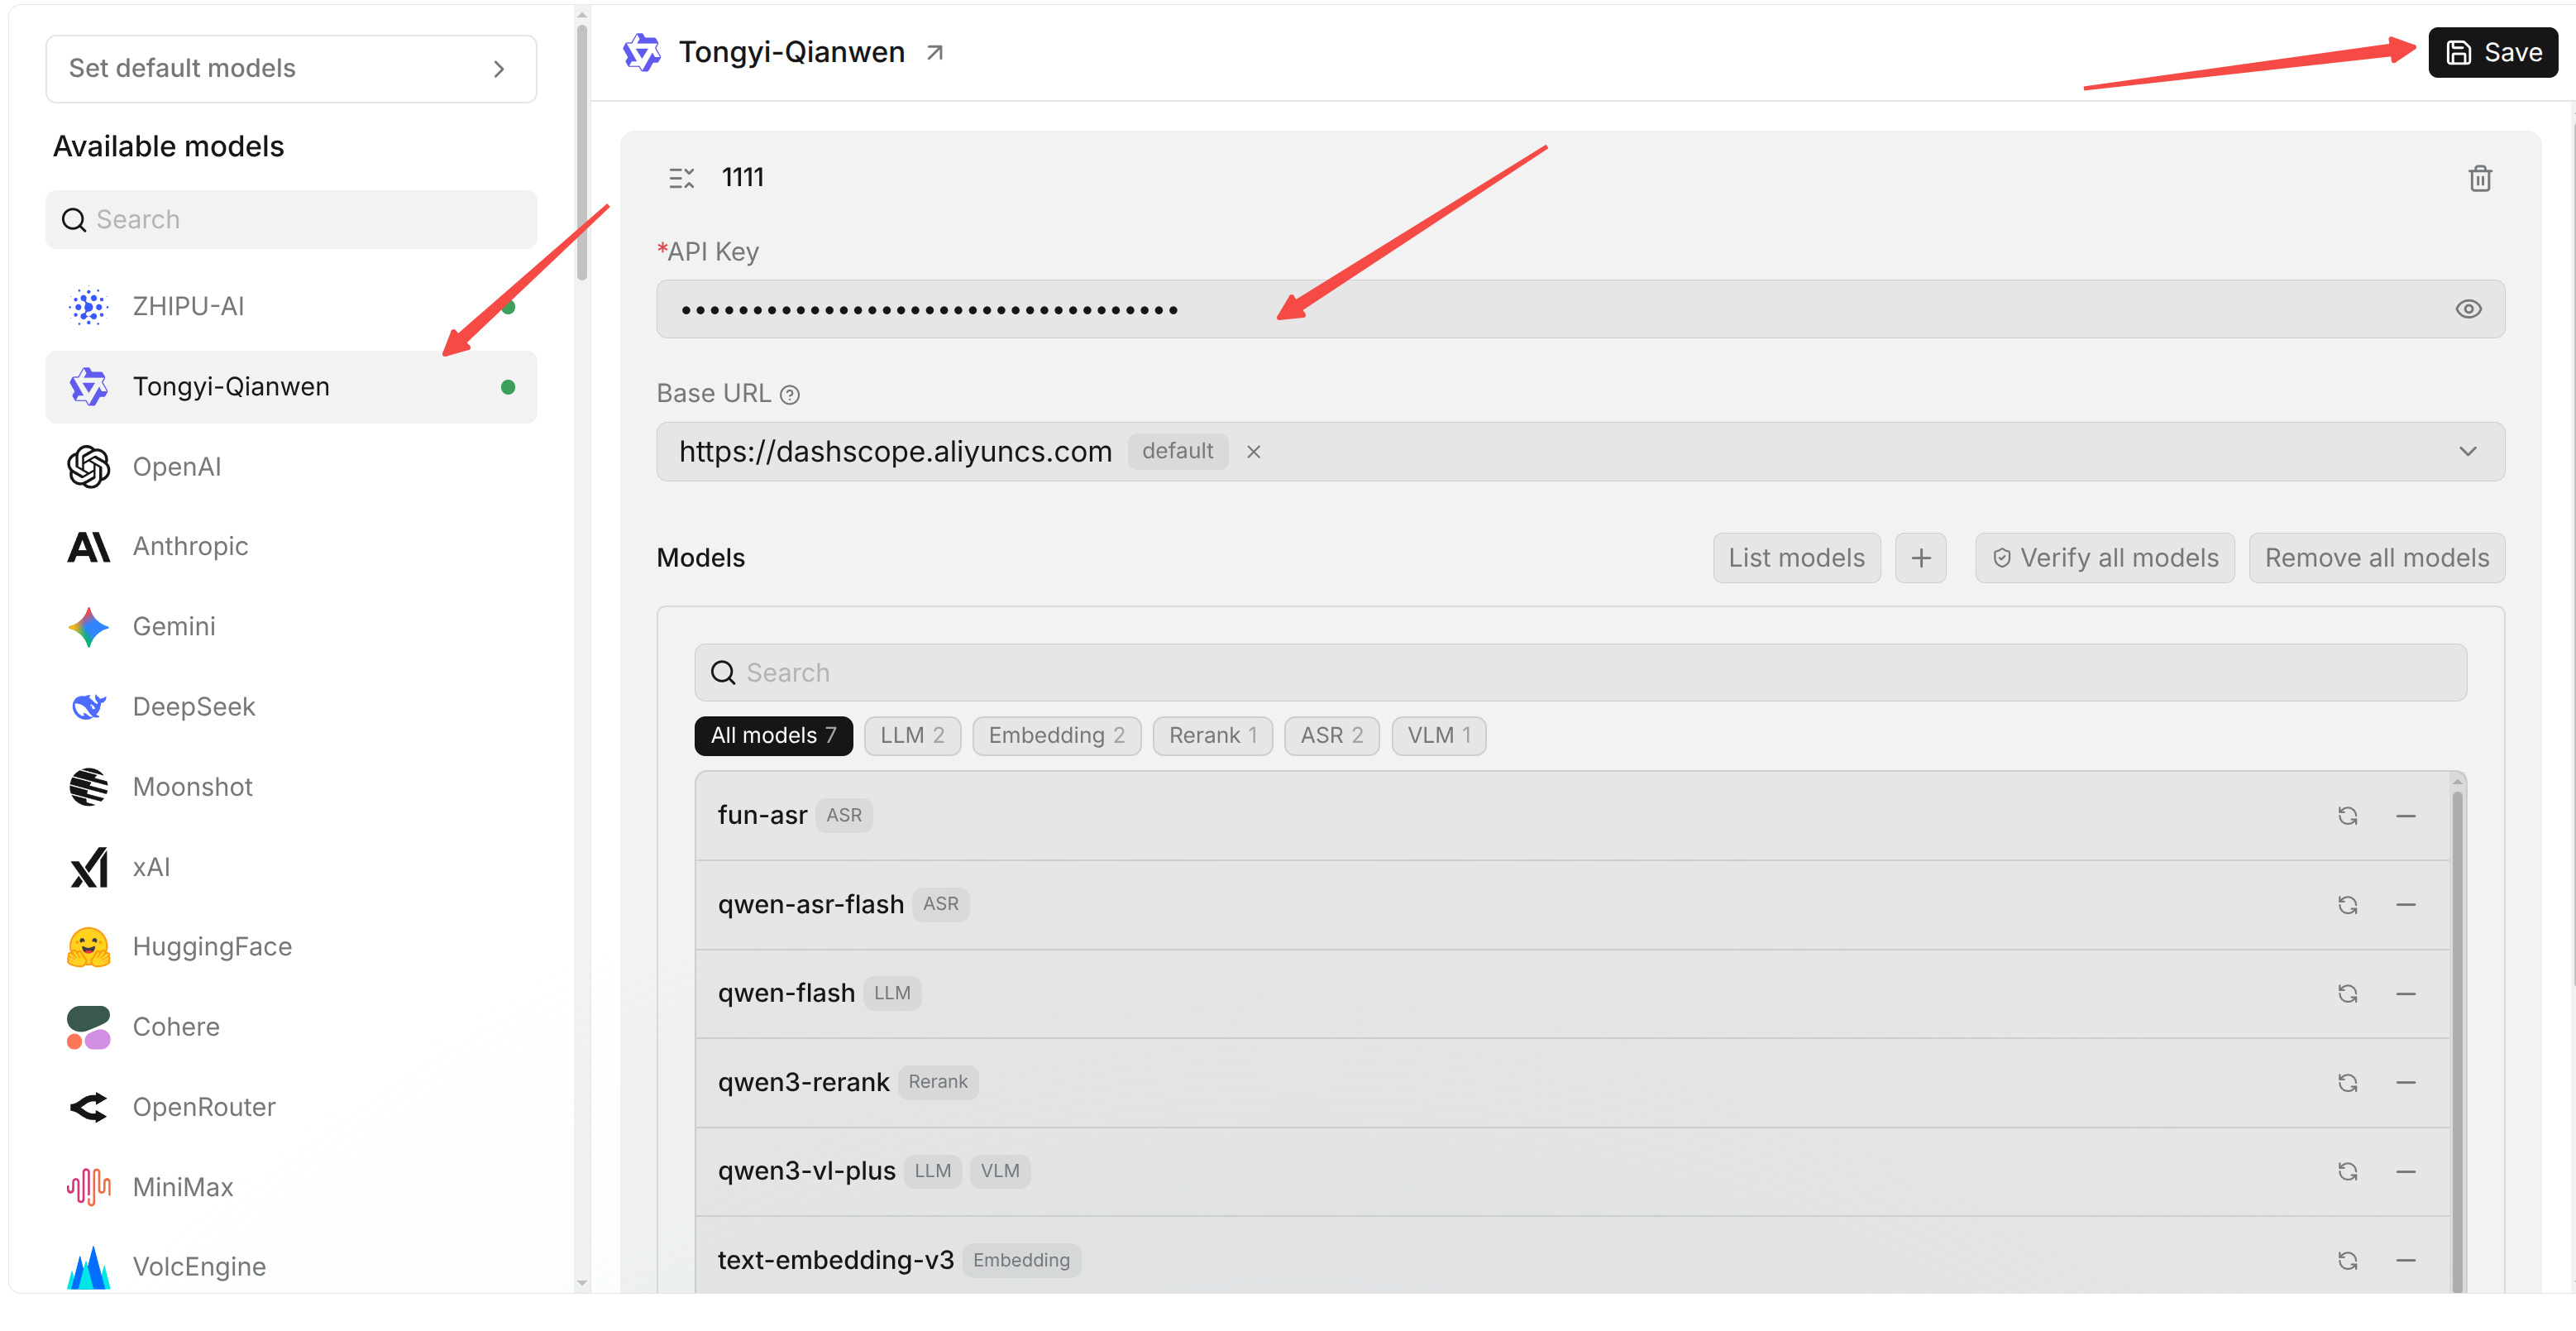
5. Verify models individually, or click **Verify all models** to verify every model currently shown by the active search and type filters.
|
||||
6. Save the instance.
|
||||
|
||||
|
||||
|
||||
|
||||
:::caution
|
||||
Do not expose your API Key. An incorrect Base URL causes model verification or model calls to fail. When using a compatible API, confirm whether the path must include `/v1`.
|
||||
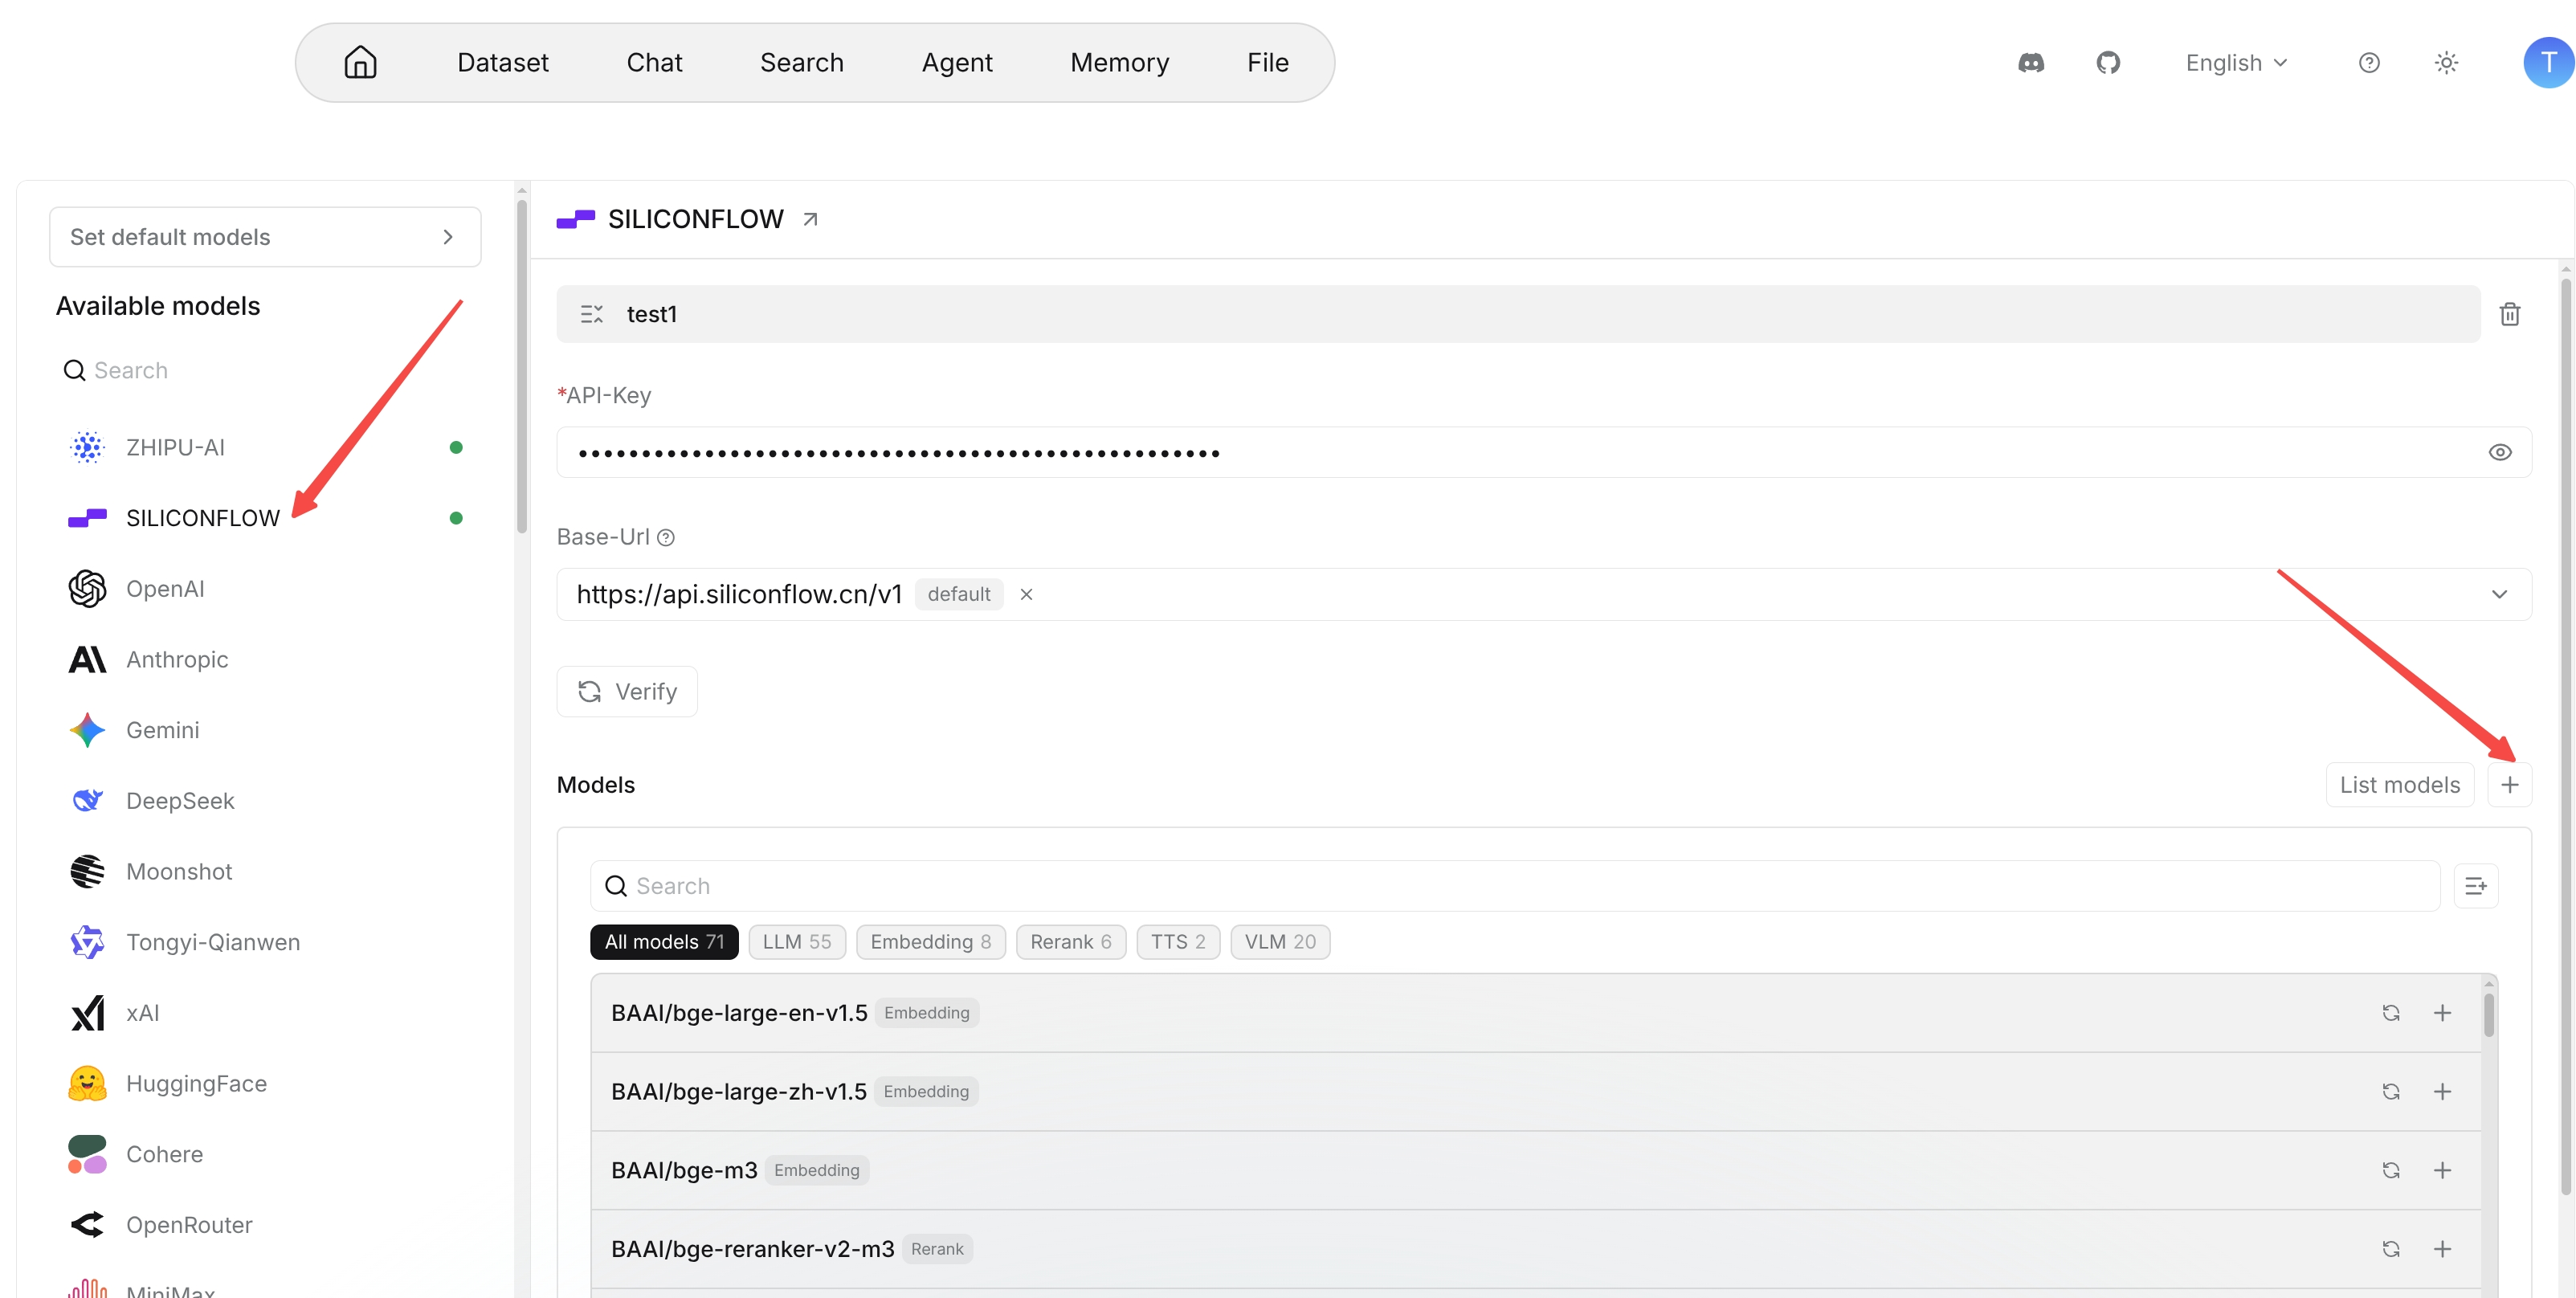
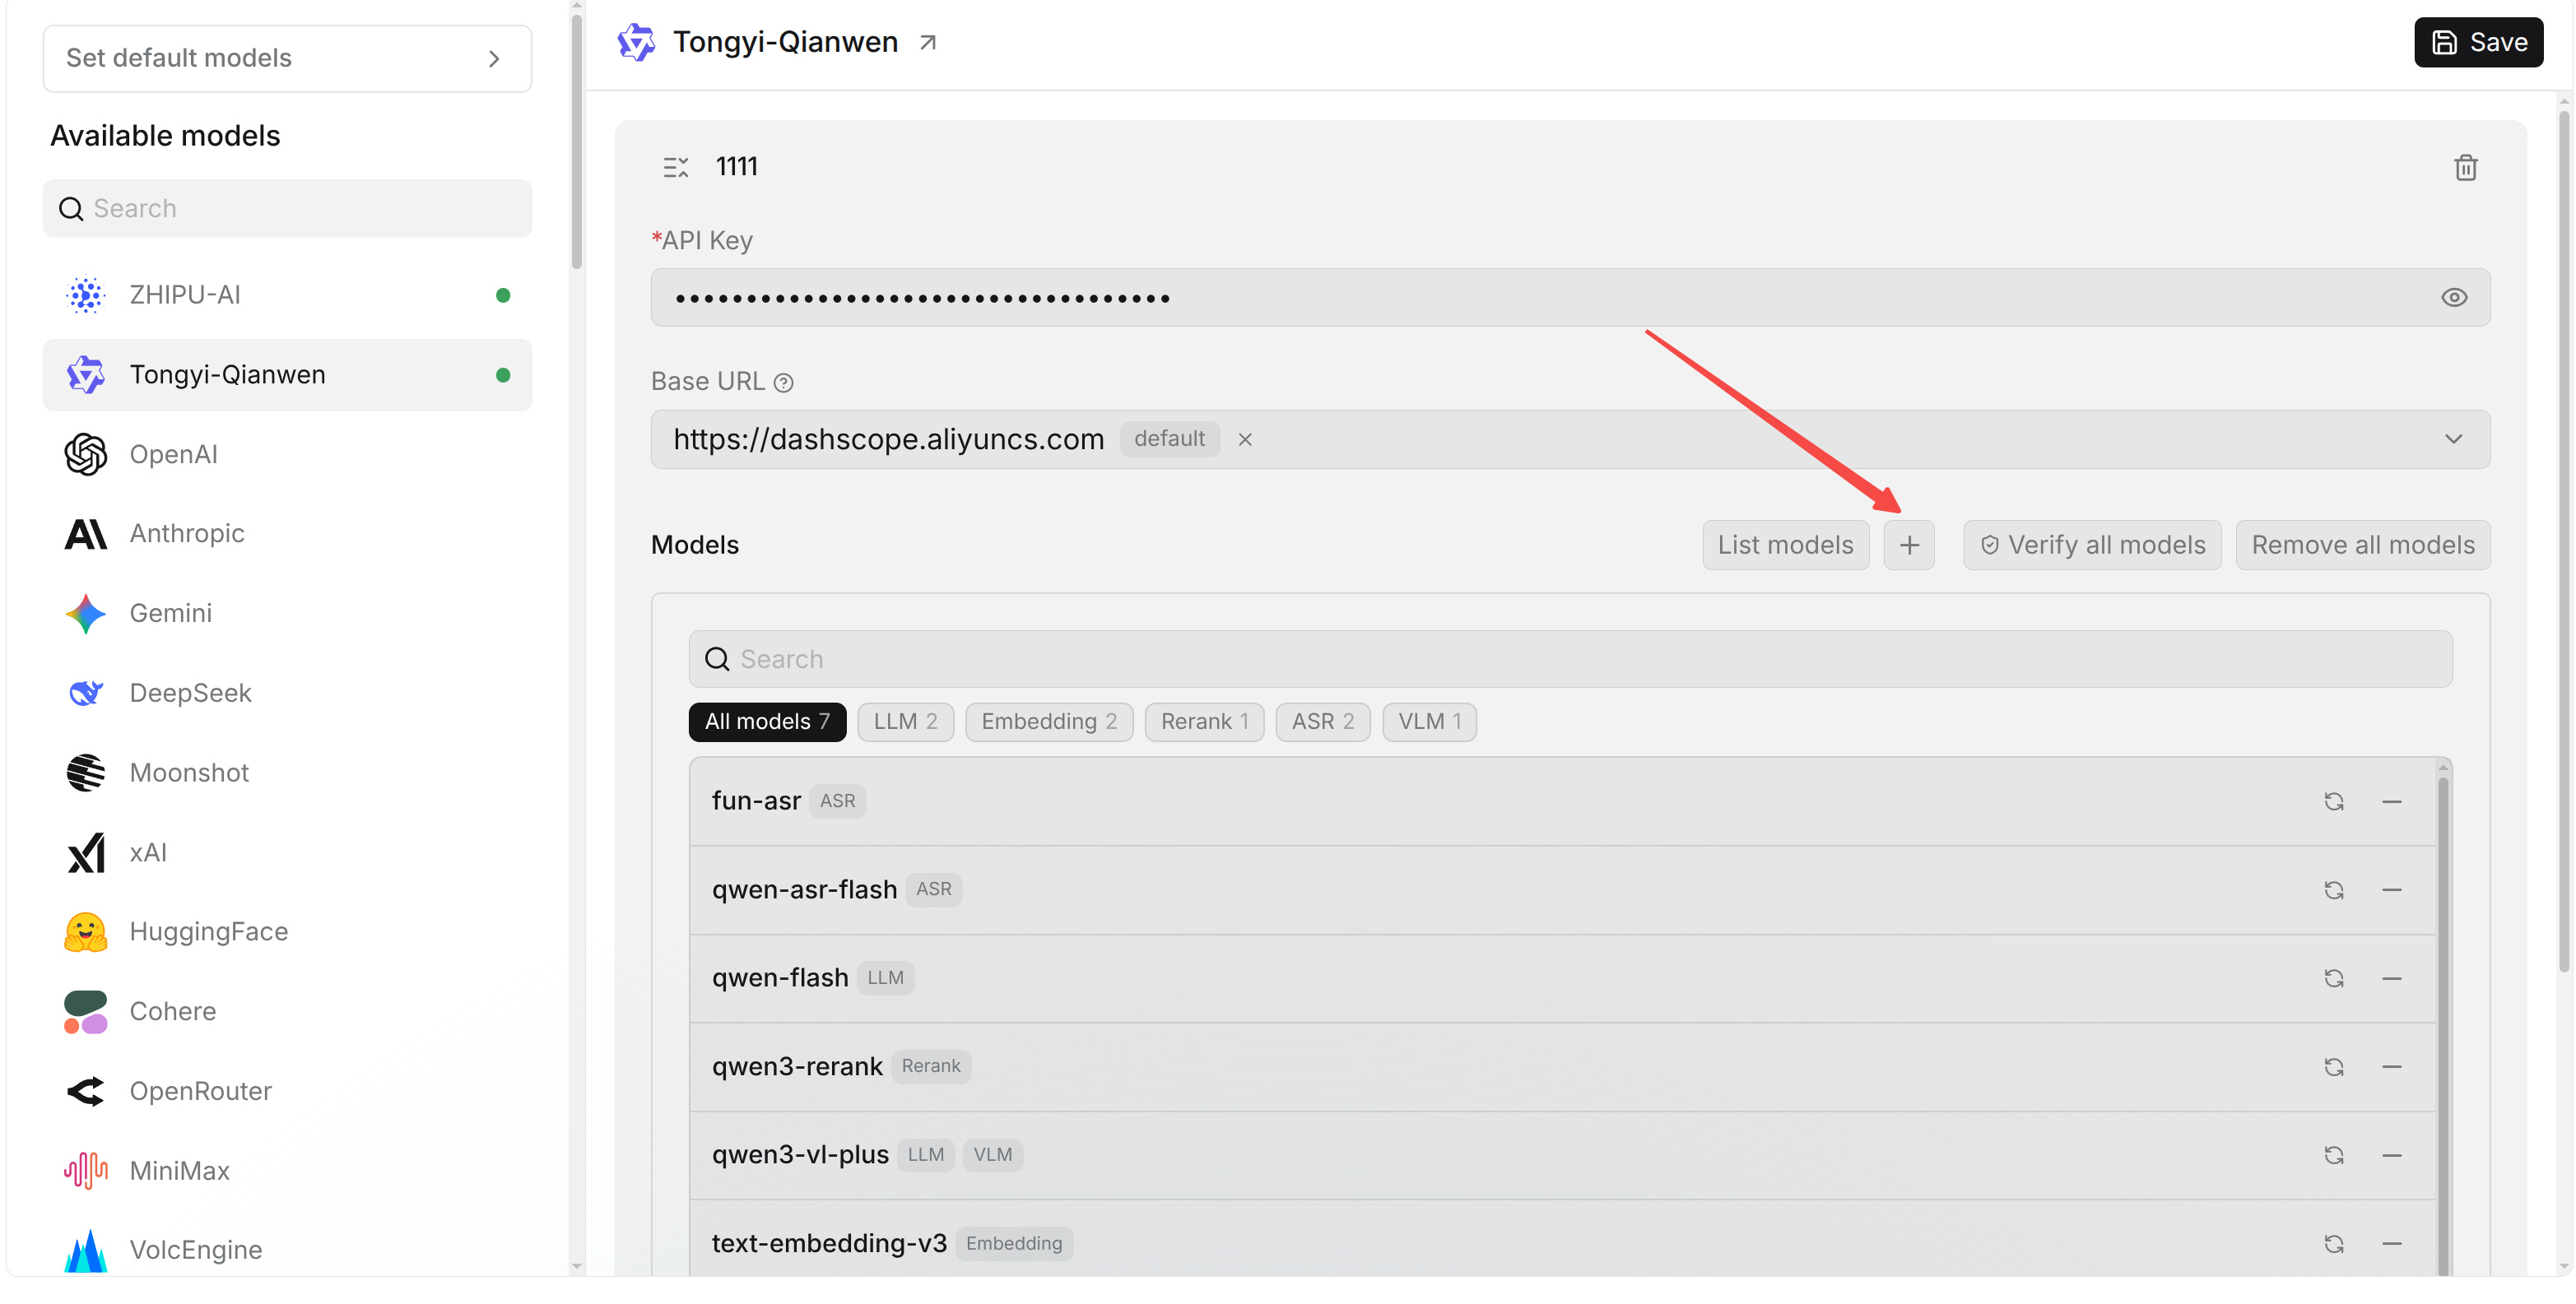
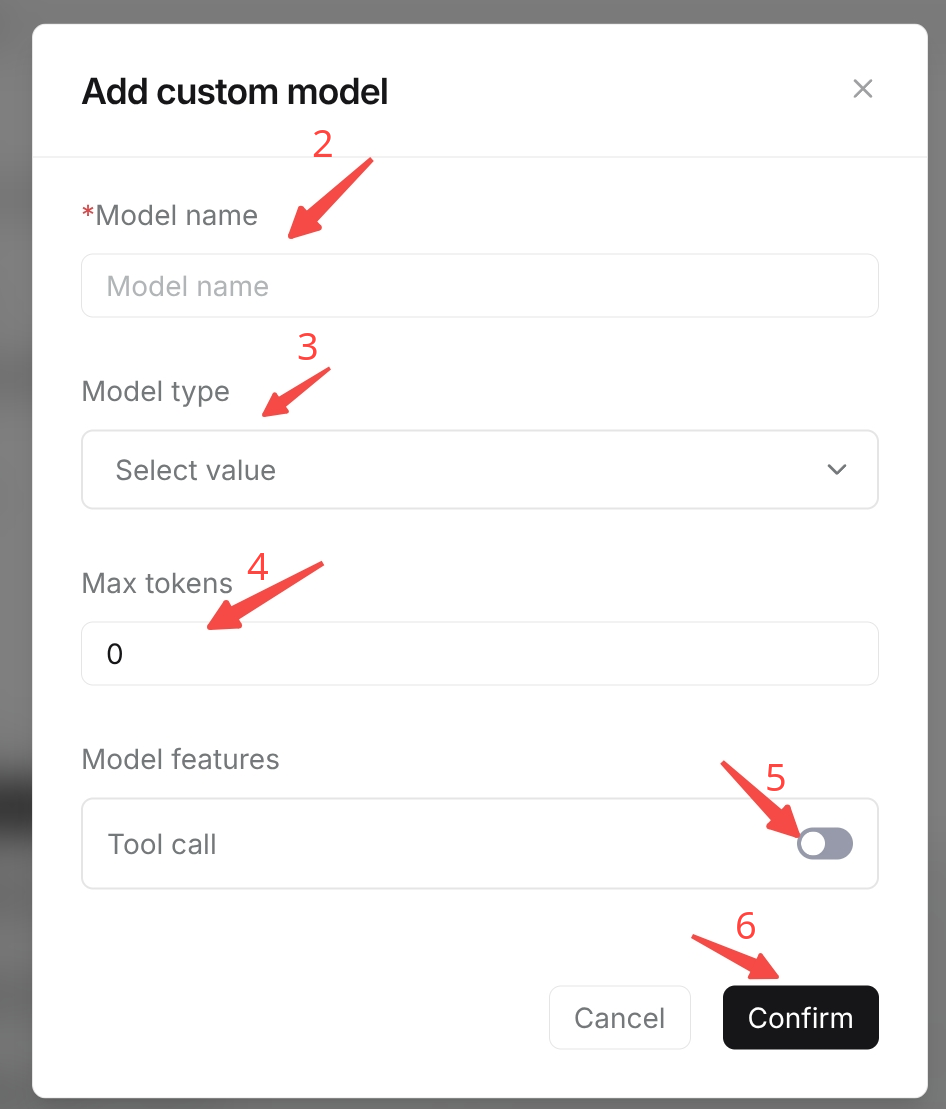
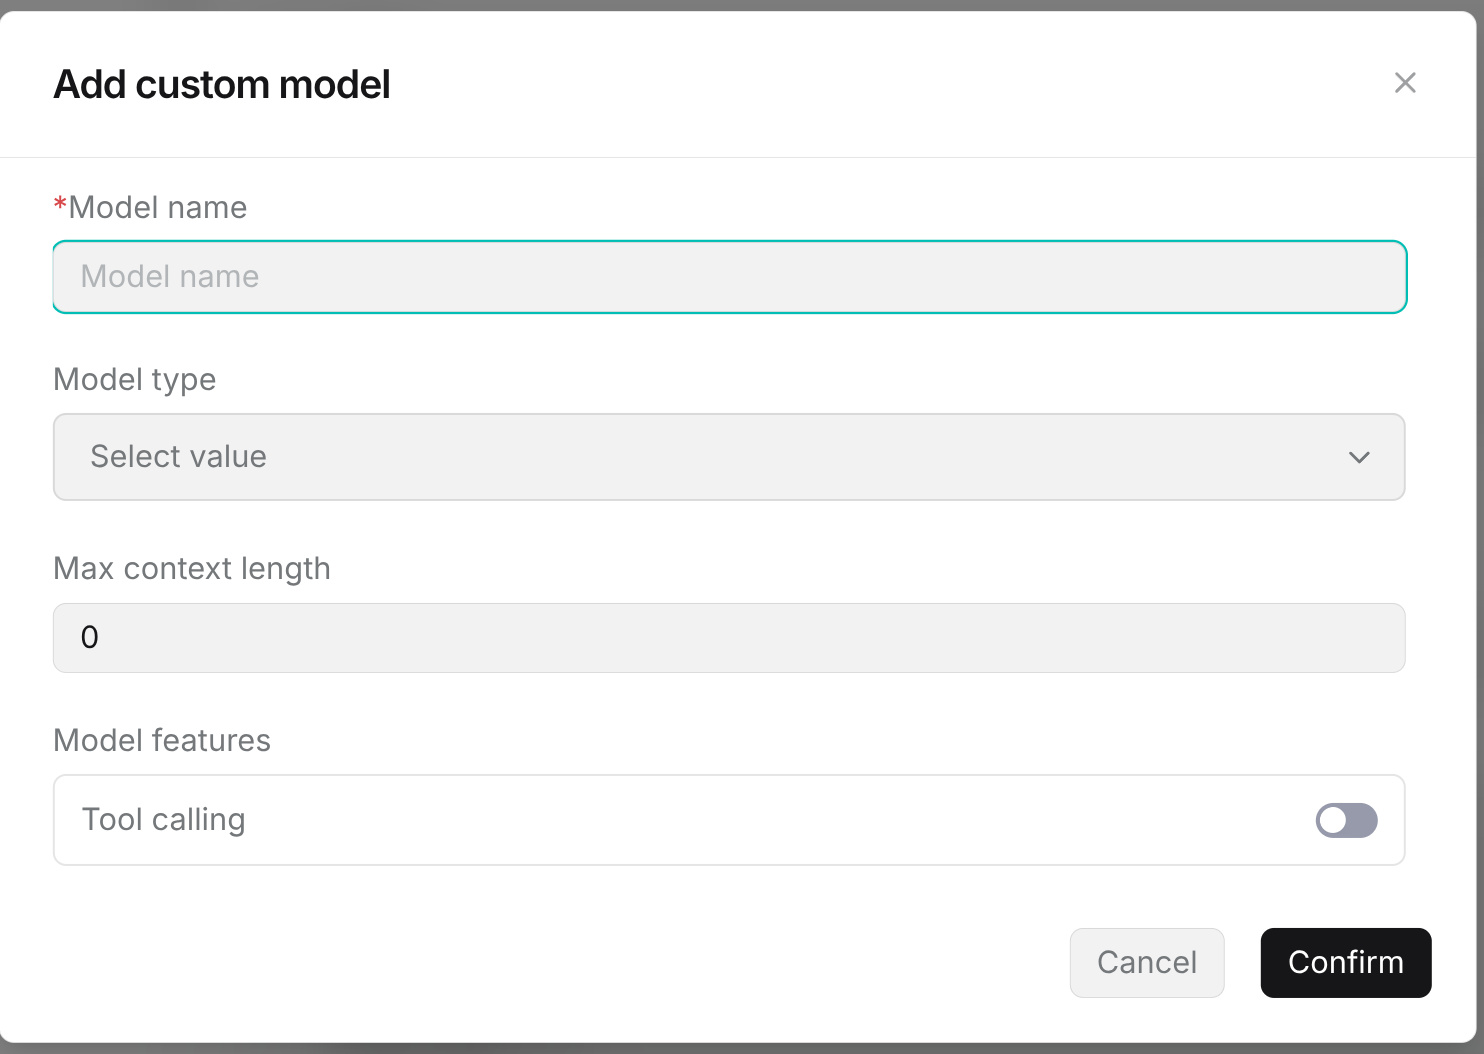
@@ -86,9 +86,9 @@ To add a custom model:
|
||||
6. Click **Confirm** to add the model.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
### Verify Models
|
||||
|
||||
@@ -112,7 +112,7 @@ At minimum, set the following defaults:
|
||||
|
||||
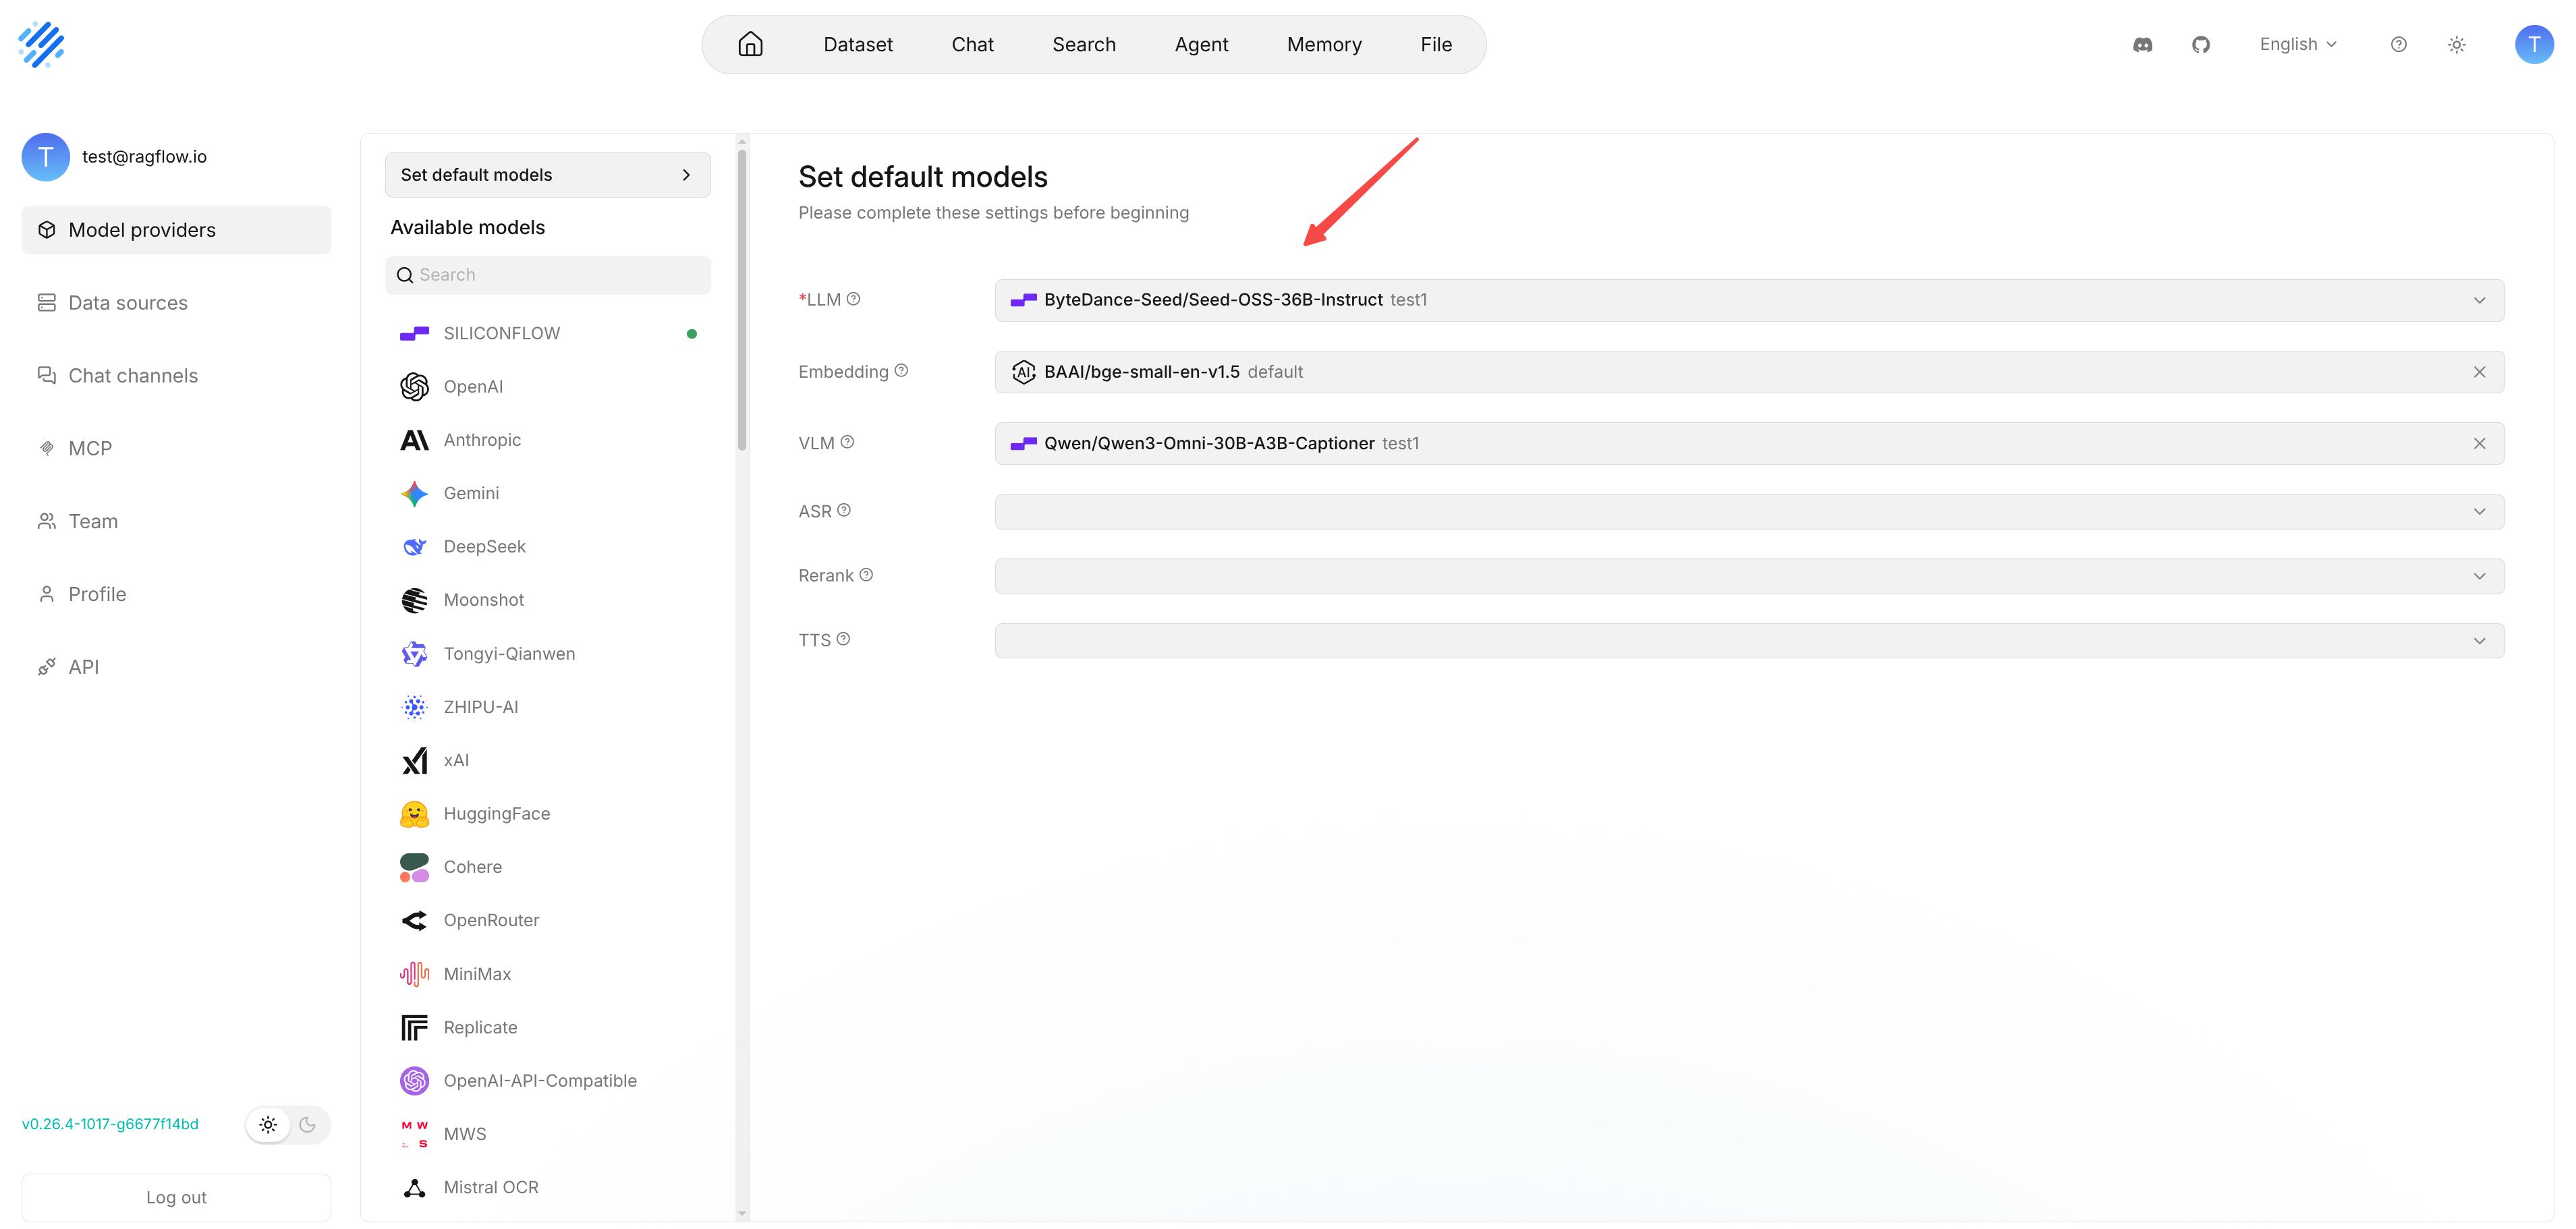
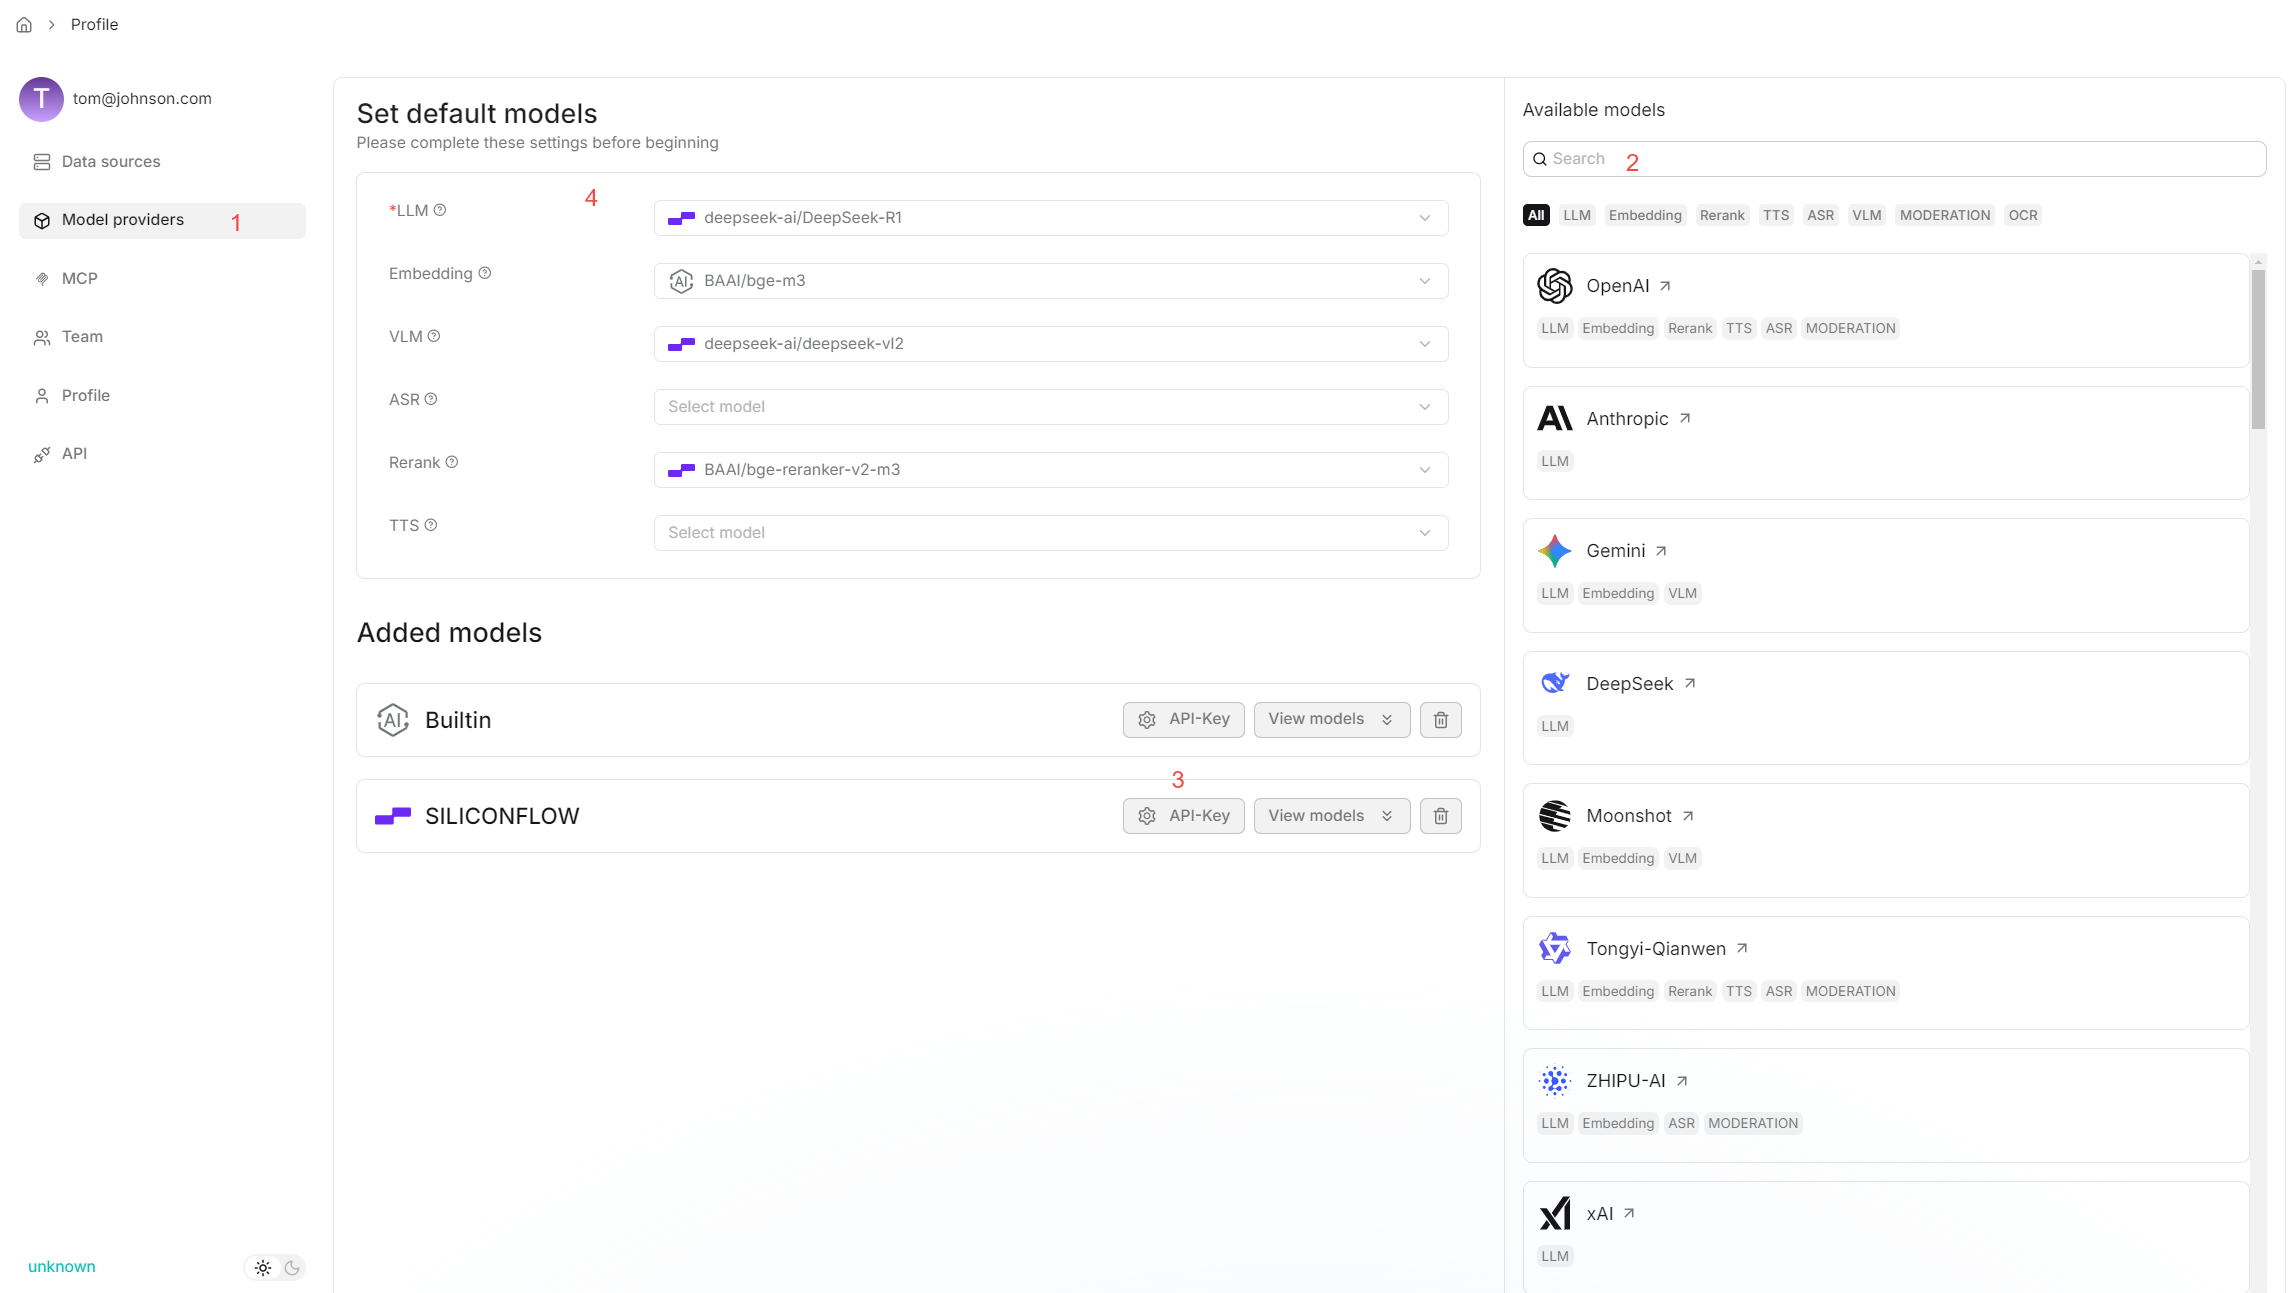
If you have configured a rerank model, it is also recommended to set a default rerank model. Configure VLM, ASR, and TTS defaults as required by your business.
|
||||
|
||||
|
||||
|
||||
|
||||
### Decision Model
|
||||
|
||||
|
||||
Reference in new issue
Block a user