mirror of
https://github.com/infiniflow/ragflow.git
synced 2026-11-10 21:32:43 +08:00
feat(connector): add Sitemap data source for sitemap.xml-based web ingestion (#19344)
Add Sitemap data source — ingests web pages from sitemap.xml with incremental sync. Supports HTML→Markdown extraction, PDF discovery, URL filtering, SSRF protection.
This commit is contained in:
 VincentLambert authored and
 GitHub committed
1 parent
a670f5260b
commit
371cfabd95
30 files changed
+3273
-22
No files matched your search
@@ -142,6 +142,7 @@ class FileSource(StrEnum):
|
||||
LOCAL = ""
|
||||
KNOWLEDGEBASE = "knowledgebase"
|
||||
RSS = "rss"
|
||||
SITEMAP = "sitemap"
|
||||
S3 = "s3"
|
||||
NOTION = "notion"
|
||||
REST_API = "rest_api"
|
||||
|
||||
@@ -63,6 +63,7 @@ from .rss_connector import RSSConnector
|
||||
from .salesforce_connector import SalesforceConnector
|
||||
from .seafile_connector import SeaFileConnector
|
||||
from .sharepoint_connector import SharePointConnector
|
||||
from .sitemap_connector import SitemapConnector
|
||||
from .slack_connector import SlackConnector
|
||||
from .teams_connector import TeamsConnector
|
||||
from .webdav_connector import WebDAVConnector
|
||||
@@ -83,6 +84,7 @@ CONNECTOR_BY_SOURCE: dict[str, type] = {
|
||||
FileSource.GOOGLE_DRIVE: GoogleDriveConnector,
|
||||
FileSource.JIRA: JiraConnector,
|
||||
FileSource.SHAREPOINT: SharePointConnector,
|
||||
FileSource.SITEMAP: SitemapConnector,
|
||||
FileSource.SLACK: SlackConnector,
|
||||
FileSource.TEAMS: TeamsConnector,
|
||||
FileSource.WEBDAV: WebDAVConnector,
|
||||
@@ -160,6 +162,7 @@ __all__ = [
|
||||
"SalesforceConnector",
|
||||
"SeaFileConnector",
|
||||
"SharePointConnector",
|
||||
"SitemapConnector",
|
||||
"SlackConnector",
|
||||
"TeamsConnector",
|
||||
"TextSection",
|
||||
|
||||
@@ -44,6 +44,7 @@ class DocumentSource(str, Enum):
|
||||
"""Document sources"""
|
||||
|
||||
RSS = "rss"
|
||||
SITEMAP = "sitemap"
|
||||
S3 = "s3"
|
||||
NOTION = "notion"
|
||||
REST_API = "rest_api"
|
||||
|
||||
@@ -48,8 +48,13 @@ def format_element_text(element_text: str, link_href: str | None) -> str:
|
||||
return f"[{element_text_no_newlines}]({link_href})"
|
||||
|
||||
|
||||
def parse_html_with_trafilatura(html_content: str) -> str:
|
||||
"""Parse HTML content using trafilatura."""
|
||||
def parse_html_with_trafilatura(html_content: str, output_format: str = "txt") -> str:
|
||||
"""Parse HTML content using trafilatura.
|
||||
|
||||
``output_format`` is passed through to trafilatura: ``"txt"`` (default) yields the
|
||||
flat text used by the web connectors, ``"markdown"`` keeps headings, lists, links
|
||||
and tables as Markdown (see :func:`web_html_to_markdown`).
|
||||
"""
|
||||
import trafilatura # type: ignore
|
||||
from trafilatura.settings import use_config # type: ignore
|
||||
|
||||
@@ -59,6 +64,24 @@ def parse_html_with_trafilatura(html_content: str) -> str:
|
||||
config.set("DEFAULT", "include_images", "True")
|
||||
config.set("DEFAULT", "include_formatting", "True")
|
||||
|
||||
if output_format == "markdown":
|
||||
# trafilatura reads the include_* switches from keyword arguments, not from the
|
||||
# config object, so they are passed explicitly here: links and tables are kept
|
||||
# as Markdown, images are dropped (noise for retrieval), and favor_recall keeps
|
||||
# short but relevant sections. Markdown is whitespace-sensitive (nested lists,
|
||||
# tables), so only the ends are trimmed.
|
||||
extracted_text = trafilatura.extract(
|
||||
html_content,
|
||||
config=config,
|
||||
output_format="markdown",
|
||||
include_links=True,
|
||||
include_tables=True,
|
||||
include_images=False,
|
||||
include_formatting=True,
|
||||
favor_recall=True,
|
||||
)
|
||||
return extracted_text.strip() if extracted_text else ""
|
||||
|
||||
extracted_text = trafilatura.extract(html_content, config=config)
|
||||
return strip_excessive_newlines_and_spaces(extracted_text) if extracted_text else ""
|
||||
|
||||
@@ -155,11 +178,20 @@ def parse_html_page_basic(text: str | BytesIO | IO[bytes]) -> str:
|
||||
return format_document_soup(soup)
|
||||
|
||||
|
||||
def web_html_cleanup(
|
||||
def _clean_web_soup(
|
||||
page_content: str | bs4.BeautifulSoup,
|
||||
mintlify_cleanup_enabled: bool = True,
|
||||
additional_element_types_to_discard: list[str] | None = None,
|
||||
) -> ParsedHTML:
|
||||
mintlify_cleanup_enabled: bool,
|
||||
additional_element_types_to_discard: list[str] | None,
|
||||
remove_title: bool = True,
|
||||
) -> tuple[str | None, bs4.BeautifulSoup]:
|
||||
"""Shared pre-processing of web pages: title extraction and removal of boilerplate.
|
||||
|
||||
Boilerplate is dropped by CSS class (``WEB_CONNECTOR_IGNORED_CLASSES``, plus the
|
||||
Mintlify ones when enabled) and by tag (``WEB_CONNECTOR_IGNORED_ELEMENTS`` such as
|
||||
nav/footer/script, plus any caller-provided tags). The ``<title>`` text is returned;
|
||||
the tag itself is removed unless ``remove_title`` is False (trafilatura otherwise
|
||||
promotes the first ``<h1>`` to document title and drops it from the body).
|
||||
"""
|
||||
if isinstance(page_content, str):
|
||||
soup = bs4.BeautifulSoup(page_content, "html.parser")
|
||||
else:
|
||||
@@ -169,7 +201,8 @@ def web_html_cleanup(
|
||||
title = None
|
||||
if title_tag and title_tag.text:
|
||||
title = title_tag.text
|
||||
title_tag.extract()
|
||||
if remove_title:
|
||||
title_tag.extract()
|
||||
|
||||
# Heuristics based cleaning of elements based on css classes
|
||||
unwanted_classes = copy(WEB_CONNECTOR_IGNORED_CLASSES)
|
||||
@@ -185,21 +218,51 @@ def web_html_cleanup(
|
||||
for undesired_tag in additional_element_types_to_discard:
|
||||
[tag.extract() for tag in soup.find_all(undesired_tag)]
|
||||
|
||||
soup_string = str(soup)
|
||||
page_text = ""
|
||||
return title, soup
|
||||
|
||||
if PARSE_WITH_TRAFILATURA:
|
||||
|
||||
def _extract_web_text(soup: bs4.BeautifulSoup, output_format: str, use_trafilatura: bool) -> str:
|
||||
"""Extract text from a cleaned soup with trafilatura, falling back on the bs4 formatter."""
|
||||
page_text = ""
|
||||
if use_trafilatura:
|
||||
try:
|
||||
page_text = parse_html_with_trafilatura(soup_string)
|
||||
page_text = parse_html_with_trafilatura(str(soup), output_format=output_format)
|
||||
if not page_text:
|
||||
raise ValueError("Empty content returned by trafilatura.")
|
||||
except Exception as e:
|
||||
logging.info(f"Trafilatura parsing failed: {e}. Falling back on bs4.")
|
||||
page_text = format_document_soup(soup)
|
||||
else:
|
||||
if not page_text:
|
||||
title_tag = soup.find("title")
|
||||
if title_tag is not None:
|
||||
title_tag.extract()
|
||||
page_text = format_document_soup(soup)
|
||||
|
||||
# 200B is ZeroWidthSpace which we don't care for
|
||||
cleaned_text = page_text.replace("\u200b", "")
|
||||
return page_text.replace("\u200b", "")
|
||||
|
||||
return ParsedHTML(title=title, cleaned_text=cleaned_text)
|
||||
|
||||
def web_html_cleanup(
|
||||
page_content: str | bs4.BeautifulSoup,
|
||||
mintlify_cleanup_enabled: bool = True,
|
||||
additional_element_types_to_discard: list[str] | None = None,
|
||||
) -> ParsedHTML:
|
||||
"""Clean a web page and extract its flat text (title + boilerplate-free content)."""
|
||||
title, soup = _clean_web_soup(page_content, mintlify_cleanup_enabled, additional_element_types_to_discard)
|
||||
return ParsedHTML(title=title, cleaned_text=_extract_web_text(soup, "txt", use_trafilatura=PARSE_WITH_TRAFILATURA))
|
||||
|
||||
|
||||
def web_html_to_markdown(
|
||||
page_content: str | bs4.BeautifulSoup,
|
||||
mintlify_cleanup_enabled: bool = True,
|
||||
additional_element_types_to_discard: list[str] | None = None,
|
||||
) -> ParsedHTML:
|
||||
"""Clean a web page like :func:`web_html_cleanup` but keep the structure as Markdown.
|
||||
|
||||
Same boilerplate removal and title extraction; the content is extracted by
|
||||
trafilatura with ``output_format="markdown"`` (headings, lists, links, tables).
|
||||
Markdown output needs trafilatura, so this path does not depend on the
|
||||
``PARSE_WITH_TRAFILATURA`` switch (which only governs the flat-text connectors);
|
||||
the flat bs4 text is used as a fallback when trafilatura fails or returns nothing.
|
||||
"""
|
||||
title, soup = _clean_web_soup(page_content, mintlify_cleanup_enabled, additional_element_types_to_discard, remove_title=False)
|
||||
return ParsedHTML(title=title, cleaned_text=_extract_web_text(soup, "markdown", use_trafilatura=True))
|
||||
@@ -0,0 +1,615 @@
|
||||
import asyncio
|
||||
import hashlib
|
||||
import logging
|
||||
import queue
|
||||
import re
|
||||
import threading
|
||||
from collections.abc import Callable, Iterator
|
||||
from datetime import UTC, datetime
|
||||
from typing import Any
|
||||
from urllib.parse import urljoin, urlparse
|
||||
from xml.etree import ElementTree as ET
|
||||
|
||||
import regex
|
||||
import requests
|
||||
|
||||
from common.data_source.config import (
|
||||
INDEX_BATCH_SIZE,
|
||||
REQUEST_TIMEOUT_SECONDS,
|
||||
DocumentSource,
|
||||
)
|
||||
from common.data_source.html_utils import web_html_to_markdown
|
||||
from common.data_source.interfaces import LoadConnector, PollConnector, SlimConnectorWithPermSync
|
||||
from common.data_source.models import (
|
||||
Document,
|
||||
GenerateDocumentsOutput,
|
||||
GenerateSlimDocumentOutput,
|
||||
SecondsSinceUnixEpoch,
|
||||
SlimDocument,
|
||||
)
|
||||
from common.ssrf_guard import assert_url_is_safe
|
||||
from common.ssrf_guard import pin_dns as _pin_dns
|
||||
|
||||
_SITEMAP_NS = "http://www.sitemaps.org/schemas/sitemap/0.9"
|
||||
_MAX_REDIRECTS = 10
|
||||
_MAX_SITEMAP_DEPTH = 5
|
||||
_MAX_SITEMAP_FETCHES = 1000
|
||||
_MAX_RESPONSE_BYTES = 64 * 1024 * 1024
|
||||
_READ_CHUNK_BYTES = 64 * 1024
|
||||
_MAX_URL_FILTER_LENGTH = 512
|
||||
_MAX_MATCHED_URL_LENGTH = 4096
|
||||
_URL_FILTER_TIMEOUT_SECONDS = 1.0
|
||||
# A quantified group that itself contains a quantifier, e.g. "(a+)+" or "(a*b)*":
|
||||
# the classic shape behind catastrophic backtracking in Python's regex engine.
|
||||
_NESTED_QUANTIFIER_RE = re.compile(r"\([^()]*[+*}][^()]*\)\s*[+*{?]")
|
||||
|
||||
logger = logging.getLogger(__name__)
|
||||
|
||||
_QUEUE_END = object()
|
||||
_QUEUE_POLL_SECONDS = 0.5
|
||||
|
||||
|
||||
class _WorkerThreadIterator:
|
||||
"""Iterator over items produced by ``source`` in a daemon worker thread.
|
||||
|
||||
See :func:`iter_in_worker_thread`. ``offload_next`` tells the sync worker that
|
||||
``next()`` may block and should be awaited through ``asyncio.to_thread``.
|
||||
"""
|
||||
|
||||
offload_next = True
|
||||
|
||||
def __init__(self, source: Iterator[Any], maxsize: int, on_close: Callable[[], None] | None):
|
||||
self._source = source
|
||||
self._queue: queue.Queue = queue.Queue(maxsize=maxsize)
|
||||
self._stop = threading.Event()
|
||||
self._closed = False
|
||||
self._on_close = on_close
|
||||
self._worker = threading.Thread(target=self._produce, name="sitemap-batch-producer", daemon=True)
|
||||
self._worker.start()
|
||||
|
||||
def _put(self, item: Any) -> bool:
|
||||
"""Enqueue ``item`` unless the consumer went away; never blocks forever."""
|
||||
while not self._stop.is_set():
|
||||
try:
|
||||
self._queue.put(item, timeout=_QUEUE_POLL_SECONDS)
|
||||
return True
|
||||
except queue.Full:
|
||||
continue
|
||||
return False
|
||||
|
||||
def _produce(self) -> None:
|
||||
try:
|
||||
for item in self._source:
|
||||
if not self._put(item):
|
||||
return
|
||||
self._put(_QUEUE_END)
|
||||
except BaseException as exc: # noqa: BLE001 - forwarded to the consumer
|
||||
self._put(exc)
|
||||
finally:
|
||||
close = getattr(self._source, "close", None)
|
||||
if close is not None:
|
||||
try:
|
||||
close()
|
||||
except Exception:
|
||||
logger.debug("worker-thread generator close() failed", exc_info=True)
|
||||
|
||||
def __iter__(self) -> "_WorkerThreadIterator":
|
||||
return self
|
||||
|
||||
def __next__(self) -> Any:
|
||||
while True:
|
||||
if self._closed:
|
||||
raise StopIteration
|
||||
try:
|
||||
item = self._queue.get(timeout=_QUEUE_POLL_SECONDS)
|
||||
except queue.Empty:
|
||||
continue
|
||||
if item is _QUEUE_END:
|
||||
self.close()
|
||||
raise StopIteration
|
||||
if isinstance(item, BaseException):
|
||||
self.close()
|
||||
raise item
|
||||
return item
|
||||
|
||||
def close(self) -> None:
|
||||
"""Stop the producer; also invoked when the consumer abandons iteration."""
|
||||
if self._closed:
|
||||
return
|
||||
self._closed = True
|
||||
self._stop.set()
|
||||
if self._on_close is not None:
|
||||
try:
|
||||
self._on_close()
|
||||
except Exception:
|
||||
logger.debug("worker-thread on_close callback failed", exc_info=True)
|
||||
|
||||
def join(self, timeout: float | None = None) -> None:
|
||||
self._worker.join(timeout)
|
||||
|
||||
@property
|
||||
def producer_alive(self) -> bool:
|
||||
return self._worker.is_alive()
|
||||
|
||||
|
||||
async def validate_connector_in_thread(connector: "SitemapConnector") -> None:
|
||||
"""Run ``validate_connector_settings`` off the event loop and propagate cancellation.
|
||||
|
||||
The sync worker wraps the whole task in ``asyncio.wait_for``. A thread started by
|
||||
``asyncio.to_thread`` cannot be interrupted, so when the awaiting coroutine is
|
||||
cancelled (task timeout) the connector is told to stop at its next cancellation
|
||||
check instead of finishing its fetches in the background.
|
||||
"""
|
||||
try:
|
||||
await asyncio.to_thread(connector.validate_connector_settings)
|
||||
except asyncio.CancelledError:
|
||||
logger.warning("Sitemap validation cancelled (task timeout) for %s; stopping the connector", connector.sitemap_url)
|
||||
connector.cancel()
|
||||
raise
|
||||
|
||||
|
||||
def iter_in_worker_thread(source: Iterator[Any], maxsize: int = 2, on_close: Callable[[], None] | None = None) -> _WorkerThreadIterator:
|
||||
"""Consume ``source`` in a daemon worker thread and hand its items over through a bounded queue.
|
||||
|
||||
The sync worker iterates connector generators on the asyncio thread. Running the
|
||||
generator (and therefore all its blocking HTTP calls) in a worker thread keeps that
|
||||
blocking off the event-loop thread and lets the next batch be downloaded while the
|
||||
previous one is indexed. Exceptions raised by the source are re-raised in the
|
||||
consumer. Closing the consumer stops the producer: queue writes are abandoned,
|
||||
and ``on_close`` (typically the connector's ``cancel``) is invoked so that an
|
||||
in-progress traversal gives up at its next check instead of finishing its fetches.
|
||||
"""
|
||||
return _WorkerThreadIterator(source, maxsize, on_close)
|
||||
|
||||
|
||||
class SitemapConnector(LoadConnector, PollConnector, SlimConnectorWithPermSync):
|
||||
"""Connector that ingests web pages listed in a sitemap.xml.
|
||||
|
||||
Supports:
|
||||
- Standard urlset sitemaps
|
||||
- Sitemap index files (recursive, up to _MAX_SITEMAP_DEPTH levels)
|
||||
- Incremental polling via <lastmod>
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
sitemap_url: str,
|
||||
batch_size: int = 10,
|
||||
user_agent: str = "RAGFlow-SitemapConnector/1.0",
|
||||
url_filter: str | None = None,
|
||||
follow_pdf_links: bool = False,
|
||||
restrict_pdf_to_domain: bool = True,
|
||||
) -> None:
|
||||
self.sitemap_url = sitemap_url.strip()
|
||||
self.batch_size = batch_size
|
||||
self.user_agent = user_agent
|
||||
self._url_filter: regex.Pattern | None = self._compile_url_filter(url_filter) if url_filter else None
|
||||
# Dedicated session: no ambient proxies / .netrc credentials from the worker
|
||||
# environment, so every request goes straight to the DNS-pinned address.
|
||||
self._session = requests.Session()
|
||||
self._session.trust_env = False
|
||||
self._cancel = threading.Event()
|
||||
self.follow_pdf_links = follow_pdf_links
|
||||
self.restrict_pdf_to_domain = restrict_pdf_to_domain
|
||||
self.credentials: dict[str, Any] = {}
|
||||
|
||||
@classmethod
|
||||
def build_connector(cls, config: dict[str, Any]) -> "SitemapConnector":
|
||||
"""Build a connector from the connector config stored by the UI/API."""
|
||||
connector = cls(
|
||||
sitemap_url=config["sitemap_url"],
|
||||
batch_size=int(config.get("batch_size") or INDEX_BATCH_SIZE),
|
||||
user_agent=(config.get("user_agent") or "").strip() or "RAGFlow-SitemapConnector/1.0",
|
||||
url_filter=(config.get("url_filter") or "").strip() or None,
|
||||
follow_pdf_links=bool(config.get("follow_pdf_links", False)),
|
||||
restrict_pdf_to_domain=bool(config.get("restrict_pdf_to_domain", True)),
|
||||
)
|
||||
connector.load_credentials(config.get("credentials") or {})
|
||||
return connector
|
||||
|
||||
def load_credentials(self, credentials: dict[str, Any]) -> dict[str, Any] | None:
|
||||
self.credentials = credentials or {}
|
||||
return None
|
||||
|
||||
def cancel(self) -> None:
|
||||
"""Ask an in-progress traversal to stop at its next check (next URL or next body chunk)."""
|
||||
self._cancel.set()
|
||||
|
||||
@property
|
||||
def cancelled(self) -> bool:
|
||||
return self._cancel.is_set()
|
||||
|
||||
@staticmethod
|
||||
def _compile_url_filter(pattern: str) -> regex.Pattern:
|
||||
"""Compile the user-provided url_filter with bounded evaluation.
|
||||
|
||||
The pattern is matched against sitemap-controlled URLs. It is compiled with the
|
||||
``regex`` module (already a transitive dependency through tiktoken / nltk) so
|
||||
that every match runs under a timeout, which is the only robust defence against
|
||||
catastrophic backtracking (``(a|aa)+`` and friends cannot be detected syntactically).
|
||||
The obvious nested-quantifier shapes are still refused up front to give users an
|
||||
immediate error, and the pattern length is bounded.
|
||||
"""
|
||||
if len(pattern) > _MAX_URL_FILTER_LENGTH:
|
||||
raise ValueError(f"url_filter is too long (max {_MAX_URL_FILTER_LENGTH} characters)")
|
||||
if _NESTED_QUANTIFIER_RE.search(pattern):
|
||||
raise ValueError("url_filter must not contain nested quantifiers such as '(a+)+', which can cause catastrophic backtracking")
|
||||
try:
|
||||
return regex.compile(pattern)
|
||||
except regex.error as exc:
|
||||
raise ValueError(f"url_filter is not a valid regex: {exc}") from exc
|
||||
|
||||
def validate_connector_settings(self) -> None:
|
||||
self._validate_url(self.sitemap_url)
|
||||
if self.batch_size < 1:
|
||||
raise ValueError("batch_size must be greater than 0")
|
||||
if not any(self._url_matches(u[0]) for u in self._iter_sitemap_urls(self.sitemap_url, depth=0)):
|
||||
raise ValueError("Sitemap contains no URLs matching the filter")
|
||||
|
||||
def load_from_state(self) -> GenerateDocumentsOutput:
|
||||
yield from self._load_urls()
|
||||
|
||||
def poll_source(self, start: SecondsSinceUnixEpoch, end: SecondsSinceUnixEpoch) -> GenerateDocumentsOutput:
|
||||
yield from self._load_urls(start=start, end=end)
|
||||
|
||||
def retrieve_all_slim_docs_perm_sync(self, callback: Any = None) -> GenerateSlimDocumentOutput:
|
||||
"""Yield the complete set of document IDs the connector currently exposes.
|
||||
|
||||
When ``follow_pdf_links`` is enabled the HTML pages are fetched so that
|
||||
the PDFs discovered in them are part of the retained set; otherwise a
|
||||
prune run would delete them right after they were indexed.
|
||||
"""
|
||||
del callback
|
||||
seen: set[str] = set()
|
||||
sitemap_domain = urlparse(self.sitemap_url).netloc
|
||||
batch: list[SlimDocument] = []
|
||||
for url, _lastmod in self._iter_sitemap_urls(self.sitemap_url, depth=0):
|
||||
if url in seen or not self._url_matches(url):
|
||||
continue
|
||||
seen.add(url)
|
||||
batch.append(SlimDocument(id=self._build_document_id(url)))
|
||||
if len(batch) >= self.batch_size:
|
||||
yield batch
|
||||
batch = []
|
||||
|
||||
if not self.follow_pdf_links:
|
||||
continue
|
||||
try:
|
||||
raw, content_type = self._fetch_raw(url)
|
||||
except (requests.RequestException, ValueError, OSError) as exc:
|
||||
logger.warning("Failed to fetch page %s for PDF discovery: %s", url, exc)
|
||||
continue
|
||||
if "application/pdf" in content_type:
|
||||
continue
|
||||
for pdf_url in self._extract_pdf_links(raw, url):
|
||||
if pdf_url in seen:
|
||||
continue
|
||||
if self.restrict_pdf_to_domain and urlparse(pdf_url).netloc != sitemap_domain:
|
||||
continue
|
||||
seen.add(pdf_url)
|
||||
batch.append(SlimDocument(id=self._build_document_id(pdf_url)))
|
||||
if len(batch) >= self.batch_size:
|
||||
yield batch
|
||||
batch = []
|
||||
if batch:
|
||||
yield batch
|
||||
|
||||
# ------------------------------------------------------------------
|
||||
# Internal helpers
|
||||
# ------------------------------------------------------------------
|
||||
|
||||
def _load_urls(
|
||||
self,
|
||||
start: SecondsSinceUnixEpoch | None = None,
|
||||
end: SecondsSinceUnixEpoch | None = None,
|
||||
) -> GenerateDocumentsOutput:
|
||||
seen: set[str] = set()
|
||||
pending_pdfs: list[tuple[str, str]] = [] # (pdf_url, parent_url)
|
||||
sitemap_domain = urlparse(self.sitemap_url).netloc
|
||||
|
||||
# --- Pass 1: sitemap URLs ---
|
||||
batch: list[Document] = []
|
||||
for url, lastmod in self._iter_sitemap_urls(self.sitemap_url, depth=0):
|
||||
if self._cancel.is_set():
|
||||
logger.info("Sitemap traversal cancelled")
|
||||
return
|
||||
if url in seen or not self._url_matches(url):
|
||||
continue
|
||||
seen.add(url)
|
||||
|
||||
if start is not None or end is not None:
|
||||
if lastmod is None:
|
||||
if start is not None:
|
||||
continue
|
||||
else:
|
||||
ts = lastmod.timestamp()
|
||||
if start is not None and ts <= start:
|
||||
continue
|
||||
if end is not None and ts > end:
|
||||
continue
|
||||
|
||||
doc = self._fetch_and_build_document(url, lastmod, seen, pending_pdfs, sitemap_domain)
|
||||
if doc is None:
|
||||
continue
|
||||
|
||||
batch.append(doc)
|
||||
if len(batch) >= self.batch_size:
|
||||
yield batch
|
||||
batch = []
|
||||
|
||||
if batch:
|
||||
yield batch
|
||||
|
||||
# --- Pass 2: PDF links discovered from HTML pages ---
|
||||
if not self.follow_pdf_links or not pending_pdfs:
|
||||
return
|
||||
|
||||
batch = []
|
||||
for pdf_url, parent_url in pending_pdfs:
|
||||
if self._cancel.is_set():
|
||||
logger.info("Sitemap traversal cancelled during PDF pass")
|
||||
return
|
||||
doc = self._fetch_and_build_document(pdf_url, None, seen, [], sitemap_domain, parent_url)
|
||||
if doc is None:
|
||||
continue
|
||||
batch.append(doc)
|
||||
if len(batch) >= self.batch_size:
|
||||
yield batch
|
||||
batch = []
|
||||
|
||||
if batch:
|
||||
yield batch
|
||||
|
||||
def _iter_sitemap_urls(self, sitemap_url: str, depth: int, _walk: dict[str, Any] | None = None) -> Iterator[tuple[str, datetime | None]]:
|
||||
"""Recursively yield (url, lastmod) pairs from a sitemap or sitemap index.
|
||||
|
||||
Each sitemap URL is fetched at most once (an index referencing itself or an
|
||||
ancestor is skipped) and the walk stops after ``_MAX_SITEMAP_FETCHES`` sitemap
|
||||
documents, so one connector cannot trigger unbounded egress.
|
||||
"""
|
||||
if _walk is None:
|
||||
_walk = {"visited": set(), "fetched": 0}
|
||||
if depth > _MAX_SITEMAP_DEPTH:
|
||||
logger.warning("Max sitemap depth reached, stopping at %s", sitemap_url)
|
||||
return
|
||||
if sitemap_url in _walk["visited"]:
|
||||
logger.warning("Sitemap %s already visited, skipping", sitemap_url)
|
||||
return
|
||||
_walk["visited"].add(sitemap_url)
|
||||
if _walk["fetched"] >= _MAX_SITEMAP_FETCHES:
|
||||
logger.warning("Maximum number of sitemap fetches (%s) reached, stopping at %s", _MAX_SITEMAP_FETCHES, sitemap_url)
|
||||
return
|
||||
_walk["fetched"] += 1
|
||||
if self._cancel.is_set():
|
||||
return
|
||||
|
||||
try:
|
||||
self._validate_url(sitemap_url)
|
||||
content, _ = self._fetch_raw(sitemap_url)
|
||||
except (requests.RequestException, ValueError, OSError) as exc:
|
||||
logger.warning("Failed to fetch sitemap %s: %s", sitemap_url, exc)
|
||||
return
|
||||
|
||||
try:
|
||||
root = ET.fromstring(content)
|
||||
except ET.ParseError as exc:
|
||||
raise ValueError(f"Failed to parse sitemap XML from {sitemap_url!r}: {exc}") from exc
|
||||
|
||||
tag = root.tag.lower()
|
||||
|
||||
# Sitemap index → recurse into child sitemaps
|
||||
if "sitemapindex" in tag:
|
||||
for sitemap_el in root.iter(f"{{{_SITEMAP_NS}}}sitemap"):
|
||||
loc_el = sitemap_el.find(f"{{{_SITEMAP_NS}}}loc")
|
||||
if loc_el is None or not (loc_el.text or "").strip():
|
||||
continue
|
||||
child_url = loc_el.text.strip()
|
||||
yield from self._iter_sitemap_urls(child_url, depth + 1, _walk)
|
||||
return
|
||||
|
||||
# Standard urlset
|
||||
for url_el in root.iter(f"{{{_SITEMAP_NS}}}url"):
|
||||
loc_el = url_el.find(f"{{{_SITEMAP_NS}}}loc")
|
||||
if loc_el is None or not (loc_el.text or "").strip():
|
||||
continue
|
||||
loc = loc_el.text.strip()
|
||||
|
||||
lastmod: datetime | None = None
|
||||
lastmod_el = url_el.find(f"{{{_SITEMAP_NS}}}lastmod")
|
||||
if lastmod_el is not None and (lastmod_el.text or "").strip():
|
||||
lastmod = self._parse_lastmod(lastmod_el.text.strip())
|
||||
|
||||
yield loc, lastmod
|
||||
|
||||
def _fetch_and_build_document(
|
||||
self,
|
||||
url: str,
|
||||
lastmod: datetime | None,
|
||||
seen: set[str] | None = None,
|
||||
pending_pdfs: list[tuple[str, str]] | None = None,
|
||||
sitemap_domain: str | None = None,
|
||||
parent_url: str | None = None,
|
||||
) -> Document | None:
|
||||
try:
|
||||
self._validate_url(url)
|
||||
raw, content_type = self._fetch_raw(url)
|
||||
except (requests.RequestException, ValueError, OSError) as exc:
|
||||
logger.warning("Failed to fetch page %s: %s", url, exc)
|
||||
return None
|
||||
|
||||
updated_at = lastmod or datetime.now(UTC)
|
||||
|
||||
if "application/pdf" in content_type:
|
||||
if not raw:
|
||||
logger.debug("Empty PDF for %s, skipping", url)
|
||||
return None
|
||||
blob = raw
|
||||
extension = ".pdf"
|
||||
else:
|
||||
if self.follow_pdf_links and seen is not None and pending_pdfs is not None:
|
||||
for pdf_url in self._extract_pdf_links(raw, url):
|
||||
if pdf_url in seen:
|
||||
continue
|
||||
if not self.restrict_pdf_to_domain or urlparse(pdf_url).netloc == sitemap_domain:
|
||||
pending_pdfs.append((pdf_url, url))
|
||||
seen.add(pdf_url)
|
||||
|
||||
try:
|
||||
text = web_html_to_markdown(raw.decode("utf-8", errors="replace")).cleaned_text
|
||||
except Exception as exc: # noqa: BLE001 - third-party extractor, any failure just skips the page
|
||||
logger.warning("Failed to parse page %s: %s", url, exc)
|
||||
return None
|
||||
|
||||
if not text or not text.strip():
|
||||
logger.debug("Empty content for %s, skipping", url)
|
||||
return None
|
||||
|
||||
blob = text.encode("utf-8")
|
||||
extension = ".md"
|
||||
|
||||
return Document(
|
||||
id=self._build_document_id(url),
|
||||
source=DocumentSource.SITEMAP,
|
||||
semantic_identifier=self._url_to_identifier(url),
|
||||
extension=extension,
|
||||
blob=blob,
|
||||
doc_updated_at=updated_at,
|
||||
size_bytes=len(blob),
|
||||
metadata={
|
||||
"sitemap_url": self.sitemap_url,
|
||||
"url": url,
|
||||
**({"parent_url": parent_url} if parent_url else {}),
|
||||
},
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def _extract_pdf_links(html_bytes: bytes, base_url: str) -> list[str]:
|
||||
"""Extract absolute PDF href links from an HTML page."""
|
||||
from html.parser import HTMLParser
|
||||
|
||||
class _Extractor(HTMLParser):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.links: list[str] = []
|
||||
|
||||
def handle_starttag(self, tag, attrs):
|
||||
if tag == "a":
|
||||
href = (dict(attrs).get("href", "") or "").strip()
|
||||
if href:
|
||||
self.links.append(href)
|
||||
|
||||
ex = _Extractor()
|
||||
ex.feed(html_bytes.decode("utf-8", errors="replace"))
|
||||
pdf_links: list[str] = []
|
||||
for href in ex.links:
|
||||
absolute = urljoin(base_url, href)
|
||||
# Match on the path only, so "/manual.pdf?download=1#page=2" counts.
|
||||
if urlparse(absolute).path.lower().endswith(".pdf"):
|
||||
pdf_links.append(absolute)
|
||||
return pdf_links
|
||||
|
||||
def _fetch_raw(self, url: str) -> tuple[bytes, str]:
|
||||
"""Fetch a URL with redirect following, SSRF protection and a response size cap.
|
||||
|
||||
Every hop is validated by ``assert_url_is_safe`` and the resolved address is
|
||||
pinned for the duration of the request (DNS rebinding protection). The body
|
||||
is streamed and rejected once it exceeds ``_MAX_RESPONSE_BYTES``.
|
||||
|
||||
Returns (content, content_type).
|
||||
"""
|
||||
current_url = url
|
||||
current_hostname, current_ip = assert_url_is_safe(current_url)
|
||||
|
||||
response: requests.Response | None = None
|
||||
for _ in range(_MAX_REDIRECTS + 1):
|
||||
with _pin_dns(current_hostname, current_ip):
|
||||
response = self._session.get(
|
||||
current_url,
|
||||
timeout=REQUEST_TIMEOUT_SECONDS,
|
||||
allow_redirects=False,
|
||||
stream=True,
|
||||
headers={"User-Agent": self.user_agent},
|
||||
)
|
||||
if response.status_code not in (301, 302, 303, 307, 308):
|
||||
response.raise_for_status()
|
||||
content_type = response.headers.get("Content-Type", "").lower()
|
||||
return self._read_capped(response, current_url), content_type
|
||||
response.close()
|
||||
location = response.headers.get("Location")
|
||||
if not location:
|
||||
response.raise_for_status()
|
||||
raise ValueError(f"Redirect without Location header fetching {url!r}")
|
||||
redirect_url = urljoin(current_url, location)
|
||||
current_hostname, current_ip = assert_url_is_safe(redirect_url)
|
||||
current_url = redirect_url
|
||||
raise ValueError(f"Exceeded {_MAX_REDIRECTS} redirects fetching {url!r}")
|
||||
|
||||
def _read_capped(self, response: requests.Response, url: str) -> bytes:
|
||||
"""Read a streamed response body, refusing anything larger than _MAX_RESPONSE_BYTES.
|
||||
|
||||
Stops early (raising ``ValueError``) when :meth:`cancel` was called.
|
||||
"""
|
||||
declared = response.headers.get("Content-Length")
|
||||
if declared and declared.isdigit() and int(declared) > _MAX_RESPONSE_BYTES:
|
||||
response.close()
|
||||
raise ValueError(f"Response for {url!r} exceeds the maximum allowed size of {_MAX_RESPONSE_BYTES} bytes")
|
||||
chunks: list[bytes] = []
|
||||
total = 0
|
||||
try:
|
||||
for chunk in response.iter_content(chunk_size=_READ_CHUNK_BYTES):
|
||||
if self._cancel.is_set():
|
||||
raise ValueError(f"Fetch of {url!r} cancelled")
|
||||
if not chunk:
|
||||
continue
|
||||
total += len(chunk)
|
||||
if total > _MAX_RESPONSE_BYTES:
|
||||
raise ValueError(f"Response for {url!r} exceeds the maximum allowed size of {_MAX_RESPONSE_BYTES} bytes")
|
||||
chunks.append(chunk)
|
||||
finally:
|
||||
response.close()
|
||||
return b"".join(chunks)
|
||||
|
||||
@staticmethod
|
||||
def _validate_url(url: str) -> tuple[str, str]:
|
||||
if not url:
|
||||
raise ValueError("URL is required")
|
||||
parsed = urlparse(url)
|
||||
if parsed.scheme not in {"http", "https"} or not parsed.netloc:
|
||||
raise ValueError(f"URL must be a valid http or https URL: {url!r}")
|
||||
return assert_url_is_safe(url)
|
||||
|
||||
def _url_matches(self, url: str) -> bool:
|
||||
if self._url_filter is None:
|
||||
return True
|
||||
try:
|
||||
return bool(self._url_filter.search(url[:_MAX_MATCHED_URL_LENGTH], timeout=_URL_FILTER_TIMEOUT_SECONDS))
|
||||
except TimeoutError:
|
||||
logger.warning("url_filter evaluation timed out after %ss on %s; URL skipped", _URL_FILTER_TIMEOUT_SECONDS, url[:200])
|
||||
return False
|
||||
|
||||
@staticmethod
|
||||
def _url_to_identifier(url: str) -> str:
|
||||
parsed = urlparse(url)
|
||||
identifier = f"{parsed.netloc}{parsed.path}"
|
||||
if parsed.query:
|
||||
identifier += f"?{parsed.query}"
|
||||
if parsed.fragment:
|
||||
identifier += f"#{parsed.fragment}"
|
||||
return identifier.strip("/") or url
|
||||
|
||||
@staticmethod
|
||||
def _build_document_id(url: str) -> str:
|
||||
return f"sitemap:{hashlib.md5(url.encode('utf-8')).hexdigest()}"
|
||||
|
||||
@staticmethod
|
||||
def _parse_lastmod(value: str) -> datetime | None:
|
||||
for fmt in ("%Y-%m-%dT%H:%M:%S.%f%z", "%Y-%m-%dT%H:%M:%S.%fZ", "%Y-%m-%dT%H:%M:%S%z", "%Y-%m-%dT%H:%M:%SZ", "%Y-%m-%d"):
|
||||
try:
|
||||
dt = datetime.strptime(value, fmt) # noqa: DTZ007 - tz set explicitly below
|
||||
if dt.tzinfo is None:
|
||||
dt = dt.replace(tzinfo=UTC)
|
||||
return dt.astimezone(UTC)
|
||||
except ValueError:
|
||||
continue
|
||||
logger.debug("Unrecognised lastmod format: %r", value)
|
||||
return None
|
||||
@@ -24,6 +24,6 @@ RAGFlow supports many data sources. It is recommended to first select a major ca
|
||||
|
||||
**Business systems and tables**: Used to synchronize CRM, tickets, online tables, courses, or operation records. This category is suitable for building business ledgers and service knowledge bases. It includes Salesforce, Airtable, Dingtalk AI Table, Zendesk, and Moodle.
|
||||
|
||||
**General APIs and subscriptions**: Used to connect custom APIs, X search results, or public subscription feeds. This category is suitable for business systems without standard connectors and for collecting public content. It includes REST API, Xquik, and RSS.
|
||||
**General APIs and subscriptions**: Used to connect custom APIs, X search results, or public subscription feeds. This category is suitable for business systems without standard connectors and for collecting public content. It includes REST API, Xquik, RSS, and Sitemap.
|
||||
|
||||
Account version note: In this manual, **Personal Edition** and **Enterprise Edition** refer to the external system account or service version, not the RAGFlow license. Whether synchronization is available ultimately depends on whether the external system allows the current account to access the target content and API.
|
||||
@@ -699,3 +699,26 @@ The RSS data source is used to subscribe public websites, blogs, announcements,
|
||||
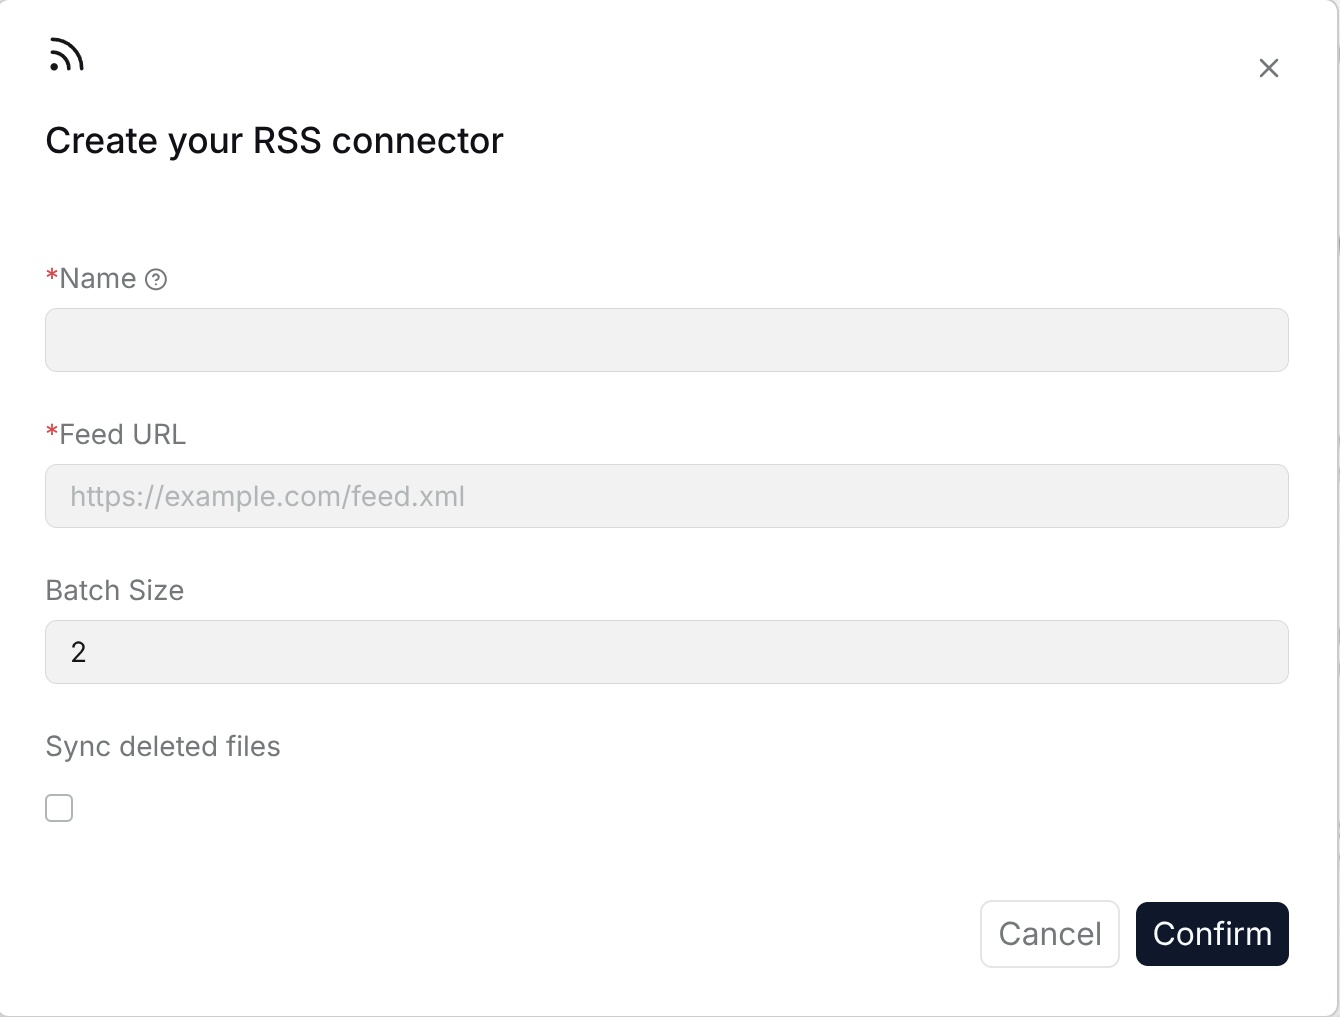
- **Sync deleted files**: After this is enabled, content deleted from the external system is removed from the knowledge base index.
|
||||
|
||||
|
||||
|
||||
## Sitemap
|
||||
|
||||
The Sitemap data source is used to synchronize the web pages listed in a public `sitemap.xml` to a RAGFlow knowledge base. It is the simplest way to index a documentation site, a corporate website, or a blog without writing a crawler: the site itself declares which pages exist and when they were last modified.
|
||||
|
||||
**Permission requirements**: The sitemap and the pages it lists must be reachable over HTTP or HTTPS from the RAGFlow server. No credentials are used. Every request is checked by the SSRF guard, so private or loopback addresses are rejected.
|
||||
|
||||
**Account version requirements**: None. Sitemaps are a public XML standard ([sitemaps.org](https://www.sitemaps.org/protocol.html)); both plain `urlset` files and `sitemapindex` files (followed recursively, up to 5 levels) are supported.
|
||||
|
||||
**Configuration parameters**:
|
||||
|
||||
- **Name**: Customize the name in RAGFlow to identify this Sitemap connection.
|
||||
- **Sitemap URL**: The URL of the `sitemap.xml` or sitemap index to crawl, for example `https://example.com/sitemap.xml`.
|
||||
- **URL filter (regex)**: Optional regular expression. Only URLs matching it are indexed, for example `^https://example\.com/docs/` to restrict the sync to one section of the site. The connection test fails when no URL matches. The pattern is limited to 512 characters, nested quantifiers such as `(a+)+` are refused, and it is evaluated with a 1-second timeout against the first 4,096 characters of each URL.
|
||||
- **Follow PDF links**: When enabled, PDF files linked from the crawled HTML pages are indexed as well. Each PDF is indexed once even when several pages link to it.
|
||||
- **Restrict PDFs to sitemap domain**: When enabled (default), only PDF links hosted on the same domain as the sitemap are followed.
|
||||
- **User-Agent**: The `User-Agent` header sent with every request. Leave empty to use `RAGFlow-SitemapConnector/1.0`. Set it when the target site filters unknown crawlers.
|
||||
- **Batch size**: The number of pages fetched and sent to RAGFlow per batch.
|
||||
- **Sync deleted files**: After this is enabled, pages removed from the sitemap are removed from the knowledge base index.
|
||||
|
||||
Every request goes through the SSRF guard with the resolved address pinned for the duration of the request, response bodies are capped at 64 MB, and at most 1000 sitemap documents are fetched per sync (each sitemap URL once). HTML pages are converted to Markdown with the same boilerplate removal as the other web connectors (`WEB_CONNECTOR_IGNORED_ELEMENTS`: navigation, footer, aside, scripts and styles by default) and stored as `.md` documents. URLs served with `Content-Type: application/pdf` are stored as `.pdf` documents and processed by the regular PDF pipeline. Each document keeps the page URL, the sitemap URL, and, for discovered PDFs, the parent page URL in its metadata.
|
||||
|
||||
Incremental syncs rely on the `<lastmod>` element: only pages whose `lastmod` falls inside the sync window are fetched again, and pages without `lastmod` are only fetched by a full sync. Every document also carries a content fingerprint, so a page that is fetched again but has not changed is skipped instead of being re-indexed.
|
||||
@@ -28,6 +28,7 @@ import (
|
||||
func RegisterBuiltIns(registry *Registry) {
|
||||
registerBuiltIn(registry, "confluence", NewConfluenceConnector)
|
||||
registerBuiltIn(registry, "rss", NewRSSConnector)
|
||||
registerBuiltIn(registry, "sitemap", NewSitemapConnector)
|
||||
registerBuiltIn(registry, "salesforce", NewSalesforceConnector)
|
||||
registerBuiltIn(registry, "bitbucket", NewBitbucketConnector)
|
||||
registerBuiltIn(registry, "azure_devops", NewAzureDevOpsConnector)
|
||||
|
||||
@@ -0,0 +1,765 @@
|
||||
//
|
||||
// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
//
|
||||
|
||||
package connector
|
||||
|
||||
import (
|
||||
"bytes"
|
||||
"context"
|
||||
"crypto/md5"
|
||||
"encoding/hex"
|
||||
"encoding/xml"
|
||||
"fmt"
|
||||
"io"
|
||||
"log/slog"
|
||||
"net/http"
|
||||
"net/url"
|
||||
"regexp"
|
||||
"strings"
|
||||
"time"
|
||||
|
||||
"ragflow/internal/utility"
|
||||
|
||||
md "github.com/JohannesKaufmann/html-to-markdown"
|
||||
"golang.org/x/net/html"
|
||||
)
|
||||
|
||||
const (
|
||||
defaultSitemapBatchSize = 10
|
||||
defaultSitemapUserAgent = "RAGFlow-SitemapConnector/1.0"
|
||||
maxSitemapDepth = 5
|
||||
maxSitemapFetches = 1000
|
||||
maxSitemapRedirects = 10
|
||||
maxSitemapFileSize = 64 * 1024 * 1024
|
||||
sitemapFetchTimeout = 60 * time.Second
|
||||
)
|
||||
|
||||
// sitemapFetchFunc downloads one URL and returns its body and Content-Type.
|
||||
type sitemapFetchFunc func(ctx context.Context, rawURL string) ([]byte, string, error)
|
||||
|
||||
// sitemapAssertURLSafe is the SSRF guard, indirected so tests can stub DNS resolution.
|
||||
var sitemapAssertURLSafe = utility.AssertURLSafe
|
||||
|
||||
// SitemapConnector ingests the web pages listed in a sitemap.xml.
|
||||
//
|
||||
// It supports plain urlset sitemaps and sitemapindex files (recursively, up to
|
||||
// maxSitemapDepth levels), incremental polling via <lastmod>, HTML to Markdown
|
||||
// extraction, PDF documents served directly, and optional discovery of PDF
|
||||
// links inside HTML pages. Sitemaps are a public XML standard (sitemaps.org),
|
||||
// so there is no vendor SDK: every request is a plain HTTP GET guarded by the
|
||||
// shared SSRF checks.
|
||||
type SitemapConnector struct {
|
||||
sitemapURL string
|
||||
batchSize int
|
||||
userAgent string
|
||||
urlFilter *regexp.Regexp
|
||||
followPDFLinks bool
|
||||
restrictPDFToDomain bool
|
||||
|
||||
fetch sitemapFetchFunc
|
||||
}
|
||||
|
||||
// NewSitemapConnector creates a sitemap connector from Python-compatible config.
|
||||
func NewSitemapConnector(config map[string]any) (*SitemapConnector, error) {
|
||||
sitemapURL := strings.TrimSpace(stringConfig(config["sitemap_url"]))
|
||||
userAgent := strings.TrimSpace(stringConfig(config["user_agent"]))
|
||||
if userAgent == "" {
|
||||
userAgent = defaultSitemapUserAgent
|
||||
}
|
||||
|
||||
var urlFilter *regexp.Regexp
|
||||
if pattern := strings.TrimSpace(stringConfig(config["url_filter"])); pattern != "" {
|
||||
compiled, err := regexp.Compile(pattern)
|
||||
if err != nil {
|
||||
return nil, fmt.Errorf("url_filter is not a valid regex: %w", err)
|
||||
}
|
||||
urlFilter = compiled
|
||||
}
|
||||
|
||||
connector := &SitemapConnector{
|
||||
sitemapURL: sitemapURL,
|
||||
batchSize: configInt(config["batch_size"], defaultSitemapBatchSize),
|
||||
userAgent: userAgent,
|
||||
urlFilter: urlFilter,
|
||||
followPDFLinks: configBoolDefault(config["follow_pdf_links"], false),
|
||||
restrictPDFToDomain: configBoolDefault(config["restrict_pdf_to_domain"], true),
|
||||
}
|
||||
connector.fetch = connector.fetchRemote
|
||||
return connector, nil
|
||||
}
|
||||
|
||||
// Validate validates sitemap settings and checks that the sitemap lists at
|
||||
// least one URL accepted by the filter.
|
||||
func (c *SitemapConnector) Validate(ctx context.Context) error {
|
||||
if c == nil {
|
||||
return fmt.Errorf("sitemap connector is nil")
|
||||
}
|
||||
if c.sitemapURL == "" {
|
||||
return fmt.Errorf("sitemap URL is required")
|
||||
}
|
||||
if err := validateSitemapURL(c.sitemapURL); err != nil {
|
||||
return err
|
||||
}
|
||||
if c.batchSize <= 0 {
|
||||
return fmt.Errorf("batch_size must be a positive integer")
|
||||
}
|
||||
|
||||
entries, err := c.listEntries(ctx)
|
||||
if err != nil {
|
||||
return err
|
||||
}
|
||||
for _, entry := range entries {
|
||||
if c.urlMatches(entry.loc) {
|
||||
return nil
|
||||
}
|
||||
}
|
||||
return fmt.Errorf("sitemap contains no URLs matching the filter")
|
||||
}
|
||||
|
||||
// ValidateConnectorSetting validates sitemap settings from an unsaved config.
|
||||
func (c *SitemapConnector) ValidateConnectorSetting(ctx context.Context, request map[string]any) error {
|
||||
ctx, cancel := context.WithTimeout(ctx, connectorSettingValidationTimeout)
|
||||
defer cancel()
|
||||
return c.Validate(ctx)
|
||||
}
|
||||
|
||||
// OpenSync opens one sitemap sync session.
|
||||
//
|
||||
// Page bodies are fetched lazily, batch by batch, inside NextBatch so that a
|
||||
// large sitemap never has to be materialized in memory. Documents carry a
|
||||
// content fingerprint, so unchanged pages are skipped by the runner before
|
||||
// being re-indexed even when the sitemap exposes no usable <lastmod>.
|
||||
func (c *SitemapConnector) OpenSync(ctx context.Context, request SyncRequest) (SyncSession, error) {
|
||||
entries, err := c.listEntries(ctx)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
incremental := !request.FromBeginning && request.WindowStart != nil
|
||||
pending := make([]sitemapEntry, 0, len(entries))
|
||||
for _, entry := range entries {
|
||||
if incremental {
|
||||
// Pages without <lastmod> cannot be attributed to a window; they are
|
||||
// only picked up by a full sync, exactly like the Python connector.
|
||||
if entry.lastmod.IsZero() {
|
||||
continue
|
||||
}
|
||||
if beforeOrAtWindowStart(entry.lastmod, request.WindowStart) || afterWindowEnd(entry.lastmod, request.WindowEnd) {
|
||||
continue
|
||||
}
|
||||
}
|
||||
pending = append(pending, entry)
|
||||
}
|
||||
|
||||
session := &sitemapSyncSession{
|
||||
connector: c,
|
||||
pending: pending,
|
||||
seen: make(map[string]struct{}, len(entries)),
|
||||
}
|
||||
for _, entry := range entries {
|
||||
session.seen[entry.loc] = struct{}{}
|
||||
}
|
||||
if err := session.applyResume(request.Resume); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
return session, nil
|
||||
}
|
||||
|
||||
// OpenPrune opens one complete sitemap prune snapshot session.
|
||||
//
|
||||
// When PDF link discovery is enabled the HTML pages are fetched so that the
|
||||
// discovered PDFs are part of the retained set; otherwise they would be pruned
|
||||
// as stale right after being indexed.
|
||||
func (c *SitemapConnector) OpenPrune(ctx context.Context, request PruneRequest) (PruneSession, error) {
|
||||
entries, err := c.listEntries(ctx)
|
||||
if err != nil {
|
||||
return nil, err
|
||||
}
|
||||
|
||||
documents := make([]SlimDocument, 0, len(entries))
|
||||
seen := make(map[string]struct{}, len(entries))
|
||||
for _, entry := range entries {
|
||||
seen[entry.loc] = struct{}{}
|
||||
if !c.urlMatches(entry.loc) {
|
||||
continue
|
||||
}
|
||||
documents = append(documents, SlimDocument{SourceID: sitemapSourceID(entry.loc)})
|
||||
}
|
||||
|
||||
if c.followPDFLinks {
|
||||
for _, entry := range entries {
|
||||
if !c.urlMatches(entry.loc) {
|
||||
continue
|
||||
}
|
||||
body, contentType, err := c.fetch(ctx, entry.loc)
|
||||
if err != nil {
|
||||
slog.Warn("sitemap prune: failed to fetch page for PDF discovery", "url", entry.loc, "error", err)
|
||||
continue
|
||||
}
|
||||
if isPDFResponse(contentType, body) {
|
||||
continue
|
||||
}
|
||||
for _, pdfURL := range c.discoverPDFLinks(body, entry.loc) {
|
||||
if _, exists := seen[pdfURL]; exists {
|
||||
continue
|
||||
}
|
||||
seen[pdfURL] = struct{}{}
|
||||
documents = append(documents, SlimDocument{SourceID: sitemapSourceID(pdfURL)})
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
return &sitemapPruneSession{documents: documents, batchSize: c.batchSize}, nil
|
||||
}
|
||||
|
||||
// listEntries walks the sitemap (and nested sitemap indexes) and returns the
|
||||
// deduplicated entries in document order. url_filter is applied by callers.
|
||||
//
|
||||
// Every sitemap URL is fetched at most once (a sitemapindex that references
|
||||
// itself or an ancestor is skipped) and the walk stops after maxSitemapFetches
|
||||
// sitemap documents, so one connector configuration cannot trigger unbounded
|
||||
// egress.
|
||||
func (c *SitemapConnector) listEntries(ctx context.Context) ([]sitemapEntry, error) {
|
||||
var (
|
||||
entries []sitemapEntry
|
||||
seen = make(map[string]struct{})
|
||||
visited = make(map[string]struct{})
|
||||
fetched int
|
||||
)
|
||||
var walk func(sitemapURL string, depth int) error
|
||||
walk = func(sitemapURL string, depth int) error {
|
||||
if depth > maxSitemapDepth {
|
||||
slog.Warn("sitemap: max depth reached, stopping", "url", sitemapURL)
|
||||
return nil
|
||||
}
|
||||
if _, done := visited[sitemapURL]; done {
|
||||
slog.Warn("sitemap: nested sitemap already visited, skipping", "url", sitemapURL)
|
||||
return nil
|
||||
}
|
||||
visited[sitemapURL] = struct{}{}
|
||||
if fetched >= maxSitemapFetches {
|
||||
slog.Warn("sitemap: maximum number of sitemap fetches reached, stopping", "url", sitemapURL, "max", maxSitemapFetches)
|
||||
return nil
|
||||
}
|
||||
if err := validateSitemapURL(sitemapURL); err != nil {
|
||||
if depth == 0 {
|
||||
return err
|
||||
}
|
||||
slog.Warn("sitemap: skipping invalid nested sitemap URL", "url", sitemapURL, "error", err)
|
||||
return nil
|
||||
}
|
||||
body, _, err := c.fetch(ctx, sitemapURL)
|
||||
if err != nil {
|
||||
if depth == 0 {
|
||||
return fmt.Errorf("failed to fetch sitemap %s: %w", sitemapURL, err)
|
||||
}
|
||||
slog.Warn("sitemap: failed to fetch nested sitemap", "url", sitemapURL, "error", err)
|
||||
return nil
|
||||
}
|
||||
fetched++
|
||||
|
||||
document, err := parseSitemapXML(body)
|
||||
if err != nil {
|
||||
return fmt.Errorf("failed to parse sitemap XML from %s: %w", sitemapURL, err)
|
||||
}
|
||||
if document.isIndex {
|
||||
for _, child := range document.sitemaps {
|
||||
if err := walk(child, depth+1); err != nil {
|
||||
return err
|
||||
}
|
||||
}
|
||||
return nil
|
||||
}
|
||||
for _, entry := range document.entries {
|
||||
if _, exists := seen[entry.loc]; exists {
|
||||
continue
|
||||
}
|
||||
seen[entry.loc] = struct{}{}
|
||||
entries = append(entries, entry)
|
||||
}
|
||||
return nil
|
||||
}
|
||||
if err := walk(c.sitemapURL, 0); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
if fetched == 0 {
|
||||
return nil, fmt.Errorf("failed to fetch sitemap %s", c.sitemapURL)
|
||||
}
|
||||
return entries, nil
|
||||
}
|
||||
|
||||
// urlMatches reports whether a URL passes the optional url_filter regex.
|
||||
func (c *SitemapConnector) urlMatches(rawURL string) bool {
|
||||
return c.urlFilter == nil || c.urlFilter.MatchString(rawURL)
|
||||
}
|
||||
|
||||
// buildDocument downloads one URL and converts it into a source document.
|
||||
// It returns nil when the page must be skipped (fetch error or empty content).
|
||||
func (c *SitemapConnector) buildDocument(ctx context.Context, rawURL string, lastmod time.Time, parentURL string) (*SourceDocument, []string) {
|
||||
if err := validateSitemapURL(rawURL); err != nil {
|
||||
slog.Warn("sitemap: skipping invalid page URL", "url", rawURL, "error", err)
|
||||
return nil, nil
|
||||
}
|
||||
body, contentType, err := c.fetch(ctx, rawURL)
|
||||
if err != nil {
|
||||
slog.Warn("sitemap: failed to fetch page", "url", rawURL, "error", err)
|
||||
return nil, nil
|
||||
}
|
||||
|
||||
updatedAt := lastmod
|
||||
if updatedAt.IsZero() {
|
||||
updatedAt = time.Now().UTC()
|
||||
}
|
||||
|
||||
var (
|
||||
blob []byte
|
||||
extension string
|
||||
pdfLinks []string
|
||||
)
|
||||
if isPDFResponse(contentType, body) {
|
||||
if len(body) == 0 {
|
||||
slog.Debug("sitemap: empty PDF, skipping", "url", rawURL)
|
||||
return nil, nil
|
||||
}
|
||||
blob = body
|
||||
extension = ".pdf"
|
||||
} else {
|
||||
if c.followPDFLinks {
|
||||
pdfLinks = c.discoverPDFLinks(body, rawURL)
|
||||
}
|
||||
text, err := sitemapHTMLToMarkdown(body)
|
||||
if err != nil {
|
||||
slog.Warn("sitemap: failed to parse page", "url", rawURL, "error", err)
|
||||
return nil, pdfLinks
|
||||
}
|
||||
if strings.TrimSpace(text) == "" {
|
||||
slog.Debug("sitemap: empty content, skipping", "url", rawURL)
|
||||
return nil, pdfLinks
|
||||
}
|
||||
blob = []byte(text)
|
||||
extension = ".md"
|
||||
}
|
||||
|
||||
metadata := map[string]any{
|
||||
"sitemap_url": c.sitemapURL,
|
||||
"url": rawURL,
|
||||
}
|
||||
if parentURL != "" {
|
||||
metadata["parent_url"] = parentURL
|
||||
}
|
||||
return &SourceDocument{
|
||||
SourceID: sitemapSourceID(rawURL),
|
||||
SemanticIdentifier: sitemapSemanticIdentifier(rawURL),
|
||||
Extension: extension,
|
||||
Blob: blob,
|
||||
UpdatedAt: updatedAt,
|
||||
SizeBytes: int64(len(blob)),
|
||||
Metadata: metadata,
|
||||
Fingerprint: contentFingerprint(blob),
|
||||
}, pdfLinks
|
||||
}
|
||||
|
||||
// discoverPDFLinks returns the absolute PDF links found in an HTML page that
|
||||
// pass the optional same-domain restriction.
|
||||
func (c *SitemapConnector) discoverPDFLinks(body []byte, pageURL string) []string {
|
||||
links := extractPDFLinks(body, pageURL)
|
||||
if !c.restrictPDFToDomain {
|
||||
return links
|
||||
}
|
||||
sitemapHost := hostOf(c.sitemapURL)
|
||||
filtered := links[:0]
|
||||
for _, link := range links {
|
||||
if hostOf(link) == sitemapHost {
|
||||
filtered = append(filtered, link)
|
||||
}
|
||||
}
|
||||
return filtered
|
||||
}
|
||||
|
||||
// fetchRemote downloads rawURL with SSRF protection, manual redirect handling
|
||||
// that re-validates every hop, the configured User-Agent, and a hard size cap.
|
||||
func (c *SitemapConnector) fetchRemote(ctx context.Context, rawURL string) ([]byte, string, error) {
|
||||
currentURL := rawURL
|
||||
for redirects := 0; redirects <= maxSitemapRedirects; redirects++ {
|
||||
hostname, resolvedIP, err := sitemapAssertURLSafe(currentURL)
|
||||
if err != nil {
|
||||
return nil, "", err
|
||||
}
|
||||
client := utility.PinnedHTTPClient(hostname, resolvedIP, sitemapFetchTimeout)
|
||||
client.CheckRedirect = func(req *http.Request, via []*http.Request) error {
|
||||
return http.ErrUseLastResponse
|
||||
}
|
||||
|
||||
req, err := http.NewRequestWithContext(ctx, http.MethodGet, currentURL, nil)
|
||||
if err != nil {
|
||||
return nil, "", fmt.Errorf("failed to create request: %w", err)
|
||||
}
|
||||
req.Header.Set("User-Agent", c.userAgent)
|
||||
resp, err := client.Do(req) // `#nosec` G107
|
||||
if err != nil {
|
||||
return nil, "", fmt.Errorf("failed to fetch URL: %w", err)
|
||||
}
|
||||
|
||||
switch resp.StatusCode {
|
||||
case http.StatusMovedPermanently, http.StatusFound, http.StatusSeeOther, http.StatusTemporaryRedirect, http.StatusPermanentRedirect:
|
||||
location := resp.Header.Get("Location")
|
||||
resp.Body.Close()
|
||||
if location == "" {
|
||||
return nil, "", fmt.Errorf("redirect response missing Location header")
|
||||
}
|
||||
base, parseErr := url.Parse(currentURL)
|
||||
if parseErr != nil {
|
||||
return nil, "", parseErr
|
||||
}
|
||||
next, resolveErr := base.Parse(location)
|
||||
if resolveErr != nil {
|
||||
return nil, "", resolveErr
|
||||
}
|
||||
currentURL = next.String()
|
||||
continue
|
||||
}
|
||||
|
||||
if resp.StatusCode >= 400 {
|
||||
resp.Body.Close()
|
||||
return nil, "", fmt.Errorf("remote URL returned HTTP %d", resp.StatusCode)
|
||||
}
|
||||
data, readErr := io.ReadAll(io.LimitReader(resp.Body, maxSitemapFileSize+1))
|
||||
contentType := strings.ToLower(resp.Header.Get("Content-Type"))
|
||||
resp.Body.Close()
|
||||
if readErr != nil {
|
||||
return nil, "", fmt.Errorf("failed to read remote content: %w", readErr)
|
||||
}
|
||||
if int64(len(data)) > maxSitemapFileSize {
|
||||
return nil, "", fmt.Errorf("remote file exceeds the maximum allowed size of %d bytes", maxSitemapFileSize)
|
||||
}
|
||||
return data, contentType, nil
|
||||
}
|
||||
return nil, "", fmt.Errorf("exceeded %d redirects fetching %s", maxSitemapRedirects, rawURL)
|
||||
}
|
||||
|
||||
// sitemapSyncSession streams sitemap pages and then the PDFs discovered in them.
|
||||
type sitemapSyncSession struct {
|
||||
connector *SitemapConnector
|
||||
|
||||
pending []sitemapEntry // sitemap URLs still to fetch
|
||||
index int
|
||||
|
||||
seen map[string]struct{}
|
||||
pendingPDFs []sitemapPDFLink // discovered PDFs, emitted after the sitemap pass
|
||||
pdfIndex int
|
||||
}
|
||||
|
||||
// sitemapPDFLink is a PDF discovered inside an HTML page.
|
||||
type sitemapPDFLink struct {
|
||||
url string
|
||||
parentURL string
|
||||
}
|
||||
|
||||
// NextBatch fetches and returns the next batch of documents.
|
||||
func (s *sitemapSyncSession) NextBatch(ctx context.Context) (SyncBatch, error) {
|
||||
batchSize := s.connector.batchSize
|
||||
documents := make([]SourceDocument, 0, batchSize)
|
||||
|
||||
for s.index < len(s.pending) && len(documents) < batchSize {
|
||||
if err := ctx.Err(); err != nil {
|
||||
return SyncBatch{}, err
|
||||
}
|
||||
entry := s.pending[s.index]
|
||||
s.index++
|
||||
if !s.connector.urlMatches(entry.loc) {
|
||||
continue
|
||||
}
|
||||
doc, pdfLinks := s.connector.buildDocument(ctx, entry.loc, entry.lastmod, "")
|
||||
for _, pdfURL := range pdfLinks {
|
||||
if _, exists := s.seen[pdfURL]; exists {
|
||||
continue
|
||||
}
|
||||
s.seen[pdfURL] = struct{}{}
|
||||
s.pendingPDFs = append(s.pendingPDFs, sitemapPDFLink{url: pdfURL, parentURL: entry.loc})
|
||||
}
|
||||
if doc != nil {
|
||||
documents = append(documents, *doc)
|
||||
}
|
||||
}
|
||||
|
||||
if len(documents) == 0 {
|
||||
for s.pdfIndex < len(s.pendingPDFs) && len(documents) < batchSize {
|
||||
if err := ctx.Err(); err != nil {
|
||||
return SyncBatch{}, err
|
||||
}
|
||||
link := s.pendingPDFs[s.pdfIndex]
|
||||
s.pdfIndex++
|
||||
doc, _ := s.connector.buildDocument(ctx, link.url, time.Time{}, link.parentURL)
|
||||
if doc != nil {
|
||||
documents = append(documents, *doc)
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
if len(documents) == 0 {
|
||||
return SyncBatch{}, io.EOF
|
||||
}
|
||||
return SyncBatch{Documents: documents, Checkpoint: sitemapSyncCheckpoint(documents[len(documents)-1])}, nil
|
||||
}
|
||||
|
||||
// Close closes the sitemap sync session.
|
||||
func (s *sitemapSyncSession) Close() error {
|
||||
return nil
|
||||
}
|
||||
|
||||
// applyResume advances past the last committed sitemap page when retrying a task.
|
||||
//
|
||||
// Only sitemap-listed URLs can anchor a resume: PDFs discovered inside pages are
|
||||
// not known before those pages are fetched, so a checkpoint taken during the
|
||||
// PDF pass anchors on the last sitemap page instead and the PDF pass replays.
|
||||
func (s *sitemapSyncSession) applyResume(checkpoint *SyncCheckpoint) error {
|
||||
if checkpoint == nil {
|
||||
return nil
|
||||
}
|
||||
sourceID := firstNonEmpty(checkpoint.SourceID, checkpoint.Cursor)
|
||||
if sourceID == "" {
|
||||
return fmt.Errorf("sitemap sync checkpoint has no source anchor: %w", ErrSyncResumeInvalid)
|
||||
}
|
||||
for index, entry := range s.pending {
|
||||
if sitemapSourceID(entry.loc) == sourceID {
|
||||
s.index = index + 1
|
||||
return nil
|
||||
}
|
||||
}
|
||||
return fmt.Errorf("sitemap resume anchor %q was not found in the current sitemap: %w", sourceID, ErrSyncResumeInvalid)
|
||||
}
|
||||
|
||||
// sitemapSyncCheckpoint returns a resume point after a committed document.
|
||||
func sitemapSyncCheckpoint(doc SourceDocument) *SyncCheckpoint {
|
||||
// Discovered PDFs carry parent_url; anchor on the parent page so the
|
||||
// checkpoint always points at a sitemap-listed URL.
|
||||
anchor := doc.SourceID
|
||||
if parent, ok := doc.Metadata["parent_url"].(string); ok && parent != "" {
|
||||
anchor = sitemapSourceID(parent)
|
||||
}
|
||||
updatedAt := doc.UpdatedAt
|
||||
return &SyncCheckpoint{
|
||||
Cursor: anchor,
|
||||
SourceID: anchor,
|
||||
UpdatedAt: &updatedAt,
|
||||
}
|
||||
}
|
||||
|
||||
type sitemapPruneSession struct {
|
||||
documents []SlimDocument
|
||||
batchSize int
|
||||
index int
|
||||
}
|
||||
|
||||
// NextBatch returns the next sitemap prune snapshot batch.
|
||||
func (s *sitemapPruneSession) NextBatch(ctx context.Context) (PruneBatch, error) {
|
||||
if s.index >= len(s.documents) {
|
||||
return PruneBatch{}, io.EOF
|
||||
}
|
||||
end := s.index + s.batchSize
|
||||
if end > len(s.documents) {
|
||||
end = len(s.documents)
|
||||
}
|
||||
batch := PruneBatch{Documents: s.documents[s.index:end]}
|
||||
s.index = end
|
||||
return batch, nil
|
||||
}
|
||||
|
||||
// Close closes the sitemap prune session.
|
||||
func (s *sitemapPruneSession) Close() error {
|
||||
return nil
|
||||
}
|
||||
|
||||
// sitemapEntry is one <url> element of a urlset.
|
||||
type sitemapEntry struct {
|
||||
loc string
|
||||
lastmod time.Time
|
||||
}
|
||||
|
||||
// sitemapDocument is a parsed sitemap or sitemap index.
|
||||
type sitemapDocument struct {
|
||||
isIndex bool
|
||||
sitemaps []string
|
||||
entries []sitemapEntry
|
||||
}
|
||||
|
||||
type sitemapXMLRoot struct {
|
||||
XMLName xml.Name
|
||||
Sitemaps []sitemapXMLLoc `xml:"sitemap"`
|
||||
URLs []sitemapXMLURL `xml:"url"`
|
||||
}
|
||||
|
||||
type sitemapXMLLoc struct {
|
||||
Loc string `xml:"loc"`
|
||||
}
|
||||
|
||||
type sitemapXMLURL struct {
|
||||
Loc string `xml:"loc"`
|
||||
Lastmod string `xml:"lastmod"`
|
||||
}
|
||||
|
||||
// parseSitemapXML parses a urlset or sitemapindex payload.
|
||||
func parseSitemapXML(data []byte) (*sitemapDocument, error) {
|
||||
var root sitemapXMLRoot
|
||||
decoder := xml.NewDecoder(bytes.NewReader(data))
|
||||
decoder.Strict = false
|
||||
if err := decoder.Decode(&root); err != nil {
|
||||
return nil, err
|
||||
}
|
||||
document := &sitemapDocument{}
|
||||
switch strings.ToLower(root.XMLName.Local) {
|
||||
case "sitemapindex":
|
||||
document.isIndex = true
|
||||
for _, item := range root.Sitemaps {
|
||||
if loc := strings.TrimSpace(item.Loc); loc != "" {
|
||||
document.sitemaps = append(document.sitemaps, loc)
|
||||
}
|
||||
}
|
||||
case "urlset":
|
||||
for _, item := range root.URLs {
|
||||
loc := strings.TrimSpace(item.Loc)
|
||||
if loc == "" {
|
||||
continue
|
||||
}
|
||||
document.entries = append(document.entries, sitemapEntry{loc: loc, lastmod: parseSitemapLastmod(item.Lastmod)})
|
||||
}
|
||||
default:
|
||||
return nil, fmt.Errorf("unexpected root element <%s>", root.XMLName.Local)
|
||||
}
|
||||
return document, nil
|
||||
}
|
||||
|
||||
// parseSitemapLastmod parses W3C Datetime values used by <lastmod>.
|
||||
func parseSitemapLastmod(value string) time.Time {
|
||||
value = strings.TrimSpace(value)
|
||||
if value == "" {
|
||||
return time.Time{}
|
||||
}
|
||||
layouts := []string{
|
||||
time.RFC3339Nano,
|
||||
time.RFC3339,
|
||||
"2006-01-02T15:04:05.999999999",
|
||||
"2006-01-02T15:04:05",
|
||||
"2006-01-02T15:04Z07:00",
|
||||
"2006-01-02T15:04",
|
||||
"2006-01-02",
|
||||
}
|
||||
for _, layout := range layouts {
|
||||
if parsed, err := time.Parse(layout, value); err == nil {
|
||||
return parsed.UTC()
|
||||
}
|
||||
}
|
||||
slog.Debug("sitemap: unrecognised lastmod format", "value", value)
|
||||
return time.Time{}
|
||||
}
|
||||
|
||||
// validateSitemapURL checks scheme/host shape and the SSRF guard.
|
||||
func validateSitemapURL(rawURL string) error {
|
||||
if rawURL == "" {
|
||||
return fmt.Errorf("URL is required")
|
||||
}
|
||||
parsed, err := url.Parse(rawURL)
|
||||
if err != nil || parsed.Host == "" || (parsed.Scheme != "http" && parsed.Scheme != "https") {
|
||||
return fmt.Errorf("URL must be a valid http or https URL: %q", rawURL)
|
||||
}
|
||||
if _, _, err := sitemapAssertURLSafe(rawURL); err != nil {
|
||||
return err
|
||||
}
|
||||
return nil
|
||||
}
|
||||
|
||||
// isPDFResponse reports whether a response is a PDF by Content-Type or magic bytes.
|
||||
func isPDFResponse(contentType string, body []byte) bool {
|
||||
return strings.Contains(strings.ToLower(contentType), "application/pdf") || utility.BytesLooksLikePDF(body)
|
||||
}
|
||||
|
||||
// sitemapSourceID returns the Python-compatible sitemap document ID.
|
||||
func sitemapSourceID(rawURL string) string {
|
||||
sum := md5.Sum([]byte(rawURL))
|
||||
return "sitemap:" + hex.EncodeToString(sum[:])
|
||||
}
|
||||
|
||||
// sitemapSemanticIdentifier strips the scheme so the name is a valid storage key.
|
||||
func sitemapSemanticIdentifier(rawURL string) string {
|
||||
parsed, err := url.Parse(rawURL)
|
||||
if err != nil {
|
||||
return rawURL
|
||||
}
|
||||
identifier := parsed.Host + parsed.Path
|
||||
if parsed.RawQuery != "" {
|
||||
identifier += "?" + parsed.RawQuery
|
||||
}
|
||||
if parsed.Fragment != "" {
|
||||
identifier += "#" + parsed.Fragment
|
||||
}
|
||||
identifier = strings.Trim(identifier, "/")
|
||||
if identifier == "" {
|
||||
return rawURL
|
||||
}
|
||||
return identifier
|
||||
}
|
||||
|
||||
// hostOf returns the lower-cased host of a URL, or "" when unparsable.
|
||||
func hostOf(rawURL string) string {
|
||||
parsed, err := url.Parse(rawURL)
|
||||
if err != nil {
|
||||
return ""
|
||||
}
|
||||
return strings.ToLower(parsed.Host)
|
||||
}
|
||||
|
||||
// sitemapHTMLToMarkdown converts a page to Markdown, dropping navigation chrome.
|
||||
func sitemapHTMLToMarkdown(body []byte) (string, error) {
|
||||
converter := md.NewConverter("", true, &md.Options{EmDelimiter: "*"})
|
||||
converter.Remove("script", "style", "noscript", "nav", "header", "footer", "aside", "form", "iframe", "svg")
|
||||
out, err := converter.ConvertString(string(body))
|
||||
if err != nil {
|
||||
return "", err
|
||||
}
|
||||
return strings.TrimSpace(out), nil
|
||||
}
|
||||
|
||||
// extractPDFLinks returns absolute <a href> links whose path ends in .pdf
|
||||
// (query strings and fragments are ignored, so "/manual.pdf?download=1" counts).
|
||||
func extractPDFLinks(body []byte, pageURL string) []string {
|
||||
base, err := url.Parse(pageURL)
|
||||
if err != nil {
|
||||
return nil
|
||||
}
|
||||
var links []string
|
||||
tokenizer := html.NewTokenizer(bytes.NewReader(body))
|
||||
for {
|
||||
switch tokenizer.Next() {
|
||||
case html.ErrorToken:
|
||||
return links
|
||||
case html.StartTagToken, html.SelfClosingTagToken:
|
||||
token := tokenizer.Token()
|
||||
if token.Data != "a" {
|
||||
continue
|
||||
}
|
||||
for _, attr := range token.Attr {
|
||||
if attr.Key != "href" {
|
||||
continue
|
||||
}
|
||||
resolved, err := base.Parse(strings.TrimSpace(attr.Val))
|
||||
if err != nil || !strings.HasSuffix(strings.ToLower(resolved.Path), ".pdf") {
|
||||
continue
|
||||
}
|
||||
links = append(links, resolved.String())
|
||||
}
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,454 @@
|
||||
//
|
||||
// Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
|
||||
//
|
||||
// Licensed under the Apache License, Version 2.0 (the "License");
|
||||
// you may not use this file except in compliance with the License.
|
||||
// You may obtain a copy of the License at
|
||||
//
|
||||
// http://www.apache.org/licenses/LICENSE-2.0
|
||||
//
|
||||
// Unless required by applicable law or agreed to in writing, software
|
||||
// distributed under the License is distributed on an "AS IS" BASIS,
|
||||
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
// See the License for the specific language governing permissions and
|
||||
// limitations under the License.
|
||||
//
|
||||
|
||||
package connector
|
||||
|
||||
import (
|
||||
"context"
|
||||
"crypto/md5"
|
||||
"encoding/hex"
|
||||
"errors"
|
||||
"fmt"
|
||||
"io"
|
||||
"strings"
|
||||
"testing"
|
||||
)
|
||||
|
||||
// sitemapFixture is an in-memory site: URL -> (Content-Type, body).
|
||||
type sitemapFixture map[string][2]string
|
||||
|
||||
func (f sitemapFixture) fetch(ctx context.Context, rawURL string) ([]byte, string, error) {
|
||||
entry, ok := f[rawURL]
|
||||
if !ok {
|
||||
return nil, "", fmt.Errorf("not found: %s", rawURL)
|
||||
}
|
||||
return []byte(entry[1]), entry[0], nil
|
||||
}
|
||||
|
||||
const sitemapTestIndex = `<?xml version="1.0" encoding="UTF-8"?>
|
||||
<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
|
||||
<sitemap><loc>https://example.com/sitemap-pages.xml</loc></sitemap>
|
||||
<sitemap><loc>https://example.com/sitemap-missing.xml</loc></sitemap>
|
||||
<sitemap><loc>https://example.com/sitemap.xml</loc></sitemap>
|
||||
<sitemap><loc>https://example.com/sitemap-pages.xml</loc></sitemap>
|
||||
</sitemapindex>`
|
||||
|
||||
const sitemapTestURLSet = `<?xml version="1.0" encoding="UTF-8"?>
|
||||
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
|
||||
<url><loc>https://example.com/old</loc><lastmod>2026-01-01</lastmod></url>
|
||||
<url><loc>https://example.com/new</loc><lastmod>2026-01-03T10:00:00.123Z</lastmod></url>
|
||||
<url><loc>https://example.com/future</loc><lastmod>2026-01-06T00:00:00+00:00</lastmod></url>
|
||||
<url><loc>https://example.com/undated</loc></url>
|
||||
<url><loc>https://example.com/brochure.pdf</loc><lastmod>2026-01-02</lastmod></url>
|
||||
<url><loc>https://example.com/new</loc></url>
|
||||
</urlset>`
|
||||
|
||||
func newSitemapTestConnector(t *testing.T, config map[string]any, fixture sitemapFixture) *SitemapConnector {
|
||||
t.Helper()
|
||||
restore := sitemapAssertURLSafe
|
||||
sitemapAssertURLSafe = func(rawURL string) (string, string, error) { return "example.com", "203.0.113.10", nil }
|
||||
t.Cleanup(func() { sitemapAssertURLSafe = restore })
|
||||
|
||||
if _, ok := config["sitemap_url"]; !ok {
|
||||
config["sitemap_url"] = "https://example.com/sitemap.xml"
|
||||
}
|
||||
connector, err := NewSitemapConnector(config)
|
||||
if err != nil {
|
||||
t.Fatalf("NewSitemapConnector failed: %v", err)
|
||||
}
|
||||
connector.fetch = fixture.fetch
|
||||
return connector
|
||||
}
|
||||
|
||||
func defaultSitemapFixture() sitemapFixture {
|
||||
return sitemapFixture{
|
||||
"https://example.com/sitemap.xml": {"application/xml", sitemapTestIndex},
|
||||
"https://example.com/sitemap-pages.xml": {"application/xml", sitemapTestURLSet},
|
||||
"https://example.com/old": {"text/html; charset=utf-8", `<html><head><title>Old</title></head><body><nav><a href="/">Home</a></nav><main><h1>Old page</h1><p>Old body</p></main><footer>Footer</footer></body></html>`},
|
||||
"https://example.com/new": {"text/html", `<html><body><main><h1>New page</h1><p>New body with <a href="/docs/guide.pdf">a guide</a> and <a href="https://cdn.other.org/ext.pdf">an external one</a> and <a href="/docs/manual.pdf?download=1#page=2">a download link</a>.</p></main></body></html>`},
|
||||
"https://example.com/future": {"text/html", `<html><body><p>Future body</p></body></html>`},
|
||||
"https://example.com/undated": {"text/html", `<html><body><p>Undated body</p></body></html>`},
|
||||
"https://example.com/brochure.pdf": {"application/pdf", "%PDF-1.4 brochure"},
|
||||
"https://example.com/docs/guide.pdf": {"application/octet-stream", "%PDF-1.7 guide"},
|
||||
"https://cdn.other.org/ext.pdf": {"application/pdf", "%PDF-1.7 external"},
|
||||
"https://example.com/docs/manual.pdf?download=1#page=2": {"application/pdf", "%PDF-1.7 manual"},
|
||||
}
|
||||
}
|
||||
|
||||
func drainSitemapSession(t *testing.T, session SyncSession) ([]SyncBatch, []SourceDocument) {
|
||||
t.Helper()
|
||||
var (
|
||||
batches []SyncBatch
|
||||
documents []SourceDocument
|
||||
)
|
||||
for {
|
||||
batch, err := session.NextBatch(context.Background())
|
||||
if errors.Is(err, io.EOF) {
|
||||
return batches, documents
|
||||
}
|
||||
if err != nil {
|
||||
t.Fatalf("NextBatch failed: %v", err)
|
||||
}
|
||||
batches = append(batches, batch)
|
||||
documents = append(documents, batch.Documents...)
|
||||
}
|
||||
}
|
||||
|
||||
func sitemapDocIDs(documents []SourceDocument) []string {
|
||||
ids := make([]string, 0, len(documents))
|
||||
for _, doc := range documents {
|
||||
ids = append(ids, doc.Metadata["url"].(string))
|
||||
}
|
||||
return ids
|
||||
}
|
||||
|
||||
func expectedSitemapSourceID(rawURL string) string {
|
||||
sum := md5.Sum([]byte(rawURL))
|
||||
return "sitemap:" + hex.EncodeToString(sum[:])
|
||||
}
|
||||
|
||||
// TestSitemapConnectorFullSync verifies index recursion, deduplication,
|
||||
// HTML to Markdown conversion, PDF detection, and batch checkpoints.
|
||||
func TestSitemapConnectorFullSync(t *testing.T) {
|
||||
connector := newSitemapTestConnector(t, map[string]any{"batch_size": 2}, defaultSitemapFixture())
|
||||
|
||||
session, err := connector.OpenSync(t.Context(), SyncRequest{FromBeginning: true, WindowEnd: mustTime(t, "2026-01-05T00:00:00Z")})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenSync failed: %v", err)
|
||||
}
|
||||
batches, documents := drainSitemapSession(t, session)
|
||||
|
||||
want := []string{"https://example.com/old", "https://example.com/new", "https://example.com/future", "https://example.com/undated", "https://example.com/brochure.pdf"}
|
||||
if got := sitemapDocIDs(documents); strings.Join(got, ",") != strings.Join(want, ",") {
|
||||
t.Fatalf("documents = %v, want %v", got, want)
|
||||
}
|
||||
if len(batches) != 3 {
|
||||
t.Fatalf("batches = %d, want 3", len(batches))
|
||||
}
|
||||
if batches[0].Checkpoint == nil || batches[0].Checkpoint.SourceID != expectedSitemapSourceID("https://example.com/new") {
|
||||
t.Fatalf("first checkpoint = %+v", batches[0].Checkpoint)
|
||||
}
|
||||
|
||||
old := documents[0]
|
||||
if old.SourceID != expectedSitemapSourceID("https://example.com/old") {
|
||||
t.Fatalf("source id = %s", old.SourceID)
|
||||
}
|
||||
if old.SemanticIdentifier != "example.com/old" {
|
||||
t.Fatalf("semantic identifier = %q", old.SemanticIdentifier)
|
||||
}
|
||||
if old.Extension != ".md" {
|
||||
t.Fatalf("extension = %q, want .md", old.Extension)
|
||||
}
|
||||
if body := string(old.Blob); !strings.Contains(body, "# Old page") || !strings.Contains(body, "Old body") || strings.Contains(body, "Home") || strings.Contains(body, "Footer") {
|
||||
t.Fatalf("markdown body = %q", body)
|
||||
}
|
||||
if old.UpdatedAt != mustTime(t, "2026-01-01T00:00:00Z") {
|
||||
t.Fatalf("updated at = %v", old.UpdatedAt)
|
||||
}
|
||||
if old.Fingerprint == "" || old.Metadata["sitemap_url"] != "https://example.com/sitemap.xml" {
|
||||
t.Fatalf("fingerprint/metadata = %q / %v", old.Fingerprint, old.Metadata)
|
||||
}
|
||||
|
||||
pdf := documents[4]
|
||||
if pdf.Extension != ".pdf" || string(pdf.Blob) != "%PDF-1.4 brochure" {
|
||||
t.Fatalf("pdf document = %+v", pdf)
|
||||
}
|
||||
if pdf.SemanticIdentifier != "example.com/brochure.pdf" {
|
||||
t.Fatalf("pdf semantic identifier = %q", pdf.SemanticIdentifier)
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorIncrementalSync verifies <lastmod> window filtering.
|
||||
func TestSitemapConnectorIncrementalSync(t *testing.T) {
|
||||
connector := newSitemapTestConnector(t, map[string]any{}, defaultSitemapFixture())
|
||||
|
||||
start := mustTime(t, "2026-01-02T00:00:00Z")
|
||||
session, err := connector.OpenSync(t.Context(), SyncRequest{WindowStart: &start, WindowEnd: mustTime(t, "2026-01-04T00:00:00Z")})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenSync failed: %v", err)
|
||||
}
|
||||
_, documents := drainSitemapSession(t, session)
|
||||
|
||||
want := []string{"https://example.com/new"}
|
||||
if got := sitemapDocIDs(documents); strings.Join(got, ",") != strings.Join(want, ",") {
|
||||
t.Fatalf("incremental documents = %v, want %v", got, want)
|
||||
}
|
||||
if documents[0].UpdatedAt != mustTime(t, "2026-01-03T10:00:00.123Z") {
|
||||
t.Fatalf("fractional lastmod not preserved: %v", documents[0].UpdatedAt)
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorURLFilter verifies the url_filter regex and its validation.
|
||||
func TestSitemapConnectorURLFilter(t *testing.T) {
|
||||
connector := newSitemapTestConnector(t, map[string]any{"url_filter": `/(old|new)$`}, defaultSitemapFixture())
|
||||
if err := connector.Validate(t.Context()); err != nil {
|
||||
t.Fatalf("Validate failed: %v", err)
|
||||
}
|
||||
|
||||
session, err := connector.OpenSync(t.Context(), SyncRequest{FromBeginning: true})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenSync failed: %v", err)
|
||||
}
|
||||
_, documents := drainSitemapSession(t, session)
|
||||
want := []string{"https://example.com/old", "https://example.com/new"}
|
||||
if got := sitemapDocIDs(documents); strings.Join(got, ",") != strings.Join(want, ",") {
|
||||
t.Fatalf("filtered documents = %v, want %v", got, want)
|
||||
}
|
||||
|
||||
if _, err := NewSitemapConnector(map[string]any{"sitemap_url": "https://example.com/sitemap.xml", "url_filter": "("}); err == nil {
|
||||
t.Fatalf("invalid regex accepted")
|
||||
}
|
||||
|
||||
noMatch := newSitemapTestConnector(t, map[string]any{"url_filter": `/nothing-here$`}, defaultSitemapFixture())
|
||||
if err := noMatch.Validate(t.Context()); err == nil || !strings.Contains(err.Error(), "no URLs matching") {
|
||||
t.Fatalf("Validate with non-matching filter = %v", err)
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorFollowPDFLinks verifies PDF discovery, domain restriction,
|
||||
// deduplication, and the parent-anchored checkpoint of the PDF pass.
|
||||
func TestSitemapConnectorFollowPDFLinks(t *testing.T) {
|
||||
restricted := newSitemapTestConnector(t, map[string]any{"follow_pdf_links": true, "url_filter": "/new$"}, defaultSitemapFixture())
|
||||
session, err := restricted.OpenSync(t.Context(), SyncRequest{FromBeginning: true})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenSync failed: %v", err)
|
||||
}
|
||||
batches, documents := drainSitemapSession(t, session)
|
||||
want := []string{"https://example.com/new", "https://example.com/docs/guide.pdf", "https://example.com/docs/manual.pdf?download=1#page=2"}
|
||||
if got := sitemapDocIDs(documents); strings.Join(got, ",") != strings.Join(want, ",") {
|
||||
t.Fatalf("restricted documents = %v, want %v", got, want)
|
||||
}
|
||||
guide := documents[1]
|
||||
if guide.Extension != ".pdf" || guide.Metadata["parent_url"] != "https://example.com/new" {
|
||||
t.Fatalf("discovered pdf = %+v", guide)
|
||||
}
|
||||
last := batches[len(batches)-1]
|
||||
if last.Checkpoint == nil || last.Checkpoint.SourceID != expectedSitemapSourceID("https://example.com/new") {
|
||||
t.Fatalf("pdf pass checkpoint = %+v, want parent page anchor", last.Checkpoint)
|
||||
}
|
||||
|
||||
open := newSitemapTestConnector(t, map[string]any{"follow_pdf_links": "true", "restrict_pdf_to_domain": false, "url_filter": "/new$"}, defaultSitemapFixture())
|
||||
session, err = open.OpenSync(t.Context(), SyncRequest{FromBeginning: true})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenSync failed: %v", err)
|
||||
}
|
||||
_, documents = drainSitemapSession(t, session)
|
||||
want = []string{"https://example.com/new", "https://example.com/docs/guide.pdf", "https://cdn.other.org/ext.pdf", "https://example.com/docs/manual.pdf?download=1#page=2"}
|
||||
if got := sitemapDocIDs(documents); strings.Join(got, ",") != strings.Join(want, ",") {
|
||||
t.Fatalf("unrestricted documents = %v, want %v", got, want)
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorOpenPrune verifies the slim snapshot, including discovered PDFs.
|
||||
func TestSitemapConnectorOpenPrune(t *testing.T) {
|
||||
connector := newSitemapTestConnector(t, map[string]any{"batch_size": 10}, defaultSitemapFixture())
|
||||
session, err := connector.OpenPrune(t.Context(), PruneRequest{})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenPrune failed: %v", err)
|
||||
}
|
||||
batch, err := session.NextBatch(context.Background())
|
||||
if err != nil {
|
||||
t.Fatalf("NextBatch failed: %v", err)
|
||||
}
|
||||
if len(batch.Documents) != 5 || batch.Documents[0].SourceID != expectedSitemapSourceID("https://example.com/old") {
|
||||
t.Fatalf("prune snapshot = %+v", batch.Documents)
|
||||
}
|
||||
if _, err := session.NextBatch(context.Background()); !errors.Is(err, io.EOF) {
|
||||
t.Fatalf("prune EOF = %v", err)
|
||||
}
|
||||
|
||||
withPDFs := newSitemapTestConnector(t, map[string]any{"batch_size": 10, "follow_pdf_links": true}, defaultSitemapFixture())
|
||||
session, err = withPDFs.OpenPrune(t.Context(), PruneRequest{})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenPrune failed: %v", err)
|
||||
}
|
||||
batch, err = session.NextBatch(context.Background())
|
||||
if err != nil {
|
||||
t.Fatalf("NextBatch failed: %v", err)
|
||||
}
|
||||
if len(batch.Documents) != 7 || batch.Documents[5].SourceID != expectedSitemapSourceID("https://example.com/docs/guide.pdf") {
|
||||
t.Fatalf("prune snapshot with pdf discovery = %+v", batch.Documents)
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorResume verifies retry resumes after the committed anchor.
|
||||
func TestSitemapConnectorResume(t *testing.T) {
|
||||
connector := newSitemapTestConnector(t, map[string]any{"batch_size": 2}, defaultSitemapFixture())
|
||||
session, err := connector.OpenSync(t.Context(), SyncRequest{FromBeginning: true})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenSync failed: %v", err)
|
||||
}
|
||||
first, err := session.NextBatch(context.Background())
|
||||
if err != nil {
|
||||
t.Fatalf("NextBatch failed: %v", err)
|
||||
}
|
||||
|
||||
resumed, err := connector.OpenSync(t.Context(), SyncRequest{FromBeginning: true, Resume: first.Checkpoint})
|
||||
if err != nil {
|
||||
t.Fatalf("resume OpenSync failed: %v", err)
|
||||
}
|
||||
_, documents := drainSitemapSession(t, resumed)
|
||||
want := []string{"https://example.com/future", "https://example.com/undated", "https://example.com/brochure.pdf"}
|
||||
if got := sitemapDocIDs(documents); strings.Join(got, ",") != strings.Join(want, ",") {
|
||||
t.Fatalf("resumed documents = %v, want %v", got, want)
|
||||
}
|
||||
|
||||
if _, err := connector.OpenSync(t.Context(), SyncRequest{FromBeginning: true, Resume: &SyncCheckpoint{}}); !errors.Is(err, ErrSyncResumeInvalid) {
|
||||
t.Fatalf("empty resume anchor error = %v", err)
|
||||
}
|
||||
if _, err := connector.OpenSync(t.Context(), SyncRequest{FromBeginning: true, Resume: &SyncCheckpoint{SourceID: "sitemap:gone"}}); !errors.Is(err, ErrSyncResumeInvalid) {
|
||||
t.Fatalf("unknown resume anchor error = %v", err)
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorValidate verifies configuration and reachability checks.
|
||||
func TestSitemapConnectorValidate(t *testing.T) {
|
||||
fixture := defaultSitemapFixture()
|
||||
connector := newSitemapTestConnector(t, map[string]any{}, fixture)
|
||||
if err := connector.ValidateConnectorSetting(t.Context(), nil); err != nil {
|
||||
t.Fatalf("ValidateConnectorSetting failed: %v", err)
|
||||
}
|
||||
|
||||
cases := map[string]map[string]any{
|
||||
"missing url": {"sitemap_url": ""},
|
||||
"ftp scheme": {"sitemap_url": "ftp://example.com/sitemap.xml"},
|
||||
"unreachable": {"sitemap_url": "https://example.com/missing.xml"},
|
||||
"empty urlset": {"sitemap_url": "https://example.com/empty.xml"},
|
||||
"not xml": {"sitemap_url": "https://example.com/not-xml"},
|
||||
}
|
||||
fixture["https://example.com/empty.xml"] = [2]string{"application/xml", `<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9"></urlset>`}
|
||||
fixture["https://example.com/not-xml"] = [2]string{"text/html", `<html><body>nope</body></html>`}
|
||||
for name, config := range cases {
|
||||
t.Run(name, func(t *testing.T) {
|
||||
connector := newSitemapTestConnector(t, config, fixture)
|
||||
if err := connector.Validate(t.Context()); err == nil {
|
||||
t.Fatalf("Validate accepted %v", config)
|
||||
}
|
||||
})
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorSkipsBrokenPages verifies fetch failures and empty pages
|
||||
// are skipped without aborting the sync.
|
||||
func TestSitemapConnectorSkipsBrokenPages(t *testing.T) {
|
||||
fixture := defaultSitemapFixture()
|
||||
delete(fixture, "https://example.com/old")
|
||||
fixture["https://example.com/new"] = [2]string{"text/html", `<html><body><nav>only chrome</nav></body></html>`}
|
||||
connector := newSitemapTestConnector(t, map[string]any{}, fixture)
|
||||
|
||||
session, err := connector.OpenSync(t.Context(), SyncRequest{FromBeginning: true})
|
||||
if err != nil {
|
||||
t.Fatalf("OpenSync failed: %v", err)
|
||||
}
|
||||
_, documents := drainSitemapSession(t, session)
|
||||
want := []string{"https://example.com/future", "https://example.com/undated", "https://example.com/brochure.pdf"}
|
||||
if got := sitemapDocIDs(documents); strings.Join(got, ",") != strings.Join(want, ",") {
|
||||
t.Fatalf("documents = %v, want %v", got, want)
|
||||
}
|
||||
}
|
||||
|
||||
// TestParseSitemapLastmod verifies the accepted W3C Datetime shapes.
|
||||
func TestParseSitemapLastmod(t *testing.T) {
|
||||
cases := map[string]string{
|
||||
"2026-01-02": "2026-01-02T00:00:00Z",
|
||||
"2026-01-02T03:04:05Z": "2026-01-02T03:04:05Z",
|
||||
"2026-01-02T03:04:05.789Z": "2026-01-02T03:04:05.789Z",
|
||||
"2026-01-02T03:04:05+02:00": "2026-01-02T01:04:05Z",
|
||||
"2026-01-02T03:04:05.123456+0200": "",
|
||||
"2026-01-02T03:04": "2026-01-02T03:04:00Z",
|
||||
"yesterday": "",
|
||||
}
|
||||
for input, want := range cases {
|
||||
got := parseSitemapLastmod(input)
|
||||
if want == "" {
|
||||
if !got.IsZero() {
|
||||
t.Fatalf("parseSitemapLastmod(%q) = %v, want zero", input, got)
|
||||
}
|
||||
continue
|
||||
}
|
||||
if got.IsZero() || got.Format("2006-01-02T15:04:05.999Z07:00") != want {
|
||||
t.Fatalf("parseSitemapLastmod(%q) = %v, want %s", input, got, want)
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapSemanticIdentifier verifies query and fragment are preserved.
|
||||
func TestSitemapSemanticIdentifier(t *testing.T) {
|
||||
cases := map[string]string{
|
||||
"https://example.com/": "example.com",
|
||||
"https://example.com/a/b/": "example.com/a/b",
|
||||
"https://example.com/a?page=2#top": "example.com/a?page=2#top",
|
||||
"https://example.com/a?page=2": "example.com/a?page=2",
|
||||
"https://example.com/docs/guide.pdf": "example.com/docs/guide.pdf",
|
||||
}
|
||||
for input, want := range cases {
|
||||
if got := sitemapSemanticIdentifier(input); got != want {
|
||||
t.Fatalf("sitemapSemanticIdentifier(%q) = %q, want %q", input, got, want)
|
||||
}
|
||||
}
|
||||
}
|
||||
|
||||
// TestSitemapConnectorListEntriesBoundsFetches verifies that nested sitemap
|
||||
// indexes referencing themselves or an ancestor are fetched once, and that the
|
||||
// walk stops at maxSitemapFetches.
|
||||
func TestSitemapConnectorListEntriesBoundsFetches(t *testing.T) {
|
||||
fetches := map[string]int{}
|
||||
fixture := defaultSitemapFixture()
|
||||
connector := newSitemapTestConnector(t, map[string]any{}, fixture)
|
||||
connector.fetch = func(ctx context.Context, rawURL string) ([]byte, string, error) {
|
||||
fetches[rawURL]++
|
||||
return fixture.fetch(ctx, rawURL)
|
||||
}
|
||||
|
||||
entries, err := connector.listEntries(t.Context())
|
||||
if err != nil {
|
||||
t.Fatalf("listEntries failed: %v", err)
|
||||
}
|
||||
if len(entries) != 5 {
|
||||
t.Fatalf("entries = %d, want 5", len(entries))
|
||||
}
|
||||
for rawURL, count := range fetches {
|
||||
if count != 1 {
|
||||
t.Fatalf("%s fetched %d times, want once", rawURL, count)
|
||||
}
|
||||
}
|
||||
|
||||
// A wide index tree stops at the fetch cap instead of exploding.
|
||||
var children strings.Builder
|
||||
for i := 0; i < maxSitemapFetches+50; i++ {
|
||||
fmt.Fprintf(&children, "<sitemap><loc>https://example.com/child-%d.xml</loc></sitemap>", i)
|
||||
}
|
||||
wide := sitemapFixture{"https://example.com/sitemap.xml": {"application/xml", `<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">` + children.String() + `</sitemapindex>`}}
|
||||
for i := 0; i < maxSitemapFetches+50; i++ {
|
||||
wide[fmt.Sprintf("https://example.com/child-%d.xml", i)] = [2]string{"application/xml", fmt.Sprintf(`<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9"><url><loc>https://example.com/page-%d</loc></url></urlset>`, i)}
|
||||
}
|
||||
total := 0
|
||||
capped := newSitemapTestConnector(t, map[string]any{}, wide)
|
||||
capped.fetch = func(ctx context.Context, rawURL string) ([]byte, string, error) {
|
||||
total++
|
||||
return wide.fetch(ctx, rawURL)
|
||||
}
|
||||
entries, err = capped.listEntries(t.Context())
|
||||
if err != nil {
|
||||
t.Fatalf("listEntries (wide) failed: %v", err)
|
||||
}
|
||||
if total != maxSitemapFetches {
|
||||
t.Fatalf("fetches = %d, want %d", total, maxSitemapFetches)
|
||||
}
|
||||
if len(entries) != maxSitemapFetches-1 {
|
||||
t.Fatalf("entries = %d, want %d", len(entries), maxSitemapFetches-1)
|
||||
}
|
||||
}
|
||||
@@ -39,6 +39,7 @@ dependencies = [
|
||||
"elasticsearch-dsl==8.12.0",
|
||||
"exceptiongroup>=1.3.0,<2.0.0",
|
||||
"feedparser>=6.0.11,<7.0.0",
|
||||
"trafilatura>=2.0.0",
|
||||
"extract-msg>=0.39.0",
|
||||
"ffmpeg-python>=0.2.0",
|
||||
"flasgger>=0.9.7.1,<0.10.0",
|
||||
@@ -204,6 +205,7 @@ test = [
|
||||
"python-docx>=1.1.2",
|
||||
"python-pptx>=1.0.2",
|
||||
"reportlab>=4.4.1",
|
||||
"regex>=2025.11.3",
|
||||
"requests>=2.32.2",
|
||||
"requests-toolbelt>=1.0.0",
|
||||
"pycryptodomex==3.20.0",
|
||||
|
||||
@@ -32,7 +32,7 @@ import signal
|
||||
import sys
|
||||
import threading
|
||||
import traceback
|
||||
from datetime import datetime, timezone
|
||||
from datetime import UTC, datetime, timezone
|
||||
from typing import Any
|
||||
|
||||
from flask import json
|
||||
@@ -47,6 +47,7 @@ from common.data_source.config import INDEX_BATCH_SIZE
|
||||
from common.data_source import (
|
||||
BlobStorageConnector,
|
||||
RSSConnector,
|
||||
SitemapConnector,
|
||||
NotionConnector,
|
||||
DiscordConnector,
|
||||
GoogleDriveConnector,
|
||||
@@ -81,6 +82,7 @@ from common.data_source.gitlab_connector import GitlabConnector
|
||||
from common.data_source.bitbucket.connector import BitbucketConnector
|
||||
from common.data_source.azure_devops.connector import AzureDevOpsConnector
|
||||
from common.data_source.interfaces import CheckpointOutputWrapper
|
||||
from common.data_source.sitemap_connector import iter_in_worker_thread, validate_connector_in_thread
|
||||
from common.data_source.exceptions import ConnectorValidationError
|
||||
from common.log_utils import init_root_logger
|
||||
from common.signal_utils import start_tracemalloc_and_snapshot, stop_tracemalloc
|
||||
@@ -108,6 +110,34 @@ def _redact_mailbox(value: str) -> str:
|
||||
return f"{value[:4]}***" if len(value) > 4 else "***"
|
||||
|
||||
|
||||
async def _iterate_document_batches(generator):
|
||||
"""Yield connector batches, advancing thread-bridged iterators off the event loop.
|
||||
|
||||
Connectors that return an iterator flagged ``offload_next`` (see
|
||||
``common.data_source.sitemap_connector.iter_in_worker_thread``) may block in
|
||||
``next()`` while a batch is being fetched; that call is awaited through
|
||||
``asyncio.to_thread`` so ``asyncio.wait_for`` keeps enforcing the task timeout and
|
||||
cancellation closes the source. Every other connector keeps its synchronous
|
||||
iteration unchanged.
|
||||
"""
|
||||
if not getattr(generator, "offload_next", False):
|
||||
for item in generator:
|
||||
yield item
|
||||
return
|
||||
|
||||
sentinel = object()
|
||||
try:
|
||||
while True:
|
||||
item = await asyncio.to_thread(next, generator, sentinel)
|
||||
if item is sentinel:
|
||||
return
|
||||
yield item
|
||||
finally:
|
||||
close = getattr(generator, "close", None)
|
||||
if close is not None:
|
||||
close()
|
||||
|
||||
|
||||
class SyncBase:
|
||||
"""
|
||||
Base class for all data source synchronization connectors.
|
||||
@@ -224,7 +254,7 @@ class SyncBase:
|
||||
if task["poll_range_start"]:
|
||||
next_update = task["poll_range_start"]
|
||||
|
||||
for document_batch in document_batch_generator:
|
||||
async for document_batch in _iterate_document_batches(document_batch_generator):
|
||||
if not document_batch:
|
||||
continue
|
||||
|
||||
@@ -510,6 +540,63 @@ class RSS(SyncBase):
|
||||
return document_generator
|
||||
|
||||
|
||||
class Sitemap(SyncBase):
|
||||
SOURCE_NAME: str = FileSource.SITEMAP
|
||||
|
||||
@staticmethod
|
||||
def _sanitize_docs(gen):
|
||||
"""Strip URL scheme from semantic_identifier so object storage accepts it as a key."""
|
||||
from urllib.parse import urlparse
|
||||
|
||||
for batch in gen:
|
||||
sanitized = []
|
||||
for doc in batch:
|
||||
si = doc.semantic_identifier
|
||||
if si.startswith(("http://", "https://")):
|
||||
parsed = urlparse(si)
|
||||
si = f"{parsed.netloc}{parsed.path}"
|
||||
if parsed.query:
|
||||
si += f"?{parsed.query}"
|
||||
if parsed.fragment:
|
||||
si += f"#{parsed.fragment}"
|
||||
si = si.strip("/")
|
||||
doc = doc.model_copy(update={"semantic_identifier": si})
|
||||
sanitized.append(doc)
|
||||
yield sanitized
|
||||
|
||||
async def _prepare_connector(self, task: dict):
|
||||
"""Build and validate the connector without starting any document traversal."""
|
||||
self.connector = SitemapConnector.build_connector(self.conf)
|
||||
# validate_connector_settings fetches the sitemap synchronously: keep it off the event
|
||||
# loop, and tell the connector to stop if the task is cancelled meanwhile.
|
||||
await validate_connector_in_thread(self.connector)
|
||||
self.log_connection("Sitemap", self.conf["sitemap_url"], task)
|
||||
|
||||
async def _initialize_for_prune(self, task: dict):
|
||||
# Prune only needs the connector (for retrieve_all_slim_docs_perm_sync); do not start
|
||||
# the batch producer thread that _generate() would create and the base class discard.
|
||||
await self._prepare_connector(task)
|
||||
|
||||
async def _generate(self, task: dict):
|
||||
await self._prepare_connector(task)
|
||||
|
||||
# Batches are produced in a worker thread (network I/O off the event-loop thread)
|
||||
# and handed over through a bounded queue.
|
||||
if task["reindex"] == "1" or not task["poll_range_start"]:
|
||||
return iter_in_worker_thread(self._sanitize_docs(self.connector.load_from_state()), on_close=self.connector.cancel)
|
||||
|
||||
end_time = datetime.now(UTC).timestamp()
|
||||
return iter_in_worker_thread(
|
||||
self._sanitize_docs(
|
||||
self.connector.poll_source(
|
||||
task["poll_range_start"].timestamp(),
|
||||
end_time,
|
||||
)
|
||||
),
|
||||
on_close=self.connector.cancel,
|
||||
)
|
||||
|
||||
|
||||
class Confluence(SyncBase):
|
||||
SOURCE_NAME: str = FileSource.CONFLUENCE
|
||||
|
||||
@@ -2219,6 +2306,7 @@ class Xquik(SyncBase):
|
||||
|
||||
func_factory = {
|
||||
FileSource.RSS: RSS,
|
||||
FileSource.SITEMAP: Sitemap,
|
||||
FileSource.S3: S3,
|
||||
FileSource.R2: R2,
|
||||
FileSource.OCI_STORAGE: OCI_STORAGE,
|
||||
|
||||
@@ -89,3 +89,57 @@ def test_link_inside_a_table_cell_is_linkified(markdown_links):
|
||||
def test_link_is_stripped_under_the_default_strategy():
|
||||
# Default strategy is STRIP: no markdown link syntax at all.
|
||||
assert _fmt('<p>see <a href="http://x.com">link</a> after</p>') == "see link after"
|
||||
|
||||
|
||||
_PARAGRAPH = "<p>" + " ".join(["This paragraph describes the installation process in enough detail to count as real content."] * 3) + "</p>"
|
||||
# Realistic size on purpose: on very short documents trafilatura falls back to its
|
||||
# plain-text baseline and emits no Markdown structure.
|
||||
PAGE = f"""<html><head><title>Guide</title></head><body>
|
||||
<nav><a href="/">Home</a></nav>
|
||||
<main><h1>Getting started</h1><p>Install the <a href="/docs/cli">CLI</a> first.</p>{_PARAGRAPH}
|
||||
<h2>Steps</h2><ul><li>step one</li><li>step two</li></ul>{_PARAGRAPH}</main>
|
||||
<footer>© Example</footer></body></html>"""
|
||||
|
||||
|
||||
def test_web_html_to_markdown_keeps_structure_and_drops_boilerplate():
|
||||
parsed = html_utils.web_html_to_markdown(PAGE)
|
||||
|
||||
assert parsed.title == "Guide"
|
||||
assert "# Getting started" in parsed.cleaned_text
|
||||
assert "## Steps" in parsed.cleaned_text
|
||||
assert "[CLI](/docs/cli)" in parsed.cleaned_text
|
||||
assert "step one" in parsed.cleaned_text and "step two" in parsed.cleaned_text
|
||||
assert "Home" not in parsed.cleaned_text # <nav> is in WEB_CONNECTOR_IGNORED_ELEMENTS
|
||||
assert "© Example" not in parsed.cleaned_text # <footer> too
|
||||
|
||||
|
||||
def test_web_html_to_markdown_does_not_depend_on_the_flat_text_switch(monkeypatch):
|
||||
monkeypatch.setattr(html_utils, "PARSE_WITH_TRAFILATURA", False)
|
||||
parsed = html_utils.web_html_to_markdown(PAGE)
|
||||
|
||||
assert "# Getting started" in parsed.cleaned_text
|
||||
|
||||
|
||||
def test_web_html_to_markdown_falls_back_to_flat_text_when_trafilatura_fails(monkeypatch):
|
||||
def _boom(html_content, output_format="txt"):
|
||||
raise RuntimeError("trafilatura exploded")
|
||||
|
||||
monkeypatch.setattr(html_utils, "parse_html_with_trafilatura", _boom)
|
||||
parsed = html_utils.web_html_to_markdown(PAGE)
|
||||
|
||||
assert parsed.title == "Guide"
|
||||
assert not parsed.cleaned_text.startswith("Guide") # title tag dropped before the bs4 fallback
|
||||
assert "Getting started" in parsed.cleaned_text
|
||||
assert "Home" not in parsed.cleaned_text
|
||||
|
||||
|
||||
def test_web_html_cleanup_and_markdown_share_the_same_cleanup():
|
||||
flat = html_utils.web_html_cleanup(PAGE)
|
||||
markdown = html_utils.web_html_to_markdown(PAGE)
|
||||
|
||||
assert flat.title == markdown.title == "Guide"
|
||||
for boilerplate in ("Home", "© Example"):
|
||||
assert boilerplate not in flat.cleaned_text
|
||||
assert boilerplate not in markdown.cleaned_text
|
||||
assert "Getting started" in flat.cleaned_text
|
||||
assert "# Getting started" in markdown.cleaned_text
|
||||
@@ -0,0 +1,854 @@
|
||||
"""Unit tests for SitemapConnector — no network, no external dependencies."""
|
||||
|
||||
import asyncio
|
||||
import importlib
|
||||
import logging
|
||||
import threading
|
||||
import time
|
||||
from contextlib import contextmanager
|
||||
from datetime import UTC, datetime
|
||||
from unittest.mock import MagicMock
|
||||
|
||||
import pytest
|
||||
|
||||
_sitemap_mod = importlib.import_module("common.data_source.sitemap_connector")
|
||||
SitemapConnector = _sitemap_mod.SitemapConnector
|
||||
DocumentSource = importlib.import_module("common.data_source.config").DocumentSource
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Test data
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
_NS = "http://www.sitemaps.org/schemas/sitemap/0.9"
|
||||
|
||||
_SITEMAP_XML = f"""<?xml version="1.0" encoding="UTF-8"?>
|
||||
<urlset xmlns="{_NS}">
|
||||
<url>
|
||||
<loc>https://example.com/page-1</loc>
|
||||
<lastmod>2024-03-15</lastmod>
|
||||
</url>
|
||||
<url>
|
||||
<loc>https://example.com/page-2</loc>
|
||||
</url>
|
||||
</urlset>""".encode()
|
||||
|
||||
_SITEMAP_INDEX_XML = f"""<?xml version="1.0" encoding="UTF-8"?>
|
||||
<sitemapindex xmlns="{_NS}">
|
||||
<sitemap>
|
||||
<loc>https://example.com/sitemap-en.xml</loc>
|
||||
</sitemap>
|
||||
</sitemapindex>""".encode()
|
||||
|
||||
_CHILD_SITEMAP_XML = f"""<?xml version="1.0" encoding="UTF-8"?>
|
||||
<urlset xmlns="{_NS}">
|
||||
<url>
|
||||
<loc>https://example.com/en/page-1</loc>
|
||||
<lastmod>2024-06-01</lastmod>
|
||||
</url>
|
||||
</urlset>""".encode()
|
||||
|
||||
_SITEMAP_TWO_PAGES = f"""<?xml version="1.0" encoding="UTF-8"?>
|
||||
<urlset xmlns="{_NS}">
|
||||
<url><loc>https://example.com/page-1</loc></url>
|
||||
<url><loc>https://example.com/page-2</loc></url>
|
||||
</urlset>""".encode()
|
||||
|
||||
_HTML_WITH_PDF = b"""<html><body>
|
||||
<a href="/docs/report.pdf">Report</a>
|
||||
<a href="https://other.com/external.pdf">External PDF</a>
|
||||
<p>Some content about the report.</p>
|
||||
</body></html>"""
|
||||
|
||||
_HTML_SAME_PDF = b'<html><body><a href="/shared.pdf">Shared</a></html>'
|
||||
|
||||
_PDF_BYTES = b"%PDF-1.4 fake pdf content"
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Helpers
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
def _fake_response(content: bytes, content_type: str = "text/html; charset=utf-8", headers: dict | None = None, status_code: int = 200):
|
||||
resp = MagicMock()
|
||||
resp.content = content
|
||||
resp.status_code = status_code
|
||||
all_headers = {"Content-Type": content_type, **(headers or {})}
|
||||
resp.headers.get.side_effect = lambda key, default="": all_headers.get(key, default)
|
||||
# The connector streams the body in chunks; emulate requests' iter_content.
|
||||
resp.iter_content.side_effect = lambda chunk_size=65536: [content[i : i + chunk_size] for i in range(0, len(content), chunk_size)]
|
||||
resp.raise_for_status = MagicMock()
|
||||
resp.close = MagicMock()
|
||||
return resp
|
||||
|
||||
|
||||
def _make_get(url_map: dict):
|
||||
def _get(url, **kwargs):
|
||||
if url in url_map:
|
||||
return url_map[url]
|
||||
raise AssertionError(f"Unexpected URL requested in test: {url!r}")
|
||||
|
||||
return _get
|
||||
|
||||
|
||||
def _patch_ssrf(monkeypatch):
|
||||
monkeypatch.setattr(_sitemap_mod, "assert_url_is_safe", lambda url: ("example.com", "1.2.3.4"))
|
||||
|
||||
|
||||
def _patch_requests(monkeypatch, url_map: dict):
|
||||
# The connector uses a dedicated requests.Session (trust_env=False); patch its get().
|
||||
_get = _make_get(url_map)
|
||||
monkeypatch.setattr(_sitemap_mod.requests.Session, "get", lambda self, url, **kwargs: _get(url, **kwargs))
|
||||
|
||||
|
||||
def _patch_trafilatura(monkeypatch, text="# Title\n\nBody text."):
|
||||
"""Stub the shared HTML→Markdown helper (html_utils.web_html_to_markdown) used by the connector."""
|
||||
from common.data_source.html_utils import ParsedHTML
|
||||
|
||||
mock = MagicMock(return_value=ParsedHTML(title=None, cleaned_text=text))
|
||||
monkeypatch.setattr(_sitemap_mod, "web_html_to_markdown", mock)
|
||||
return mock
|
||||
|
||||
|
||||
def _connector(**kwargs):
|
||||
return SitemapConnector(sitemap_url="https://example.com/sitemap.xml", **kwargs)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# validate_connector_settings
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_validate_rejects_non_http_scheme():
|
||||
connector = SitemapConnector(sitemap_url="ftp://example.com/sitemap.xml")
|
||||
with pytest.raises(ValueError, match="valid http or https URL"):
|
||||
connector.validate_connector_settings()
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_validate_rejects_batch_size_below_one(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
connector = _connector(batch_size=0)
|
||||
with pytest.raises(ValueError, match="batch_size"):
|
||||
connector.validate_connector_settings()
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_validate_rejects_sitemap_with_no_matching_urls(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(monkeypatch, {"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML)})
|
||||
connector = _connector(url_filter=r"/blog/.*")
|
||||
with pytest.raises(ValueError, match="no URLs matching"):
|
||||
connector.validate_connector_settings()
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_validate_accepts_valid_sitemap(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(monkeypatch, {"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML)})
|
||||
_connector().validate_connector_settings() # should not raise
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# _iter_sitemap_urls
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_sitemap_urls_parses_standard_urlset(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(monkeypatch, {"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML)})
|
||||
results = list(_connector()._iter_sitemap_urls("https://example.com/sitemap.xml", depth=0))
|
||||
|
||||
assert len(results) == 2
|
||||
assert results[0] == ("https://example.com/page-1", datetime(2024, 3, 15, tzinfo=UTC))
|
||||
assert results[1] == ("https://example.com/page-2", None)
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_sitemap_urls_recurses_into_index(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_INDEX_XML),
|
||||
"https://example.com/sitemap-en.xml": _fake_response(_CHILD_SITEMAP_XML),
|
||||
},
|
||||
)
|
||||
results = list(_connector()._iter_sitemap_urls("https://example.com/sitemap.xml", depth=0))
|
||||
|
||||
assert len(results) == 1
|
||||
assert results[0][0] == "https://example.com/en/page-1"
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# _fetch_and_build_document
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_fetch_builds_markdown_doc_for_html(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch, text="# Title\n\nHello world.")
|
||||
_patch_requests(monkeypatch, {"https://example.com/page-1": _fake_response(b"<html>page</html>")})
|
||||
lastmod = datetime(2024, 3, 15, tzinfo=UTC)
|
||||
doc = _connector()._fetch_and_build_document("https://example.com/page-1", lastmod)
|
||||
|
||||
assert doc is not None
|
||||
assert doc.source == DocumentSource.SITEMAP
|
||||
assert doc.extension == ".md"
|
||||
assert doc.semantic_identifier == "example.com/page-1"
|
||||
assert b"Hello world" in doc.blob
|
||||
assert doc.doc_updated_at == lastmod
|
||||
assert "parent_url" not in doc.metadata
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_fetch_builds_pdf_doc_for_pdf_content_type(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/doc.pdf": _fake_response(_PDF_BYTES, content_type="application/pdf"),
|
||||
},
|
||||
)
|
||||
doc = _connector()._fetch_and_build_document("https://example.com/doc.pdf", None)
|
||||
|
||||
assert doc is not None
|
||||
assert doc.extension == ".pdf"
|
||||
assert doc.blob == _PDF_BYTES
|
||||
assert doc.semantic_identifier == "example.com/doc.pdf"
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_fetch_skips_empty_html_content(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch, text="")
|
||||
_patch_requests(monkeypatch, {"https://example.com/page": _fake_response(b"<html></html>")})
|
||||
doc = _connector()._fetch_and_build_document("https://example.com/page", None)
|
||||
assert doc is None
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# load_from_state
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_load_from_state_yields_all_documents(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(b"<html>p1</html>"),
|
||||
"https://example.com/page-2": _fake_response(b"<html>p2</html>"),
|
||||
},
|
||||
)
|
||||
batches = list(_connector(batch_size=10).load_from_state())
|
||||
assert sum(len(b) for b in batches) == 2
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_load_from_state_respects_batch_size(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(b"<html>p1</html>"),
|
||||
"https://example.com/page-2": _fake_response(b"<html>p2</html>"),
|
||||
},
|
||||
)
|
||||
batches = list(_connector(batch_size=1).load_from_state())
|
||||
assert len(batches) == 2
|
||||
assert all(len(b) == 1 for b in batches)
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# poll_source
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_poll_source_includes_url_within_range(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(b"<html>p1</html>"),
|
||||
},
|
||||
)
|
||||
start = datetime(2024, 1, 1, tzinfo=UTC).timestamp()
|
||||
end = datetime(2024, 12, 31, tzinfo=UTC).timestamp()
|
||||
docs = [doc for batch in _connector().poll_source(start, end) for doc in batch]
|
||||
|
||||
# page-1 has lastmod 2024-03-15 (in range); page-2 has no lastmod (skipped)
|
||||
assert [doc.semantic_identifier for doc in docs] == ["example.com/page-1"]
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_poll_source_excludes_url_before_start(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(monkeypatch, {"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML)})
|
||||
# start after 2024-03-15 → page-1 excluded; page-2 has no lastmod → excluded too
|
||||
start = datetime(2024, 6, 1, tzinfo=UTC).timestamp()
|
||||
end = datetime(2024, 12, 31, tzinfo=UTC).timestamp()
|
||||
batches = list(_connector().poll_source(start, end))
|
||||
assert batches == []
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# _extract_pdf_links
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_extract_pdf_links_returns_absolute_urls():
|
||||
links = SitemapConnector._extract_pdf_links(_HTML_WITH_PDF, "https://example.com/page")
|
||||
assert "https://example.com/docs/report.pdf" in links
|
||||
assert "https://other.com/external.pdf" in links
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_extract_pdf_links_empty_when_no_pdf_hrefs():
|
||||
links = SitemapConnector._extract_pdf_links(b"<html><a href='/page'>link</a></html>", "https://example.com/")
|
||||
assert links == []
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# follow_pdf_links
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_follow_pdf_links_yields_pdf_documents(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(_HTML_WITH_PDF),
|
||||
"https://example.com/page-2": _fake_response(b"<html>no pdfs</html>"),
|
||||
"https://example.com/docs/report.pdf": _fake_response(_PDF_BYTES, content_type="application/pdf"),
|
||||
},
|
||||
)
|
||||
connector = _connector(follow_pdf_links=True, restrict_pdf_to_domain=True)
|
||||
docs = [doc for batch in connector.load_from_state() for doc in batch]
|
||||
|
||||
assert any(doc.extension == ".pdf" for doc in docs)
|
||||
assert any(doc.extension == ".md" for doc in docs)
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_follow_pdf_links_sets_parent_url_in_metadata(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(_HTML_WITH_PDF),
|
||||
"https://example.com/page-2": _fake_response(b"<html>no pdfs</html>"),
|
||||
"https://example.com/docs/report.pdf": _fake_response(_PDF_BYTES, content_type="application/pdf"),
|
||||
},
|
||||
)
|
||||
connector = _connector(follow_pdf_links=True, restrict_pdf_to_domain=True)
|
||||
docs = [doc for batch in connector.load_from_state() for doc in batch]
|
||||
pdf_docs = [doc for doc in docs if doc.extension == ".pdf"]
|
||||
|
||||
assert len(pdf_docs) == 1
|
||||
assert pdf_docs[0].metadata["parent_url"] == "https://example.com/page-1"
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_follow_pdf_links_restricts_to_domain(monkeypatch):
|
||||
"""External PDF (other.com) must not be fetched when restrict_pdf_to_domain=True."""
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
# https://other.com/external.pdf is intentionally NOT in the map
|
||||
# _make_get raises AssertionError if it is called
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(_HTML_WITH_PDF),
|
||||
"https://example.com/page-2": _fake_response(b"<html>no pdfs</html>"),
|
||||
"https://example.com/docs/report.pdf": _fake_response(_PDF_BYTES, content_type="application/pdf"),
|
||||
},
|
||||
)
|
||||
connector = _connector(follow_pdf_links=True, restrict_pdf_to_domain=True)
|
||||
docs = [doc for batch in connector.load_from_state() for doc in batch]
|
||||
pdf_identifiers = [doc.semantic_identifier for doc in docs if doc.extension == ".pdf"]
|
||||
|
||||
assert any("report.pdf" in s for s in pdf_identifiers)
|
||||
assert not any("external.pdf" in s for s in pdf_identifiers)
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_follow_pdf_links_allows_external_when_unrestricted(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(_HTML_WITH_PDF),
|
||||
"https://example.com/page-2": _fake_response(b"<html>no pdfs</html>"),
|
||||
"https://example.com/docs/report.pdf": _fake_response(_PDF_BYTES, content_type="application/pdf"),
|
||||
"https://other.com/external.pdf": _fake_response(_PDF_BYTES, content_type="application/pdf"),
|
||||
},
|
||||
)
|
||||
connector = _connector(follow_pdf_links=True, restrict_pdf_to_domain=False)
|
||||
docs = [doc for batch in connector.load_from_state() for doc in batch]
|
||||
pdf_count = sum(1 for doc in docs if doc.extension == ".pdf")
|
||||
assert pdf_count == 2
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_pdf_deduplicated_when_linked_from_multiple_pages(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_TWO_PAGES),
|
||||
"https://example.com/page-1": _fake_response(_HTML_SAME_PDF),
|
||||
"https://example.com/page-2": _fake_response(_HTML_SAME_PDF),
|
||||
# shared.pdf must be fetched exactly once
|
||||
"https://example.com/shared.pdf": _fake_response(_PDF_BYTES, content_type="application/pdf"),
|
||||
},
|
||||
)
|
||||
connector = _connector(follow_pdf_links=True, restrict_pdf_to_domain=True)
|
||||
docs = [doc for batch in connector.load_from_state() for doc in batch]
|
||||
pdf_docs = [doc for doc in docs if doc.extension == ".pdf"]
|
||||
assert len(pdf_docs) == 1
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# retrieve_all_slim_docs_perm_sync
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_retrieve_all_slim_docs_yields_one_per_url(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(monkeypatch, {"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML)})
|
||||
slim_docs = [doc for batch in _connector().retrieve_all_slim_docs_perm_sync() for doc in batch]
|
||||
|
||||
assert len(slim_docs) == 2
|
||||
assert all(doc.id.startswith("sitemap:") for doc in slim_docs)
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_retrieve_all_slim_docs_includes_discovered_pdfs(monkeypatch):
|
||||
"""With follow_pdf_links, discovered PDFs must be part of the retained set."""
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(_HTML_WITH_PDF),
|
||||
"https://example.com/page-2": _fake_response(b"<html>no pdfs</html>"),
|
||||
# https://other.com/external.pdf is intentionally NOT in the map
|
||||
},
|
||||
)
|
||||
connector = _connector(follow_pdf_links=True, restrict_pdf_to_domain=True)
|
||||
slim_ids = {doc.id for batch in connector.retrieve_all_slim_docs_perm_sync() for doc in batch}
|
||||
|
||||
assert slim_ids == {
|
||||
connector._build_document_id("https://example.com/page-1"),
|
||||
connector._build_document_id("https://example.com/page-2"),
|
||||
connector._build_document_id("https://example.com/docs/report.pdf"),
|
||||
}
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# build_connector (used by the connection-test endpoint and the sync worker)
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_build_connector_maps_ui_config():
|
||||
connector = SitemapConnector.build_connector(
|
||||
{
|
||||
"sitemap_url": " https://example.com/sitemap.xml ",
|
||||
"url_filter": "^https://example\\.com/docs/",
|
||||
"follow_pdf_links": True,
|
||||
"restrict_pdf_to_domain": False,
|
||||
"user_agent": "",
|
||||
"batch_size": "3",
|
||||
"credentials": {},
|
||||
}
|
||||
)
|
||||
|
||||
assert connector.sitemap_url == "https://example.com/sitemap.xml"
|
||||
assert connector._url_filter is not None and connector._url_filter.pattern == "^https://example\\.com/docs/"
|
||||
assert connector.follow_pdf_links is True
|
||||
assert connector.restrict_pdf_to_domain is False
|
||||
assert connector.user_agent == "RAGFlow-SitemapConnector/1.0"
|
||||
assert connector.batch_size == 3
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_build_connector_defaults():
|
||||
connector = SitemapConnector.build_connector({"sitemap_url": "https://example.com/sitemap.xml"})
|
||||
|
||||
assert connector._url_filter is None
|
||||
assert connector.follow_pdf_links is False
|
||||
assert connector.restrict_pdf_to_domain is True
|
||||
assert connector.batch_size >= 1
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# Hardening: regex guard, PDF link detection, DNS pinning, size cap, fetch budget
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
@pytest.mark.parametrize("pattern", ["^https://(a+)+$", "(x*y)*z", "(?:ab*)+c"])
|
||||
def test_url_filter_rejects_nested_quantifiers(pattern):
|
||||
with pytest.raises(ValueError, match="nested quantifiers"):
|
||||
_connector(url_filter=pattern)
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_url_filter_rejects_too_long_pattern():
|
||||
with pytest.raises(ValueError, match="too long"):
|
||||
_connector(url_filter="a" * (_sitemap_mod._MAX_URL_FILTER_LENGTH + 1))
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_url_filter_accepts_plain_patterns():
|
||||
connector = _connector(url_filter=r"^https://example\.com/(docs|blog)/[a-z0-9-]+$")
|
||||
assert connector._url_matches("https://example.com/docs/intro")
|
||||
assert not connector._url_matches("https://example.com/pricing")
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_extract_pdf_links_accepts_query_strings_and_fragments():
|
||||
html = b"""<html><body>
|
||||
<a href="/manual.pdf?download=1">Manual</a>
|
||||
<a href="/guide.PDF#page=3">Guide</a>
|
||||
<a href="/page.html?file=x.pdf">Not a PDF</a>
|
||||
<a href="report.pdf">Relative</a>
|
||||
</body></html>"""
|
||||
links = SitemapConnector._extract_pdf_links(html, "https://example.com/docs/index.html")
|
||||
assert links == [
|
||||
"https://example.com/manual.pdf?download=1",
|
||||
"https://example.com/guide.PDF#page=3",
|
||||
"https://example.com/docs/report.pdf",
|
||||
]
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_fetch_raw_pins_dns_on_every_hop(monkeypatch):
|
||||
pins: list[tuple[str, str]] = []
|
||||
|
||||
@contextmanager
|
||||
def _recording_pin(hostname, ip):
|
||||
pins.append((hostname, ip))
|
||||
yield
|
||||
|
||||
monkeypatch.setattr(_sitemap_mod, "_pin_dns", _recording_pin)
|
||||
monkeypatch.setattr(
|
||||
_sitemap_mod,
|
||||
"assert_url_is_safe",
|
||||
lambda url: ("example.com", "1.2.3.4") if "example.com" in url else ("cdn.example.net", "5.6.7.8"),
|
||||
)
|
||||
redirect = _fake_response(b"", headers={"Location": "https://cdn.example.net/final"}, status_code=302)
|
||||
_patch_requests(
|
||||
monkeypatch,
|
||||
{
|
||||
"https://example.com/start": redirect,
|
||||
"https://cdn.example.net/final": _fake_response(b"<html>ok</html>"),
|
||||
},
|
||||
)
|
||||
|
||||
content, _ = _connector()._fetch_raw("https://example.com/start")
|
||||
|
||||
assert content == b"<html>ok</html>"
|
||||
assert pins == [("example.com", "1.2.3.4"), ("cdn.example.net", "5.6.7.8")]
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_fetch_raw_rejects_oversized_content_length(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
big = _fake_response(b"x", headers={"Content-Length": str(_sitemap_mod._MAX_RESPONSE_BYTES + 1)})
|
||||
_patch_requests(monkeypatch, {"https://example.com/big": big})
|
||||
|
||||
with pytest.raises(ValueError, match="maximum allowed size"):
|
||||
_connector()._fetch_raw("https://example.com/big")
|
||||
big.close.assert_called()
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_fetch_raw_rejects_oversized_streamed_body(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
monkeypatch.setattr(_sitemap_mod, "_MAX_RESPONSE_BYTES", 10)
|
||||
monkeypatch.setattr(_sitemap_mod, "_READ_CHUNK_BYTES", 4)
|
||||
_patch_requests(monkeypatch, {"https://example.com/stream": _fake_response(b"0123456789ABCDEF")})
|
||||
|
||||
with pytest.raises(ValueError, match="maximum allowed size"):
|
||||
_connector()._fetch_raw("https://example.com/stream")
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_sitemap_urls_visits_each_sitemap_once(monkeypatch):
|
||||
"""A sitemap index referencing itself and its parent must not be re-fetched."""
|
||||
_patch_ssrf(monkeypatch)
|
||||
looping_index = f"""<?xml version="1.0" encoding="UTF-8"?>
|
||||
<sitemapindex xmlns="{_NS}">
|
||||
<sitemap><loc>https://example.com/sitemap.xml</loc></sitemap>
|
||||
<sitemap><loc>https://example.com/sitemap-en.xml</loc></sitemap>
|
||||
<sitemap><loc>https://example.com/sitemap-en.xml</loc></sitemap>
|
||||
</sitemapindex>""".encode()
|
||||
calls: list[str] = []
|
||||
responses = {
|
||||
"https://example.com/sitemap.xml": _fake_response(looping_index),
|
||||
"https://example.com/sitemap-en.xml": _fake_response(_CHILD_SITEMAP_XML),
|
||||
}
|
||||
|
||||
def _get(url, **kwargs):
|
||||
calls.append(url)
|
||||
return responses[url]
|
||||
|
||||
monkeypatch.setattr(_sitemap_mod.requests.Session, "get", lambda self, url, **kwargs: _get(url, **kwargs))
|
||||
urls = [u for u, _ in _connector()._iter_sitemap_urls("https://example.com/sitemap.xml", depth=0)]
|
||||
|
||||
assert urls == ["https://example.com/en/page-1"]
|
||||
assert sorted(calls) == ["https://example.com/sitemap-en.xml", "https://example.com/sitemap.xml"]
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_sitemap_urls_stops_at_fetch_budget(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
monkeypatch.setattr(_sitemap_mod, "_MAX_SITEMAP_FETCHES", 3)
|
||||
children = "".join(f"<sitemap><loc>https://example.com/child-{i}.xml</loc></sitemap>" for i in range(10))
|
||||
index = f'<?xml version="1.0" encoding="UTF-8"?><sitemapindex xmlns="{_NS}">{children}</sitemapindex>'.encode()
|
||||
responses = {"https://example.com/sitemap.xml": _fake_response(index)}
|
||||
for i in range(10):
|
||||
child = f'<?xml version="1.0" encoding="UTF-8"?><urlset xmlns="{_NS}"><url><loc>https://example.com/page-{i}</loc></url></urlset>'.encode()
|
||||
responses[f"https://example.com/child-{i}.xml"] = _fake_response(child)
|
||||
calls: list[str] = []
|
||||
|
||||
def _get(url, **kwargs):
|
||||
calls.append(url)
|
||||
return responses[url]
|
||||
|
||||
monkeypatch.setattr(_sitemap_mod.requests.Session, "get", lambda self, url, **kwargs: _get(url, **kwargs))
|
||||
urls = [u for u, _ in _connector()._iter_sitemap_urls("https://example.com/sitemap.xml", depth=0)]
|
||||
|
||||
assert len(calls) == 3 # index + 2 children
|
||||
assert urls == ["https://example.com/page-0", "https://example.com/page-1"]
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_session_ignores_environment_proxies_and_netrc():
|
||||
connector = _connector()
|
||||
assert connector._session.trust_env is False
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_url_filter_evaluation_is_time_bounded(monkeypatch):
|
||||
"""`(a|aa)+` cannot be rejected syntactically; the timeout must stop the match."""
|
||||
monkeypatch.setattr(_sitemap_mod, "_URL_FILTER_TIMEOUT_SECONDS", 0.05)
|
||||
connector = _connector(url_filter=r"^https://(a|aa)+$")
|
||||
start = time.monotonic()
|
||||
|
||||
assert connector._url_matches("https://" + "a" * 60 + "b") is False
|
||||
assert time.monotonic() - start < 2.0
|
||||
assert connector._url_matches("https://aaaa") is True
|
||||
|
||||
|
||||
# ---------------------------------------------------------------------------
|
||||
# iter_in_worker_thread (bridge used by the sync worker)
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_in_worker_thread_yields_all_items_from_another_thread():
|
||||
producer_threads: set[str] = set()
|
||||
|
||||
def _source():
|
||||
for i in range(5):
|
||||
producer_threads.add(threading.current_thread().name)
|
||||
yield [i]
|
||||
|
||||
items = list(_sitemap_mod.iter_in_worker_thread(_source(), maxsize=1))
|
||||
|
||||
assert items == [[0], [1], [2], [3], [4]]
|
||||
assert producer_threads == {"sitemap-batch-producer"}
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_in_worker_thread_propagates_exceptions():
|
||||
def _source():
|
||||
yield [1]
|
||||
raise RuntimeError("boom")
|
||||
|
||||
it = _sitemap_mod.iter_in_worker_thread(_source())
|
||||
assert next(it) == [1]
|
||||
with pytest.raises(RuntimeError, match="boom"):
|
||||
next(it)
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_in_worker_thread_stops_producer_when_consumer_closes():
|
||||
produced: list[int] = []
|
||||
closed = threading.Event()
|
||||
|
||||
def _source():
|
||||
try:
|
||||
for i in range(1000):
|
||||
produced.append(i)
|
||||
yield [i]
|
||||
finally:
|
||||
closed.set()
|
||||
|
||||
it = _sitemap_mod.iter_in_worker_thread(_source(), maxsize=1)
|
||||
assert next(it) == [0]
|
||||
it.close()
|
||||
|
||||
assert closed.wait(timeout=5)
|
||||
assert len(produced) < 10
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_in_worker_thread_terminal_writes_do_not_block_after_close():
|
||||
"""Producer must exit even if the consumer closes while the queue is full."""
|
||||
started = threading.Event()
|
||||
|
||||
def _source():
|
||||
started.set()
|
||||
for i in range(50):
|
||||
yield [i]
|
||||
|
||||
it = _sitemap_mod.iter_in_worker_thread(_source(), maxsize=1)
|
||||
assert started.wait(timeout=5)
|
||||
time.sleep(0.2) # let the producer fill the queue and block on put()
|
||||
it.close()
|
||||
it.join(timeout=5)
|
||||
assert it.producer_alive is False
|
||||
|
||||
def _failing():
|
||||
yield [1]
|
||||
raise RuntimeError("late failure")
|
||||
|
||||
it = _sitemap_mod.iter_in_worker_thread(_failing(), maxsize=1)
|
||||
time.sleep(0.2)
|
||||
it.close()
|
||||
it.join(timeout=5)
|
||||
assert it.producer_alive is False
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_iter_in_worker_thread_close_cancels_an_in_flight_fetch():
|
||||
"""Closing the consumer must interrupt the source at its next cancellation check."""
|
||||
cancel = threading.Event()
|
||||
fetch_started = threading.Event()
|
||||
fetch_aborted = threading.Event()
|
||||
|
||||
def _slow_source():
|
||||
yield ["first"]
|
||||
fetch_started.set()
|
||||
# emulate a long fetch that polls the cancellation flag (as _read_capped does)
|
||||
for _ in range(200):
|
||||
if cancel.is_set():
|
||||
fetch_aborted.set()
|
||||
return
|
||||
time.sleep(0.02)
|
||||
yield ["never"]
|
||||
|
||||
it = _sitemap_mod.iter_in_worker_thread(_slow_source(), maxsize=1, on_close=cancel.set)
|
||||
assert next(it) == ["first"]
|
||||
assert fetch_started.wait(timeout=5)
|
||||
it.close()
|
||||
|
||||
assert fetch_aborted.wait(timeout=5)
|
||||
it.join(timeout=5)
|
||||
assert it.producer_alive is False
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_cancel_stops_traversal_before_next_fetch(monkeypatch):
|
||||
_patch_ssrf(monkeypatch)
|
||||
_patch_trafilatura(monkeypatch)
|
||||
fetched: list[str] = []
|
||||
responses = {
|
||||
"https://example.com/sitemap.xml": _fake_response(_SITEMAP_XML),
|
||||
"https://example.com/page-1": _fake_response(b"<html>1</html>"),
|
||||
"https://example.com/page-2": _fake_response(b"<html>2</html>"),
|
||||
}
|
||||
connector = _connector(batch_size=1)
|
||||
|
||||
def _get(self, url, **kwargs):
|
||||
fetched.append(url)
|
||||
if url.endswith("/page-1"):
|
||||
connector.cancel() # cancellation arrives while the first page is being fetched
|
||||
return responses[url]
|
||||
|
||||
monkeypatch.setattr(_sitemap_mod.requests.Session, "get", _get)
|
||||
batches = list(connector.load_from_state())
|
||||
|
||||
assert connector.cancelled is True
|
||||
assert "https://example.com/page-2" not in fetched
|
||||
assert len(batches) <= 1
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
def test_read_capped_aborts_when_cancelled(monkeypatch):
|
||||
connector = _connector()
|
||||
chunks = iter([b"aaaa", b"bbbb", b"cccc"])
|
||||
|
||||
def _iter_content(chunk_size=65536):
|
||||
for chunk in chunks:
|
||||
connector.cancel()
|
||||
yield chunk
|
||||
|
||||
resp = _fake_response(b"")
|
||||
resp.iter_content.side_effect = _iter_content
|
||||
|
||||
with pytest.raises(ValueError, match="cancelled"):
|
||||
connector._read_capped(resp, "https://example.com/big")
|
||||
resp.close.assert_called()
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
async def test_validate_connector_in_thread_signals_cancellation_on_timeout(caplog):
|
||||
"""A task timeout during validation must tell the connector to stop, and log it."""
|
||||
caplog.set_level(logging.WARNING, logger=_sitemap_mod.__name__)
|
||||
connector = _connector()
|
||||
started = threading.Event()
|
||||
finished = threading.Event()
|
||||
|
||||
def _blocking_validate():
|
||||
started.set()
|
||||
while not connector.cancelled:
|
||||
time.sleep(0.01)
|
||||
finished.set()
|
||||
|
||||
connector.validate_connector_settings = _blocking_validate # type: ignore[method-assign]
|
||||
|
||||
with pytest.raises(asyncio.TimeoutError):
|
||||
await asyncio.wait_for(_sitemap_mod.validate_connector_in_thread(connector), timeout=0.2)
|
||||
|
||||
assert started.is_set()
|
||||
assert connector.cancelled is True
|
||||
assert finished.wait(timeout=5)
|
||||
assert any("validation cancelled" in rec.getMessage() and "https://example.com/sitemap.xml" in rec.getMessage() for rec in caplog.records)
|
||||
|
||||
|
||||
@pytest.mark.p2
|
||||
async def test_validate_connector_in_thread_propagates_validation_errors():
|
||||
connector = _connector()
|
||||
connector.validate_connector_settings = lambda: (_ for _ in ()).throw(ValueError("bad sitemap")) # type: ignore[method-assign]
|
||||
|
||||
with pytest.raises(ValueError, match="bad sitemap"):
|
||||
await _sitemap_mod.validate_connector_in_thread(connector)
|
||||
assert connector.cancelled is False
|
||||
@@ -1385,6 +1385,20 @@ wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/80/99/2adc7d8ffead633234817ef8e9a87115c8a11927a94478f6bb3d3f4d4f7d/contourpy-1.3.3-cp313-cp313t-win_arm64.whl", hash = "sha256:3c30273eb2a55024ff31ba7d052dde990d7d8e5450f4bbb6e913558b3d6c2301" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "courlan"
|
||||
version = "1.4.0"
|
||||
source = { registry = "https://mirrors.aliyun.com/pypi/simple" }
|
||||
dependencies = [
|
||||
{ name = "babel" },
|
||||
{ name = "tld" },
|
||||
{ name = "urllib3" },
|
||||
]
|
||||
sdist = { url = "https://mirrors.aliyun.com/pypi/packages/bb/16/2a771612ee0b3acaa95ac21cc7e8a3319e815d6360f8ffc5987d1ce28499/courlan-1.4.0.tar.gz", hash = "sha256:fbbac7b7fcde2195ea08e707609503c81cf39c891e8d26cdb1fed4585782d63d" }
|
||||
wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/1f/38/ce65091ff20a16e06d17418c4353af5f56d3190821b1a06983c79ae79274/courlan-1.4.0-py3-none-any.whl", hash = "sha256:ad1dbdefd912ca7238d4607dc855df5df097f56bac175dd662c84eed3802f49e" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "coverage"
|
||||
version = "7.13.1"
|
||||
@@ -1662,6 +1676,21 @@ wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/30/15/35551e6c6d3ea19df754ed32aa5f281b2052ef9e1ff1538f2708f74f3312/dashscope-1.25.11-py3-none-any.whl", hash = "sha256:93e86437f5f30e759e98292f0490e44eff00c337968363f27d29dd42ec7cc07c" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "dateparser"
|
||||
version = "1.4.3"
|
||||
source = { registry = "https://mirrors.aliyun.com/pypi/simple" }
|
||||
dependencies = [
|
||||
{ name = "python-dateutil" },
|
||||
{ name = "pytz" },
|
||||
{ name = "regex" },
|
||||
{ name = "tzlocal" },
|
||||
]
|
||||
sdist = { url = "https://mirrors.aliyun.com/pypi/packages/c7/5d/bd21ba1519b6b1e222b29878301d2e1fb928e890dc7d085fa4222ac5671b/dateparser-1.4.3.tar.gz", hash = "sha256:bab8c43a746266e68142f4926e69438ce551441aa88e54e78bb6410bf3ee7000" }
|
||||
wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/30/5f/63f927b5ffd1cc2c030fc2bd362bf920890e8806cf42f701198de5b3f9c7/dateparser-1.4.3-py3-none-any.whl", hash = "sha256:cbce86c64e0cea5c54c84c015d34c903d46c51bfad50632bf2f05a6141d10c05" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "datrie"
|
||||
version = "0.8.3"
|
||||
@@ -2729,6 +2758,22 @@ wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/6c/dd/a834df6482147d48e225a49515aabc28974ad5a4ca3215c18a882565b028/html5lib-1.1-py2.py3-none-any.whl", hash = "sha256:0d78f8fde1c230e99fe37986a60526d7049ed4bf8a9fadbad5f00e22e58e041d" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "htmldate"
|
||||
version = "1.10.0"
|
||||
source = { registry = "https://mirrors.aliyun.com/pypi/simple" }
|
||||
dependencies = [
|
||||
{ name = "charset-normalizer" },
|
||||
{ name = "dateparser" },
|
||||
{ name = "lxml" },
|
||||
{ name = "python-dateutil" },
|
||||
{ name = "urllib3" },
|
||||
]
|
||||
sdist = { url = "https://mirrors.aliyun.com/pypi/packages/ad/1f/e7cf83e23d7b68105de8b874a8b36ba23b450d6f71388583e4ca3ce475ca/htmldate-1.10.0.tar.gz", hash = "sha256:a38df10772ab5d7dbb11896e3f6a852a8491fb1b0965465bc174e23fc2baae58" }
|
||||
wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/f7/17/d3356233c826c641f940983d9479eab27faec59d49f4070bc58e80fcc021/htmldate-1.10.0-py3-none-any.whl", hash = "sha256:9211dae35ab94147c8ed9e5fc2c9287a5cf31d2394cb7857e7f5dd814eb2aad6" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "httpcore"
|
||||
version = "1.0.9"
|
||||
@@ -3251,6 +3296,18 @@ wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/41/45/1a4ed80516f02155c51f51e8cedb3c1902296743db0bbc66608a0db2814f/jsonschema_specifications-2025.9.1-py3-none-any.whl", hash = "sha256:98802fee3a11ee76ecaca44429fda8a41bff98b00a0f2838151b113f210cc6fe" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "justext"
|
||||
version = "3.0.2"
|
||||
source = { registry = "https://mirrors.aliyun.com/pypi/simple" }
|
||||
dependencies = [
|
||||
{ name = "lxml", extra = ["html-clean"] },
|
||||
]
|
||||
sdist = { url = "https://mirrors.aliyun.com/pypi/packages/49/f3/45890c1b314f0d04e19c1c83d534e611513150939a7cf039664d9ab1e649/justext-3.0.2.tar.gz", hash = "sha256:13496a450c44c4cd5b5a75a5efcd9996066d2a189794ea99a49949685a0beb05" }
|
||||
wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/f2/ac/52f4e86d1924a7fc05af3aeb34488570eccc39b4af90530dd6acecdf16b5/justext-3.0.2-py2.py3-none-any.whl", hash = "sha256:62b1c562b15c3c6265e121cc070874243a443bfd53060e869393f09d6b6cc9a7" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "kaitaistruct"
|
||||
version = "0.11"
|
||||
@@ -8241,6 +8298,7 @@ dependencies = [
|
||||
{ name = "tavily-python" },
|
||||
{ name = "tencentcloud-sdk-python" },
|
||||
{ name = "tika" },
|
||||
{ name = "trafilatura" },
|
||||
{ name = "ucloud-sandbox" },
|
||||
{ name = "valkey" },
|
||||
{ name = "volcengine" },
|
||||
@@ -8272,6 +8330,7 @@ test = [
|
||||
{ name = "pytest-xdist" },
|
||||
{ name = "python-docx" },
|
||||
{ name = "python-pptx" },
|
||||
{ name = "regex" },
|
||||
{ name = "reportlab" },
|
||||
{ name = "requests" },
|
||||
{ name = "requests-toolbelt" },
|
||||
@@ -8406,6 +8465,7 @@ requires-dist = [
|
||||
{ name = "tavily-python", specifier = "==0.5.1" },
|
||||
{ name = "tencentcloud-sdk-python", specifier = "==3.0.1478" },
|
||||
{ name = "tika", specifier = "==2.6.0" },
|
||||
{ name = "trafilatura", specifier = ">=2.0.0" },
|
||||
{ name = "ucloud-sandbox", specifier = ">=1.4.2,<2.0.0" },
|
||||
{ name = "valkey", specifier = "==6.0.2" },
|
||||
{ name = "volcengine", specifier = "==1.0.194" },
|
||||
@@ -8437,6 +8497,7 @@ test = [
|
||||
{ name = "pytest-xdist", specifier = ">=3.8.0" },
|
||||
{ name = "python-docx", specifier = ">=1.1.2" },
|
||||
{ name = "python-pptx", specifier = ">=1.0.2" },
|
||||
{ name = "regex", specifier = ">=2025.11.3" },
|
||||
{ name = "reportlab", specifier = ">=4.4.1" },
|
||||
{ name = "requests", specifier = ">=2.32.2" },
|
||||
{ name = "requests-toolbelt", specifier = ">=1.0.0" },
|
||||
@@ -9643,6 +9704,15 @@ wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/93/e0/6cc82a562bc6365785a3ff0af27a2a092d57c47d7a81d9e2295d8c36f011/tiktoken-0.12.0-cp313-cp313t-win_amd64.whl", hash = "sha256:dc2dd125a62cb2b3d858484d6c614d136b5b848976794edfb63688d539b8b93f" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "tld"
|
||||
version = "0.13.2"
|
||||
source = { registry = "https://mirrors.aliyun.com/pypi/simple" }
|
||||
sdist = { url = "https://mirrors.aliyun.com/pypi/packages/5c/5d/76b4383ac4e5b5e254e50c09807b3e13820bed6d6c11cd540264988d6802/tld-0.13.2.tar.gz", hash = "sha256:d983fa92b9d717400742fca844e29d5e18271079c7bcfabf66d01b39b4a14345" }
|
||||
wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/9e/90/39a85a4b63c84213e78b3c17d22e1bf45328acf8ebb33ef93be30d0a3911/tld-0.13.2-py2.py3-none-any.whl", hash = "sha256:9b8fdbdb880e7ba65b216a4937f2c94c49a7226723783d5838fc958ac76f4e0c" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "tokenizers"
|
||||
version = "0.22.2"
|
||||
@@ -9681,6 +9751,24 @@ wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/d0/30/dc54f88dd4a2b5dc8a0279bdd7270e735851848b762aeb1c1184ed1f6b14/tqdm-4.67.1-py3-none-any.whl", hash = "sha256:26445eca388f82e72884e0d580d5464cd801a3ea01e63e5601bdff9ba6a48de2" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "trafilatura"
|
||||
version = "2.1.0"
|
||||
source = { registry = "https://mirrors.aliyun.com/pypi/simple" }
|
||||
dependencies = [
|
||||
{ name = "certifi" },
|
||||
{ name = "charset-normalizer" },
|
||||
{ name = "courlan" },
|
||||
{ name = "htmldate" },
|
||||
{ name = "justext" },
|
||||
{ name = "lxml" },
|
||||
{ name = "urllib3" },
|
||||
]
|
||||
sdist = { url = "https://mirrors.aliyun.com/pypi/packages/e8/19/24833e905df2d80e3bb67424f95febcc17709a1f61a522120bc438afca70/trafilatura-2.1.0.tar.gz", hash = "sha256:f689e2116fc89c7bc0b9a296d01dcfe2eb0b5455f8c371a77dc0db1f06a05643" }
|
||||
wheels = [
|
||||
{ url = "https://mirrors.aliyun.com/pypi/packages/0e/78/4ad99d79aee2784f49f20fd0a29058ce4c032fe4439047924c43521cd211/trafilatura-2.1.0-py3-none-any.whl", hash = "sha256:0eded5207a806445ddebbe36eae30b9035fe6a2f233c36f6fe82663fca8b9d30" },
|
||||
]
|
||||
|
||||
[[package]]
|
||||
name = "trec-car-tools"
|
||||
version = "2.6"
|
||||
|
||||
@@ -924,7 +924,10 @@ export default {
|
||||
'Upload the OAuth JSON generated from Google Console. If it only contains client credentials, run the browser-based verification once to mint long-lived refresh tokens.',
|
||||
dropboxDescription:
|
||||
'Connect your Dropbox to sync files and folders from a chosen account.',
|
||||
azure_devopsDescription: 'اربط Azure DevOps لمزامنة ملفات المستودع وطلبات السحب.',
|
||||
sitemapDescription:
|
||||
'اربط ملف sitemap.xml عامًا لمزامنة صفحات الويب ومستندات PDF المدرجة فيه مع قاعدة المعرفة.',
|
||||
azure_devopsDescription:
|
||||
'اربط Azure DevOps لمزامنة ملفات المستودع وطلبات السحب.',
|
||||
bitbucketDescription: 'Connect Bitbucket to sync PR content.',
|
||||
bitbucketTopWorkspaceTip:
|
||||
'The Bitbucket workspace to index (e.g., "atlassian" from https://bitbucket.org/atlassian/workspace ).',
|
||||
|
||||
@@ -1001,7 +1001,10 @@ The above is the content you need to summarize.`,
|
||||
gmailTokenTip: 'Качете OAuth JSON, генериран от Google Console.',
|
||||
dropboxDescription:
|
||||
'Свържете вашия Dropbox за синхронизиране на файлове и папки от избран акаунт.',
|
||||
azure_devopsDescription: 'Свържете Azure DevOps, за да синхронизирате файловете на хранилището и заявките за изтегляне (pull requests).',
|
||||
sitemapDescription:
|
||||
'Свържете публичен sitemap.xml, за да синхронизирате изброените уеб страници и PDF документи с базата от знания.',
|
||||
azure_devopsDescription:
|
||||
'Свържете Azure DevOps, за да синхронизирате файловете на хранилището и заявките за изтегляне (pull requests).',
|
||||
bitbucketDescription:
|
||||
'Свържете Bitbucket за синхронизиране на PR съдържание.',
|
||||
bitbucketTopWorkspaceTip:
|
||||
|
||||
@@ -1015,7 +1015,10 @@ Beispiel: Virtual Hosted Style`,
|
||||
'Laden Sie das OAuth-JSON hoch, das von der Google Console generiert wurde. Wenn es nur Client-Anmeldeinformationen enthält, führen Sie die browserbasierte Überprüfung einmal durch, um langlebige Refresh-Token zu erstellen.',
|
||||
dropboxDescription:
|
||||
'Verbinden Sie Ihre Dropbox, um Dateien und Ordner von einem ausgewählten Konto zu synchronisieren.',
|
||||
azure_devopsDescription: 'Verbinden Sie Azure DevOps, um Repository-Dateien und Pull Requests zu synchronisieren.',
|
||||
sitemapDescription:
|
||||
'Verbinden Sie eine öffentliche sitemap.xml, um die aufgeführten Webseiten und PDF-Dokumente mit Ihrer Wissensdatenbank zu synchronisieren.',
|
||||
azure_devopsDescription:
|
||||
'Verbinden Sie Azure DevOps, um Repository-Dateien und Pull Requests zu synchronisieren.',
|
||||
bitbucketDescription:
|
||||
'Bitbucket verbinden, um PR-Inhalte zu synchronisieren.',
|
||||
zendeskDescription:
|
||||
|
||||
@@ -1307,6 +1307,11 @@ This auto-tagging feature enhances retrieval by adding another layer of domain-s
|
||||
dataSourceFieldContainerName: 'Container Name',
|
||||
dataSourceFieldPrefixOptional: 'Prefix (optional)',
|
||||
dataSourceFieldFeedUrl: 'Feed URL',
|
||||
dataSourceFieldSitemapUrl: 'Sitemap URL',
|
||||
dataSourceFieldUrlFilter: 'URL filter (regex)',
|
||||
dataSourceFieldFollowPdfLinks: 'Follow PDF links',
|
||||
dataSourceFieldRestrictPdfToDomain: 'Restrict PDFs to sitemap domain',
|
||||
dataSourceFieldUserAgent: 'User-Agent',
|
||||
dataSourceFieldGcsAccessKeyId: 'GCS Access Key ID',
|
||||
dataSourceFieldGcsSecretAccessKey: 'GCS Secret Access Key',
|
||||
dataSourceFieldBucketName: 'Bucket Name',
|
||||
@@ -1608,6 +1613,20 @@ Example: Virtual Hosted Style`,
|
||||
'Every repository visible to the token in this organization will be indexed.',
|
||||
azureDevOpsContentTypesTip:
|
||||
'Choose what to index: source files, pull requests, or both.',
|
||||
sitemapDescription:
|
||||
'Connect a public sitemap.xml to sync the listed web pages and PDF documents into your knowledge base.',
|
||||
sitemapUrlTip:
|
||||
'URL of the sitemap.xml or sitemap index to crawl, e.g. https://example.com/sitemap.xml. Sitemap indexes are followed recursively (up to 5 levels).',
|
||||
sitemapUrlFilterTip:
|
||||
'Optional regular expression. Only URLs matching it are indexed, e.g. ^https://example\\.com/docs/ to restrict the sync to a section of the site.',
|
||||
sitemapFollowPdfLinksTip:
|
||||
'Also index the PDF files linked from the crawled HTML pages.',
|
||||
sitemapRestrictPdfToDomainTip:
|
||||
'Only follow PDF links hosted on the same domain as the sitemap.',
|
||||
sitemapUserAgentTip:
|
||||
'User-Agent header sent with every request. Leave empty to use RAGFlow-SitemapConnector/1.0.',
|
||||
sitemapBatchSizeTip:
|
||||
'Number of pages fetched and sent to RAGFlow per batch.',
|
||||
azure_devopsDescription:
|
||||
'Connect Azure DevOps to sync repository files and pull requests.',
|
||||
bitbucketDescription: 'Connect Bitbucket to sync PR content.',
|
||||
|
||||
@@ -1505,6 +1505,26 @@ Exemple : Virtual Hosted Style`,
|
||||
'Connectez un site SharePoint via Microsoft Graph pour synchroniser ses bibliothèques de documents.',
|
||||
sharepointSiteUrlTip:
|
||||
'URL complète du site SharePoint à indexer, ex. : https://contoso.sharepoint.com/sites/MonSite. Nécessite une application Azure AD avec les permissions applicatives Sites.Read.All et Files.Read.All (consentement administrateur).',
|
||||
dataSourceFieldSitemapUrl: 'URL du sitemap',
|
||||
dataSourceFieldUrlFilter: 'Filtre d’URL (regex)',
|
||||
dataSourceFieldFollowPdfLinks: 'Suivre les liens PDF',
|
||||
dataSourceFieldRestrictPdfToDomain:
|
||||
'Limiter les PDF au domaine du sitemap',
|
||||
dataSourceFieldUserAgent: 'User-Agent',
|
||||
sitemapDescription:
|
||||
'Connectez un sitemap.xml public pour synchroniser dans votre base de connaissances les pages web et les documents PDF qu’il répertorie.',
|
||||
sitemapUrlTip:
|
||||
'URL du sitemap.xml ou de l’index de sitemaps à parcourir, ex. : https://example.com/sitemap.xml. Les index de sitemaps sont suivis récursivement (5 niveaux maximum).',
|
||||
sitemapUrlFilterTip:
|
||||
'Expression régulière facultative. Seules les URL correspondantes sont indexées, ex. : ^https://example\\.com/docs/ pour limiter la synchronisation à une section du site.',
|
||||
sitemapFollowPdfLinksTip:
|
||||
'Indexer également les fichiers PDF liés depuis les pages HTML parcourues.',
|
||||
sitemapRestrictPdfToDomainTip:
|
||||
'Ne suivre que les liens PDF hébergés sur le même domaine que le sitemap.',
|
||||
sitemapUserAgentTip:
|
||||
'En-tête User-Agent envoyé avec chaque requête. Laissez vide pour utiliser RAGFlow-SitemapConnector/1.0.',
|
||||
sitemapBatchSizeTip:
|
||||
'Nombre de pages récupérées et envoyées à RAGFlow par lot.',
|
||||
azure_devopsDescription:
|
||||
'Connectez Azure DevOps pour synchroniser les fichiers du dépôt et les pull requests.',
|
||||
bitbucketDescription:
|
||||
|
||||
@@ -1284,6 +1284,8 @@ Esempio: Virtual Hosted Style`,
|
||||
'Connetti un sito SharePoint tramite Microsoft Graph per sincronizzare le sue librerie documenti.',
|
||||
sharepointSiteUrlTip:
|
||||
"URL completo del sito SharePoint da indicizzare, es. https://contoso.sharepoint.com/sites/MySite. Richiede un'app Azure AD con permessi applicativi Sites.Read.All e Files.Read.All (consenso admin).",
|
||||
sitemapDescription:
|
||||
'Collega una sitemap.xml pubblica per sincronizzare nella tua knowledge base le pagine web e i documenti PDF che elenca.',
|
||||
azure_devopsDescription:
|
||||
'Collega Azure DevOps per sincronizzare i file del repository e le pull request.',
|
||||
bitbucketDescription:
|
||||
|
||||
@@ -1339,6 +1339,8 @@ export default {
|
||||
'Microsoft Graph経由でSharePointサイトに接続し、ドキュメントライブラリを同期します。',
|
||||
sharepointSiteUrlTip:
|
||||
'インデックス対象のSharePointサイトの完全なURLです(例: https://contoso.sharepoint.com/sites/MySite)。Sites.Read.AllおよびFiles.Read.Allのアプリケーション権限(管理者の同意)を持つAzure ADアプリが必要です。',
|
||||
sitemapDescription:
|
||||
'公開されている sitemap.xml を接続し、記載されたウェブページと PDF ドキュメントをナレッジベースに同期します。',
|
||||
azure_devopsDescription:
|
||||
'Azure DevOps に接続し、リポジトリのファイルとプルリクエストを同期します。',
|
||||
bitbucketDescription: 'Bitbucketに接続し、PRの内容を同期します。',
|
||||
|
||||
@@ -1256,6 +1256,8 @@ export default {
|
||||
'Microsoft Graph를 통해 SharePoint 사이트를 연결하여 문서 라이브러리를 동기화합니다.',
|
||||
sharepointSiteUrlTip:
|
||||
'인덱싱할 SharePoint 사이트의 전체 URL (예: https://contoso.sharepoint.com/sites/MySite). Sites.Read.All 및 Files.Read.All 애플리케이션 권한이 있는 Azure AD 앱이 필요합니다 (관리자 동의).',
|
||||
sitemapDescription:
|
||||
'공개 sitemap.xml을 연결하여 나열된 웹 페이지와 PDF 문서를 지식 베이스에 동기화합니다.',
|
||||
azure_devopsDescription:
|
||||
'Azure DevOps를 연결하여 리포지토리 파일과 풀 리퀘스트를 동기화합니다.',
|
||||
bitbucketDescription: 'Bitbucket을 연결하여 PR 콘텐츠를 동기화합니다.',
|
||||
|
||||
@@ -1067,6 +1067,8 @@ export default {
|
||||
'Загрузите OAuth JSON, сгенерированный в Google Console. Если он содержит только учетные данные клиента, выполните одноразовое подтверждение в браузере, чтобы получить долгоживущие токены обновления.',
|
||||
dropboxDescription:
|
||||
'Подключите ваш Dropbox для синхронизации файлов и папок из выбранного аккаунта.',
|
||||
sitemapDescription:
|
||||
'Подключите публичный sitemap.xml, чтобы синхронизировать перечисленные веб-страницы и PDF-документы с базой знаний.',
|
||||
azure_devopsDescription:
|
||||
"Подключите Azure DevOps для синхронизации файлов репозитория и pull request'ов.",
|
||||
bitbucketDescription:
|
||||
|
||||
@@ -1604,6 +1604,8 @@ Bu otomatik etiketleme özelliği, mevcut datasete alanına özgü bilgi katman
|
||||
"Bu kuruluşta token'ın görebildiği her depo dizinlenecektir.",
|
||||
azureDevOpsContentTypesTip:
|
||||
'Neyin dizinleneceğini seçin: kaynak dosyalar, çekme istekleri veya her ikisi.',
|
||||
sitemapDescription:
|
||||
'Listelenen web sayfalarını ve PDF belgelerini bilgi tabanınıza eşitlemek için herkese açık bir sitemap.xml bağlayın.',
|
||||
azure_devopsDescription:
|
||||
"Depo dosyalarını ve pull request'leri senkronize etmek için Azure DevOps'u bağlayın.",
|
||||
bitbucketDescription:
|
||||
|
||||
@@ -780,6 +780,22 @@ export default {
|
||||
modelsToBeAddedTooltip:
|
||||
'若您的模型供應商未列於此處,但宣稱與 OpenAI 相容,可透過選擇「OpenAI-API-compatible」卡片來設定相關模型。',
|
||||
dropboxDescription: '連接 Dropbox,同步指定帳號下的文件與文件夾。',
|
||||
sitemapDescription:
|
||||
'連接公開的 sitemap.xml,將其中列出的網頁和 PDF 文件同步到知識庫。',
|
||||
dataSourceFieldSitemapUrl: 'Sitemap URL',
|
||||
dataSourceFieldUrlFilter: 'URL 篩選(正規表示式)',
|
||||
dataSourceFieldFollowPdfLinks: '跟隨 PDF 連結',
|
||||
dataSourceFieldRestrictPdfToDomain: '僅限 sitemap 所在網域的 PDF',
|
||||
dataSourceFieldUserAgent: 'User-Agent',
|
||||
sitemapUrlTip:
|
||||
'要擷取的 sitemap.xml 或 sitemap 索引的 URL,例如 https://example.com/sitemap.xml。sitemap 索引會被遞迴跟隨(最多 5 層)。',
|
||||
sitemapUrlFilterTip:
|
||||
'選填的正規表示式。僅索引與之符合的 URL,例如 ^https://example\\.com/docs/ 可將同步限制在網站的某個區塊。',
|
||||
sitemapFollowPdfLinksTip: '同時索引已擷取 HTML 頁面中連結的 PDF 檔案。',
|
||||
sitemapRestrictPdfToDomainTip: '僅跟隨與 sitemap 同網域下的 PDF 連結。',
|
||||
sitemapUserAgentTip:
|
||||
'每次請求送出的 User-Agent 標頭。留空則使用 RAGFlow-SitemapConnector/1.0。',
|
||||
sitemapBatchSizeTip: '每批擷取並送到 RAGFlow 的頁面數量。',
|
||||
azure_devopsDescription: '連接 Azure DevOps 以同步儲存庫檔案和拉取請求。',
|
||||
bitbucketDescription: '連接 Bitbucket,同步 PR 內容。',
|
||||
zendeskDescription: '連接 Zendesk,同步工單、文章及其他內容。',
|
||||
|
||||
@@ -1272,6 +1272,22 @@ NER:使用 spaCy NER 和基于规则的关键词提取来抽取 Entities 和 R
|
||||
azureDevOpsOrganizationScopeTip: '将索引该组织中令牌可见的所有仓库。',
|
||||
azureDevOpsContentTypesTip:
|
||||
'选择要索引的内容:源文件、拉取请求,或两者。',
|
||||
sitemapDescription:
|
||||
'连接公开的 sitemap.xml,将其中列出的网页和 PDF 文档同步到知识库。',
|
||||
dataSourceFieldSitemapUrl: 'Sitemap URL',
|
||||
dataSourceFieldUrlFilter: 'URL 过滤(正则)',
|
||||
dataSourceFieldFollowPdfLinks: '跟随 PDF 链接',
|
||||
dataSourceFieldRestrictPdfToDomain: '仅限 sitemap 所在域名的 PDF',
|
||||
dataSourceFieldUserAgent: 'User-Agent',
|
||||
sitemapUrlTip:
|
||||
'要抓取的 sitemap.xml 或 sitemap 索引的 URL,例如 https://example.com/sitemap.xml。sitemap 索引会被递归跟随(最多 5 层)。',
|
||||
sitemapUrlFilterTip:
|
||||
'可选的正则表达式。仅索引与之匹配的 URL,例如 ^https://example\\.com/docs/ 可将同步限制在站点的某个栏目。',
|
||||
sitemapFollowPdfLinksTip: '同时索引已抓取 HTML 页面中链接的 PDF 文件。',
|
||||
sitemapRestrictPdfToDomainTip: '仅跟随与 sitemap 同域名下的 PDF 链接。',
|
||||
sitemapUserAgentTip:
|
||||
'每次请求发送的 User-Agent 请求头。留空则使用 RAGFlow-SitemapConnector/1.0。',
|
||||
sitemapBatchSizeTip: '每批抓取并发送到 RAGFlow 的页面数量。',
|
||||
azure_devopsDescription: '连接 Azure DevOps 以同步仓库文件和拉取请求。',
|
||||
bitbucketDescription: '连接 Bitbucket,同步 PR 内容。',
|
||||
bitbucketTopWorkspaceTip:
|
||||
|
||||
@@ -69,3 +69,53 @@ describe('Xquik data source', () => {
|
||||
expect(maxPages?.validation).toMatchObject({ min: 1, max: 1000 });
|
||||
});
|
||||
});
|
||||
|
||||
describe('Sitemap data source', () => {
|
||||
it('registers its catalog entry and defaults', () => {
|
||||
const info = generateDataSourceInfo(translate)[DataSourceKey.SITEMAP];
|
||||
const defaults = DataSourceFormDefaultValues[DataSourceKey.SITEMAP];
|
||||
|
||||
expect(info.name).toBe('Sitemap');
|
||||
expect(info.description).toBe('setting.sitemapDescription');
|
||||
expect(defaults).toEqual({
|
||||
name: '',
|
||||
source: 'sitemap',
|
||||
config: {
|
||||
sitemap_url: '',
|
||||
url_filter: '',
|
||||
follow_pdf_links: false,
|
||||
restrict_pdf_to_domain: true,
|
||||
user_agent: '',
|
||||
batch_size: 10,
|
||||
},
|
||||
});
|
||||
});
|
||||
|
||||
it('requires the sitemap URL and only shows the domain restriction when following PDFs', () => {
|
||||
const fields = getDataSourceFieldsWithExtras(
|
||||
translate,
|
||||
DataSourceKey.SITEMAP,
|
||||
) as Array<{
|
||||
name: string;
|
||||
type?: FormFieldType;
|
||||
required?: boolean;
|
||||
validation?: { min?: number };
|
||||
shouldRender?: (values: any) => boolean;
|
||||
}>;
|
||||
const sitemapUrl = fields.find((f) => f.name === 'config.sitemap_url');
|
||||
const restrict = fields.find(
|
||||
(f) => f.name === 'config.restrict_pdf_to_domain',
|
||||
);
|
||||
const batchSize = fields.find((f) => f.name === 'config.batch_size');
|
||||
|
||||
expect(sitemapUrl?.required).toBe(true);
|
||||
expect(restrict?.type).toBe(FormFieldType.Switch);
|
||||
expect(
|
||||
restrict?.shouldRender?.({ config: { follow_pdf_links: false } }),
|
||||
).toBe(false);
|
||||
expect(
|
||||
restrict?.shouldRender?.({ config: { follow_pdf_links: true } }),
|
||||
).toBe(true);
|
||||
expect(batchSize?.validation?.min).toBe(1);
|
||||
});
|
||||
});
|
||||
@@ -18,7 +18,7 @@ import { FormFieldType } from '@/components/dynamic-form';
|
||||
import { IconFontFill } from '@/components/icon-font';
|
||||
import SvgIcon from '@/components/svg-icon';
|
||||
import { TFunction } from 'i18next';
|
||||
import { Mail, Rss, Search } from 'lucide-react';
|
||||
import { Globe, Mail, Rss, Search } from 'lucide-react';
|
||||
import { useEffect, useState } from 'react';
|
||||
import { useTranslation } from 'react-i18next';
|
||||
import BoxTokenField from '../component/box-token-field';
|
||||
@@ -31,6 +31,7 @@ import { confluenceConstant } from './confluence-constant';
|
||||
import { jiraConstant } from './jira-constant';
|
||||
import { S3Constant } from './s3-constant';
|
||||
import { seafileConstant } from './seafile-constant';
|
||||
import { sitemapConstant } from './sitemap-constant';
|
||||
|
||||
export enum DataSourceKey {
|
||||
CONFLUENCE = 'confluence',
|
||||
@@ -63,6 +64,7 @@ export enum DataSourceKey {
|
||||
BIGQUERY = 'bigquery',
|
||||
REST_API = 'rest_api',
|
||||
RSS = 'rss',
|
||||
SITEMAP = 'sitemap',
|
||||
ONEDRIVE = 'onedrive',
|
||||
OUTLOOK = 'outlook',
|
||||
SALESFORCE = 'salesforce',
|
||||
@@ -153,6 +155,9 @@ export const DataSourceFeatureVisibilityMap: Partial<
|
||||
[DataSourceKey.RSS]: {
|
||||
syncDeletedFiles: true,
|
||||
},
|
||||
[DataSourceKey.SITEMAP]: {
|
||||
syncDeletedFiles: true,
|
||||
},
|
||||
[DataSourceKey.MOODLE]: {
|
||||
syncDeletedFiles: true,
|
||||
},
|
||||
@@ -206,6 +211,11 @@ export const generateDataSourceInfo = (t: TFunction) => {
|
||||
description: t(`setting.${DataSourceKey.RSS}Description`),
|
||||
icon: <Rss className="text-text-primary" size={22} />,
|
||||
},
|
||||
[DataSourceKey.SITEMAP]: {
|
||||
name: 'Sitemap',
|
||||
description: t(`setting.${DataSourceKey.SITEMAP}Description`),
|
||||
icon: <Globe className="text-text-primary" size={22} />,
|
||||
},
|
||||
[DataSourceKey.GOOGLE_CLOUD_STORAGE]: {
|
||||
name: 'Google Cloud Storage',
|
||||
description: t(
|
||||
@@ -783,6 +793,7 @@ const generateDataSourceFormFields = (t: TFunction) => ({
|
||||
},
|
||||
},
|
||||
],
|
||||
[DataSourceKey.SITEMAP]: sitemapConstant(t),
|
||||
[DataSourceKey.GOOGLE_CLOUD_STORAGE]: [
|
||||
{
|
||||
label: t('setting.dataSourceFieldGcsAccessKeyId'),
|
||||
@@ -2075,6 +2086,18 @@ export const DataSourceFormDefaultValues = {
|
||||
batch_size: 2,
|
||||
},
|
||||
},
|
||||
[DataSourceKey.SITEMAP]: {
|
||||
name: '',
|
||||
source: DataSourceKey.SITEMAP,
|
||||
config: {
|
||||
sitemap_url: '',
|
||||
url_filter: '',
|
||||
follow_pdf_links: false,
|
||||
restrict_pdf_to_domain: true,
|
||||
user_agent: '',
|
||||
batch_size: 10,
|
||||
},
|
||||
},
|
||||
[DataSourceKey.S3]: {
|
||||
name: '',
|
||||
source: DataSourceKey.S3,
|
||||
|
||||
@@ -0,0 +1,76 @@
|
||||
/*
|
||||
* Copyright 2026 The InfiniFlow Authors. All Rights Reserved.
|
||||
*
|
||||
* Licensed under the Apache License, Version 2.0 (the "License");
|
||||
* you may not use this file except in compliance with the License.
|
||||
* You may obtain a copy of the License at
|
||||
*
|
||||
* http://www.apache.org/licenses/LICENSE-2.0
|
||||
*
|
||||
* Unless required by applicable law or agreed to in writing, software
|
||||
* distributed under the License is distributed on an "AS IS" BASIS,
|
||||
* WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
* See the License for the specific language governing permissions and
|
||||
* limitations under the License.
|
||||
*/
|
||||
|
||||
import { FormFieldType } from '@/components/dynamic-form';
|
||||
import { TFunction } from 'i18next';
|
||||
|
||||
export const sitemapConstant = (t: TFunction) => [
|
||||
{
|
||||
label: t('setting.dataSourceFieldSitemapUrl'),
|
||||
name: 'config.sitemap_url',
|
||||
type: FormFieldType.Text,
|
||||
required: true,
|
||||
placeholder: 'https://example.com/sitemap.xml',
|
||||
tooltip: t('setting.sitemapUrlTip'),
|
||||
},
|
||||
{
|
||||
label: t('setting.dataSourceFieldUrlFilter'),
|
||||
name: 'config.url_filter',
|
||||
type: FormFieldType.Text,
|
||||
required: false,
|
||||
placeholder: '^https://example\\.com/docs/',
|
||||
tooltip: t('setting.sitemapUrlFilterTip'),
|
||||
},
|
||||
{
|
||||
label: t('setting.dataSourceFieldFollowPdfLinks'),
|
||||
name: 'config.follow_pdf_links',
|
||||
type: FormFieldType.Switch,
|
||||
required: false,
|
||||
defaultValue: false,
|
||||
tooltip: t('setting.sitemapFollowPdfLinksTip'),
|
||||
},
|
||||
{
|
||||
label: t('setting.dataSourceFieldRestrictPdfToDomain'),
|
||||
name: 'config.restrict_pdf_to_domain',
|
||||
type: FormFieldType.Switch,
|
||||
required: false,
|
||||
defaultValue: true,
|
||||
shouldRender: (formValues: any) =>
|
||||
formValues?.config?.follow_pdf_links === true,
|
||||
tooltip: t('setting.sitemapRestrictPdfToDomainTip'),
|
||||
},
|
||||
{
|
||||
label: t('setting.dataSourceFieldUserAgent'),
|
||||
name: 'config.user_agent',
|
||||
type: FormFieldType.Text,
|
||||
required: false,
|
||||
placeholder: 'RAGFlow-SitemapConnector/1.0',
|
||||
tooltip: t('setting.sitemapUserAgentTip'),
|
||||
},
|
||||
{
|
||||
label: t('setting.dataSourceFieldBatchSize'),
|
||||
name: 'config.batch_size',
|
||||
type: FormFieldType.Number,
|
||||
required: false,
|
||||
tooltip: t('setting.sitemapBatchSizeTip'),
|
||||
validation: {
|
||||
min: 1,
|
||||
message: t('setting.dataSourceValidationMinOne', {
|
||||
label: t('setting.dataSourceFieldBatchSize'),
|
||||
}),
|
||||
},
|
||||
},
|
||||
];
|
||||
Reference in new issue
Block a user